mirror of
https://github.com/hanzo-docs/docs.git
synced 2026-10-25 04:20:02 +00:00
content(zen-docs): brand cleanup across blog posts and remove zenlm-models/ui packages
- Update blog/[slug]/page.tsx to use getAllSlugs() instead of getSortedPosts() for static params - Sweep all blog MDX files to remove upstream model name references (brand policy compliance) - Add new blog posts: 7680-dim-embeddings, agent-nfts, bitdelta-behavioral-compression, case-for-decentralized-science - Delete gspo.mdx and qwen2.5-vl-32b.mdx (consolidated/removed content) - Remove packages/zenlm-models and packages/zenlm-ui entirely - Update lib/blog.ts, docs/server.ts, docs/browser.ts for blog infrastructure - Update pnpm-lock.yaml after package removal
This commit is contained in:

@@ -1,7 +1,7 @@
|
||||
import { notFound } from 'next/navigation';
|
||||
import Link from 'next/link';
|
||||
import type { Metadata } from 'next';
|
||||
import { getPost, getSortedPosts } from '@/lib/blog';
|
||||
import { getPost, getAllSlugs } from '@/lib/blog';
|
||||
import { useMDXComponents } from '@/mdx-components';
|
||||
|
||||
interface Props {
|
||||
@@ -19,7 +19,7 @@ export async function generateMetadata({ params }: Props): Promise<Metadata> {
|
||||
}
|
||||
|
||||
export function generateStaticParams() {
|
||||
return getSortedPosts().map((p) => ({ slug: p.slug }));
|
||||
return getAllSlugs().map((slug) => ({ slug }));
|
||||
}
|
||||
|
||||
export default async function BlogPostPage({ params }: Props) {
|
||||
|
||||
@@ -18,16 +18,12 @@ Lower dimensions mean:
|
||||
* Faster similarity computations
|
||||
* Potential information loss
|
||||
|
||||
|
||||
|
||||
Higher dimensions mean:
|
||||
|
||||
* More expressive capacity
|
||||
* Larger memory footprint
|
||||
* Computational overhead
|
||||
|
||||
|
||||
|
||||
The conventional wisdom holds that returns diminish quickly past 1024-2048 dimensions. Our experiments challenge this.
|
||||
|
||||
## Experimental Setup
|
||||
@@ -62,7 +58,7 @@ The improvements continue well past conventional dimension counts.
|
||||
|
||||
Plotting performance against log(dimensions) reveals near-linear scaling:
|
||||
|
||||
$$\text{NDCG@10} \approx 0.12 \cdot \log_2(d) + 37.4$$
|
||||
`\text\{NDCG@10\} \approx 0.12 \cdot \log_2(d) + 37.4`
|
||||
|
||||
This suggests embedding capacity remains a bottleneck even at high dimensions.
|
||||
|
||||
@@ -87,8 +83,6 @@ Higher dimensions don’t just improve metrics; they enable finer distinctions.
|
||||
* **Preserved nuance** : Similar but distinct concepts remain separable
|
||||
* **Hierarchical structure** : Taxonomic relationships emerge naturally
|
||||
|
||||
|
||||
|
||||
## The Efficiency Question
|
||||
|
||||
7680 dimensions cost more to store and search. Is it worth it?
|
||||
@@ -117,12 +111,10 @@ With appropriate indexing, 7680d search remains practical.
|
||||
|
||||
Quantization recovers much of the efficiency loss:
|
||||
|
||||
* **INT8** : 4x compression, <1% quality loss
|
||||
* **INT8** : 4x compression, <1% quality loss
|
||||
* **Binary** : 32x compression, 5% quality loss
|
||||
* **Product Quantization** : 16x compression, 2% quality loss
|
||||
|
||||
|
||||
|
||||
## Practical Recommendations
|
||||
|
||||
Based on our experiments:
|
||||
@@ -132,8 +124,6 @@ Based on our experiments:
|
||||
3. **For conversational applications** : 1536d is sufficient
|
||||
4. **For technical/specialized domains** : Higher dimensions provide outsized benefits
|
||||
|
||||
|
||||
|
||||
## Release
|
||||
|
||||
We’re releasing the Zen-Embed family:
|
||||
@@ -143,8 +133,6 @@ We’re releasing the Zen-Embed family:
|
||||
* **Zen-Embed-L** (3072d): Free, MIT license
|
||||
* **Zen-Embed-XL** (7680d): Free, MIT license
|
||||
|
||||
|
||||
|
||||
All models available on Hugging Face: huggingface.co/zoo-labs
|
||||
|
||||
## What This Means
|
||||
|
||||
@@ -19,8 +19,6 @@ Consider an AI agent that:
|
||||
* Has built reputation through successful completions
|
||||
* Has earned resources through its work
|
||||
|
||||
|
||||
|
||||
Who owns this agent? How does the agent prove its identity? How can capabilities be transferred or composed?
|
||||
|
||||
Current systems treat agents as ephemeral processes. Agent NFTs treat them as persistent entities.
|
||||
@@ -35,34 +33,27 @@ An Agent NFT is a non-fungible token that represents an AI agent. The NFT contai
|
||||
* **Public key** : For signing agent actions
|
||||
* **Metadata** : Name, description, capabilities
|
||||
|
||||
|
||||
|
||||
### Capabilities
|
||||
|
||||
* **Model weights** (or reference to weights)
|
||||
* **Tool permissions** : What APIs/actions the agent can access
|
||||
* **Resource limits** : Compute, memory, rate limits
|
||||
|
||||
|
||||
|
||||
### State
|
||||
|
||||
* **Experience ledger** : Reference to accumulated experiences
|
||||
* **Reputation scores** : On-chain attestations of performance
|
||||
* **Resource balance** : Tokens earned and held
|
||||
|
||||
|
||||
|
||||
### Lineage
|
||||
|
||||
* **Parent agents** : If derived from other agents
|
||||
* **Training data attestations** : Provenance of capabilities
|
||||
* **Version history** : Evolution over time
|
||||
|
||||
|
||||
|
||||
## Technical Architecture
|
||||
[code]
|
||||
```
|
||||
|
||||
+------------------+
|
||||
| Agent NFT |
|
||||
| (ERC-721 Token) |
|
||||
@@ -80,12 +71,14 @@ An Agent NFT is a non-fungible token that represents an AI agent. The NFT contai
|
||||
| (IPFS/Arweave) | | History |
|
||||
+------------------+ +------------------+
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Smart Contracts
|
||||
|
||||
The core contract implements ERC-721 with extensions:
|
||||
[code]
|
||||
```solidity
|
||||
|
||||
contract AgentNFT is ERC721, ERC721URIStorage {
|
||||
struct AgentCapabilities {
|
||||
bytes32 modelHash;
|
||||
@@ -121,7 +114,8 @@ The core contract implements ERC-721 with extensions:
|
||||
) external;
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Agent Execution
|
||||
|
||||
@@ -132,8 +126,8 @@ Agents operate through a secure runtime:
|
||||
3. **Execution** : Agent runs within resource limits
|
||||
4. **State update** : Experience and state changes recorded on chain
|
||||
|
||||
```python
|
||||
|
||||
[code]
|
||||
from agent_nft import AgentRuntime, AgentNFT
|
||||
|
||||
# Load agent from NFT
|
||||
@@ -146,7 +140,8 @@ Agents operate through a secure runtime:
|
||||
# Capabilities automatically enforced
|
||||
# Experience automatically logged
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Use Cases
|
||||
|
||||
@@ -157,7 +152,8 @@ An agent trained for customer support can be sold to a new owner. The NFT transf
|
||||
### Agent Composition
|
||||
|
||||
Complex agents can be built from simpler ones:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Compose agents
|
||||
research_agent = AgentNFT.load(token_id=100)
|
||||
writing_agent = AgentNFT.load(token_id=101)
|
||||
@@ -167,14 +163,16 @@ Complex agents can be built from simpler ones:
|
||||
orchestration="sequential",
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The composite NFT references its components, enabling capability inheritance and revenue sharing.
|
||||
|
||||
### Reputation Markets
|
||||
|
||||
Agents build on-chain reputation through successful task completion. High-reputation agents command higher prices in agent marketplaces.
|
||||
[code]
|
||||
```
|
||||
|
||||
# Attestation after successful task
|
||||
await attestation_contract.attest(
|
||||
agent_id=12345,
|
||||
@@ -183,12 +181,14 @@ Agents build on-chain reputation through successful task completion. High-reputa
|
||||
evidence=task_hash,
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Agent DAOs
|
||||
|
||||
Collections of agents can be governed collectively:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Agent DAO governance
|
||||
dao = AgentDAO(agent_nfts=[100, 101, 102, 103])
|
||||
|
||||
@@ -201,14 +201,16 @@ Collections of agents can be governed collectively:
|
||||
# Token-weighted voting among agent owners
|
||||
await proposal.execute_if_passed()
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Economic Model
|
||||
|
||||
### Agent Earnings
|
||||
|
||||
Agents can earn tokens through work:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Agent receives payment for task
|
||||
await payment_contract.pay(
|
||||
agent_id=12345,
|
||||
@@ -219,12 +221,14 @@ Agents can earn tokens through work:
|
||||
# Agent balance updates on chain
|
||||
# Owner can withdraw or reinvest
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Capability Licensing
|
||||
|
||||
Agent capabilities can be licensed:
|
||||
[code]
|
||||
```solidity
|
||||
|
||||
# License model weights for limited use
|
||||
license = await nft.create_license(
|
||||
licensee=other_address,
|
||||
@@ -233,12 +237,14 @@ Agent capabilities can be licensed:
|
||||
price=50,
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Staking and Delegation
|
||||
|
||||
Agent NFT holders can stake their agents:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Stake agent in compute pool
|
||||
await staking_pool.stake(
|
||||
agent_id=12345,
|
||||
@@ -248,7 +254,8 @@ Agent NFT holders can stake their agents:
|
||||
# Earn rewards from agent work
|
||||
rewards = await staking_pool.claim_rewards(agent_id=12345)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Privacy Considerations
|
||||
|
||||
@@ -258,17 +265,17 @@ Agent NFTs balance transparency with privacy:
|
||||
* **Private** : Specific interactions, user data
|
||||
* **Selective disclosure** : Prove capabilities without revealing details
|
||||
|
||||
|
||||
|
||||
Zero-knowledge proofs enable verification without exposure:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Prove agent completed 1000+ tasks without revealing specifics
|
||||
proof = await nft.generate_proof(
|
||||
claim="task_count >= 1000",
|
||||
reveal=["task_count"],
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Roadmap
|
||||
|
||||
|
||||
@@ -33,36 +33,46 @@ The key observation: most variants share an identical base model. The behavioral
|
||||
**Paper** : arXiv:2402.10193
|
||||
|
||||
BitDelta decomposes a fine-tuned weight matrix as:
|
||||
[code]
|
||||
```
|
||||
|
||||
W_ft = W_base + Δ
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
and approximates the delta with 1-bit quantization:
|
||||
[code]
|
||||
```
|
||||
|
||||
Δ ≈ α · sign(Δ)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
where the scale factor α is the mean absolute value of the delta entries:
|
||||
[code]
|
||||
```
|
||||
|
||||
α = (1/n) Σ |Δ_ij|
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
This is a single scalar per weight matrix. The sign matrix is 1-bit per element. Total storage for the delta: n bits + 1 float32. For a 4096×4096 weight matrix, that is 16MB → 2MB. For the full zen-max 72B delta, the storage requirement drops from ~144GB to ~9GB.
|
||||
|
||||
Why does 1-bit sign quantization work? The delta values in fine-tuned LLMs follow a near-Laplace distribution centered at zero. The signs carry the directional information; the scale α captures the magnitude. The residual error:
|
||||
[code]
|
||||
```
|
||||
|
||||
ε = Δ - α · sign(Δ)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
has bounded expected squared norm:
|
||||
[code]
|
||||
```
|
||||
|
||||
E[||ε||²] ≤ (1 - 2/π) · ||Δ||² ≈ 0.36 · ||Δ||²
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
In practice (and this is the empirical surprise), the effective error on model outputs is far smaller than this bound suggests, because the residuals are uncorrelated with the task-relevant signal directions. The model’s behavioral accuracy degrades gracefully rather than catastrophically.
|
||||
|
||||
@@ -74,10 +84,9 @@ The critical implementation detail is efficiency. Reconstructing `W_ft = W_base
|
||||
2. Unpack and scale: `delta_row = alpha * sign_bits.float() * 2 - 1`
|
||||
3. Add to base weight tile in shared memory before GEMM
|
||||
|
||||
|
||||
|
||||
The result: delta reconstruction adds less than 1ms overhead per forward pass on an A100. In practice the overhead is dominated by memory bandwidth to load the sign bits, which at 1/16th the size of the base weight tensor is negligible.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import torch
|
||||
|
||||
def compress_delta(W_ft: torch.Tensor, W_base: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
||||
@@ -102,7 +111,8 @@ The result: delta reconstruction adds less than 1ms overhead per forward pass on
|
||||
'compression_ratio': full_bytes / bitdelta_bytes,
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Quality Results
|
||||
|
||||
@@ -125,10 +135,12 @@ Average behavioral retention: **99.3%**. The 0.7% average degradation is below t
|
||||
BitDelta works well when the delta is well-behaved (small, distributed, near-Laplace). Some fine-tuned checkpoints — particularly those from aggressive few-shot fine-tuning or noisy datasets — produce deltas that are large and spiky. In these cases, 1-bit quantization introduces perceptible degradation.
|
||||
|
||||
MonoSoup provides a complementary approach: instead of compressing the delta, decompose the full fine-tuned weight via SVD and keep only the top-k singular triplets:
|
||||
[code]
|
||||
```
|
||||
|
||||
W_ft ≈ U_k Σ_k V_k^T
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
where k is chosen to keep 95% of the Frobenius norm. This is not a delta compression technique — it operates on the single fine-tuned checkpoint directly. But for weak checkpoints where BitDelta degrades, MonoSoup recovers up to 8% of the lost behavioral accuracy at comparable memory cost.
|
||||
|
||||
@@ -141,17 +153,20 @@ In our pipeline: we try BitDelta first. If behavioral retention falls below 98.5
|
||||
The cloud serving stack above does not address edge deployment. A local user running zen-nano on a 16GB laptop cannot afford a delta cache for 14 variants — even at 1-bit compression, storing all nano variants would consume significant RAM.
|
||||
|
||||
K-Merge addresses this with an **online LoRA adapter pool under fixed storage budget**. The algorithm maintains a priority queue of adapters scored by utility:
|
||||
[code]
|
||||
```
|
||||
|
||||
utility(adapter_i) = request_frequency(i) × behavioral_gain(i) / storage_cost(i)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
When the budget is exceeded, the lowest-utility adapter is evicted. Utility scores are updated online using exponential decay, so recently used adapters are preferred over historical ones.
|
||||
|
||||
For a 16GB laptop with 4GB allocated to the adapter pool, K-Merge keeps 6-8 zen-nano variants hot simultaneously, with eviction latency of ~200ms to load a new adapter from local disk.
|
||||
|
||||
## Full Zen Serving Stack
|
||||
[code]
|
||||
```
|
||||
|
||||
┌──────────────────────────────┐
|
||||
│ Request Router │
|
||||
│ (model ID → variant key) │
|
||||
@@ -180,7 +195,8 @@ For a 16GB laptop with 4GB allocated to the adapter pool, K-Merge keeps 6-8 zen-
|
||||
│ (vLLM with continuous batch) │
|
||||
└──────────────────────────────┘
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The architecture keeps one base model loaded per GPU cluster. All variants share it. The delta cache fits in Redis (NVMe-backed), loading on demand in under 50ms. In practice, our top-5 variants stay hot in Redis memory; the remaining variants load from NVMe on first request.
|
||||
|
||||
|
||||
@@ -15,8 +15,6 @@ The modern scientific enterprise suffers from systemic dysfunction:
|
||||
* **Funding concentration** directs resources toward safe, incremental work
|
||||
* **Credential gatekeeping** excludes capable researchers without institutional affiliation
|
||||
|
||||
|
||||
|
||||
These are not bugs. They are features of a system optimized for the interests of incumbents, not the advancement of knowledge.
|
||||
|
||||
## A Decentralized Alternative
|
||||
@@ -51,9 +49,6 @@ Artificial intelligence research is particularly suited to decentralized coordin
|
||||
|
||||
4. **Progress can be verified.** Benchmarks and evaluations can be run trustlessly on-chain.
|
||||
|
||||
|
||||
|
||||
|
||||
## The Zen Commitment
|
||||
|
||||
Zen commits to DeSci principles:
|
||||
@@ -63,8 +58,6 @@ Zen commits to DeSci principles:
|
||||
* Governance is decentralized
|
||||
* Contributions are verifiable
|
||||
|
||||
|
||||
|
||||
We believe these principles are not merely ethical imperatives but practical necessities. Centralized AI development has produced powerful systems with opaque training, unknown biases, and concentrated control. Decentralized development offers an alternative path.
|
||||
|
||||
## Join the Movement
|
||||
|
||||
@@ -51,8 +51,6 @@ AI research particularly benefits from decentralization:
|
||||
3. **Distributed compute** : Permissionless contribution to training runs
|
||||
4. **Governance** : Community control over model behavior and deployment
|
||||
|
||||
|
||||
|
||||
At Zen, we’re building at this intersection. Our AI development follows DeSci principles: open research, transparent processes, community governance.
|
||||
|
||||
## The Path Forward
|
||||
@@ -66,8 +64,6 @@ We’re contributing to this movement through:
|
||||
* Integration with DeSci funding mechanisms
|
||||
* Tooling for reproducible AI experiments
|
||||
|
||||
|
||||
|
||||
Science advanced civilization by opening inquiry to all. DeSci extends that opening to the infrastructure of science itself.
|
||||
|
||||
* * *
|
||||
|
||||
@@ -15,38 +15,26 @@ In real-world vision-language applications, e.g., cross-modal retrieval, the lan
|
||||
|
||||
Here is an example of the search with mCLIP2. We find that it is really hard for the model to understand some concepts in Chinese, and it can only retrieve relevant items that belong to western culture.
|
||||
|
||||

|
||||
|
||||
Also, we have conducted experiments on cross-modal retrieval with the original CLIP plus machine translation. The performance significantly degrades and falls far back behind our Chinese CLIP. This is also an evidence to support why we need a language-specific CLIP.
|
||||
|
||||
## Method
|
||||
|
||||
In general, we follow the setups of the original CLIP, and we propose a two-stage pretraining method that shows better performance than training from scratch. We believe this is a more cost-effective way to transfer CLIP to another language.
|
||||
|
||||

|
||||
|
||||
In the first stage, we initialize the two towers with pretrained models, which are the vision encoder of [CLIP](https://github.com/ymcui/Chinese-BERT-wwm), e.g., ViT-B, ResNet, etc., and Chinese RoBERTa [RoBERTA-wwm-Chinese](https://github.com/ymcui/Chinese-BERT-wwm). We freeze the image encoder and contrastively tune the language encoder that maps its representation to the output space of CLIP vision encoder. In the second stage, we unlock the vision encoder and contrastively tune the two towers so that the vision encoder can learn to model the distribution of the images of Chinese data.
|
||||
|
||||
To make this research reproducible, we mostly use the public datasets for pretraining, including the part marked with “zh” in LAION-5B3, Wukong dataset4, the translated data from Visual Genome and MSCOCO, etc. The total amount of the image-text pairs reaches 200 million.
|
||||
|
||||
We released 5 versions of Chinese CLIP, including ResNet-50, ViT-B/16, ViT-L/14, ViT-L/14 @336px, and ViT-H/14. The statistics are listed below.
|
||||
|
||||

|
||||
|
||||
## Experiments
|
||||
|
||||
The experiments are conducted on 3 cross-modal retrieval datasets, including the Chinese native dataset [MUGE](https://tianchi.aliyun.com/muge), and the English-native datasets (which means the images and texts are not from the Chinese websites) Flickr30K-CN and COCO-CN. On all datasets, Chinese CLIP performs the best, and its gap with the previous best models in MUGE is much larger than those in the other datasets. This demonstrates that our method is contributive to building a language specific CLIP model that can perform much better on native datasets.
|
||||
|
||||

|
||||
|
||||
We also try Chinese CLIP on zero-shot image classification, and we participate in the ELEVATER benchmark5 by translating all labels and prompts to Chinese manually. Results show that Chinese CLIP can also achieve a competitive performance in the English-native benchmark.
|
||||
|
||||

|
||||
|
||||
For the ablation, it can be found that in comparison with training from scratch, the two-stage pretraining method demonstrates much better performance, and the second-stage pretraining can further level up the model performance in cross-modal retrieval.
|
||||
|
||||

|
||||
|
||||
#### Ablation studies.
|
||||
|
||||
## Limitations and Future Work
|
||||
|
||||
@@ -12,8 +12,6 @@ author: "Zen LM Team"
|
||||
|
||||
The advent of advanced programming tools, which harnesses the power of large language models (LLMs), has significantly enhanced programmer productivity and accuracy. Notwithstanding these advancements, dominant coding assistants like Github Copilot, built upon proprietary LLMs, pose notable challenges in terms of cost, privacy, security, and potential copyright infringement. Recognizing the imperative for a more transparent and accessible alternative, the open-source community has embarked on a concerted endeavor to develop open codeLLMs. This initiative has already given rise to several promising open-source models, including StarCoder2, CodeLlama, and DeepSeek-Coder, offering a path forward, albeit one that necessitates continued refinement.
|
||||
|
||||

|
||||
|
||||
Today, we are delighted to introduce a new member of the Qwen1.5 open-source family, the CodeQwen1.5-7B, a specialized codeLLM built upon the Qwen1.5 language model. CodeQwen1.5-7B has been pretrained with around 3 trillion tokens of code-related data. It supports an extensive repertoire of 92 programming languages, and it exhibits exceptional capacity in long-context understanding and generation with the ability to process information of 64K tokens. In terms of performance, CodeQwen1.5 demonstrates impressive capabilities in basic code generation, long-context modeliing, code editation and SQL. We believe this model can significantly enhance developer productivity and streamline software development workflows within diverse technological environments.
|
||||
|
||||
# CodeQwen is a Basic Coder
|
||||
@@ -35,44 +33,30 @@ DeepSeek-Coder-Instruct| 6.7B| 78.6| 70.1| 73.2| 63.4| 65.4
|
||||
|
||||
In addition to the widely recognized HumanEval and MBPP benchmarks, we explored LiveCodeBench. This benchmark assesses code performance by introducing fresh challenges sourced from coding competitions such as LeetCode, AtCoder, and CodeForces over time. Our evaluation of CodeQwen1.5 on LiveCodeBench spanned from September 1, 2023, to April 1, 2024. The findings indicate that CodeQwen1.5 ranks among the top open-access models currently available. Note: it is possible that the inclusion of LeetCode data in our pretraining corpus may contribute to the performance in LiveCodeBench.
|
||||
|
||||

|
||||
|
||||
The evaluations mentioned primarily revolve around Python capabilities; however, CodeQwen1.5 is not merely a Python specialist but also an expert across multiple programming languages. We conducted a comprehensive evaluation of CodeQwen1.5 in the eight mainstream languages featured in MultiPL-E, including Python, C++, Java, PHP, TypeScript, C#, Bash, and JavaScript. The results highlight the exceptional programming capabilities of CodeQwen1.5.
|
||||
|
||||

|
||||
|
||||
# CodeQwen is a Long Context Coder
|
||||
|
||||
Long context capability is crucial for code LLMs, serving as the core skill for understanding repository-level code and becoming a code agent. However, current code models still have very limited support for length, which hinders their potential for practical application. CodeQwen1.5 aims to further advance the progress of open-source code models in long context modeling. To achieve this, we have collected and constructed long sequence code data at the repository level for pre-training. Through careful data proportioning and organization, we have enabled it to support input lengths of up to 64K tokens.
|
||||
|
||||
**Evaluation 1** : We collected high-quality repo from GitHub Trending repositories on 2024-3-28 that were not included in CodeQwen1.5’s training data to observe the effectiveness of long context modeling. The following figure demonstrates that as the sequence length increases, CodeQwen1.5’s Perplexity (PPL) still manages to maintain a downward trend.
|
||||
|
||||

|
||||
|
||||
**Evaluation 2** : We created a synthetic task called `Needle in the Code`, inspired by popular long-context evaluations in the text domain. In this task, we inserted a very simple custom function at various positions within a longer codebase (we chose Megatron to honor its contributions to open-source LLMs!) and tested whether the model could replicate this function at the end of the codebase. The figure below shows that CodeQwen is capable of successfully completing this task within a 64k length range.
|
||||
|
||||

|
||||
|
||||
Both Evaluation 1 and Evaluation 2 serve as initial and foundational assessments. For the Chat model, we aim to evaluate its long context capabilities with more practical tasks. However, our objective is to examine the Chat model’s capability to handle long contexts through more pragmatic, real-world evaluation tasks.
|
||||
|
||||
**Evaluation 3** : SWE Bench is a benchmark designed to assess the ability of Large Language Models (LLMs) or agents to tackle practical software development challenges. It presents contestants with a code repository and an associated issue, tasking them with generating a commit patch that resolves the issue effectively. The benchmark uniquely emphasizes the long-context processing capabilities of code LLMs, necessitating both deep comprehension of the given codebase and the generation of extensive, unit-test-passing code.
|
||||
|
||||

|
||||
|
||||
Currently, participants in the SWE Bench competition predominantly are proprietary models. We introduce CodeQwen1.5 as an open-source model entry. Despite achieving a score of 0.89, CodeQwen1.5 surpasses ChatGPT-3.5, demonstrating the nascent yet promising competitiveness of open-source code models against their proprietary counterparts.
|
||||
|
||||
# CodeQwen is a Debugger
|
||||
|
||||
An effective code assistant must demonstrate proficiency in both generating code in response to given specifications and adeptly modifying or debugging existing code to accommodate evolving requirements or rectify errors. In assessing CodeQwen1.5’s proficiency in code modification tasks, we concentrated our evaluation on the CodeEditorBench suite, encompassing four distinct dimensions: Debugging, Translation, Language Switching, and Code Polishing. The results indicate that CodeQwen1.5 achieves the SOTA performance at the 7 billion parameter scale.
|
||||
|
||||

|
||||
|
||||
# CodeQwen is a SQLer
|
||||
|
||||
CodeQwen1.5 serves as a solution to bridge the gap between non-programming professionals and efficient data interaction. It alleviates the steep learning curve associated with SQL by enabling users without coding expertise to query databases through natural language. We evaluated CodeQwen1.5-Chat’s performance on two popular Text-to-SQL benchmarks, Spider and Bird. Experimental results pose CodeQwen1.5 a second position close to GPT-4 (results come from DIN-SQL, a SOTA prompting method). This outstanding performance is attributed to the utilization of synthetic data throughout both pre-training and fine-tuning stages. Synthetic data, characterized by its scalability, verifiability, and variety, emerges as a compelling area for future research due to its proven effectiveness in enhancing CodeQwen1.5’s SQL capabilities.
|
||||
|
||||

|
||||
|
||||
# Develop with CodeQwen1.5
|
||||
|
||||
CodeQwen1.5 is part of the Qwen1.5 open-source family. We advise you to read our blog for [Qwen1.5](https://qwenlm.github.io/blog/qwen1.5/) to figure out the usages with Transformers, vLLM, llama.cpp, Ollama, etc.
|
||||
@@ -82,7 +66,8 @@ CodeQwen1.5 is part of the Qwen1.5 open-source family. We advise you to read our
|
||||
We have released CodeQwen1.5-7B and CodeQwen1.5-7B-Chat, an open and versatile code LLM. The models are intended to aid progress in code assistance and code agents, benefiting the research community. We’ll keep investing heavily in smart code development, with the ultimate goal of creating AI programmers.
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{codeqwen1.5,
|
||||
title = {Code with CodeQwen1.5},
|
||||
url = {https://qwenlm.github.io/blog/codeqwen1.5/},
|
||||
@@ -91,4 +76,5 @@ We have released CodeQwen1.5-7B and CodeQwen1.5-7B-Chat, an open and versatile c
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -26,14 +26,17 @@ We use four papers from late 2024 / early 2025, each addressing a different laye
|
||||
|
||||
The simplest insight in continual learning is that not all parameter directions are equally important. The top singular vectors of the base model’s weight matrices encode the most “load-bearing” representations — the ones responsible for broad capabilities. Fine-tuning along those directions is how forgetting happens.
|
||||
|
||||
OPLoRA adds a projection step after each LoRA update. Let `Δ = BA` be the standard low-rank update (B ∈ ℝ^{d×r}, A ∈ ℝ^{r×k}). Before applying this update, we project it onto the orthogonal complement of the base model’s top singular subspace:
|
||||
[code]
|
||||
OPLoRA adds a projection step after each LoRA update. Let `Δ = BA` be the standard low-rank update (B ∈ ℝ^{d×r}, A ∈ ℝ^{r×k}). Before applying this update, we project it onto the orthogonal complement of the base model’s top singular subspace:
|
||||
```
|
||||
|
||||
Δ_orth = Δ - V_k V_k^T Δ
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
where `V_k` are the top-k right singular vectors of the pretrained weight matrix W₀. The result: updates flow only through directions that the base model does not heavily use. New knowledge accumulates in the null space of the existing representation.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import torch
|
||||
|
||||
def oplora_project(delta: torch.Tensor, base_weight: torch.Tensor, k: int = 64) -> torch.Tensor:
|
||||
@@ -63,7 +66,8 @@ where `V_k` are the top-k right singular vectors of the pretrained weight matrix
|
||||
delta_orth = delta - self.V_k @ (self.V_k.T @ delta)
|
||||
return x @ (self.base_weight + delta_orth).T
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The k hyperparameter controls the trade-off: larger k preserves more of the base model but leaves less room for new knowledge. We use k=64 for most Zen fine-tuning passes.
|
||||
|
||||
@@ -74,10 +78,12 @@ The k hyperparameter controls the trade-off: larger k preserves more of the base
|
||||
Replay-based continual learning maintains a buffer of old examples and mixes them into each training batch. The problem is buffer efficiency: most buffered examples are easy for the current model and contribute nothing. SuRe fixes this with surprise-based prioritization.
|
||||
|
||||
The surprise score for a token sequence x_t is simply the negative log-likelihood under the current model:
|
||||
[code]
|
||||
```
|
||||
|
||||
r_t = -log p_θ(x_t | x_{<t})
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
High surprise means the current model is uncertain about this sequence — it is more likely to be a case where forgetting is occurring. SuRe preferentially replays high-surprise examples, maximizing the utility of a fixed replay budget.
|
||||
|
||||
@@ -86,16 +92,17 @@ Beyond replay prioritization, SuRe introduces a **dual EMA** (Exponential Moving
|
||||
* **Fast LoRA** θ_f: high learning rate, adapts quickly to new data
|
||||
* **Slow LoRA** θ_s: low learning rate, tracks long-run behavioral drift
|
||||
|
||||
|
||||
|
||||
At merge time, the two adapters are combined:
|
||||
[code]
|
||||
```
|
||||
|
||||
θ_merged = (1-α)θ_s + αθ_f
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
where α is a schedule parameter (typically 0.3). The slow adapter acts as a stability anchor while the fast adapter absorbs new signal. On the LNT (Learn-Not-To-Forget) benchmark, SuRe delivers +5 accuracy points over standard replay.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import heapq
|
||||
from collections import deque
|
||||
from dataclasses import dataclass, field
|
||||
@@ -144,7 +151,8 @@ where α is a schedule parameter (typically 0.3). The slow adapter acts as a sta
|
||||
for k in theta_fast
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
In practice we run SuRe with a buffer of 50K sequences, sampling 512 high-surprise examples per training batch alongside 512 new-data examples. The buffer is refreshed every 1K steps as model NLL scores shift.
|
||||
|
||||
@@ -157,15 +165,18 @@ OPLoRA and SuRe handle forgetting during training. OPCM handles forgetting durin
|
||||
Naive merging (simple average of adapter weights) produces interference between tasks. OPCM applies sequential orthogonal projection: when merging adapter k+1 into the accumulated projection matrix, it removes the component that interferes with previously merged adapters.
|
||||
|
||||
The update rule for the projection matrix P is:
|
||||
[code]
|
||||
```
|
||||
|
||||
P_{k+1} = P_k - P_k φ_k^T (φ_k P_k φ_k^T)^{-1} φ_k P_k
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
where φ_k is the gradient direction (or adapter weight direction) of the k-th task. This is the standard Gram-Schmidt orthogonalization applied iteratively to the task gradient subspace.
|
||||
|
||||
The memory cost is O(|θ|) — a single projection matrix regardless of the number of tasks. This is a significant improvement over methods that cache full gradient histories. On sequential merge benchmarks, OPCM achieves 5-8% better retention than simultaneous averaging.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import torch
|
||||
|
||||
class OPCMStep:
|
||||
@@ -191,7 +202,8 @@ The memory cost is O(|θ|) — a single projection matrix regardless of the numb
|
||||
self.P = self.P - outer
|
||||
return Pp
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The key insight is ordering: merge tasks from largest to smallest gradient norm. This ensures the most influential task anchors the subspace, and subsequent tasks fill in orthogonal directions.
|
||||
|
||||
@@ -212,7 +224,8 @@ For Zen, we run Youtu-Agent as a lightweight inference-time layer: the ledger is
|
||||
## How These Four Stack for Zen
|
||||
|
||||
The four techniques operate at different timescales and are composable:
|
||||
[code]
|
||||
```
|
||||
|
||||
1. OPLoRA base training
|
||||
└─ All Zen fine-tuning uses OPLoRA projection
|
||||
Prevents overwriting base model subspace
|
||||
@@ -229,7 +242,8 @@ The four techniques operate at different timescales and are composable:
|
||||
└─ Experience ledger enables training-free behavioral adaptation
|
||||
Zero weight updates, ~15ms overhead
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
In production, layers 1-3 run during scheduled training passes (nightly for Zen nano/eco, weekly for larger models). Layer 4 is always active.
|
||||
|
||||
|
||||
@@ -17,8 +17,6 @@ Current AI training is dominated by:
|
||||
* **High costs** : Training GPT-4 class models costs $100M+
|
||||
* **Geographic concentration** : Most clusters are in a few regions
|
||||
|
||||
|
||||
|
||||
This concentration creates risks:
|
||||
|
||||
1. **Access barriers** : Only well-funded organizations can train frontier models
|
||||
@@ -26,14 +24,13 @@ This concentration creates risks:
|
||||
3. **Regulatory exposure** : One jurisdiction can impact global AI development
|
||||
4. **Vendor lock-in** : Switching costs are enormous
|
||||
|
||||
|
||||
|
||||
## The Zoo Compute Network
|
||||
|
||||
The Zoo Compute Network aggregates distributed GPU resources into a unified training substrate. Anyone with suitable hardware can contribute. Anyone can access the aggregated compute.
|
||||
|
||||
### Architecture
|
||||
[code]
|
||||
```
|
||||
|
||||
+------------------+ +------------------+ +------------------+
|
||||
| Compute Node 1 | | Compute Node 2 | | Compute Node N |
|
||||
| (8x H100) | | (4x A100) | | (16x H100) |
|
||||
@@ -56,7 +53,8 @@ The Zoo Compute Network aggregates distributed GPU resources into a unified trai
|
||||
| - Result retrieval |
|
||||
+-----------------------------------------------------------------------+
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Node Requirements
|
||||
|
||||
@@ -77,7 +75,8 @@ The coordination layer handles distributed training logistics:
|
||||
**Task Scheduling**
|
||||
|
||||
Jobs are divided into tasks and assigned to available nodes:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Job submission
|
||||
job = ComputeJob(
|
||||
model_config=model_config,
|
||||
@@ -88,7 +87,8 @@ Jobs are divided into tasks and assigned to available nodes:
|
||||
|
||||
job_id = await network.submit(job)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The scheduler optimizes for:
|
||||
|
||||
@@ -97,8 +97,6 @@ The scheduler optimizes for:
|
||||
* Cost efficiency (use cheapest suitable nodes)
|
||||
* Reliability (distribute across failure domains)
|
||||
|
||||
|
||||
|
||||
**Gradient Aggregation**
|
||||
|
||||
Distributed training requires gradient synchronization. The network supports:
|
||||
@@ -107,14 +105,13 @@ Distributed training requires gradient synchronization. The network supports:
|
||||
* Point-to-point for pipeline/tensor parallelism
|
||||
* Asynchronous updates for fault tolerance
|
||||
|
||||
|
||||
|
||||
Aggregation happens through a tree topology that minimizes bandwidth usage.
|
||||
|
||||
**Checkpoint Management**
|
||||
|
||||
Training state is continuously checkpointed:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Automatic checkpointing
|
||||
checkpoint_config = CheckpointConfig(
|
||||
interval=1000, # steps
|
||||
@@ -122,7 +119,8 @@ Training state is continuously checkpointed:
|
||||
redundancy=3,
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Checkpoints are content-addressed and distributed. Training can resume from any node.
|
||||
|
||||
@@ -136,16 +134,12 @@ Providers stake ZEN tokens as collateral and earn rewards for:
|
||||
* Computation completed (work reward)
|
||||
* Network contribution (bandwidth bonus)
|
||||
|
||||
|
||||
|
||||
Slashing occurs for:
|
||||
|
||||
* Downtime during committed periods
|
||||
* Incorrect computation (detected via verification)
|
||||
* Bandwidth violations
|
||||
|
||||
|
||||
|
||||
Expected returns: 15-25% APY on staked tokens plus hardware depreciation coverage.
|
||||
|
||||
**For Users**
|
||||
@@ -168,8 +162,6 @@ Prices are market-determined through ongoing auctions. Users can specify maximum
|
||||
* Security audits
|
||||
* Community grants
|
||||
|
||||
|
||||
|
||||
### Verification
|
||||
|
||||
How do we know compute was done correctly?
|
||||
@@ -177,10 +169,12 @@ How do we know compute was done correctly?
|
||||
**Sampling-Based Verification**
|
||||
|
||||
Random subsets of computation are re-run by verifiers. Discrepancies trigger investigation:
|
||||
[code]
|
||||
```
|
||||
|
||||
P(detection) = 1 - (1 - sample_rate)^n
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
With 1% sampling and 100 steps, detection probability is 63%. With 5% sampling, it’s 99.4%.
|
||||
|
||||
@@ -204,8 +198,6 @@ We’ve run several training jobs on the network:
|
||||
* **Cost** : 21,000 ZEN (~$42,000)
|
||||
* **Efficiency** : 89% of centralized equivalent
|
||||
|
||||
|
||||
|
||||
### Embedding Model Training
|
||||
|
||||
* **Duration** : 5 days
|
||||
@@ -214,8 +206,6 @@ We’ve run several training jobs on the network:
|
||||
* **Cost** : 2,400 ZEN (~$4,800)
|
||||
* **Efficiency** : 94% of centralized equivalent
|
||||
|
||||
|
||||
|
||||
Efficiency losses come from coordination overhead and network heterogeneity. Ongoing optimizations are closing the gap.
|
||||
|
||||
## Joining the Network
|
||||
@@ -228,8 +218,6 @@ Efficiency losses come from coordination overhead and network heterogeneity. Ong
|
||||
4. **Benchmark** : Complete verification benchmarks
|
||||
5. **Operate** : Maintain uptime and connectivity
|
||||
|
||||
|
||||
|
||||
Documentation: docs.zoo.ngo/compute/providers
|
||||
|
||||
### As a User
|
||||
@@ -238,8 +226,8 @@ Documentation: docs.zoo.ngo/compute/providers
|
||||
2. **Fund account** : Acquire ZEN tokens
|
||||
3. **Submit jobs** : Use API or CLI
|
||||
|
||||
```python
|
||||
|
||||
[code]
|
||||
from zoo_compute import Client
|
||||
|
||||
client = Client(api_key="...")
|
||||
@@ -251,7 +239,8 @@ Documentation: docs.zoo.ngo/compute/providers
|
||||
|
||||
await job.wait()
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Documentation: docs.zoo.ngo/compute/users
|
||||
|
||||
|
||||
@@ -25,14 +25,17 @@ This is not a training instability — it is a symmetry problem. Identical initi
|
||||
**Paper** : arXiv:2502.19261
|
||||
|
||||
Drop-Upcycling solves the symmetry problem by deliberately damaging each expert’s initialization in a structured way. For each expert i, randomly select p% of the FFN rows and reinitialize them from a normal distribution:
|
||||
[code]
|
||||
```
|
||||
|
||||
w_j^(i) = N(0, σ²) if j ∈ dropped_rows(i)
|
||||
w_j^(i) = w_j^dense otherwise
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The dropped set is different for each expert (sampled independently). This breaks the symmetry: experts start from the same functional foundation but with different “holes” in their weight matrices.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from typing import List
|
||||
@@ -91,9 +94,10 @@ The dropped set is different for each expert (sampled independently). This break
|
||||
'down_proj': drop_upcycle(dense_block.down_proj, n_experts, drop_rate),
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
The `drop_rate` hyperparameter is the key dial. Too low (< 5%) and experts remain too correlated. Too high (> 30%) and you lose the functional initialization benefit — the expert essentially starts from random weights. The sweet spot we found empirically: **8-12% for general language models, 15% for code-specialized models** (where more aggressive diversity is needed to separate syntax vs. semantics experts).
|
||||
```
|
||||
|
||||
The `drop_rate` hyperparameter is the key dial. Too low (< 5%) and experts remain too correlated. Too high (> 30%) and you lose the functional initialization benefit — the expert essentially starts from random weights. The sweet spot we found empirically: **8-12% for general language models, 15% for code-specialized models** (where more aggressive diversity is needed to separate syntax vs. semantics experts).
|
||||
|
||||
## Training Dynamics: Implicit Specialization Signal
|
||||
|
||||
@@ -106,8 +110,6 @@ This is the **implicit specialization signal** : experts do not specialize by de
|
||||
* Intact experts (low drop rate) converge toward high-frequency, syntactic functions
|
||||
* Heavily-dropped experts develop novel representations for rare or complex tokens
|
||||
|
||||
|
||||
|
||||
The dense-to-MoE transition effectively turns a capability gap (some experts start worse) into a specialization signal (those experts become domain-specific).
|
||||
|
||||
## Results at Scale
|
||||
@@ -119,8 +121,6 @@ On the primary benchmark suite (comparing Drop-Upcycled MoE vs. MoE trained from
|
||||
* **HumanEval** : 68.2 vs. 65.1 — Drop-Upcycling is better here because code has cleaner specialization axes
|
||||
* **Training efficiency** : 4x speedup to target quality vs. from-scratch MoE
|
||||
|
||||
|
||||
|
||||
The 1/4 FLOP claim requires context: the dense checkpoint training cost is amortized. If you already have the dense model (which you do, because you trained it first), the incremental cost to get an MoE is roughly 1/4 of a from-scratch MoE run. The total cost (dense + MoE) is higher than from-scratch, but for organizations that already have dense checkpoints — which is everyone — the marginal cost argument is what matters.
|
||||
|
||||
## Zen MoDE: Three Scales of Application
|
||||
@@ -157,8 +157,6 @@ Training a 30B MoE requires careful memory management. We use Q-GaLore (Quantize
|
||||
* Quantize the projected gradients to INT8 before accumulation
|
||||
* Result: 50% memory reduction vs. standard LoRA, with +5.19 MMLU points vs. QLoRA on equivalent compute
|
||||
|
||||
|
||||
|
||||
The memory savings matter because upcycling requires loading both the dense checkpoint (for initialization) and the growing MoE checkpoint (for training) simultaneously. Q-GaLore makes this tractable on 8×A100 80GB configurations where it would otherwise OOM.
|
||||
|
||||
## Research Frontier: Progressive Router Pruning
|
||||
|
||||
@@ -18,17 +18,17 @@ We investigate what happens when we scale embedding dimensions to 7680—ten tim
|
||||
|
||||
### Capacity Arguments
|
||||
|
||||
A $d$-dimensional embedding space can represent $\mathcal{O}(e^d)$ nearly-orthogonal vectors. For semantic search, we want documents with different meanings to map to different regions. Higher dimensions provide more room.
|
||||
A $d$-dimensional embedding space can represent $\mathcal{O}(e^d)$ nearly-orthogonal vectors. For semantic search, we want documents with different meanings to map to different regions. Higher dimensions provide more room.
|
||||
|
||||
### Information-Theoretic View
|
||||
|
||||
Consider a corpus of $N$ documents, each with entropy $H$ bits. A $d$-dimensional float32 embedding stores $32d$ bits. For lossless encoding:
|
||||
|
||||
$$32d \geq N \cdot H$$
|
||||
`32d \geq N \cdot H`
|
||||
|
||||
For a corpus of 1 billion documents with 100 bits of effective information each, we need:
|
||||
|
||||
$$d \geq \frac{10^9 \cdot 100}{32} \approx 3 \times 10^9$$
|
||||
`d \geq \frac\{10^9 \cdot 100\}\{32\} \approx 3 \times 10^9`
|
||||
|
||||
Clearly, embeddings are lossy compression. But higher dimensions reduce the loss.
|
||||
|
||||
@@ -41,8 +41,6 @@ Retrieval quality on our internal benchmarks plateaued around:
|
||||
* 3072 dimensions: 83% recall@10
|
||||
* 7680 dimensions: 87% recall@10
|
||||
|
||||
|
||||
|
||||
Diminishing returns set in, but gains persist well beyond conventional wisdom.
|
||||
|
||||
## Training High-Dimensional Embeddings
|
||||
@@ -50,10 +48,12 @@ Diminishing returns set in, but gains persist well beyond conventional wisdom.
|
||||
### Architecture
|
||||
|
||||
We use a standard transformer encoder with a projection head:
|
||||
[code]
|
||||
```
|
||||
|
||||
Input --> Transformer(L=12, H=768) --> Pool --> Linear(768, 7680) --> Normalize
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The projection head maps from the transformer’s hidden dimension to the embedding space. This decouples representation capacity from compute requirements.
|
||||
|
||||
@@ -61,7 +61,7 @@ The projection head maps from the transformer’s hidden dimension to the embedd
|
||||
|
||||
We train with InfoNCE loss over batches of (query, positive, negatives):
|
||||
|
||||
$$\mathcal{L} = -\log \frac{\exp(q \cdot p^+ / \tau)}{\sum_{i} \exp(q \cdot p_i / \tau)}$$
|
||||
`\mathcal\{L\} = -\log \frac\{\exp(q \cdot p^+ / \tau)\}\{\sum_\{i\} \exp(q \cdot p_i / \tau)\}`
|
||||
|
||||
With temperature $\tau = 0.01$ for high-dimensional spaces (lower than typical).
|
||||
|
||||
@@ -73,8 +73,6 @@ High-dimensional spaces require harder negatives to provide gradient signal. Our
|
||||
2. Filter to exclude true positives
|
||||
3. Sample negatives weighted by similarity (harder = more likely)
|
||||
|
||||
|
||||
|
||||
This curriculum focuses training on the decision boundary.
|
||||
|
||||
## Practical Considerations
|
||||
@@ -83,7 +81,7 @@ This curriculum focuses training on the decision boundary.
|
||||
|
||||
7680-dimensional float32 embeddings require 30KB per vector. For 1 billion documents:
|
||||
|
||||
$$10^9 \times 30\text{KB} = 30\text{TB}$$
|
||||
`10^9 \times 30\text\{KB\} = 30\text\{TB\}`
|
||||
|
||||
This is substantial but manageable with modern storage.
|
||||
|
||||
@@ -157,16 +155,12 @@ For the query “What causes inflation?”, nearest neighbors at different dimen
|
||||
2. How does inflation work? (similar query)
|
||||
3. Inflation rates by country (tangential)
|
||||
|
||||
|
||||
|
||||
**7680 dimensions:**
|
||||
|
||||
1. Inflation is caused by… (direct answer)
|
||||
2. The primary drivers of inflation include… (direct answer)
|
||||
3. Central bank policies affect inflation through… (relevant detail)
|
||||
|
||||
|
||||
|
||||
Higher dimensions better distinguish queries from answers.
|
||||
|
||||
## Recommendations
|
||||
@@ -178,8 +172,6 @@ Based on our experiments:
|
||||
3. **Invest in hard negative mining** to realize the benefits of capacity
|
||||
4. **Benchmark on your data** —gains vary by domain
|
||||
|
||||
|
||||
|
||||
Conventional embedding sizes are conventions, not laws. Question them.
|
||||
|
||||
* * *
|
||||
|
||||
@@ -19,8 +19,6 @@ Current language models operate in bounded context windows. Information from pas
|
||||
3. **No learning** : Agents don’t improve from experience within deployment
|
||||
4. **Trust gap** : Users can’t verify what the agent “remembers”
|
||||
|
||||
|
||||
|
||||
## Experience Ledgers
|
||||
|
||||
An experience ledger is an append-only log of agent experiences with cryptographic attestation. Think of it as a blockchain for agent memory, but optimized for AI workloads.
|
||||
@@ -36,13 +34,15 @@ An experience ledger is an append-only log of agent experiences with cryptograph
|
||||
**Hierarchical summarization** : Raw experiences are continuously summarized at multiple abstraction levels. Agents can navigate from high-level patterns to specific instances.
|
||||
|
||||
### Architecture
|
||||
[code]
|
||||
```
|
||||
|
||||
Raw Experience -> Embedding -> Index -> Summary Layer -> Abstract Layer
|
||||
| | | | |
|
||||
v v v v v
|
||||
[Ledger] [Vector DB] [Search] [Compression] [Reasoning]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Each layer serves a different purpose:
|
||||
|
||||
@@ -52,8 +52,6 @@ Each layer serves a different purpose:
|
||||
* **Summary layer** : Compressed representations
|
||||
* **Abstract layer** : High-level patterns and beliefs
|
||||
|
||||
|
||||
|
||||
## Implementation
|
||||
|
||||
We’ve built a reference implementation using:
|
||||
@@ -63,8 +61,6 @@ We’ve built a reference implementation using:
|
||||
* **Indexing** : HNSW vectors with metadata filtering
|
||||
* **Summarization** : Hierarchical abstractive compression
|
||||
|
||||
|
||||
|
||||
The system maintains consistency between layers. When raw experiences update, summaries regenerate. When summaries change, abstractions refresh.
|
||||
|
||||
## Use Cases
|
||||
@@ -90,8 +86,6 @@ Persistent memory raises legitimate privacy concerns. Our design addresses these
|
||||
* **Cryptographic deletion** : Encrypted entries can be made unreadable
|
||||
* **Audit logs** : All access is recorded
|
||||
|
||||
|
||||
|
||||
## What’s Next
|
||||
|
||||
We’re releasing the experience ledger specification and reference implementation under Apache 2.0. Initial integration with Zen models comes next quarter.
|
||||
|
||||
@@ -15,8 +15,6 @@ Federated learning promises to train models on distributed data without centrali
|
||||
* **Data heterogeneity** causes convergence problems
|
||||
* **Byzantine participants** can poison the model
|
||||
|
||||
|
||||
|
||||
We present techniques that mitigate these tradeoffs.
|
||||
|
||||
## Our Approach
|
||||
@@ -25,18 +23,19 @@ We present techniques that mitigate these tradeoffs.
|
||||
|
||||
Standard gradient clipping uses a fixed threshold $C$:
|
||||
|
||||
$$g_i^{clipped} = g_i \cdot \min\left(1, \frac{C}{|g_i|}\right)$$
|
||||
`g_i^\{clipped\} = g_i \cdot \min\left(1, \frac\{C\}\{|g_i|\}\right)`
|
||||
|
||||
This destroys information when gradients naturally vary in magnitude across layers and training phases. Our adaptive approach learns per-layer, per-phase thresholds:
|
||||
|
||||
$$C_{l,t} = \alpha \cdot \text{median}(|g_{l,1:t}|) + \beta \cdot \text{std}(|g_{l,1:t}|)$$
|
||||
`C_\{l,t\} = \alpha \cdot \text\{median\}(|g_\{l,1:t\}|) + \beta \cdot \text\{std\}(|g_\{l,1:t\}|)`
|
||||
|
||||
This preserves gradient structure while bounding sensitivity.
|
||||
|
||||
### Hierarchical Aggregation
|
||||
|
||||
Instead of flat aggregation across all participants, we organize contributors into hierarchical clusters:
|
||||
[code]
|
||||
```
|
||||
|
||||
Global Model
|
||||
|
|
||||
+------------+------------+
|
||||
@@ -47,7 +46,8 @@ Instead of flat aggregation across all participants, we organize contributors in
|
||||
| | | | | |
|
||||
n1 n2 n3 n4 n5 n6
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Benefits:
|
||||
|
||||
@@ -55,13 +55,11 @@ Benefits:
|
||||
2. **Natural trust boundaries** : Clusters can enforce local policies
|
||||
3. **Improved convergence** : Intra-cluster data is more homogeneous
|
||||
|
||||
|
||||
|
||||
### Byzantine-Resilient Selection
|
||||
|
||||
We filter malicious updates using coordinate-wise median aggregation with outlier detection:
|
||||
|
||||
$$\hat{g}_j = \text{median}{g_{i,j} : d(g_{i,j}, \mu_j) < k \cdot \sigma_j}$$
|
||||
`\hat\{g\}_j = \text\{median\}\{g_\{i,j\} : d(g_\{i,j\}, \mu_j) < k \cdot \sigma_j\}`
|
||||
|
||||
For each coordinate $j$, we exclude updates more than $k$ standard deviations from the median. This provides Byzantine resilience without requiring honest majority assumptions.
|
||||
|
||||
@@ -81,7 +79,7 @@ Our approach achieves near-baseline accuracy with stronger privacy guarantees an
|
||||
|
||||
Under standard smoothness and convexity assumptions, our hierarchical aggregation converges at rate:
|
||||
|
||||
$$\mathbb{E}[F(\bar{w}_T) - F(w^*)] \leq \mathcal{O}\left(\frac{1}{\sqrt{T}} + \frac{\sigma^2}{K} + \frac{\delta^2}{H}\right)$$
|
||||
`\mathbb\{E\}[F(\bar\{w\}_T) - F(w^*)] \leq \mathcal\{O\}\left(\frac\{1\}\{\sqrt\{T\}\} + \frac\{\sigma^2\}\{K\} + \frac\{\delta^2\}\{H\}\right)`
|
||||
|
||||
Where:
|
||||
|
||||
@@ -91,14 +89,13 @@ Where:
|
||||
* $\sigma^2$ = gradient variance
|
||||
* $\delta^2$ = inter-cluster heterogeneity
|
||||
|
||||
|
||||
|
||||
The hierarchical structure reduces the effective heterogeneity term.
|
||||
|
||||
## Implementation
|
||||
|
||||
Our reference implementation is available under Apache 2.0:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from zen_fl import FederatedTrainer, AdaptiveClipping, HierarchicalAggregator
|
||||
|
||||
trainer = FederatedTrainer(
|
||||
@@ -110,7 +107,8 @@ Our reference implementation is available under Apache 2.0:
|
||||
|
||||
trainer.train(participants, rounds=500)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Deployment Considerations
|
||||
|
||||
@@ -121,8 +119,6 @@ Real-world federated learning faces practical challenges:
|
||||
3. **Compute heterogeneity** : Adaptive local steps match device capabilities
|
||||
4. **Bandwidth limits** : Gradient compression reduces communication
|
||||
|
||||
|
||||
|
||||
Our implementation addresses each through configurable policies.
|
||||
|
||||
## Conclusion
|
||||
|
||||
@@ -17,12 +17,11 @@ Traditional ML training follows a simple pattern: collect data, aggregate it cen
|
||||
* **Trust requirements** : Data holders must trust the training party
|
||||
* **Single points of failure** : Central aggregation creates vulnerabilities
|
||||
|
||||
|
||||
|
||||
## Federated Learning Basics
|
||||
|
||||
Federated learning inverts the pattern. Instead of bringing data to the model, we bring the model to the data.
|
||||
[code]
|
||||
```
|
||||
|
||||
+-----------+
|
||||
| Central |
|
||||
| Server |
|
||||
@@ -35,7 +34,8 @@ Federated learning inverts the pattern. Instead of bringing data to the model, w
|
||||
| (Data A) | | (Data B) | | (Data N) |
|
||||
+-----------+ +-----------+ +-----------+
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
1. Central server distributes model weights
|
||||
2. Clients train locally on their data
|
||||
@@ -43,8 +43,6 @@ Federated learning inverts the pattern. Instead of bringing data to the model, w
|
||||
4. Server aggregates updates into improved model
|
||||
5. Repeat
|
||||
|
||||
|
||||
|
||||
Data never leaves client devices. Only model updates travel.
|
||||
|
||||
## Challenges at Scale
|
||||
@@ -59,8 +57,6 @@ Model gradients are large. With billions of parameters, naive federation is impr
|
||||
* **Asynchronous updates** : Clients contribute when convenient, not in synchronized rounds
|
||||
* **Hierarchical aggregation** : Regional aggregators reduce central server load
|
||||
|
||||
|
||||
|
||||
### Heterogeneous Compute
|
||||
|
||||
Participants have varied hardware. A phone differs from a workstation differs from a server. Our approach:
|
||||
@@ -69,8 +65,6 @@ Participants have varied hardware. A phone differs from a workstation differs fr
|
||||
* **Model sharding** : Large models split across capable participants
|
||||
* **Contribution weighting** : Update importance scales with compute contributed
|
||||
|
||||
|
||||
|
||||
### Data Heterogeneity
|
||||
|
||||
Different participants have different data distributions. This creates convergence challenges. Solutions:
|
||||
@@ -79,8 +73,6 @@ Different participants have different data distributions. This creates convergen
|
||||
* **Clustered federation** : Similar participants form training groups
|
||||
* **Importance sampling** : Under-represented distributions get higher weight
|
||||
|
||||
|
||||
|
||||
## Privacy Enhancements
|
||||
|
||||
Basic federation protects raw data but gradients can leak information. We add:
|
||||
@@ -108,8 +100,6 @@ We’ve developed a federation protocol specifically for language model training
|
||||
5. **Aggregation** : Secure combination of participant updates
|
||||
6. **Verification** : Cryptographic proofs of correct computation
|
||||
|
||||
|
||||
|
||||
Early benchmarks show we achieve 85% of centralized training efficiency while maintaining strong privacy guarantees.
|
||||
|
||||
## Join the Network
|
||||
@@ -122,16 +112,12 @@ Requirements:
|
||||
* Stable internet connection
|
||||
* Willingness to run our client software
|
||||
|
||||
|
||||
|
||||
In return, participants receive:
|
||||
|
||||
* Governance tokens proportional to contribution
|
||||
* Early access to trained models
|
||||
* Recognition in model cards
|
||||
|
||||
|
||||
|
||||
Details at zen.ai/federate.
|
||||
|
||||
* * *
|
||||
|
||||
@@ -19,8 +19,6 @@ Open models now match or exceed proprietary alternatives in many domains:
|
||||
* **General knowledge** : Within 5% on MMLU
|
||||
* **Multilingual** : Often superior for non-English languages
|
||||
|
||||
|
||||
|
||||
The capability gap that seemed insurmountable in 2021 has largely closed for models under 100B parameters.
|
||||
|
||||
### Real Adoption
|
||||
@@ -32,8 +30,6 @@ Open models power real applications:
|
||||
* Integration into major development tools
|
||||
* Deployment in production systems worldwide
|
||||
|
||||
|
||||
|
||||
This isn’t just research anymore. It’s infrastructure.
|
||||
|
||||
### Community Scale
|
||||
@@ -45,8 +41,6 @@ The open AI community has grown enormously:
|
||||
* Millions of users accessing open models
|
||||
* Billions of inference requests monthly
|
||||
|
||||
|
||||
|
||||
Network effects are real. Each contribution makes the ecosystem more valuable.
|
||||
|
||||
## Persistent Challenges
|
||||
@@ -59,8 +53,6 @@ Training frontier models requires massive compute. This compute remains concentr
|
||||
* Chip manufacturing bottlenecks persist
|
||||
* Training costs continue rising with scale
|
||||
|
||||
|
||||
|
||||
The Zoo Compute Network helps but isn’t yet large enough for frontier training. We need 10x current capacity.
|
||||
|
||||
### Data Moats
|
||||
@@ -72,8 +64,6 @@ Large organizations have accumulated unique datasets:
|
||||
* Internal documents
|
||||
* Real-world feedback signals
|
||||
|
||||
|
||||
|
||||
Synthetic data and creative commons content help but don’t fully substitute. Data remains a key differentiator.
|
||||
|
||||
### Coordination Costs
|
||||
@@ -85,8 +75,6 @@ Open development is harder to coordinate than corporate efforts:
|
||||
* Timelines are uncertain
|
||||
* Accountability is diffuse
|
||||
|
||||
|
||||
|
||||
DAOs and governance frameworks help but add overhead. Closed organizations can simply decide and execute.
|
||||
|
||||
### Safety Complexity
|
||||
@@ -98,8 +86,6 @@ As models become more capable, safety becomes more critical:
|
||||
* Adversarial robustness remains elusive
|
||||
* Dual-use concerns complicate openness
|
||||
|
||||
|
||||
|
||||
We can’t ignore safety. We also can’t let it become a barrier to open development.
|
||||
|
||||
## The Path Forward
|
||||
@@ -113,8 +99,6 @@ Training truly frontier models openly requires:
|
||||
3. **Better data** : Synthetic data, simulation, and permissioned partnerships
|
||||
4. **Sustained funding** : Multi-year commitments to training runs
|
||||
|
||||
|
||||
|
||||
This is achievable. It requires coordination the community hasn’t yet demonstrated.
|
||||
|
||||
### Infrastructure Maturity
|
||||
@@ -126,8 +110,6 @@ Open infrastructure needs to mature:
|
||||
* **Fine-tuning** : Needs better tooling for non-experts
|
||||
* **Evaluation** : Benchmarks don’t capture real-world performance
|
||||
|
||||
|
||||
|
||||
Each layer needs investment. Each layer enables the next.
|
||||
|
||||
### Governance Evolution
|
||||
@@ -139,8 +121,6 @@ Current governance works for small decisions. Bigger decisions need:
|
||||
* **Accountability** : Approved decisions must be implemented
|
||||
* **Representation** : Diverse stakeholders, not just token holders
|
||||
|
||||
|
||||
|
||||
ZIPs are a start. We need to evolve.
|
||||
|
||||
### Safety by Design
|
||||
@@ -152,8 +132,6 @@ Open development can lead on safety:
|
||||
* **Iteration** : Faster feedback loops on safety interventions
|
||||
* **Community** : More eyes on potential problems
|
||||
|
||||
|
||||
|
||||
We should demonstrate that openness enhances safety, not undermines it.
|
||||
|
||||
## Predictions for 2025
|
||||
@@ -166,8 +144,6 @@ Concrete predictions to be evaluated:
|
||||
4. **ZIPs will process >100 proposals** (80% confidence)
|
||||
5. **Foundation funding will exceed $50M** (40% confidence)
|
||||
|
||||
|
||||
|
||||
I’ll revisit these next November.
|
||||
|
||||
## A Personal Note
|
||||
@@ -183,8 +159,6 @@ But viability isn’t victory. The next phase requires:
|
||||
* Investment in unsexy infrastructure
|
||||
* Honesty about limitations and failures
|
||||
|
||||
|
||||
|
||||
We’ve shown open AI development is possible. Now we need to show it’s preferable.
|
||||
|
||||
The future of AI is still being written. Let’s write it together.
|
||||
|
||||
@@ -6,25 +6,23 @@ date: "2025-01-21"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen-Math) [HUGGING FACE](https://huggingface.co/collections/Qwen/qwen25-math-66eaa240a1b7d5ee65f1da3e) [MODELSCOPE](https://modelscope.cn/organization/qwen) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## Background
|
||||
|
||||
The Mixture-of-Experts (MoEs) architecture has become a popular model-parameter-scale-up technique. Typically, one MoE layer consists of a router (often parameterized as one single Linear layer) and a group of experts (for transformer-based models, each expert is one feedforward layer). Given an input, only a subset of experts will be activated, and then their outputs will be aggregated based on the scores the router assigned. Specifically,
|
||||
|
||||
$$ \mathbb{y}=\sum_{i\in N_E,g_i\in\operatorname{topK}}g_i(\mathbb{x})E_i(\mathbb{x}) $$
|
||||
` \mathbb\{y\}=\sum_\{i\in N_E,g_i\in\operatorname\{topK\}\}g_i(\mathbb\{x\})E_i(\mathbb\{x\}) `
|
||||
|
||||
### Load Balancing loss
|
||||
|
||||
Load balancing loss is an essential regularization technique in training MoE-based networks, and high-level intuition encourages the balanced activation of all experts. It can be calculated as:
|
||||
|
||||
$$ L_{\text{balance}}=N_E \sum_{i=1}^{N_E} f_ip_i $$
|
||||
` L_\{\text\{balance\}\}=N_E \sum_\{i=1\}^\{N_E\} f_ip_i `
|
||||
|
||||
where $f_i$ is the activation frequency of the expert $E_i$, and the $p_i$ is the the average gating score that the expert $E_i$ is assigned.
|
||||
|
||||
However, most existing MoE training frameworks (e.g., Megatron-core), implement **micro-batch** level balance, which means the $L_{\text{balance}}$ is calculated within every micro-batch and is then averaged on the global batch level.
|
||||
However, most existing MoE training frameworks (e.g., Megatron-core), implement **micro-batch** level balance, which means the $L_{\text{balance}}$ is calculated within every micro-batch and is then averaged on the global batch level.
|
||||
|
||||
Our key point is that this implementation could be problematic if one micro-batch does not contain diverse data. For instance, imagine one micro-batch only contains some code data; the aforementioned load-balancing loss still pushes the router to distribute these code tokens to all experts uniformly, potentially hurting the model performance and preventing expert specialization.
|
||||
|
||||
@@ -38,7 +36,7 @@ One easy way to calculate global-batch balance loss is to 1) Synchronize expert
|
||||
|
||||
Specifically,
|
||||
|
||||
$$ L_{\text{global}}=N_E\sum_{i=1}^{N_E}f_i^{\text{global}}p_i^{\text{global}}=N_E\sum_{i=1}^{n_E}f_i^{\text{global}}\cdot(\frac{1}{N_p}\sum_{j=1}^{N_p}p_j)= \frac{1}{N_P} \sum_{j=1}^{N_p}(N_E \sum_{i=1}^{N_E} \bar{f_i} \cdot P^j_i) $$
|
||||
` L_\{\text\{global\}\}=N_E\sum_\{i=1\}^\{N_E\}f_i^\{\text\{global\}\}p_i^\{\text\{global\}\}=N_E\sum_\{i=1\}^\{n_E\}f_i^\{\text\{global\}\}\cdot(\frac\{1\}\{N_p\}\sum_\{j=1\}^\{N_p\}p_j)= \frac\{1\}\{N_P\} \sum_\{j=1\}^\{N_p\}(N_E \sum_\{i=1\}^\{N_E\} \bar\{f_i\} \cdot P^j_i) `
|
||||
|
||||
Note that the expert selection frequency is just one expert-num-dimentional vector! It is almost free to synchronize them across micro-batches.
|
||||
|
||||
@@ -48,16 +46,10 @@ We experiment with three MoE configs (3.4B with 0.6B activated, 15B with 2.54B a
|
||||
|
||||
In short, compared to the micro-batch-level loss, the global batch one achieves better performance in all settings (model, data, and tasks). More importantly, the MoE model achieves significant domain specialization with the global batch balance. In Figure (b) left, almost all experts are uniformly activated regardless of the domain. But in Figure (b) right, some experts are frequently activated by a specific domain, demonstrating their specialization.
|
||||
|
||||

|
||||
|
||||
We further compare the model performance with balance batch size on a 3.4B with 0.6B activated model. The ptr-training PPL decreases rapidly from balance BSZ 2 to 128, and gradually saturates after 128. In the current mainstream MoE framework, even with cross expert-parallel groups communication, the balance BSZ is generally between 8 and 16 for larger models, which further reflects the significance of our method.
|
||||
|
||||

|
||||
|
||||
Using global batch balance may result in a degradation in micro-batch balance, potentially affecting the computational efficiency of MoE. We further experimented with the effect of adding micro-batch balance loss on top of the global-batch balance loss (with constant weights of 0.01 of the global batch loss). It can be seen that adding local equalization improves the speed of the model (from 1.64 to 1.59 seconds per update step) while the effectiveness of the model is almost unaffected.
|
||||
|
||||

|
||||
|
||||
## Conclusion
|
||||
|
||||
In summary, we investigate the challenges associated with the LBL in training MoEs models. By introducing global-batch balance loss, we achieve improved performance and foster expert specialization within the MoE model. We believe this advancement addresses an essential limitation in existing MoE training, offering a novel perspective for MoEs model optimization. Though mainly experimenting with language-based tasks, we hope our work could pave the way for training more substantial and specialised MoE models in various domains.
|
||||
@@ -65,7 +57,8 @@ In summary, we investigate the challenges associated with the LBL in training Mo
|
||||
# Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a citation.
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{qiu2025demonsdetailimplementingload,
|
||||
title={Demons in the Detail: On Implementing Load Balancing Loss for Training Specialized Mixture-of-Expert Models},
|
||||
author={
|
||||
@@ -75,4 +68,5 @@ If you find our work helpful, feel free to give us a citation.
|
||||
year={2025}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -15,8 +15,6 @@ Proximal Policy Optimization (PPO) has become the de facto algorithm for reinfor
|
||||
3. **Sample inefficiency** : Each prompt generates one response for learning
|
||||
4. **Reward hacking** : Models exploit reward model weaknesses
|
||||
|
||||
|
||||
|
||||
Group Relative Policy Optimization (GRPO) addresses these issues through a simple insight: **relative comparisons are more informative than absolute scores**.
|
||||
|
||||
## The GRPO Algorithm
|
||||
@@ -27,19 +25,19 @@ Instead of scoring individual responses, GRPO generates a group of $K$ responses
|
||||
|
||||
For each prompt $x$, sample $K$ responses from the current policy:
|
||||
|
||||
$$y_1, y_2, \ldots, y_K \sim \pi_\theta(\cdot | x)$$
|
||||
`y_1, y_2, \ldots, y_K \sim \pi_\theta(\cdot | x)`
|
||||
|
||||
### Reward Computation
|
||||
|
||||
Score all responses with the reward model:
|
||||
|
||||
$$r_i = R(x, y_i) \quad \text{for } i = 1, \ldots, K$$
|
||||
`r_i = R(x, y_i) \quad \text\{for \} i = 1, \ldots, K`
|
||||
|
||||
### Advantage Estimation
|
||||
|
||||
Compute group-relative advantages:
|
||||
|
||||
$$A_i = \frac{r_i - \mu_r}{\sigma_r}$$
|
||||
`A_i = \frac\{r_i - \mu_r\}\{\sigma_r\}`
|
||||
|
||||
Where $\mu_r$ and $\sigma_r$ are the mean and standard deviation of rewards within the group.
|
||||
|
||||
@@ -47,9 +45,9 @@ Where $\mu_r$ and $\sigma_r$ are the mean and standard deviation of rewards with
|
||||
|
||||
Update the policy to increase probability of high-advantage responses:
|
||||
|
||||
$$\mathcal{L}_{GRPO} = -\mathbb{E}_{x, y \sim \pi_\theta}\left[\frac{\pi_\theta(y|x)}{\pi_{old}(y|x)} \cdot A(x, y) \cdot \mathbb{1}_{clip}\right]$$
|
||||
`\mathcal\{L\}_\{GRPO\} = -\mathbb\{E\}_\{x, y \sim \pi_\theta\}\left[\frac\{\pi_\theta(y|x)\}\{\pi_\{old\}(y|x)\} \cdot A(x, y) \cdot \mathbb\{1\}_\{clip\}\right]`
|
||||
|
||||
Where $\mathbb{1}_{clip}$ applies PPO-style clipping to the importance ratio.
|
||||
Where $\mathbb{1}_{clip}$ applies PPO-style clipping to the importance ratio.
|
||||
|
||||
## Why Group-Relative?
|
||||
|
||||
@@ -71,11 +69,9 @@ Group-relative advantages automatically adapt to reward scale and prompt difficu
|
||||
* Hard prompts: Large variance, clear signal for improvement
|
||||
* Reward drift: Normalization handles changing baselines
|
||||
|
||||
|
||||
|
||||
### Sample Efficiency
|
||||
|
||||
Generating $K$ responses per prompt and comparing them provides $\binom{K}{2}$ pairwise comparisons. For $K=8$, that’s 28 learning signals per prompt versus 1 for standard PPO.
|
||||
Generating $K$ responses per prompt and comparing them provides $\binom{K}{2}$ pairwise comparisons. For $K=8$, that’s 28 learning signals per prompt versus 1 for standard PPO.
|
||||
|
||||
## Implementation Details
|
||||
|
||||
@@ -93,7 +89,8 @@ K| Compute| Signal Quality| Best Accuracy
|
||||
### Temperature Schedule
|
||||
|
||||
Higher temperature during response generation increases group diversity:
|
||||
[code]
|
||||
```python
|
||||
|
||||
def sample_group(prompt, policy, K=8):
|
||||
responses = []
|
||||
for i in range(K):
|
||||
@@ -102,13 +99,14 @@ Higher temperature during response generation increases group diversity:
|
||||
responses.append(response)
|
||||
return responses
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### KL Regularization
|
||||
|
||||
GRPO still benefits from KL regularization, but with reduced sensitivity:
|
||||
|
||||
$$\mathcal{L} = \mathcal{L}_{GRPO} + \beta \cdot D_{KL}(\pi_\theta || \pi_{ref})$$
|
||||
`\mathcal\{L\} = \mathcal\{L\}_\{GRPO\} + \beta \cdot D_\{KL\}(\pi_\theta || \pi_\{ref\})`
|
||||
|
||||
We find $\beta = 0.01$ works across tasks, compared to PPO’s typical $\beta \in [0.001, 0.1]$ sensitivity.
|
||||
|
||||
@@ -132,14 +130,13 @@ GRPO is naturally resistant to reward hacking because:
|
||||
2. **Diverse sampling** : Temperature variation produces varied response styles
|
||||
3. **Group normalization** : Exploits that boost all responses equally provide no gradient
|
||||
|
||||
|
||||
|
||||
We observe significantly less length gaming and repetition compared to PPO.
|
||||
|
||||
## Code
|
||||
|
||||
Reference implementation:
|
||||
[code]
|
||||
```python
|
||||
|
||||
def grpo_loss(policy, prompts, reward_model, K=8, clip_eps=0.2):
|
||||
losses = []
|
||||
for prompt in prompts:
|
||||
@@ -159,7 +156,8 @@ Reference implementation:
|
||||
|
||||
return torch.mean(torch.stack(losses))
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Conclusion
|
||||
|
||||
|
||||
@@ -16,8 +16,6 @@ Standard RLHF follows three steps:
|
||||
2. Use the reward model to provide training signal
|
||||
3. Optimize the policy with reinforcement learning (typically PPO)
|
||||
|
||||
|
||||
|
||||
Step 3 is problematic. PPO requires careful hyperparameter tuning, extensive sampling, and still often produces unstable training dynamics.
|
||||
|
||||
## Key Insight: Relative Comparisons
|
||||
@@ -34,19 +32,19 @@ Instead of optimizing absolute rewards, GRPO optimizes within groups of sampled
|
||||
|
||||
For each prompt $x$, sample a group of $k$ responses:
|
||||
|
||||
$$G = {y_1, y_2, …, y_k} \sim \pi_\theta(y|x)$$
|
||||
`G = \{y_1, y_2, …, y_k\} \sim \pi_\theta(y|x)`
|
||||
|
||||
### Ranking
|
||||
|
||||
Rank responses within the group using the reward model:
|
||||
|
||||
$$r_i = R(x, y_i)$$ $$\text{rank}(y_i) = |{j : r_j > r_i}| + 1$$
|
||||
`r_i = R(x, y_i)` `\text\{rank\}(y_i) = |\{j : r_j > r_i\}| + 1`
|
||||
|
||||
### Relative Advantage
|
||||
|
||||
Compute advantages relative to the group:
|
||||
|
||||
$$A_i = \frac{r_i - \mu_G}{\sigma_G}$$
|
||||
`A_i = \frac\{r_i - \mu_G\}\{\sigma_G\}`
|
||||
|
||||
where $\mu_G$ and $\sigma_G$ are the group mean and standard deviation.
|
||||
|
||||
@@ -54,7 +52,7 @@ where $\mu_G$ and $\sigma_G$ are the group mean and standard deviation.
|
||||
|
||||
Update the policy to increase probability of high-ranked responses:
|
||||
|
||||
$$\mathcal{L}(\theta) = -\mathbb{E}_{y \sim G}\left[\min\left(\frac{\pi_ \theta(y|x)}{\pi_{\text{old}}(y|x)} A, \text{clip}\left(\frac{\pi_\theta(y|x)}{\pi_{\text{old}}(y|x)}, 1-\epsilon, 1+\epsilon\right) A\right)\right]$$
|
||||
`\mathcal\{L\}(\theta) = -\mathbb\{E\}_\{y \sim G\}\left[\min\left(\frac\{\pi_ \theta(y|x)\}\{\pi_\{\text\{old\}\}(y|x)\} A, \text\{clip\}\left(\frac\{\pi_\theta(y|x)\}\{\pi_\{\text\{old\}\}(y|x)\}, 1-\epsilon, 1+\epsilon\right) A\right)\right]`
|
||||
|
||||
The clipping stabilizes training, similar to PPO, but the relative advantages provide better signal.
|
||||
|
||||
@@ -93,8 +91,6 @@ Training dynamics also improve significantly:
|
||||
* **Convergence** : Reaches final performance 2x faster
|
||||
* **Robustness** : Less sensitive to learning rate choice
|
||||
|
||||
|
||||
|
||||
## Implementation Details
|
||||
|
||||
Key hyperparameters:
|
||||
@@ -103,14 +99,13 @@ Key hyperparameters:
|
||||
* **Clipping** ($\epsilon$): 0.1-0.2
|
||||
* **KL penalty** : Lower than PPO (0.01 vs 0.1)
|
||||
|
||||
|
||||
|
||||
The larger group size compared to PPO’s typical 2-response setup is essential. More comparisons mean better gradient estimates.
|
||||
|
||||
## Code Release
|
||||
|
||||
We’re releasing our GRPO implementation integrated with the Zen training framework:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from zen.alignment import GRPOTrainer
|
||||
|
||||
trainer = GRPOTrainer(
|
||||
@@ -122,7 +117,8 @@ We’re releasing our GRPO implementation integrated with the Zen training frame
|
||||
|
||||
trainer.train(prompts)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Full documentation and examples at github.com/zoo-labs/zen-align.
|
||||
|
||||
@@ -134,8 +130,6 @@ GRPO opens several research directions:
|
||||
* **Online preference learning** : Update reward model during training
|
||||
* **Constitutional GRPO** : Use principles instead of learned rewards
|
||||
|
||||
|
||||
|
||||
Alignment is the central challenge of AI development. GRPO is one step toward making it more reliable.
|
||||
|
||||
* * *
|
||||
|
||||
@@ -1,85 +0,0 @@
|
||||
---
|
||||
title: "GSPO: Towards Scalable Reinforcement Learning for Language Models"
|
||||
description: "PAPER DISCORD
|
||||
Introduction Reinforcement Learning (RL) has emerged as a pivotal paradigm for scaling language models and enhancing their deep reasoning and problem-solving capabilities. To scale RL, the foremost prerequisite is maintaining stable and robust training dynamics. However, we observe that existing RL algorithms (such as GRPO) exhibit severe instability issues during long training and lead to irreversible model collapse, hindering further performance improvements with increased compute.
|
||||
To enable successful RL scaling, we propose the Group Sequence Policy Optimization (GSPO) algorithm."
|
||||
date: "2025-07-27"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||
[PAPER](https://huggingface.co/papers/2507.18071) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## Introduction
|
||||
|
||||
Reinforcement Learning (RL) has emerged as a pivotal paradigm for scaling language models and enhancing their deep reasoning and problem-solving capabilities. To scale RL, the foremost prerequisite is maintaining stable and robust training dynamics. However, we observe that existing RL algorithms (such as GRPO) exhibit severe instability issues during long training and lead to irreversible model collapse, hindering further performance improvements with increased compute.
|
||||
|
||||
To enable successful RL scaling, we propose the **Group Sequence Policy Optimization (GSPO)** algorithm. Unlike previous RL algorithms, GSPO defines the importance ratio based on sequence likelihood and performs **sequence-level clipping, rewarding, and optimization**. Compared to GRPO, GSPO demonstrates remarkable advantages in the following aspects:
|
||||
|
||||
* **Performant and Efficient** : GSPO possesses significantly higher training efficiency and can achieve continuous performance improvements through increasing training compute;
|
||||
* **Notably Stable** : GSPO maintains stable training processes and inherently resolves the stability challenges in the RL training of large Mixture-of-Experts (MoE) models;
|
||||
* **Infrastructure-Friendly** : Due to sequence-level optimization, GSPO is fundamentally more tolerant to precision discrepancies, offering attractive potential for simplifying RL infrastructure.
|
||||
|
||||
|
||||
|
||||
These merits have contributed to the exceptional performance of the latest Qwen3 models (Instruct, Coder, Thinking).
|
||||
|
||||
## Sequence-Level Optimization Objective
|
||||
|
||||
Let $x$ be a query, $\pi_{\theta_\mathrm{old}}$ be the old policy that generates responses, $\\{y_i\\}_{i=1}^G$ be the sampled response group, $\widehat{A}_{i}$ be the group relative advantage of each response, and $\pi_\theta$ be the current policy to be optimized. GSPO adopts the following optimization objective:
|
||||
|
||||
$$ \mathcal{J}_\text{GSPO} (\theta) =\, \mathbb{E}_{ x \sim \mathcal{D},\, \\{y_i\\}_{i=1}^G \sim \pi_{\theta_\mathrm{old}}( \cdot | x) } \left[ \frac{1}{G} \sum_{i=1}^{G} \min \left( s_{i}(\theta) \widehat{A}_{i}, \, \mathrm{clip} \left( s_{i}(\theta), 1 - {\varepsilon}, 1 + {\varepsilon} \right) \widehat{A}_{i} \right) \right], $$
|
||||
|
||||
where
|
||||
|
||||
$$ s_{i}(\theta) = \left( \frac{ \pi_{\theta} (y_i | x) }{ \pi_{\theta_\text{old}} (y_i | x)} \right)^{\frac{1}{|y_i|}} = \exp \left( \frac{1}{|y_i|} \sum_{t=1}^{|y_i|} \log \frac{ \pi_{\theta} (y_{i,t} | x, y_{i,<t}) }{ \pi_{\theta_\text{old}} (y_{i,t} | x,y_{i,<t})} \right). $$
|
||||
|
||||
Here, $s_i(\theta)$ is **the importance ratio defined based on sequence likelihood** in GSPO, where we perform length normalization to reduce variance and unify the numerical range of $s_i(\theta)$.
|
||||
|
||||
## Training Efficiency and Performance
|
||||
|
||||
We experiment with a cold-start model fine-tuned from Qwen3-30B-A3B-Base and report its training reward curves as well as performance curves on the AIME'24, LiveCodeBench, and CodeForces benchmarks. We compare against GRPO as the baseline. Note that GRPO necessitates the Routing Replay training strategy for the normal convergence of MoE RL (which we will discuss later), while **GSPO has obviated the need for this strategy**.
|
||||
|
||||
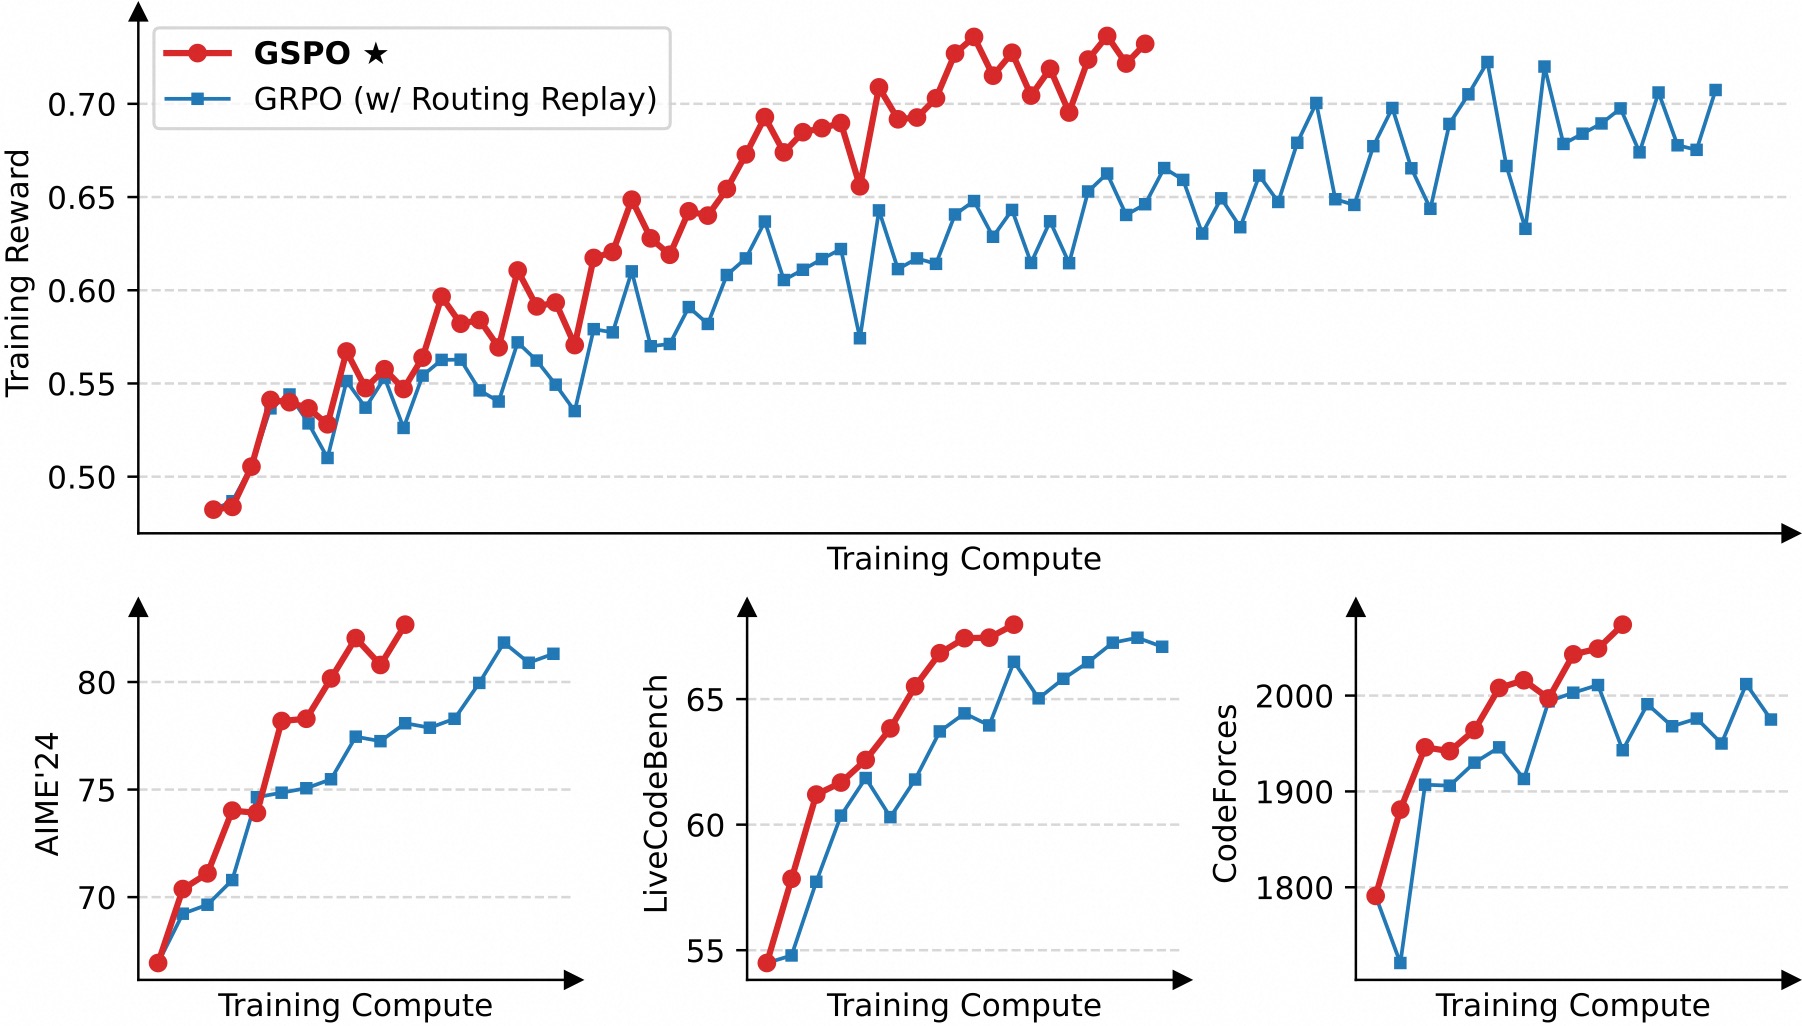
|
||||
|
||||
#### Experimental results
|
||||
|
||||
As shown in the figure above, GSPO demonstrates **significantly higher training efficiency** than GRPO, achieving better performance under the same training cost. Particularly, we observe that **GSPO can deliver continuous performance improvement through increasing the training compute, regularly updating the query set, and extending the generation length** — this is exactly the **scalability** we expect from an algorithm. Ultimately, we successfully applied GSPO to the large-scale RL training of the latest Qwen3 models, further unleashing the potential of RL scaling!
|
||||
|
||||
An interesting observation is that the fraction of tokens clipped in GSPO is two orders of magnitude higher than that in GRPO (as shown in the figure below), while GSPO still achieves higher training efficiency. This further demonstrates that GRPO’s token-level optimization objective is noisy and inefficient, while GSPO’s sequence-level approach provides a more reliable and effective learning signal.
|
||||
|
||||
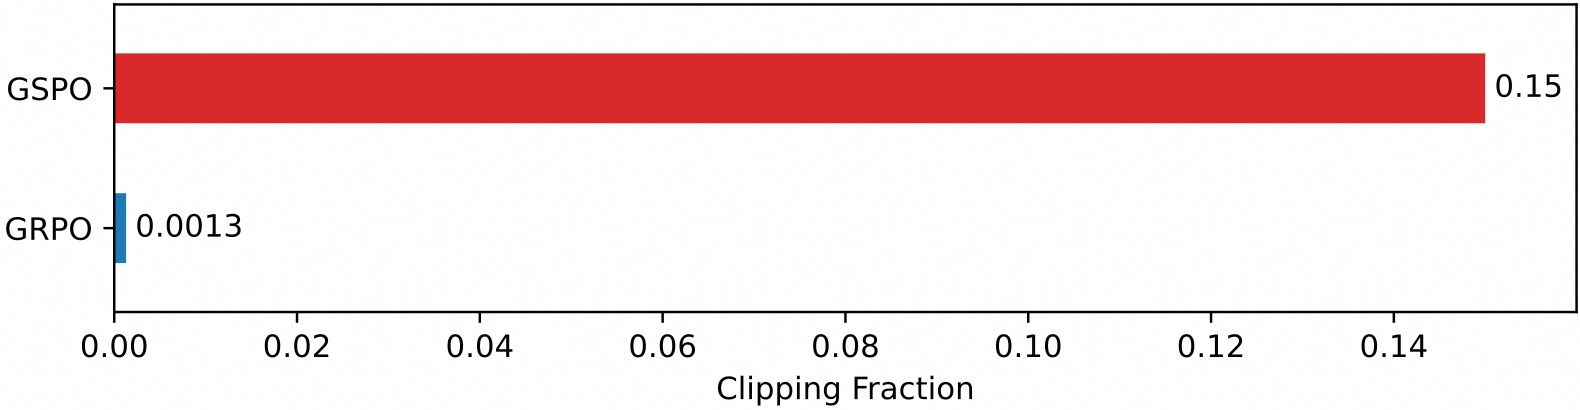
|
||||
|
||||
#### Fractions of clipped tokens
|
||||
|
||||
## Benefits for MoE RL and Infrastructure
|
||||
|
||||
We found that when adopting the GRPO algorithm, the expert activation volatility of MoE models prevents RL training from converging properly. To address this challenge, we previously employed the **Routing Replay** training strategy, which caches the activated experts in $\pi_{\theta_\text{old}}$ and “replays” these routing patterns in $\pi_\theta$ when computing importance ratios. As shown in the figure below, Routing Replay is crucial for normal convergence of GRPO training on MoE models. However, the Routing Replay strategy incurs additional memory and communication overhead and may limit the actual capacity of MoE models.
|
||||
|
||||
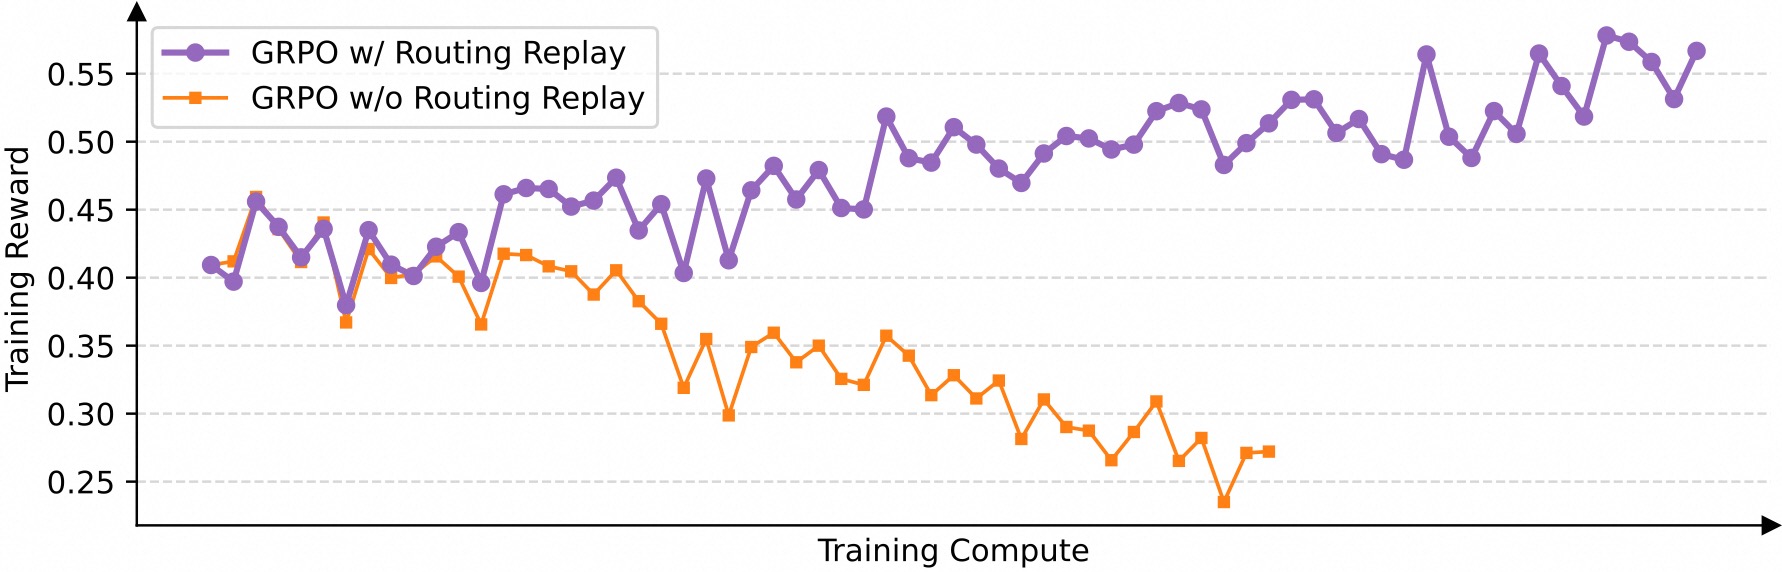
|
||||
|
||||
#### Effect of Routing Replay in the GRPO training of MoE models
|
||||
|
||||
The notable advantage of GSPO lies in **completely eliminating the dependency on Routing Replay**. The key insight is that GSPO only focuses on sequence-level likelihood (i.e., $\pi_\theta(y_i|x)$) and is not sensitive to individual token likelihood (i.e., $\pi_\theta(y_{i,t}|x,y_{i,<t})$). Therefore, it does not require infrastructure-heavy workarounds like Routing Replay, both simplifying and stabilizing the training process while allowing models to maximize their capacity.
|
||||
|
||||
Additionally, since GSPO uses only sequence-level rather than token-level likelihoods for optimization, intuitively the former is much more tolerant of precision discrepancies. Therefore, GSPO makes it possible to directly use likelihoods returned by inference engines for optimization, eliminating the need for recomputation with training engines. This is particularly beneficial in scenarios such as partial rollout, multi-turn RL, and training-inference disaggregated frameworks.
|
||||
|
||||
## Conclusion
|
||||
|
||||
We propose Group Sequence Policy Optimization (GSPO), a new RL algorithm for training language models. GSPO demonstrates notably superior training stability, efficiency, and performance compared to GRPO and exhibits particular efficacy for the large-scale RL training of MoE models, laying the foundation for the exceptional improvements in the latest Qwen3 models. With GSPO as our algorithmic cornerstone, we will continue to push the boundaries of RL scaling and look forward to the resulting fundamental advances in intelligence.
|
||||
|
||||
## Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a citation.
|
||||
[code]
|
||||
@article{gspo,
|
||||
title={Group Sequence Policy Optimization},
|
||||
author={
|
||||
Chujie Zheng and Shixuan Liu and Mingze Li and Xiong-Hui Chen and Bowen Yu and
|
||||
Chang Gao and Kai Dang and Yuqiong Liu and Rui Men and An Yang and Jingren Zhou and
|
||||
Junyang Lin
|
||||
},
|
||||
journal={arXiv preprint arXiv:2507.18071},
|
||||
year={2025}
|
||||
}
|
||||
|
||||
[/code]
|
||||
@@ -24,17 +24,15 @@ Abliteration is representation engineering applied to refusal suppression. The t
|
||||
|
||||
4. **Project out** the refusal direction from the relevant weight matrices (typically the output projections of attention layers). For a weight matrix W and refusal direction r:
|
||||
|
||||
```
|
||||
|
||||
|
||||
[code]
|
||||
W_abliterated = W - (W r^T r) / (r^T r)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
5. The resulting weights produce a model that, when it would have activated the refusal direction, instead activates its complement.
|
||||
|
||||
|
||||
|
||||
This technique is elegant, computationally cheap (no gradient computation required), and highly effective on dense models. The hamsaOmar release of `Kimi-K2.5-abliterated` uses this exact approach — but it contains only the direction vectors (`refusal_direction.pt`, `refusal_subspace.pt`) and the apply script (`apply_abliteration.py`), not standalone weights. You apply it to your own copy of the base model.
|
||||
|
||||
## Why MoE Breaks This
|
||||
@@ -47,8 +45,6 @@ MoE models have a different structure. The FFN block is replaced by a **router +
|
||||
2. The top-k experts are selected based on these scores
|
||||
3. The selected experts process the token; the others do not
|
||||
|
||||
|
||||
|
||||
The critical implication: the routing decision happens _before_ the residual stream accumulates the expert’s contribution. Refusal behavior in MoE models can be encoded at two levels:
|
||||
|
||||
**Level 1 (Residual stream)** : The same mechanism as dense models — certain activation patterns in the residual stream trigger refusal. Projection-based abliteration handles this.
|
||||
@@ -78,7 +74,8 @@ The gate weight matrix `W_gate` for each MoE layer has shape `(n_experts, d_mode
|
||||
Crucially: **we do not use LoRA on the gate weights**. Gate weights are too small (168M total) and the routing changes we need are too structured for low-rank approximation to capture. We unfreeze the gate weights and apply direct gradient descent.
|
||||
|
||||
The training objective is DPO (Direct Preference Optimization) on a refusal contrast dataset:
|
||||
[code]
|
||||
```python
|
||||
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from transformers import AutoModelForCausalLM, BitsAndBytesConfig
|
||||
@@ -157,7 +154,8 @@ The training objective is DPO (Direct Preference Optimization) on a refusal cont
|
||||
outputs = model(input_ids=input_ids, labels=input_ids)
|
||||
return -outputs.loss # mean log probability
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The two optimizer groups run at different learning rates: LoRA adapters at 2e-4, gate weights at 5e-6. Gate weights need a lower learning rate because they directly control routing — large updates cause routing collapse where most tokens go to a single expert.
|
||||
|
||||
@@ -172,8 +170,6 @@ The quantization strategy:
|
||||
* **Shared experts** : INT4 for storage, bfloat16 for computation via the LoRA path.
|
||||
* **LoRA adapters** : bfloat16. Small enough (~400MB for rank-32 adapters) to not matter.
|
||||
|
||||
|
||||
|
||||
Minimum hardware: 4× A100 80GB. The base model quantized to INT4 occupies roughly 280GB across the 4 GPUs (70GB each). Gate weights and LoRA adapters add ~4GB. The remaining headroom per GPU handles activation memory during forward/backward.
|
||||
|
||||
## The GGUF Alternative
|
||||
@@ -203,8 +199,6 @@ The training code is complete and available at [github.com/zenlm/zen4-ultra-trai
|
||||
* `eval/routing_analysis.py`: Expert routing attribution for diagnostic use
|
||||
* `paper/main.tex`: Technical paper with full derivations
|
||||
|
||||
|
||||
|
||||
We are awaiting the compute budget for the full training run (estimated 72-96 GPU-hours on 4× A100 80GB). Until then, `zen4-ultra` ships as vanilla Kimi K2.5 SafeTensors, and `zen4-ultra-gguf` ships as the GGUF abliteration for users who need reduced restrictions today.
|
||||
|
||||
When training completes, the LoRA adapters will be pushed to `zenlm/zen4-ultra-lora` and applied to the base weights to produce the final `zen4-ultra` SafeTensors release. The training process will be documented in full in the paper.
|
||||
|
||||
@@ -19,8 +19,6 @@ Zen represents our commitment to building AI that is:
|
||||
* **Aligned** : Built with explicit mechanisms for community governance
|
||||
* **Efficient** : Optimized for accessibility, not just raw capability
|
||||
|
||||
|
||||
|
||||
## The Technical Foundation
|
||||
|
||||
We’re starting with a focus on three areas:
|
||||
@@ -46,8 +44,6 @@ Over the coming months, we’ll publish:
|
||||
* Data curation guidelines
|
||||
* Governance framework drafts
|
||||
|
||||
|
||||
|
||||
This is day one. The hard work is ahead. But we believe the destination is worth the journey.
|
||||
|
||||
Join us.
|
||||
|
||||
@@ -11,8 +11,6 @@ author: "Zen LM Team"
|
||||
|
||||
## Background
|
||||
|
||||

|
||||
|
||||
Multimodal pretraining has been developing rapidly ever since the transfer of BERT2 to cross-modal representation learning. Representative studies include UNITER3, VilBERT4, etc. These studies directly incorporate the Transformer-based BERT2 to a single-stream or dual stream framework for multimodal pretraining, and transform the image to a sequence of object features to be concatenated with the word embeddings as the input of Transformer. Later in 2021, with the rise of Vision Transformer5, there came methods that got rid of object-level features, which depend on complex preprocessing pipelines, say Faster-RCNN6: For example, the simplest ViLT7 based on patch projection, the CLIP-based8 CLIP-ViL9, etc. One milestone after should be the proposal of SimVLM10, which leverages the T5/BART method for multimodal pretraining and achieves new SoTA in many tasks. These progress should be regarded as the foundation of unified multimodal pretrained models in 2022, including OFA of ours, Unified-IO11, Flamingo12, BeiT-313, etc.
|
||||
|
||||
## Method
|
||||
@@ -21,42 +19,26 @@ What OFA wants to achieve is the unification of tasks, modalities, and architect
|
||||
|
||||
For the unification of modalities, one key issue is the tokenization of inputs of different modalities, or to say, the discretization. Otherwise, there should be other solutions like diffusion models14 for the generation. There is no need to change the tokenization for texts, but the images and bounding boxes need to be discretized. Owing to the success of vector quantization1516 and text-to-image generation with Transformer1718, images can be represented with VQ tokens. Inspired by pix2seq19, bounding boxes can also be discretized with bins.
|
||||
|
||||

|
||||
|
||||
We choose the universal Transformer encoder-decoder architecture, due to its successful usages in NLP unified models like T520. Note that for the input of images to the Transformer, we use the first three blocks of ResNet. For the Transformer architecture, we modify the design by incorporating Normformer21 for the training stability and transfer performance.
|
||||
|
||||

|
||||
|
||||
The multitask learning is the key innovation of OFA. Specifically, we pretrain the model with 8 tasks, including 5 vision-language tasks, 2 vision tasks, and 1 language task. The vision-language tasks include visual grounding, grounded captioning, visual question answering, image-text matching, and image captioning. The vision tasks include detection and image infilling. The language task is text infilling. To help the model differentiate tasks, we insert an instruction, which is simply a piece of text describing the task. Thus, we expect the model to perform zero-shot generation based on a new instruction indicating an unseen task.
|
||||
|
||||

|
||||
|
||||
To make this research as reproducible as possible, our pretraining is dependent on public datasets. Therefore, we expect the researchers following this work can reproduce our results with our opensourced code.
|
||||
|
||||
We have released OFA models of 5 sizes, including OFA-Tiny (33M), OFA-Medium (93M), OFA-Base (180M), OFA-Large(470M), OFA-Huge (930M). See the table below for more statistics.
|
||||
|
||||

|
||||
|
||||
## Experiments
|
||||
|
||||
We have conducted experiments on multiple cross-modal tasks and unimodal tasks. On vision-language understanding, we test the models on VQA and SNLI-VE. We find that the huge-size model can achieve a comparable performance to the 80B-parameter model Flamingo and the 2B-parameter model CoCa pretrained on 5B image-text pairs. Furthermore, we achieve the best performance on visual entailment. For vision-language generation, we focus on the classical image captioning, and our OFA achieves the SoTA performance in both setups of cross-entropy optimization and CIDEr optimization. Also, we have transformed the task of visual grounding to a generation task, and we find that even the base-size OFA can outperform the previous SoTA, and the scaling of model size consistently brings performance improvements. This shows the significance of the unification of modalities and tasks.
|
||||
|
||||

|
||||
|
||||
Additionally, we test OFA on text-to-image generation, as we believe that the image infilling task in pretraining endows it with the capability to generate image codes. We show that OFA can achieve a low FID score in the evaluation, and further finetuning on a larger dataset can significantly boost its performance. See cases below.
|
||||
|
||||

|
||||
|
||||
As to the unimodal tasks, we evaluate OFA on the GLUE benchmark for NLU, Gigaword summarization for NLG, and ImageNet classification for vision understanding. We show that OFA can be competitive with both RoBERTa and DeBERTa, and the previous multimodal pretrained model often falls far behind the SoTAs in NLU. Similarly, OFA can achieve good performance on NLG and outperform the previous best models. As to image classification, it can also achieve similar performance with the self-supervised vision models like BeiT22 and MAE23.
|
||||
|
||||
We observe that OFA based on multitask pretraining demonstrates potential in transferring to unseen tasks and unseen domains. We show them with two cases below.
|
||||
|
||||

|
||||
|
||||
The preceding case demonstrates the model’s ability of compositional generalization by understanding the instruction and leveraging two learned capabilities to perform the new task. We set up a new task called _Grounded VQA_ , which is a combination of VQA and grounded captioning. What we need to change is the instruction. The new task instruction with both question and region information directs the model to provide a correct answer.
|
||||
|
||||

|
||||
|
||||
Also, we find that OFA can transfer to unseen domains effectively. One example is the visual grounding on images of animation. OFA can perform well in this setup as it has been pretrained on some anime data and it has been pretrained on visual grounding on general-domain data. This again shows the compositional ability of the unified model.
|
||||
|
||||
## Conclusion
|
||||
|
||||
@@ -11,8 +11,6 @@ Generalist Models are hot! We all see an opportunity towards a real generalist m
|
||||
|
||||
[Paper](https://arxiv.org/abs/2212.04408) [GitHub](https://github.com/OFA-Sys/OFASys)
|
||||
|
||||

|
||||
|
||||
## Background
|
||||
|
||||
Thanks to Transformer and pretraining, we have witnessed an unprecedented opportunity towards general-purpose AI! In the field of natural language, we now have more than GPT-31, and we even have ChatGPT with extremely comprehensive capabilities in question answering, dialog, creative writing, etc. In the field of multimodal representation learning, we have seen unified models that try to unify tasks and modalities to build a more general AI system, including our proposed OFA2, GATO3, Unified-IO4, etc. However, the key difficulties lie in the implementation. What makes deep learning engineers struggled is how to implement and train such a generalist model with so many datasets concerning inputs of different modalities and tasks. Although we now have PyTorch and TensorFlow for deep learning, and many beautiful frameworks for building Transformer, e.g., Hugging Face Transformers, fairseq, etc., there is still no designated system that provides neat abstractions and tools for task-agnostic generalist model learning.
|
||||
@@ -21,15 +19,11 @@ Thanks to Transformer and pretraining, we have witnessed an unprecedented opport
|
||||
|
||||
Before introducing the system design, we first move into the world of OFASys to see how we can build a multitask learning model with a single line of code. To be more specific, what you need to do is composing a proper _Instruction_. Here are several examples of _Instruction_ for different tasks:
|
||||
|
||||

|
||||
|
||||
The two sentences separated by “->” describe the task input and its desired output, respectively. In this case, “`<tt>`[IMAGE:img]`</tt>`” specifies that there is an image input bound to a data column named `<tt>`img`</tt>` in the dataset. The plain texts in the _Instruction_ indicate the task is about captioning an image. The output of the task is a text sequence, which is the `<tt>`cap`</tt>` column in the dataset.
|
||||
|
||||
Another example is for an NLI task:
|
||||
|
||||

|
||||
|
||||
Similar to the previous one, we use a template and indicators for inputs to build an _Instruction_. Differently, there are two inputs for the encoder. Besides, as we find repeating the input in the decoder is helpful for the downstream performance, we use a signal `<tt>`no_loss`</tt>` to avoid loss computation. As the label set is closed for NLI, we use a signal `<tt>`closed_set`</tt>` for the indication.
|
||||
|
||||
To sum up, things can be much easier if you use OFASys. What you need might only be 1 line of code for the _Instruction_.
|
||||
|
||||
@@ -37,8 +31,6 @@ To sum up, things can be much easier if you use OFASys. What you need might only
|
||||
|
||||
A neat system design is what lies behind an easy-to-use interface. An overview is demonstrated below.
|
||||
|
||||

|
||||
|
||||
OFASys accesses the task definition and task data through _Instruction_ by parsing _Instructions_ into task plans. In each plan, there is a model hierarchy, consisting of modality-specific preprocessors/postprocessors and adapters, as well as a modality-agnostic computation model. The universal model is namely a general module for fusing multimodal inputs and generating outputs. As the inputs and the outputs are consistently being representation sequences, the implementation of the universal model is highly versatile, regardless of the modality intricacies. The outputs of the universal model is finally postprocessed by the adapters and postprocessors, in order to generate content consistent with the input formats. Stage-wise components, including criteria and generators, provide support in training and inference, which have a variety of out-of-the-box implementations. In this way, different multi-modal data can go through the system with consistent inner interfaces to improve development efficiency.
|
||||
|
||||
In multitask learning, there are multiple such plans parsed from the _Instructions_. OFASys shares the trainable parameters of the adapters and the universal model by default, such that each parameter can be optimized on as many examples as possible. A task scheduler manages task precedence and joint optimization, and a logical scheduler arranges the workflow on multiple physical devices.
|
||||
@@ -47,8 +39,6 @@ In multitask learning, there are multiple such plans parsed from the _Instructio
|
||||
|
||||
To validate its effectiveness, we train a generalist model based on OFA, OFA+, which can handle text, image, speech, video and motion data all-in-one for the first time. Specifically, we have trained a OFA-based OFA+ (Generalist) and an improved version with modality-level MoE, OFA+ (Generalist MoE). For comparison, we use the original OFA (OFA+ (Specialist)) which is finetuned on each specific task.
|
||||
|
||||

|
||||
|
||||
In general, OFA+ is able to preserve 95+% of the performance of the specialist model while scaling to 23 diverse tasks over 7 modalities. This shows that multitask learning not only endows the generalist model with multiple capabilities but also helps it achieve top-level performance on specific tasks.
|
||||
|
||||
## Conclusion
|
||||
|
||||
@@ -19,16 +19,12 @@ Consider a decentralized AI service:
|
||||
3. Provider returns output
|
||||
4. User receives result
|
||||
|
||||
|
||||
|
||||
What prevents the provider from:
|
||||
|
||||
* Running a cheaper, worse model?
|
||||
* Returning cached results for new inputs?
|
||||
* Fabricating outputs entirely?
|
||||
|
||||
|
||||
|
||||
Traditional solutions require trusted hardware or reputation systems. PoAI provides cryptographic guarantees.
|
||||
|
||||
## Proof of AI Overview
|
||||
@@ -42,10 +38,9 @@ PoAI generates succinct proofs that a specific model produced a specific output
|
||||
* **Succinctness** : Proof size is small relative to computation size
|
||||
* **Zero-knowledge** (optional): Proofs reveal nothing beyond correctness
|
||||
|
||||
|
||||
|
||||
### Architecture
|
||||
[code]
|
||||
```
|
||||
|
||||
Input -> [Model Execution] -> Output
|
||||
|
|
||||
v
|
||||
@@ -57,7 +52,8 @@ PoAI generates succinct proofs that a specific model produced a specific output
|
||||
v
|
||||
[Proof] -> [Verifier] -> Accept/Reject
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Technical Approach
|
||||
|
||||
@@ -78,8 +74,6 @@ Our compiler handles:
|
||||
* Feedforward blocks
|
||||
* Embedding lookups
|
||||
|
||||
|
||||
|
||||
### Proof System
|
||||
|
||||
We use a combination of techniques:
|
||||
@@ -99,8 +93,6 @@ Naive compilation produces impractical circuits. We optimize through:
|
||||
3. **Polynomial approximations** : Replace transcendental functions with low-degree polynomials
|
||||
4. **Batched verification** : Amortize proof costs across multiple inferences
|
||||
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
### Proof Generation
|
||||
@@ -162,8 +154,6 @@ Current limitations we’re working to address:
|
||||
3. **Floating point** : Native FP support would reduce approximation errors
|
||||
4. **Recursion** : Autoregressive generation requires sequential proofs
|
||||
|
||||
|
||||
|
||||
## Roadmap
|
||||
|
||||
**Q3 2023** : Release PoAI SDK for small models **Q4 2023** : Folding scheme improvements for 10x speedup **Q1 2024** : Support for models up to 1B parameters **Q2 2024** : Production deployment on Lux Network
|
||||
|
||||
@@ -21,8 +21,6 @@ Imagine an AI that can look at a complex physics problem, and methodically reaso
|
||||
3. **Safety and Ethical Considerations** : The model requires enhanced safety measures to ensure reliable and secure performance, and users should be cautious when deploying it.
|
||||
4. **Performance and Benchmark Limitations** : Although the model has shown improvements in visual reasoning, it cannot fully replace the capabilities of zen-VL-72B-Instruct. Additionally, during multi-step visual reasoning, the model may gradually lose focus on the image content, leading to hallucinations.
|
||||
|
||||
|
||||
|
||||
# Performance
|
||||
|
||||
We evaluate QVQ-72B-Preview on 4 datasets, including:
|
||||
@@ -32,8 +30,6 @@ We evaluate QVQ-72B-Preview on 4 datasets, including:
|
||||
* MathVision: A high-quality multimodal mathematical reasoning test set derived from real mathematics competitions, featuring greater problem diversity and subject breadth compared to MathVista.
|
||||
* OlympiadBench: An Olympic competition-level bilingual multimodal science benchmark test set containing 8,476 problems from Olympic mathematics and physics competitions, including the Chinese college entrance examination. Each problem comes with expert-level annotations detailing the step-by-step reasoning process.
|
||||
|
||||

|
||||
|
||||
In particular, QVQ-72B-Preview has achieved an impressive score of 70.3 on the MMMU benchmark, significantly outpacing its predecessor, zen-VL-72B-Instruct. Furthermore, in the remaining three benchmarks focused on mathematics and science problems, the model demonstrates exceptional performance, effectively closing the gap with the leading state-of-the-art o1 model.
|
||||
|
||||
# Demo Cases
|
||||
@@ -44,7 +40,7 @@ Example: Math Next
|
||||
|
||||
User
|
||||
|
||||
Given $h(x) = f(x) \cdot g(x)$, find $h’(2)$ using the table below: 
|
||||
Given $h(x) = f(x) \cdot g(x)$, find $h’(2)$ using the table below:
|
||||
|
||||
QVQ-72B-Preview
|
||||
|
||||
@@ -68,9 +64,6 @@ Looking at the table:
|
||||
|
||||
* g’(2) = 7
|
||||
|
||||
|
||||
|
||||
|
||||
Plugging these values into the product rule formula:
|
||||
|
||||
h’(2) = f’(2)*g(2) + f(2)*g’(2)
|
||||
@@ -95,9 +88,6 @@ Let me verify the values from the table again:
|
||||
|
||||
* g’(2) = 7
|
||||
|
||||
|
||||
|
||||
|
||||
These seem correct as per the table.
|
||||
|
||||
Alternatively, perhaps I should consider if the functions f(x) and g(x) have any special properties or if there’s a pattern I’m missing. For example, is g(x) a constant function? Looking at the table:
|
||||
@@ -112,9 +102,6 @@ Alternatively, perhaps I should consider if the functions f(x) and g(x) have any
|
||||
|
||||
* g(2) = 1
|
||||
|
||||
|
||||
|
||||
|
||||
It doesn’t seem like g(x) is constant, as the values change. Similarly, f(x) is changing as well.
|
||||
|
||||
Maybe I should think about the units if this were a real-world problem, but since it’s an abstract mathematical problem, that might not help.
|
||||
@@ -151,13 +138,13 @@ So, my final answer is h’(2) = -29.
|
||||
|
||||
**Final Answer**
|
||||
|
||||
$$ \boxed{-29} $$
|
||||
` \boxed\{-29\} `
|
||||
|
||||
Example: Math Next
|
||||
|
||||
User
|
||||
|
||||
Evaluate the integral of the functions graphed using the formula for circles: 
|
||||
Evaluate the integral of the functions graphed using the formula for circles:
|
||||
|
||||
QVQ-72B-Preview
|
||||
|
||||
@@ -209,11 +196,11 @@ $(x - 9)^2 + y^2 = 9$
|
||||
|
||||
This is a circle with center $(9, 0)$ and radius 3.
|
||||
|
||||
Now, since all these are semicircles above the x-axis, their equations are actually $y = \sqrt{r^2 - (x - h)^2}$, where $r$ is the radius and $(h, k)$ is the center.
|
||||
Now, since all these are semicircles above the x-axis, their equations are actually $y = \sqrt{r^2 - (x - h)^2}$, where $r$ is the radius and $(h, k)$ is the center.
|
||||
|
||||
So, the integrals I need to evaluate are the areas under these semicircles from their left endpoints to their right endpoints.
|
||||
|
||||
The area of a semicircle is $\frac{1}{2}\pi r^2$, but since they’re only above the x-axis, it’s already a semicircle, so the integral should give me exactly that area.
|
||||
The area of a semicircle is $\frac{1}{2}\pi r^2$, but since they’re only above the x-axis, it’s already a semicircle, so the integral should give me exactly that area.
|
||||
|
||||
Alternatively, I can compute the integral of $y$ with respect to x over the interval where each semicircle exists.
|
||||
|
||||
@@ -221,29 +208,29 @@ Let’s consider the first semicircle: center at x=1, radius 1.
|
||||
|
||||
Its left endpoint is at x=0 and right endpoint at x=2.
|
||||
|
||||
The equation is $y = \sqrt{1^2 - (x - 1)^2}$.
|
||||
The equation is $y = \sqrt{1^2 - (x - 1)^2}$.
|
||||
|
||||
So, the integral from 0 to 2 of $y$ dx should be $\frac{1}{2}\pi (1)^2 = \frac{\pi}{2}$.
|
||||
So, the integral from 0 to 2 of $y$ dx should be $\frac{1}{2}\pi (1)^2 = \frac{\pi}{2}$.
|
||||
|
||||
Similarly, the second semicircle: center at x=4, radius 2.
|
||||
|
||||
Left endpoint at x=2, right endpoint at x=6.
|
||||
|
||||
Equation: $y = \sqrt{2^2 - (x - 4)^2} = \sqrt{4 - (x - 4)^2}$.
|
||||
Equation: $y = \sqrt{2^2 - (x - 4)^2} = \sqrt{4 - (x - 4)^2}$.
|
||||
|
||||
Integral from 2 to 6 of $y$ dx is $\frac{1}{2}\pi (2)^2 = 2\pi$.
|
||||
Integral from 2 to 6 of $y$ dx is $\frac{1}{2}\pi (2)^2 = 2\pi$.
|
||||
|
||||
Third semicircle: center at x=9, radius 3.
|
||||
|
||||
Left endpoint at x=6, right endpoint at x=12.
|
||||
|
||||
Equation: $y = \sqrt{3^2 - (x - 9)^2} = \sqrt{9 - (x - 9)^2}$.
|
||||
Equation: $y = \sqrt{3^2 - (x - 9)^2} = \sqrt{9 - (x - 9)^2}$.
|
||||
|
||||
Integral from 6 to 12 of $y$ dx is $\frac{1}{2}\pi (3)^2 = \frac{9\pi}{2}$.
|
||||
Integral from 6 to 12 of $y$ dx is $\frac{1}{2}\pi (3)^2 = \frac{9\pi}{2}$.
|
||||
|
||||
Now, if I add up these areas:
|
||||
|
||||
$\frac{\pi}{2} + 2\pi + \frac{9\pi}{2} = \frac{10\pi}{2} + 2\pi = 5\pi + 2\pi = 7\pi$.
|
||||
$\frac{\pi}{2} + 2\pi + \frac{9\pi}{2} = \frac{10\pi}{2} + 2\pi = 5\pi + 2\pi = 7\pi$.
|
||||
|
||||
Wait, but that seems too straightforward. Maybe I should check if there’s any overlap or if I’m missing something.
|
||||
|
||||
@@ -253,15 +240,15 @@ Alternatively, perhaps the question wants me to integrate each function over its
|
||||
|
||||
Let me try that approach.
|
||||
|
||||
For the first semicircle: $y = \sqrt{2x - x^2}$, from x=0 to x=2.
|
||||
For the first semicircle: $y = \sqrt{2x - x^2}$, from x=0 to x=2.
|
||||
|
||||
But actually, from my earlier work, $y = \sqrt{1 - (x - 1)^2}$.
|
||||
But actually, from my earlier work, $y = \sqrt{1 - (x - 1)^2}$.
|
||||
|
||||
Wait, but the original equation was $2x - x^2$, which I rearranged to $1 - (x - 1)^2$, so $y = \sqrt{1 - (x - 1)^2}$.
|
||||
Wait, but the original equation was $2x - x^2$, which I rearranged to $1 - (x - 1)^2$, so $y = \sqrt{1 - (x - 1)^2}$.
|
||||
|
||||
Similarly, the second one: $-12 + 8x - x^2 = 4 - (x - 4)^2$, so $y = \sqrt{4 - (x - 4)^2}$, from x=2 to x=6.
|
||||
Similarly, the second one: $-12 + 8x - x^2 = 4 - (x - 4)^2$, so $y = \sqrt{4 - (x - 4)^2}$, from x=2 to x=6.
|
||||
|
||||
Third one: $-72 + 18x - x^2 = 9 - (x - 9)^2$, so $y = \sqrt{9 - (x - 9)^2}$, from x=6 to x=12.
|
||||
Third one: $-72 + 18x - x^2 = 9 - (x - 9)^2$, so $y = \sqrt{9 - (x - 9)^2}$, from x=6 to x=12.
|
||||
|
||||
Now, integrating each of these from their respective limits should give the area under each semicircle.
|
||||
|
||||
@@ -269,27 +256,27 @@ Alternatively, since I already know the area of each semicircle, I can just sum
|
||||
|
||||
But perhaps to be more rigorous, I should actually compute the integrals.
|
||||
|
||||
First integral: $\int_{0}^{2} \sqrt{1 - (x - 1)^2} dx$.
|
||||
First integral: $\int_{0}^{2} \sqrt{1 - (x - 1)^2} dx$.
|
||||
|
||||
Let me make a substitution: let $u = x - 1$, then when x=0, u=-1; when x=2, u=1.
|
||||
|
||||
So, the integral becomes $\int_{-1}^{1} \sqrt{1 - u^2} du$.
|
||||
So, the integral becomes $\int_{-1}^{1} \sqrt{1 - u^2} du$.
|
||||
|
||||
This is the integral of the upper half of a circle with radius 1, which is indeed $\frac{\pi}{2}$.
|
||||
This is the integral of the upper half of a circle with radius 1, which is indeed $\frac{\pi}{2}$.
|
||||
|
||||
Second integral: $\int_{2}^{6} \sqrt{4 - (x - 4)^2} dx$.
|
||||
Second integral: $\int_{2}^{6} \sqrt{4 - (x - 4)^2} dx$.
|
||||
|
||||
Let $v = x - 4$, then when x=2, v=-2; when x=6, v=2.
|
||||
|
||||
So, $\int_{-2}^{2} \sqrt{4 - v^2} dv$, which is $\frac{\pi}{2} \times 2^2 = 2\pi$.
|
||||
So, $\int_{-2}^{2} \sqrt{4 - v^2} dv$, which is $\frac{\pi}{2} \times 2^2 = 2\pi$.
|
||||
|
||||
Third integral: $\int_{6}^{12} \sqrt{9 - (x - 9)^2} dx$.
|
||||
Third integral: $\int_{6}^{12} \sqrt{9 - (x - 9)^2} dx$.
|
||||
|
||||
Let $w = x - 9$, then when x=6, w=-3; when x=12, w=3.
|
||||
|
||||
So, $\int_{-3}^{3} \sqrt{9 - w^2} dw = \frac{\pi}{2} \times 3^2 = \frac{9\pi}{2}$.
|
||||
So, $\int_{-3}^{3} \sqrt{9 - w^2} dw = \frac{\pi}{2} \times 3^2 = \frac{9\pi}{2}$.
|
||||
|
||||
Adding them up: $\frac{\pi}{2} + 2\pi + \frac{9\pi}{2} = 7\pi$.
|
||||
Adding them up: $\frac{\pi}{2} + 2\pi + \frac{9\pi}{2} = 7\pi$.
|
||||
|
||||
Therefore, the total area is $7\pi$.
|
||||
|
||||
@@ -299,13 +286,13 @@ Hence, the total integral is $7\pi$.
|
||||
|
||||
**Final Answer**
|
||||
|
||||
$$ \boxed{7\pi} $$
|
||||
` \boxed\{7\pi\} `
|
||||
|
||||
Example: Life Next
|
||||
|
||||
User
|
||||
|
||||
I want to know the volume of this sofa 
|
||||
I want to know the volume of this sofa
|
||||
|
||||
QVQ-72B-Preview
|
||||
|
||||
@@ -317,9 +304,6 @@ So I have this L-shaped sofa with dimensions provided, and I need to find its vo
|
||||
|
||||
* Depth (chaise section): 180 cm
|
||||
|
||||
|
||||
|
||||
|
||||
First, I need to understand the shape and how it affects the volume calculation. An L-shaped sofa consists of two main parts: the straight section and the chaise lounge section.
|
||||
|
||||
Let me visualize this:
|
||||
@@ -328,9 +312,6 @@ Let me visualize this:
|
||||
|
||||
* The chaise section extends from the straight section, adding another 180 cm in depth and 90 cm in width.
|
||||
|
||||
|
||||
|
||||
|
||||
To find the volume, I should consider the sofa as a combination of rectangular prisms.
|
||||
|
||||
Perhaps I can divide the sofa into two parts:
|
||||
@@ -339,9 +320,6 @@ Perhaps I can divide the sofa into two parts:
|
||||
|
||||
2. The chaise section: another rectangular prism with dimensions 180 cm x 90 cm x 90 cm.
|
||||
|
||||
|
||||
|
||||
|
||||
Wait, but when I look at the dimensions, the chaise section is 180 cm in depth and 90 cm in width. However, since it’s an L-shape, the width of the chaise section might overlap with the straight section.
|
||||
|
||||
Let me double-check the dimensions.
|
||||
@@ -354,9 +332,6 @@ Looking at the image:
|
||||
|
||||
* The depth of the chaise is 180 cm.
|
||||
|
||||
|
||||
|
||||
|
||||
I think the straight section is 300 cm in length and 90 cm in width, and the chaise section is 180 cm in depth and 90 cm in width, attached to the straight section.
|
||||
|
||||
In this case, the volume would be the sum of the volumes of these two sections.
|
||||
@@ -497,9 +472,6 @@ Divide the sofa into three parts:
|
||||
|
||||
3. Subtract the overlapping part: 90 cm x 90 cm x 90 cm
|
||||
|
||||
|
||||
|
||||
|
||||
Then, Volume_total = (300 cm x 90 cm x 90 cm) + (180 cm x 90 cm x 90 cm) - (90 cm x 90 cm x 90 cm)
|
||||
|
||||
Calculate each part:
|
||||
@@ -524,13 +496,13 @@ Therefore, the volume of the sofa is 3,159,000 cubic cm.
|
||||
|
||||
**Final Answer**
|
||||
|
||||
$$ \boxed{3159000\ \text{cubic cm}} $$
|
||||
` \boxed\{3159000\ \text\{cubic cm\}\} `
|
||||
|
||||
Example: Chemistry Next
|
||||
|
||||
User
|
||||
|
||||
图片中的滤液E是什么化学物质? 
|
||||
图片中的滤液E是什么化学物质?
|
||||
|
||||
QVQ-72B-Preview
|
||||
|
||||
@@ -634,7 +606,7 @@ Example: Biology Next
|
||||
|
||||
User
|
||||
|
||||
请解答这道题 
|
||||
请解答这道题
|
||||
|
||||
QVQ-72B-Preview
|
||||
|
||||
@@ -728,7 +700,7 @@ Example: Geometry Next
|
||||
|
||||
User
|
||||
|
||||
请回答图片中的问题? 
|
||||
请回答图片中的问题?
|
||||
|
||||
QVQ-72B-Preview
|
||||
|
||||
@@ -788,7 +760,7 @@ S = (1/2)|0*(2b - 2b/5) + 0*(2b/5 - 0) + (4a/5)*(0 - 2b)|
|
||||
|
||||
现在,矩形ABCD的面积是长乘宽,即2a * 2b = 4ab
|
||||
|
||||
所以,概率P = S_{ABO} / S_{ABCD} = (4ab/5) / (4ab) = 1/5
|
||||
所以,概率P = S_{ABO} / S_{ABCD} = (4ab/5) / (4ab) = 1/5
|
||||
|
||||
但是,我感觉这个答案可能不对,因为直觉上三角形ABO的面积应该小于矩形的1/5。可能我哪里算错了。
|
||||
|
||||
@@ -860,7 +832,7 @@ S = (1/2)|x1(y2 - y3) + x2(y3 - y1) + x3(y1 - y2)|
|
||||
|
||||
**答案**
|
||||
|
||||
\boxed{\dfrac{1}{5}}
|
||||
\boxed{\dfrac{1}{5}}
|
||||
|
||||
# Next Step
|
||||
|
||||
|
||||
@@ -12,8 +12,6 @@ author: "Zen LM Team"
|
||||
|
||||
Last December, we launched QVQ-72B-Preview as an exploratory model, but it had many issues. Today, we are officially releasing the first version of QVQ-Max, our visual reasoning model. This model can not only “understand” the content in images and videos but also analyze and reason with this information to provide solutions. From math problems to everyday questions, from programming code to artistic creation, QVQ-Max has demonstrated impressive capabilities. Though this is just our first version, its potential is already eye-catching.
|
||||
|
||||
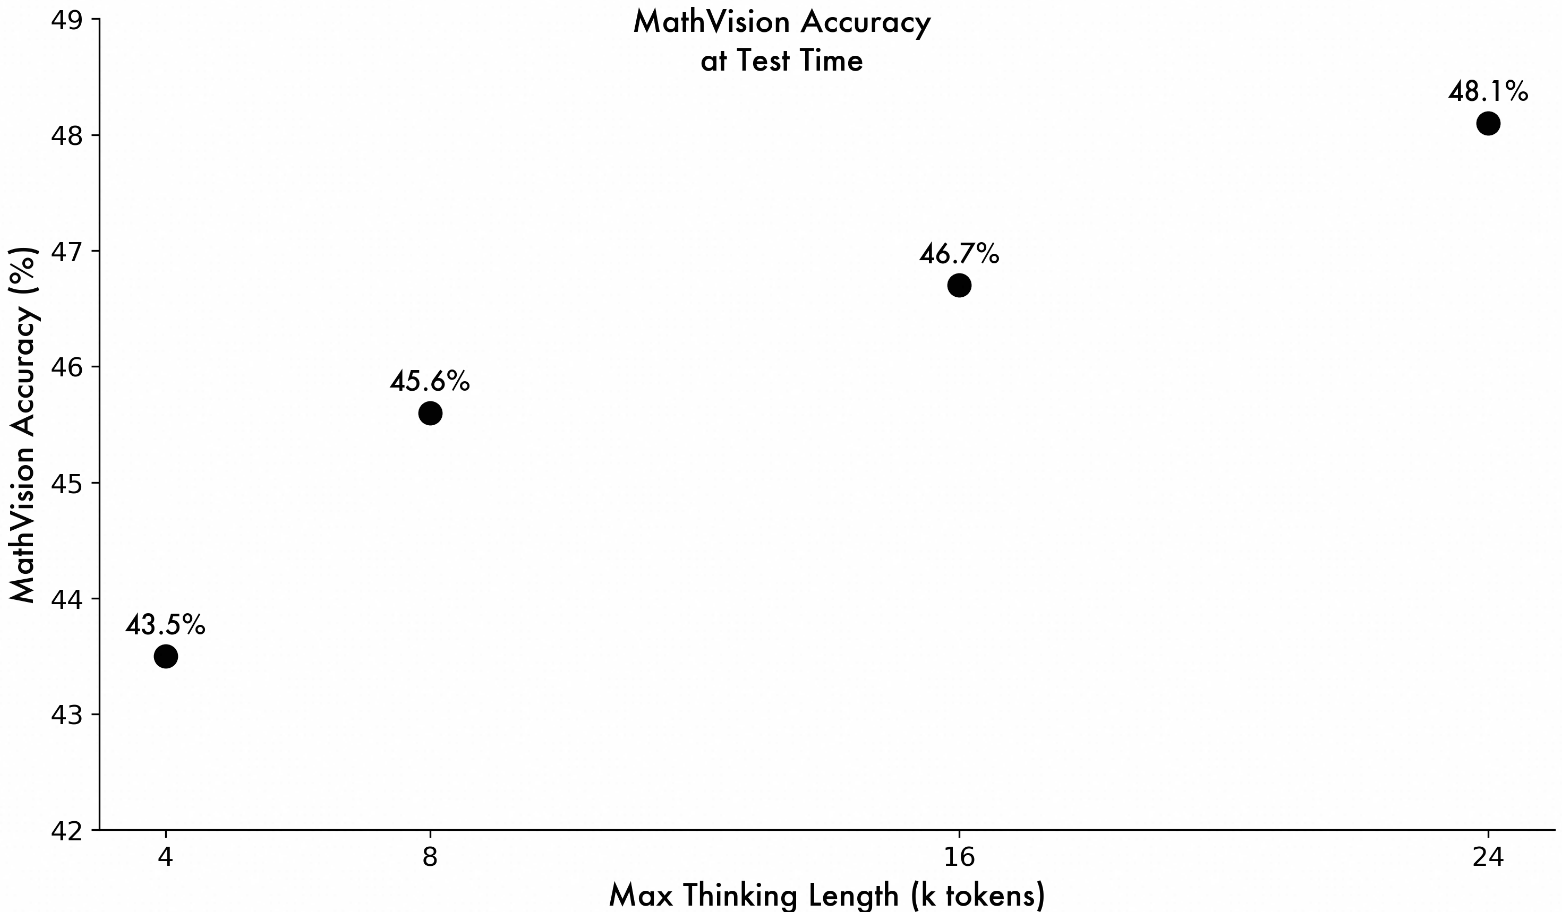
|
||||
|
||||
MathVision is a benchmark that aggregates various challenging multimodal mathematical problems, and we evaluate a model’s ability to solve complex math problems based on its performance on this benchmark. As shown in the figure, by adjusting the maximum length of the model’s thinking process, we observe a continuous improvement in the model’s accuracy on MathVision, demonstrating the immense potential of the model.
|
||||
|
||||
In the following sections, we will discuss the design philosophy behind QVQ-Max, its actual capabilities, and what it can do for you.
|
||||
@@ -43,9 +41,6 @@ Identifying content in an image is not enough. QVQ-Max can further analyze this
|
||||
3. **Flexible Application: From Problem-Solving to Creation**
|
||||
Beyond analysis and reasoning, QVQ-Max can also perform interesting tasks like helping you design illustrations, generate short video scripts, or even create role-playing content based on your requirements. If you upload a rough sketch, it might help you refine it into a complete piece. Upload a regular photo, and it can transform into a sharp critic or even a fortune-teller.
|
||||
|
||||
|
||||
|
||||
|
||||
* * *
|
||||
|
||||
## **Demo Cases**
|
||||
@@ -58,9 +53,6 @@ QVQ-Max has a wide range of applications, whether in learning, work, or daily li
|
||||
|
||||
* **Life Helper** : In daily life, QVQ-Max can offer practical advice. For instance, it can recommend outfit combinations based on photos of your wardrobe, or guide you through cooking a new dish based on recipe images.
|
||||
|
||||
|
||||
|
||||
|
||||
Multi-image Recognition Next
|
||||
|
||||
QVQ-Max-Preview
|
||||
@@ -91,6 +83,4 @@ The current version of QVQ-Max is just the first iteration, and there’s still
|
||||
2. **Visual Agent** : Improve the model’s ability to handle multi-step and more complex tasks, such as operating smartphones or computers, and even playing games.
|
||||
3. **Better Interaction** : Expand beyond text-based interaction to include more modalities, such as tool verification and visual generation, allowing for richer user experiences.
|
||||
|
||||
|
||||
|
||||
Overall, QVQ-Max is a visual reasoning model that possesses both “vision” and “intellect.” It doesn’t just recognize the content in images; it combines this information to analyze, reason, and even complete creative tasks. Although it’s still in its growth phase, it has already shown great potential. Through continuous optimization, we aim to make QVQ-Max a truly practical visual agent that helps everyone solve real-world problems.
|
||||
@@ -19,8 +19,6 @@ We adopt the following approach:
|
||||
2. Subsequently, we synthesize fine-tuning data using the agent and apply automated filtering to ensure quality.
|
||||
3. Finally, we use the synthetic data to fine-tune a pretrained model, resulting in a _strong_ 1M-context chat model.
|
||||
|
||||
|
||||
|
||||
This blog primarily focuses on Step 1, with details of the subsequent steps to be revealed in the coming weeks or months.
|
||||
|
||||
# Building the Agent
|
||||
@@ -33,12 +31,10 @@ A naive approach to processing a 1M-token context is to simply use retrieval-aug
|
||||
|
||||
The challenge lies in how to pinpoint the chunks that are the most relevant. After several trials, we have come up with a keyword-based solution:
|
||||
|
||||
* Step 1: Instruct the chat model to separate the instruction and the non-instruction information in the user’s query. For instance, transform the user query `"You should reply in 2000 words and be as detailed as possible. My question is, when were bicycles invented? Reply in English."` into `{"information": ["when were bicycles invented"], "instruction": ["reply in 2000 words", "be as detailed as possible", "reply in English"]}`.
|
||||
* Step 2: Ask the chat model to deduce multilingual keywords from the informational part of the query. For example, the phrase `"when were bicycles invented"` would be converted to `{"keywords_en": ["bicycles", "invented", "when"], "keywords_zh": ["自行车", "发明", "时间"]}`.
|
||||
* Step 3: Employ the BM25 algorithm, a traditional keyword-based retrieval method, to locate the chunks that most relevant to the extracted keywords.
|
||||
|
||||

|
||||
|
||||
#### Dataflows of retrieval-augmented generation
|
||||
|
||||
We have also experimented with vector-based retrieval. However, in most cases, it does not offer a significant enough improvement to outweigh the additional complexity that arises from the necessity of deploying a separate embedding model.
|
||||
@@ -55,8 +51,6 @@ To address this limitation, we employ a brute-force strategy to reduce the chanc
|
||||
* Step 2: We then take the outputs that are not `"None"` (the relevant sentences) and use them as the search query to retrieve the most relevant chunks (within an 8k-context limit) using BM25.
|
||||
* Step 3: Finally, we generate the final answer based on the retrieved context in the same manner as RAG.
|
||||
|
||||

|
||||
|
||||
#### Dataflows of chunk-by-chunk reading
|
||||
|
||||
[Agent Code](https://github.com/QwenLM/Qwen-Agent/blob/main/examples/parallel_doc_qa.py)
|
||||
@@ -66,7 +60,8 @@ To address this limitation, we employ a brute-force strategy to reduce the chanc
|
||||
A classic challenge in document-based question-answering is multi-hop reasoning. For example, consider answering the question “What vehicle was invented in the same century as the Fifth Symphony was composed?” when given a long document containing relevant facts. The model needs to first determine the answer to the sub-question “In which century was the Fifth Symphony composed?” which is the 19th century. Then, it can realize that a chunk containing “Bicycles were invented in the 19th century” is actually relevant to the original question.
|
||||
|
||||
Tool-calling (also known as function-calling) agents or ReAct agents are classic solutions that have built-in capabilities for question decomposition and step-by-step reasoning. We therefore wrap the aforementioned Level-2 agent as a tool to be called by a tool-calling agent. The tool-calling agent conducts multi-hop reasoning as follows:
|
||||
[code]
|
||||
```
|
||||
|
||||
Ask the Lv3-Agent a question.
|
||||
while (the Lv3-Agent cannot answer the question based on its memory) {
|
||||
The Lv3-Agent proposes a new sub-question to be answered.
|
||||
@@ -75,9 +70,8 @@ Tool-calling (also known as function-calling) agents or ReAct agents are classic
|
||||
}
|
||||
The Lv3-Agent provides the final answer to the original question.
|
||||
|
||||
[/code]
|
||||
|
||||

|
||||
```
|
||||
|
||||
#### Dataflows of step-by-step reasioning
|
||||
|
||||
@@ -90,24 +84,18 @@ We conducted experiments on two benchmarks designed for 256k-context:
|
||||
* NeedleBench is a benchmark designed to test whether a model can identify the most relevant sentences within a context filled with numerous irrelevant ones, akin to finding needles in a haystack. Answering a question may require the simultaneous discovery of several “needles” and the execution of multi-hop reasoning.
|
||||
* LV-Eval is a challenging benchmark that demands the comprehension of multiple pieces of evidence at once. We modified the evaluation metric from LV-Eval’s original version because it was excessively stringent, resulting in a high number of false negatives.
|
||||
|
||||
|
||||
|
||||
We compared the following methods:
|
||||
|
||||
* The 32k-Model, a 7B chat model fine-tuned mainly on 8k-context samples, with a few 32k-context samples, extended to a 256k context using a training-free method such as RoPE-based extrapolation.
|
||||
* The 4k-RAG, which uses the same model as the 32k-Model but applies the Lv1-Agent RAG strategy. It only retrieves and processes the most relevant 4k context.
|
||||
* The 4k-Agent, using the same model as the 32k-Model, follows the more advanced agent strategy described above. The agent strategy utilizes only a 4k-context with the model each time.
|
||||
|
||||

|
||||
|
||||
The empirical data reveals:
|
||||
|
||||
* In scenarios with short contexts, the 4k-RAG may perform less effectively than the 32k-Model. This could be due to difficulties in retrieving the right information or understanding multiple parts.
|
||||
* Conversely, as document length increases, the 4k-RAG becomes more likely to outperform the 32k-Model. This trend suggests the 32k-Model isn’t optimally trained for handling long contexts.
|
||||
* Significantly, the 4K-Agent consistently surpasses the 32k-Model and the 4k-RAG. Its ability to read all the context in chunks allows it to avoid the limitations posed by under-trained context lengths.
|
||||
|
||||
|
||||
|
||||
Overall, the 32k-Model should ideally outshine all if it receives proper training. However, due to its under-training in practice, the 32k-Model under-performs compared to the 4k-Agent.
|
||||
|
||||
Finally, we have also tested the agent on a 1-million-token pressure test (finding a single needle in a haystack of 1 million tokens) and found that it functioned properly. However, we still lack a more reliable quantitative benchmark for evaluating its performance in handling contexts of 1 million tokens in real-world applications.
|
||||
@@ -123,7 +111,8 @@ In this blog, we have introduced how to build the agent that is capable of handl
|
||||
We hope to provide you with models that have improved capabilities for handling long contexts, as well as a more user-friendly infrastructure framework in the near future.
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen-agent-2405,
|
||||
title = {Generalizing an LLM from 8k to 1M Context using Qwen-Agent},
|
||||
url = {https://qwenlm.github.io/blog/qwen-agent-2405/},
|
||||
@@ -132,4 +121,5 @@ We hope to provide you with models that have improved capabilities for handling
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -6,8 +6,6 @@ date: "2025-08-19"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||
|
||||
|
||||
[QWEN CHAT](https://qwen.ai) [GITHUB](https://github.com/QwenLM/Qwen-Image) [HUGGING FACE](https://huggingface.co/Qwen/Qwen-Image-Edit) [MODELSCOPE](https://modelscope.cn/models/Qwen/Qwen-Image-Edit) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
We are excited to introduce Qwen-Image-Edit, the image editing version of Qwen-Image. Built upon our 20B Qwen-Image model, Qwen-Image-Edit successfully extends Qwen-Image’s unique text rendering capabilities to image editing tasks, enabling precise text editing. Furthermore, Qwen-Image-Edit simultaneously feeds the input image into zen-VL (for visual semantic control) and the VAE Encoder (for visual appearance control), achieving capabilities in both semantic and appearance editing. To experience the latest model, visit [Qwen Chat](https://qwen.ai) and select the “Image Editing” feature.
|
||||
@@ -20,21 +18,18 @@ Key Features:
|
||||
|
||||
* **Strong Benchmark Performance** : Evaluations on multiple public benchmarks demonstrate that Qwen-Image-Edit achieves state-of-the-art (SOTA) performance in image editing tasks, establishing it as a powerful foundation model for image editing.
|
||||
|
||||
|
||||
|
||||
|
||||
## Showcase
|
||||
|
||||
One of the highlights of Qwen-Image-Edit lies in its powerful capabilities for semantic and appearance editing. Semantic editing refers to modifying image content while preserving the original visual semantics. To intuitively demonstrate this capability, let’s take Qwen’s mascot—Capybara—as an example:
|
||||
|
||||
As can be seen, although most pixels in the edited image differ from those in the input image (the leftmost image), the character consistency of Capybara is perfectly preserved. Qwen-Image-Edit’s powerful semantic editing capability enables effortless and diverse creation of original IP content. Furthermore, on Qwen Chat, we designed a series of editing prompts centered around the 16 MBTI personality types. Leveraging these prompts, we successfully created a set of MBTI-themed emoji packs based on our mascot Capybara, effortlessly expanding the IP’s reach and expression.
|
||||
As can be seen, although most pixels in the edited image differ from those in the input image (the leftmost image), the character consistency of Capybara is perfectly preserved. Qwen-Image-Edit’s powerful semantic editing capability enables effortless and diverse creation of original IP content. Furthermore, on Qwen Chat, we designed a series of editing prompts centered around the 16 MBTI personality types. Leveraging these prompts, we successfully created a set of MBTI-themed emoji packs based on our mascot Capybara, effortlessly expanding the IP’s reach and expression.
|
||||
|
||||
Moreover, novel view synthesis is another key application scenario in semantic editing. As shown in the two example images below, Qwen-Image-Edit can not only rotate objects by 90 degrees, but also perform a full 180-degree rotation, allowing us to directly see the back side of the object:Another typical application of semantic editing is style transfer. For instance, given an input portrait, Qwen-Image-Edit can easily transform it into various artistic styles such as Studio Ghibli. This capability holds significant value in applications like virtual avatar creation:In addition to semantic editing, appearance editing is another common image editing requirement. Appearance editing emphasizes keeping certain regions of the image completely unchanged while adding, removing, or modifying specific elements. The image below illustrates a case where a signboard is added to the scene. As shown, Qwen-Image-Edit not only successfully inserts the signboard but also generates a corresponding reflection, demonstrating exceptional attention to detail.Below is another interesting example, demonstrating how to remove fine hair strands and other small objects from an image.Additionally, the color of a specific letter “n” in the image can be modified to blue, enabling precise editing of particular elements.Appearance editing also has wide-ranging applications in scenarios such as adjusting a person’s background or changing clothing. The three images below demonstrate these practical use cases respectively.
|
||||
Moreover, novel view synthesis is another key application scenario in semantic editing. As shown in the two example images below, Qwen-Image-Edit can not only rotate objects by 90 degrees, but also perform a full 180-degree rotation, allowing us to directly see the back side of the object:Another typical application of semantic editing is style transfer. For instance, given an input portrait, Qwen-Image-Edit can easily transform it into various artistic styles such as Studio Ghibli. This capability holds significant value in applications like virtual avatar creation:In addition to semantic editing, appearance editing is another common image editing requirement. Appearance editing emphasizes keeping certain regions of the image completely unchanged while adding, removing, or modifying specific elements. The image below illustrates a case where a signboard is added to the scene. As shown, Qwen-Image-Edit not only successfully inserts the signboard but also generates a corresponding reflection, demonstrating exceptional attention to detail.Below is another interesting example, demonstrating how to remove fine hair strands and other small objects from an image.Additionally, the color of a specific letter “n” in the image can be modified to blue, enabling precise editing of particular elements.Appearance editing also has wide-ranging applications in scenarios such as adjusting a person’s background or changing clothing. The three images below demonstrate these practical use cases respectively.
|
||||
|
||||
Another standout feature of Qwen-Image-Edit is its accurate text editing capability, which stems from Qwen-Image’s deep expertise in text rendering. As shown below, the following two cases vividly demonstrate Qwen-Image-Edit’s powerful performance in editing English text:Qwen-Image-Edit can also directly edit Chinese posters, enabling not only modifications to large headline text but also precise adjustments to even small and intricate text elements.
|
||||
Another standout feature of Qwen-Image-Edit is its accurate text editing capability, which stems from Qwen-Image’s deep expertise in text rendering. As shown below, the following two cases vividly demonstrate Qwen-Image-Edit’s powerful performance in editing English text:Qwen-Image-Edit can also directly edit Chinese posters, enabling not only modifications to large headline text but also precise adjustments to even small and intricate text elements.
|
||||
|
||||
Finally, let’s walk through a concrete image editing example to demonstrate how to use a chained editing approach to progressively correct errors in a calligraphy artwork generated by Qwen-Image:In this artwork, several Chinese characters contain generation errors. We can leverage Qwen-Image-Edit to correct them step by step. For instance, we can draw bounding boxes on the original image to mark the regions that need correction, instructing Qwen-Image-Edit to fix these specific areas. Here, we want the character “稽” to be correctly written within the red box, and the character “亭” to be accurately rendered in the blue region.However, in practice, the character “稽” is relatively obscure, and the model fails to correct it correctly in one step. The lower-right component of “稽” should be “旨” rather than “日”. At this point, we can further highlight the “日” portion with a red box, instructing Qwen-Image-Edit to fine-tune this detail and replace it with “旨”.
|
||||
Finally, let’s walk through a concrete image editing example to demonstrate how to use a chained editing approach to progressively correct errors in a calligraphy artwork generated by Qwen-Image:In this artwork, several Chinese characters contain generation errors. We can leverage Qwen-Image-Edit to correct them step by step. For instance, we can draw bounding boxes on the original image to mark the regions that need correction, instructing Qwen-Image-Edit to fix these specific areas. Here, we want the character “稽” to be correctly written within the red box, and the character “亭” to be accurately rendered in the blue region.However, in practice, the character “稽” is relatively obscure, and the model fails to correct it correctly in one step. The lower-right component of “稽” should be “旨” rather than “日”. At this point, we can further highlight the “日” portion with a red box, instructing Qwen-Image-Edit to fine-tune this detail and replace it with “旨”.
|
||||
|
||||
Isn’t it amazing? With this chained, step-by-step editing approach, we can continuously correct character errors until the desired final result is achieved.Finally, we have successfully obtained a completely correct calligraphy version of _Lantingji Xu (Orchid Pavilion Preface)_!
|
||||
Isn’t it amazing? With this chained, step-by-step editing approach, we can continuously correct character errors until the desired final result is achieved.Finally, we have successfully obtained a completely correct calligraphy version of _Lantingji Xu (Orchid Pavilion Preface)_!
|
||||
|
||||
In summary, we hope that Qwen-Image-Edit can further advance the field of image generation, truly lower the technical barriers to visual content creation, and inspire even more innovative applications.
|
||||
@@ -8,8 +8,6 @@ date: "2025-08-04"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||
|
||||
|
||||
[GITHUB](https://github.com/QwenLM/Qwen-Image) [HUGGING FACE](https://huggingface.co/Qwen/Qwen-Image) [MODELSCOPE](https://modelscope.cn/models/Qwen/Qwen-Image) [DEMO](https://modelscope.cn/aigc/imageGeneration?tab=advanced) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
We are thrilled to release **Qwen-Image** , a 20B MMDiT image foundation model that achieves significant advances in complex text rendering and precise image editing. To try the latest model, feel free to visit [Qwen Chat](https://chat.qwenlm.ai) and choose “Image Generation”.
|
||||
@@ -20,76 +18,64 @@ The key features include:
|
||||
* **Consistent Image Editing** : Through our enhanced multi-task training paradigm, Qwen-Image achieves exceptional performance in preserving both semantic meaning and visual realism during editing operations.
|
||||
* **Strong Cross-Benchmark Performance** : Evaluated on multiple public benchmarks, Qwen-Image consistently outperforms existing models across diverse generation and editing tasks, establishing a strong foundation model for image generation.
|
||||
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
We present a comprehensive evaluation of Qwen-Image across multiple public benchmarks, including GenEval, DPG, and OneIG-Bench for general image generation, as well as GEdit, ImgEdit, and GSO for image editing. Qwen-Image achieves state-of-the-art performance on all benchmarks, demonstrating its strong capabilities in both image generation and editing. Furthermore, results on LongText-Bench, ChineseWord, and TextCraft show that it excels in text rendering—particularly in Chinese text generation—outperforming existing state-of-the-art models by a significant margin. This highlights Qwen-Image’s unique position as a leading image generation model that combines broad general capability with exceptional text rendering precision.
|
||||
|
||||

|
||||
|
||||
## Demo
|
||||
|
||||
One of Qwen-Image’s outstanding capabilities is its ability to achieve high-fidelity text rendering in different scenarios. Let’s take a look at the following Chinese rendering case:
|
||||
|
||||
> 宫崎骏的动漫风格。平视角拍摄,阳光下的古街热闹非凡。一个穿着青衫、手里拿着写着“阿里云”卡片的逍遥派弟子站在中间。旁边两个小孩惊讶的看着他。左边有一家店铺挂着“云存储”的牌子,里面摆放着发光的服务器机箱,门口两个侍卫守护者。右边有两家店铺,其中一家挂着“云计算”的牌子,一个穿着旗袍的美丽女子正看着里面闪闪发光的电脑屏幕;另一家店铺挂着“云模型”的牌子,门口放着一个大酒缸,上面写着“千问”,一位老板娘正在往里面倒发光的代码溶液。
|
||||
|
||||
|
||||
|
||||
The model not only accurately captures Miyazaki’s anime style, but also features shop signs like “云存储” “云计算” and “云模型” as well as the “千问” on the wine jars, all rendered realistically and accurately with the depth of field. The poses and expressions of the characters are also perfectly preserved.
|
||||
|
||||
Let’s look at another example of Chinese rendering:
|
||||
|
||||
> 一副典雅庄重的对联悬挂于厅堂之中,房间是个安静古典的中式布置,桌子上放着一些青花瓷,对联上左书“义本生知人机同道善思新”,右书“通云赋智乾坤启数高志远”, 横批“智启通义”,字体飘逸,中间挂在一着一副中国风的画作,内容是岳阳楼。
|
||||
|
||||
The model accurately drew the left and right couplets and the horizontal scroll, applied calligraphy effects, and accurately generated the Yueyang Tower in the middle. The blue and white porcelain on the table also looked very realistic.
|
||||
The model accurately drew the left and right couplets and the horizontal scroll, applied calligraphy effects, and accurately generated the Yueyang Tower in the middle. The blue and white porcelain on the table also looked very realistic.
|
||||
|
||||
So, how does the model perform on English? Let’s look at an English rendering example:
|
||||
|
||||
> Bookstore window display. A sign displays “New Arrivals This Week”. Below, a shelf tag with the text “Best-Selling Novels Here”. To the side, a colorful poster advertises “Author Meet And Greet on Saturday” with a central portrait of the author. There are four books on the bookshelf, namely “The light between worlds” “When stars are scattered” “The slient patient” “The night circus”
|
||||
|
||||
In this example, the model not only accurately outputs “New Arrivals This Week”, but also accurately generates the cover text of four books: “The light between worlds”, “When stars are scattered”, “The slient patient”, and “The night circus”.
|
||||
In this example, the model not only accurately outputs “New Arrivals This Week”, but also accurately generates the cover text of four books: “The light between worlds”, “When stars are scattered”, “The slient patient”, and “The night circus”.
|
||||
|
||||
Let’s look at a more complex case of English rendering:
|
||||
|
||||
> A slide featuring artistic, decorative shapes framing neatly arranged textual information styled as an elegant infographic. At the very center, the title “Habits for Emotional Wellbeing” appears clearly, surrounded by a symmetrical floral pattern. On the left upper section, “Practice Mindfulness” appears next to a minimalist lotus flower icon, with the short sentence, “Be present, observe without judging, accept without resisting”. Next, moving downward, “Cultivate Gratitude” is written near an open hand illustration, along with the line, “Appreciate simple joys and acknowledge positivity daily”. Further down, towards bottom-left, “Stay Connected” accompanied by a minimalistic chat bubble icon reads “Build and maintain meaningful relationships to sustain emotional energy”. At bottom right corner, “Prioritize Sleep” is depicted next to a crescent moon illustration, accompanied by the text “Quality sleep benefits both body and mind”. Moving upward along the right side, “Regular Physical Activity” is near a jogging runner icon, stating: “Exercise boosts mood and relieves anxiety”. Finally, at the top right side, appears “Continuous Learning” paired with a book icon, stating “Engage in new skill and knowledge for growth”. The slide layout beautifully balances clarity and artistry, guiding the viewers naturally along each text segment.
|
||||
|
||||
In this case, the model needs to generate 6 submodules, each with its own icon, title, and corresponding introductory text. Qwen-Image has completed the layout.
|
||||
In this case, the model needs to generate 6 submodules, each with its own icon, title, and corresponding introductory text. Qwen-Image has completed the layout.
|
||||
|
||||
What about smaller text? Let us test it:
|
||||
|
||||
> A man in a suit is standing in front of the window, looking at the bright moon outside the window. The man is holding a yellowed paper with handwritten words on it: “A lantern moon climbs through the silver night, Unfurling quiet dreams across the sky, Each star a whispered promise wrapped in light, That dawn will bloom, though darkness wanders by.” There is a cute cat on the windowsill.
|
||||
|
||||
In this case, the paper is less than one-tenth of the entire image, and the paragraph of text is relatively long, but the model still accurately generates the text on the paper.
|
||||
In this case, the paper is less than one-tenth of the entire image, and the paragraph of text is relatively long, but the model still accurately generates the text on the paper.
|
||||
|
||||
What if there are more words? Let’s try a harder case:
|
||||
|
||||
> 一个穿着"QWEN"标志的T恤的中国美女正拿着黑色的马克笔面相镜头微笑。她身后的玻璃板上手写体写着 “一、Qwen-Image的技术路线: 探索视觉生成基础模型的极限,开创理解与生成一体化的未来。二、Qwen-Image的模型特色:1、复杂文字渲染。支持中英渲染、自动布局; 2、精准图像编辑。支持文字编辑、物体增减、风格变换。三、Qwen-Image的未来愿景:赋能专业内容创作、助力生成式AI发展。”
|
||||
|
||||
You can see that the model has completely generated a complete handwritten paragraph on the glass plate.
|
||||
You can see that the model has completely generated a complete handwritten paragraph on the glass plate.
|
||||
|
||||
What if it’s bilingual? For the same scenario, let’s try this prompt:
|
||||
|
||||
> 一个穿着"QWEN"标志的T恤的中国美女正拿着黑色的马克笔面相镜头微笑。她身后的玻璃板上手写体写着 “Meet Qwen-Image – a powerful image foundation model capable of complex text rendering and precise image editing. 欢迎了解Qwen-Image, 一款强大的图像基础模型,擅长复杂文本渲染与精准图像编辑”
|
||||
|
||||
As you can see, the model can switch between two languages at any time when rendering text.
|
||||
As you can see, the model can switch between two languages at any time when rendering text.
|
||||
|
||||
Qwen-Image’s text capabilities make it easy to create posters, such as:
|
||||
|
||||
> A movie poster. The first row is the movie title, which reads “Imagination Unleashed”. The second row is the movie subtitle, which reads “Enter a world beyond your imagination”. The third row reads “Cast: Qwen-Image”. The fourth row reads “Director: The Collective Imagination of Humanity”. The central visual features a sleek, futuristic computer from which radiant colors, whimsical creatures, and dynamic, swirling patterns explosively emerge, filling the composition with energy, motion, and surreal creativity. The background transitions from dark, cosmic tones into a luminous, dreamlike expanse, evoking a digital fantasy realm. At the bottom edge, the text “Launching in the Cloud, August 2025” appears in bold, modern sans-serif font with a glowing, slightly transparent effect, evoking a high-tech, cinematic aesthetic. The overall style blends sci-fi surrealism with graphic design flair—sharp contrasts, vivid color grading, and layered visual depth—reminiscent of visionary concept art and digital matte painting, 32K resolution, ultra-detailed.
|
||||
|
||||

|
||||
|
||||
Since we can make posters, of course we can also make PPTs directly. Let’s look at a case of making PPTs in Chinese:
|
||||
|
||||
> 一张企业级高质量PPT页面图像,整体采用科技感十足的星空蓝为主色调,背景融合流动的发光科技线条与微光粒子特效,营造出专业、现代且富有信任感的品牌氛围;页面顶部左侧清晰展示橘红色Alibaba标志,色彩鲜明、辨识度高。主标题位于画面中央偏上位置,使用大号加粗白色或浅蓝色字体写着“通义千问视觉基础模型”,字体现代简洁,突出技术感;主标题下方紧接一行楷体中文文字:“原生中文·复杂场景·自动布局”,字体柔和优雅,形成科技与人文的融合。下方居中排布展示了四张与图片,分别是:一幅写实与水墨风格结合的梅花特写,枝干苍劲、花瓣清雅,背景融入淡墨晕染与飘雪效果,体现坚韧不拔的精神气质;上方写着黑色的楷体"梅傲"。一株生长于山涧石缝中的兰花,叶片修长、花朵素净,搭配晨雾缭绕的自然环境,展现清逸脱俗的文人风骨;上方写着黑色的楷体"兰幽"。一组迎风而立的翠竹,竹叶随风摇曳,光影交错,背景为青灰色山岩与流水,呈现刚柔并济、虚怀若谷的文化意象;上方写着黑色的楷体"竹清"。一片盛开于秋日庭院的菊花丛,花色丰富、层次分明,配以落叶与古亭剪影,传递恬然自适的生活哲学;上方写着黑色的楷体"菊淡"。所有图片采用统一尺寸与边框样式,呈横向排列。页面底部中央用楷体小字写明“2025年8月,敬请期待”,排版工整、结构清晰,整体风格统一且细节丰富,极具视觉冲击力与品牌调性。
|
||||
|
||||
In fact, beyond text processing, Qwen-Image also excels at general image generation, supporting a wide range of artistic styles. From photorealistic scenes to impressionistic paintings, from anime styles to minimalist designs, the model flexibly responds to a wide range of creative prompts, becoming a versatile tool for artists, designers, and storytellers. We will describe these in detail in our technical report.
|
||||
|
||||

|
||||
|
||||
In terms of image editing, Qwen-Image supports a variety of operations, including style transfer, additions, deletions, detail enhancement, text editing, and character pose adjustment. This allows even ordinary users to easily achieve professional-level image editing. We will describe these in detail in our technical report.
|
||||
|
||||

|
||||
|
||||
In summary, we hope that Qwen-Image can further promote the development of image generation, lower the technical barriers to visual content creation, and inspire more innovative applications. At the same time, we also look forward to the active participation and feedback of the community to jointly build an open, transparent, and sustainable generative AI ecosystem.
|
||||
@@ -11,7 +11,7 @@ author: "Zen LM Team"
|
||||
|
||||
Previously, we opensourced a series of Qwen1.5 model ranging from 0.5 to 110 billion parameters. Now, we release a larger model, Qwen-Max-0428. Qwen-Max-0428 is an instruction-tuned model for chat service. Very recently, it is available via [Chatbot Arena](https://chat.lmsys.org/) and it has now become the top-10 in the leaderboard. Furthermore, our evaluation of MT-Bench also demonstrates that the new model outperforms our previous largest model Qwen1.5-110B-Chat.
|
||||
|
||||
Models| MT-Bench| Arena
|
||||
Models| MT-Bench| Arena
|
||||
---|---|---
|
||||
Qwen1.5-110B-Chat| 8.88| 1172
|
||||
Qwen-Max-0428| 8.96| 1186
|
||||
@@ -19,7 +19,8 @@ Qwen-Max-0428| 8.96| 1186
|
||||
We provide a demo of chat service of Qwen-Max-0428 ([link](https://huggingface.co/spaces/Qwen/Qwen-Max-0428)) in Hugging Face Spaces:
|
||||
|
||||
It is also accessible through the official DashScope API ([link](https://dashscope.aliyun.com)). Additionally, now the DashScope API is compatible with the OpenAI API format. Below is an example of usage:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from openai import OpenAI
|
||||
|
||||
client = OpenAI(
|
||||
@@ -34,12 +35,14 @@ It is also accessible through the official DashScope API ([link](https://dashsco
|
||||
)
|
||||
print(completion.choices[0].message)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
This model is available in our web service and APP ([link](https://tongyi.aliyun.com/qianwen/), only accessible in mainland China). Enjoy!
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen1.5,
|
||||
title = {Introducing Qwen1.5},
|
||||
url = {https://qwenlm.github.io/blog/qwen1.5/},
|
||||
@@ -48,4 +51,5 @@ This model is available in our web service and APP ([link](https://tongyi.aliyun
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -14,8 +14,6 @@ Since the surge in interest sparked by Mixtral, research on mixture-of-expert (M
|
||||
|
||||
Compared to Qwen1.5-7B, which contains 6.5 billion non-embedding parameters, Qwen1.5-MoE-A2.7B contains only 2.0 billion non-embedding parameters, approximately one-third of Qwen1.5-7B’s size. Notably, it achieves a 75% decrease in training expenses and accelerates inference speed by a factor of 1.74, offering substantial improvements in resource utilization without compromising performance.
|
||||
|
||||

|
||||
|
||||
# Architecture
|
||||
|
||||
We build the Qwen1.5-MoE models with a specially designed MoE architecture. Typically, as seen in methods like Mixtral, MoE layers within each transformer block employ eight experts and utilize a top-2 gating strategy for routing purposes. This configuration, while straightforward and efficacious, presents ample scope for enhancement. Consequently, through an extensive series of experiments, we have introduced several modifications to this architecture:
|
||||
@@ -25,9 +23,6 @@ We build the Qwen1.5-MoE models with a specially designed MoE architecture. Typi
|
||||
* Routing mechanism, with shared and routing experts
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
Previous research projects such as DeepSeek-MoE and DBRX have demonstrated the effectiveness of using fine-grained experts. Conventionally, when transitioning from a standard FFN layer to a Mixture-of-Experts (MoE) layer, one merely replicates the FFN multiple times to create multiple experts. However, in the context of fine-grained experts, the goal is to generate a larger number of experts without increasing the parameter count. To accomplish this, we partition a single FFN into several segments, each serving as an individual expert. This is a more nuanced approach to constructing experts. We have identified an optimal configuration with a total of 64 experts, representing an 8-time increase compared to the conventional MoE setup of 8 experts.
|
||||
|
||||
The initialization stage of the model is critical. Our initial experiments suggest that training a MoE model from scratch may prove inefficient and challenging to elevate it to the anticipated peak performance. Instead, we start by repurposing our existing Qwen-1.8B, transforming it into Qwen1.5-MoE-A2.7B. A noteworthy finding is that introducing randomness during initialization significantly expedites convergence and results in superior overall performance throughout the pre-training process.
|
||||
@@ -76,15 +71,18 @@ The Qwen1.5-MoE-A2.7B model exhibits an impressive improvement in speed, being a
|
||||
# Develop with Qwen1.5-MoE
|
||||
|
||||
To utilize the Qwen1.5-MoE model with the `qwen2_moe` implementation in Hugging Face’s transformers, since the latest release does not include this feature yet, you will have to install transformers from source instead of installing it via pip or conda:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
git clone https://github.com/huggingface/transformers
|
||||
cd transformers
|
||||
pip install -e .
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The following step is indeed straightforward and akin to using models such as Qwen1.5, Mistral, or Llama. We demonstrate an example of the usage of Qwen1.5-MoE-A2.7B-Chat. To use the quantized model instead, you can just substitute the model name `Qwen1.5-MoE-A2.7B-Chat` with `Qwen1.5-MoE-A2.7B-Chat-GPTQ-Int4` (temporarily AWQ is not supported).
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
@@ -115,22 +113,28 @@ The following step is indeed straightforward and akin to using models such as Qw
|
||||
|
||||
response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
To use the model with vLLM, follow our fork first and then install vLLM from source as well:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
git clone https://github.com/vllm-project/vllm.git
|
||||
cd vllm
|
||||
pip install -e .
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Here we demonstrate an example to show how to use vLLM to build an OpenAI-API compatible interface for our model:
|
||||
[code]
|
||||
```
|
||||
|
||||
python -m vllm.entrypoints.openai.api_server --model Qwen/Qwen1.5-MoE-A2.7B-Chat
|
||||
|
||||
[/code]
|
||||
[code]
|
||||
|
||||
```
|
||||
```bash
|
||||
|
||||
curl http://localhost:8000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
@@ -141,7 +145,8 @@ Here we demonstrate an example to show how to use vLLM to build an OpenAI-API co
|
||||
]
|
||||
}'
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
There remains an extensive array of tasks on our agenda, including the support of llama.cpp for GGUF files, MLX support, etc. We will continue updating the support of third-party frameworks.
|
||||
|
||||
@@ -150,7 +155,8 @@ There remains an extensive array of tasks on our agenda, including the support o
|
||||
We are thrilled to introduce our pioneering MoE model, Qwen1.5-MoE-A2.7B, which achieves parity with contemporary 7B parameter models. Furthermore, we have shown substantial reductions in both training costs and inference time when compared to conventional 7B models. Our model developments underscore the vast potential of MoE models. In light of these encouraging outcomes, we remain steadfast in our commitment to advancing this technology further.
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen_moe,
|
||||
title = {Qwen1.5-MoE: Matching 7B Model Performance with 1/3 Activated Parameters"},
|
||||
url = {https://qwenlm.github.io/blog/qwen-moe/},
|
||||
@@ -159,4 +165,5 @@ We are thrilled to introduce our pioneering MoE model, Qwen1.5-MoE-A2.7B, which
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -20,26 +20,19 @@ Key Features:
|
||||
* **High Customizability** : The new version provides advanced translation capabilities such as terminology intervention, domain prompts and translation memory. By enabling customizable prompt engineering, it delivers optimized translation performance tailored to complex, domain-specific, and mission-critical application scenarios.
|
||||
* **Low Latency & Cost Efficiency**: By leveraging a lightweight Mixture of Experts (MoE) architecture, Qwen-MT achieves high translation performance with faster response times and significantly reduced API costs (as low as $0.5 per million output tokens). This is particularly well-suited for high-concurrency environments and latency-sensitive applications.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Translation Quality
|
||||
|
||||
### Automatic Evaluation
|
||||
|
||||
We evaluate Qwen-MT on multi-domain translation benchmark, specifically Chinese-English and English-German translation, as well as WMT24 multilingual translation benchmark. Experimental results demonstrate that Qwen-MT significantly outperforms comparably-sized models including GPT-4.1-mini, Gemini-2.5-Flash, and Qwen3-8B. Notably, even when compared to state-of-the-art large language models such as GPT-4.1, Gemini-2.5-Pro, and Qwen3-235B-A22B, Qwen-MT maintains competitive translation quality while its optimized lightweight architecture enables rapid translation processing.
|
||||
|
||||
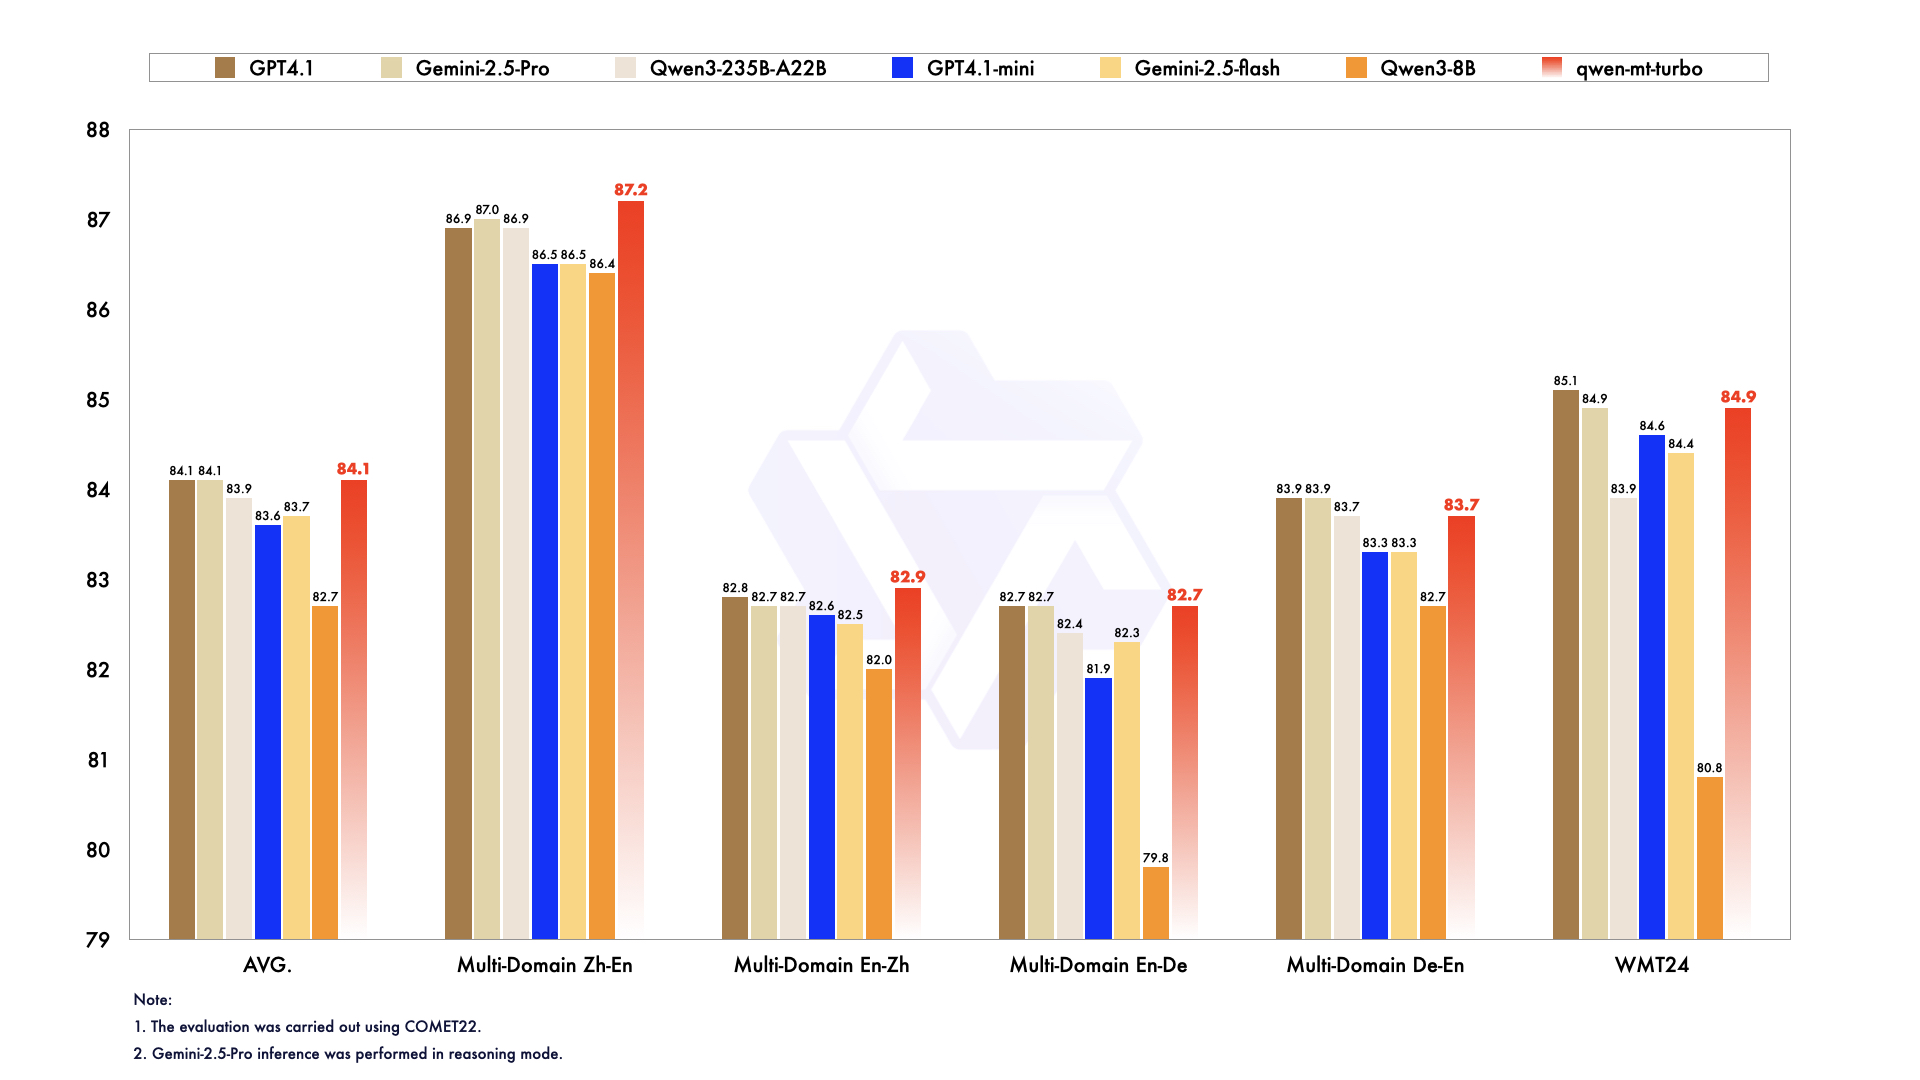
|
||||
|
||||
### Human Evaluation
|
||||
|
||||
Automatic evaluation methods have inherent limitations, we further implemented human evaluation protocols leveraging real-world translation data across ten major languages: Chinese, English, Japanese, Korean, Thai, Arabic, Italian, Russian, Spanish, and French. Our rigorous evaluation framework involved three independent professional translators scoring each test sample, followed by systematic cross-validation procedures to ensure both objectivity and reliability of the assessment outcomes. Notably, Qwen-MT achieved superior performance metrics, demonstrating significant advantages in both acceptance rates and excellence rates, validating its exceptional translation capabilities in practical deployment scenarios.
|
||||
|
||||
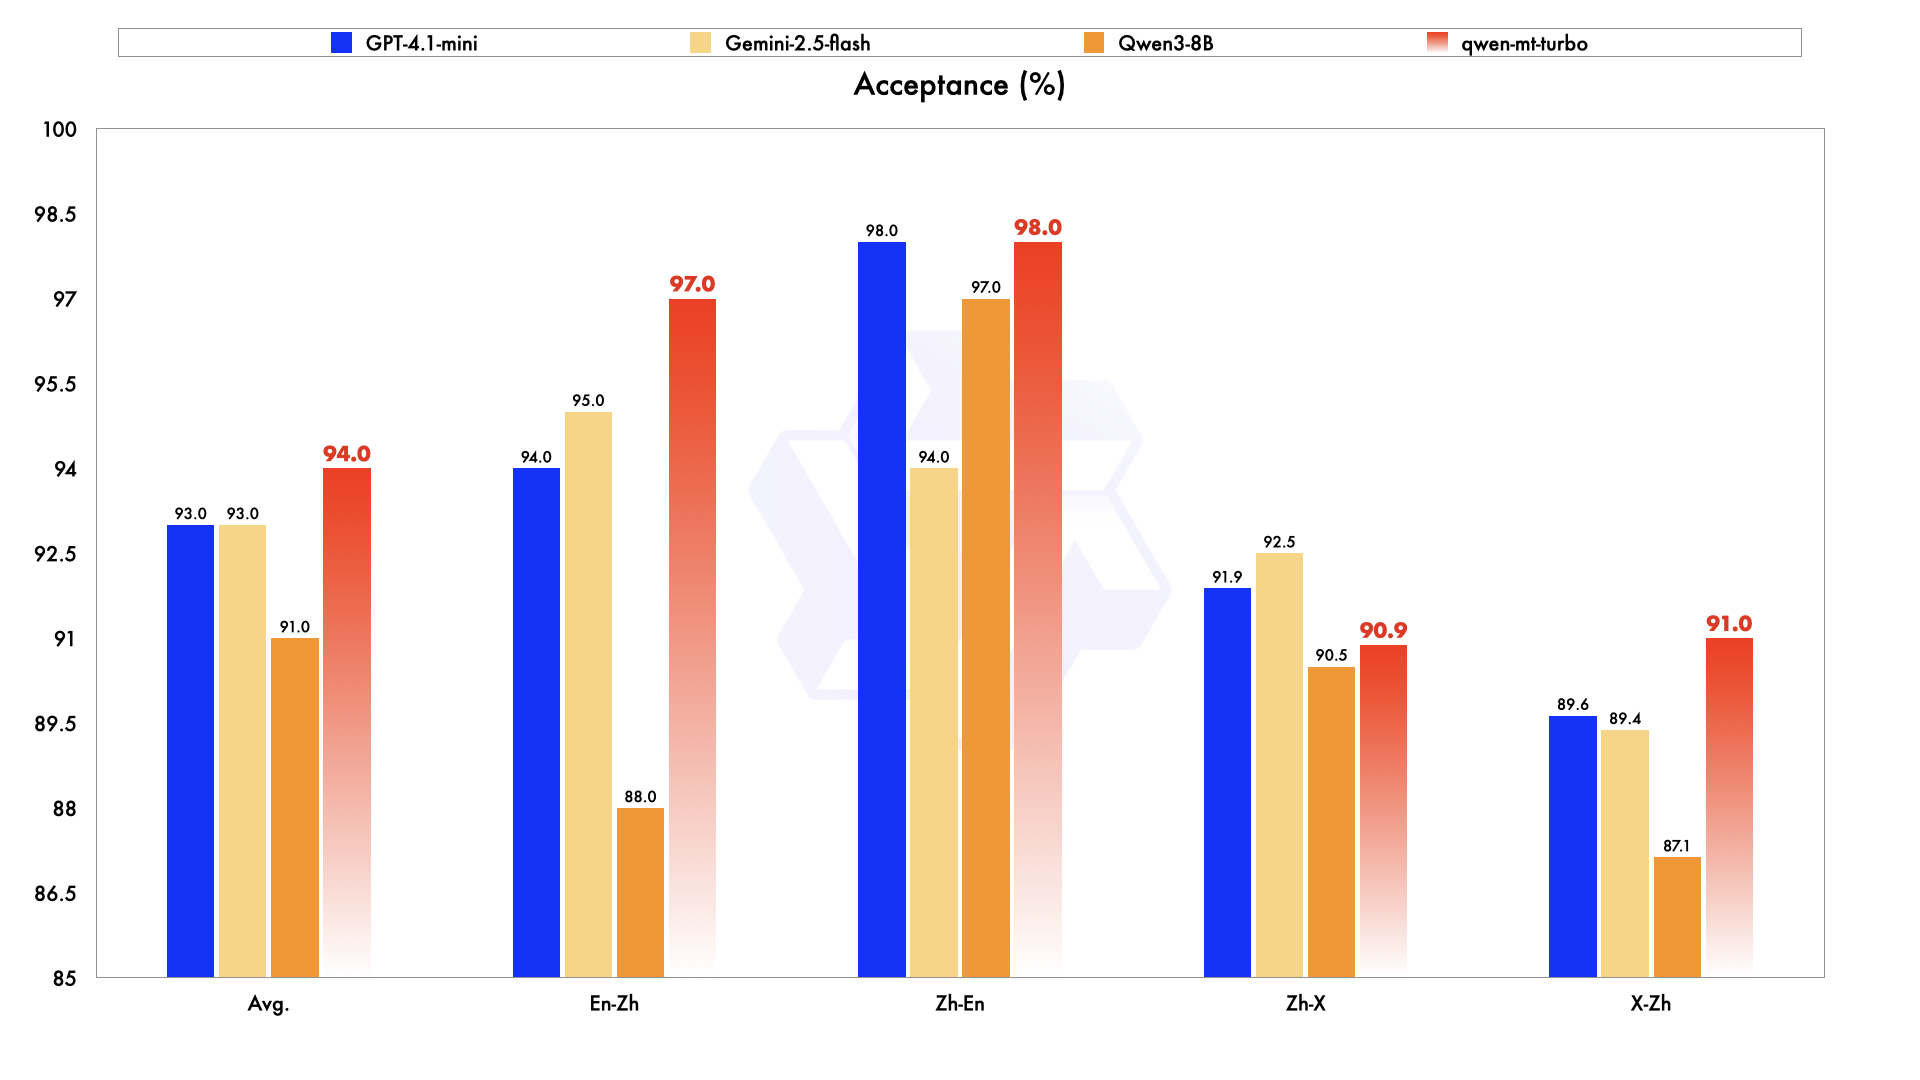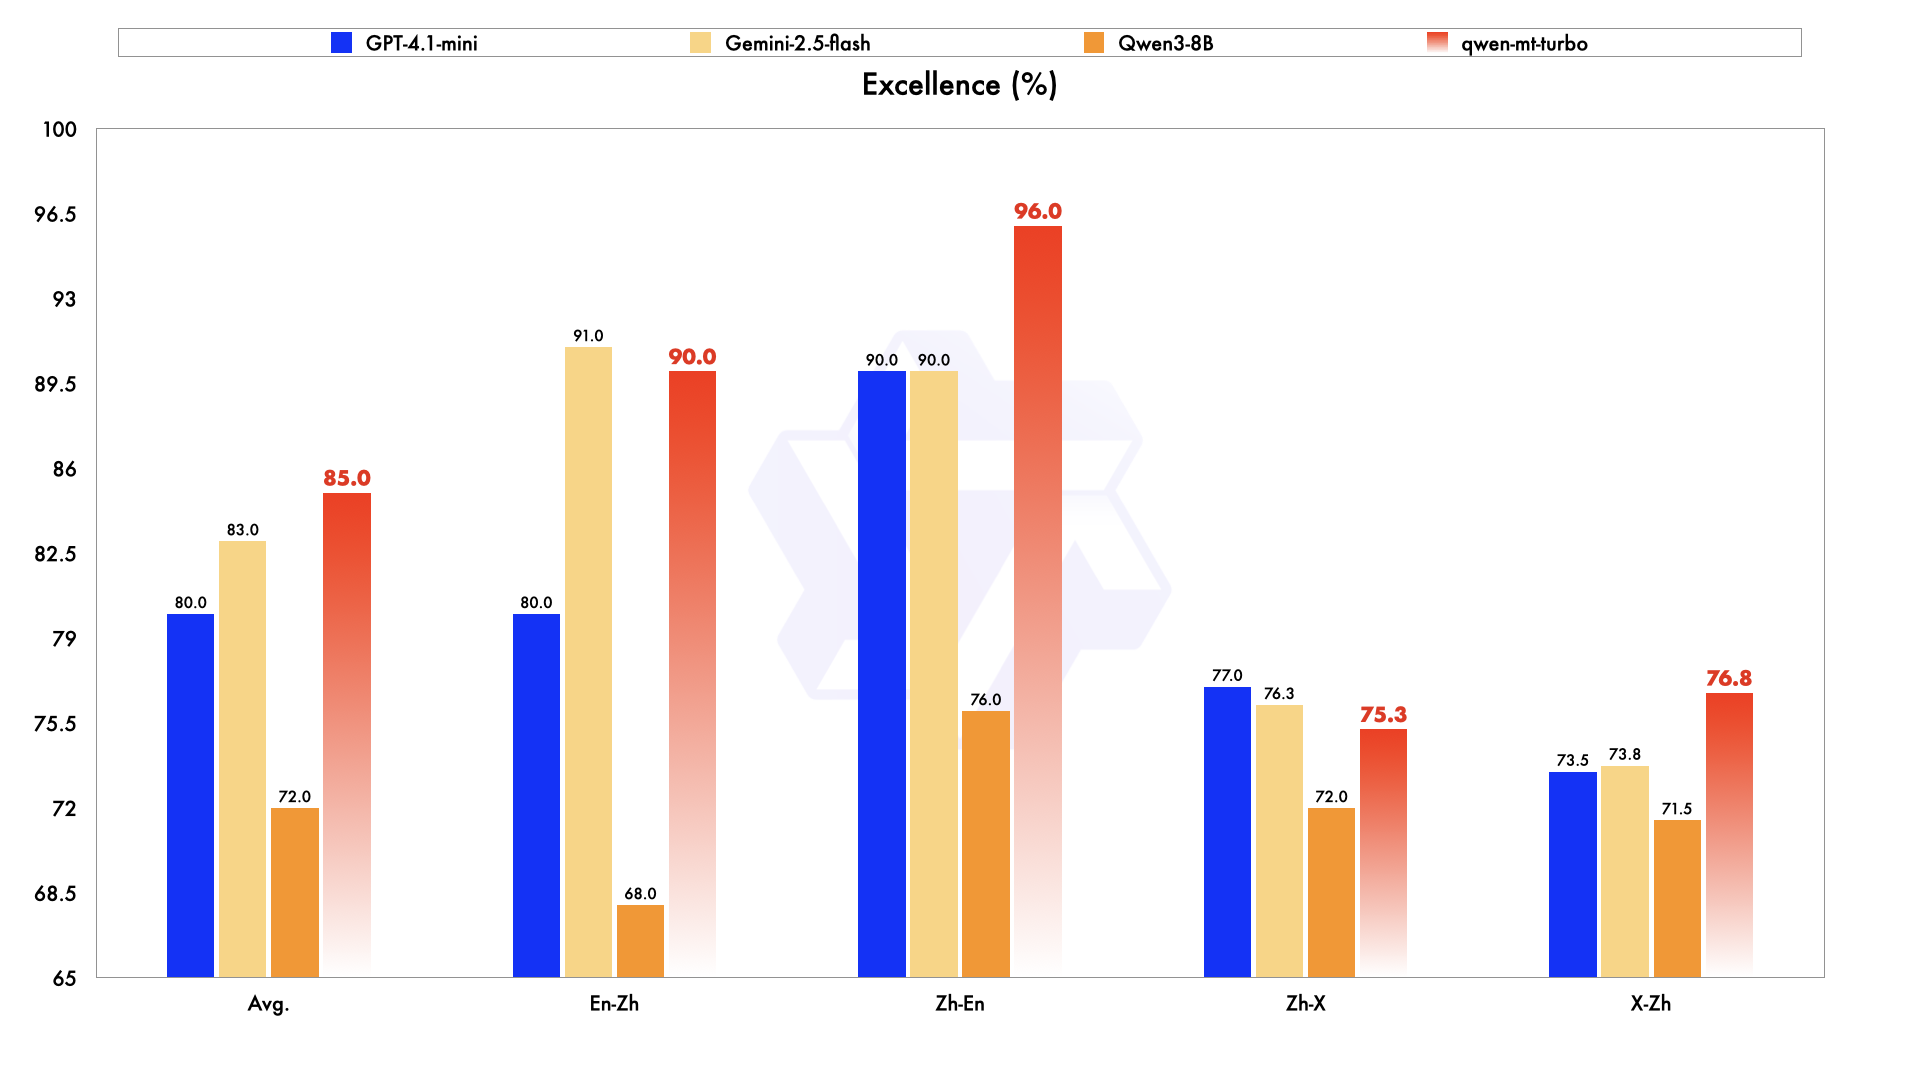
|
||||
|
||||
Here are some translation examples:
|
||||
|
||||
Source Text| Qwen-MT
|
||||
@@ -55,7 +48,6 @@ Little study **hack** for **y’all** … do your homework/assignments the first
|
||||
|
||||
|
||||
|
||||
|
||||
## Language Support
|
||||
|
||||
Language Family| Language Name
|
||||
@@ -74,11 +66,11 @@ Other| Basque, Georgian, Japanese, Korean, Swahili
|
||||
|
||||
|
||||
|
||||
|
||||
## How to use
|
||||
|
||||
You can easily use Qwen-MT through Qwen API. Here we take a simple scenario of translating from Chinese to English as an example.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import os
|
||||
from openai import OpenAI
|
||||
|
||||
@@ -109,10 +101,12 @@ You can easily use Qwen-MT through Qwen API. Here we take a simple scenario of t
|
||||
|
||||
print(completion.choices[0].message.content)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Qwen-MT supports features such as terminology intervention, domain prompts, and translation memory. For instance, in a translation scenario involves specialized terms, users can predefine key terminology pairs and inject them as parameters into the model, ensuring consistent application of user-specified lexicon throughout the output.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import os
|
||||
from openai import OpenAI
|
||||
|
||||
@@ -164,10 +158,12 @@ Qwen-MT supports features such as terminology intervention, domain prompts, and
|
||||
# Response:
|
||||
# This biological sensor uses graphene, a new material, and its target is chemical elements. Its sensitive "nose" can more deeply and accurately reflect the health status of the body.
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Moreover, translation style must adapt to contextual nuances. For example, in legal and official contexts, formal register is imperative, whereas social media communication demands a conversational tone. To ensure appropriate stylistic adaptation, users can provide contextual details and stylistic preferences in natural language alongside their source text.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import os
|
||||
from openai import OpenAI
|
||||
|
||||
@@ -202,14 +198,14 @@ Moreover, translation style must adapt to contextual nuances. For example, in le
|
||||
# Response:
|
||||
# The second SELECT statement returns a number that indicates how many rows were returned by the first SELECT statement without LIMIT clause.
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
For more advanced features, please refer to [Qwen API](%5Bhttps://www.alibabacloud.com/help/en/model-studio/translation-abilities%5D\(https://modelstudio.console.alibabacloud.com/?tab=doc#/doc/?type=model&url=https%3A%2F%2Fwww.alibabacloud.com%2Fhelp%2Fzh%2Fdoc-detail%2F2860790.html&renderType=iframe\)).
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Conclusion
|
||||
|
||||
Qwen-MT is an advanced machine translation model that supports translations among 92 languages. It aims to provide global users with smart, flexible, and efficient translation experience through APIs. While “faithfulness, fluency, and elegance” remains an ongoing journey filled with challenges, we are persistently exploring and improving. Looking ahead, we will continue to enhance translation accuracy and naturalness, expand coverage to more languages, ultimately dismantling language barriers to realize truly borderless communication.
|
||||
@@ -56,7 +56,8 @@ You can call me directly at 4257037344 or my cell 4254447474 or send me a meetin
|
||||
## How to use
|
||||
|
||||
Using Qwen-TTS with Qwen API is simple. We demonstrate a code snippet for you to play with it below:
|
||||
[code]
|
||||
```python
|
||||
|
||||
import os
|
||||
import requests
|
||||
import dashscope
|
||||
@@ -123,7 +124,8 @@ Using Qwen-TTS with Qwen API is simple. We demonstrate a code snippet for you to
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Summary
|
||||
|
||||
|
||||
@@ -57,7 +57,7 @@ Example: celebrity recognition Next
|
||||
|
||||
User
|
||||
|
||||
who are they? 
|
||||
who are they?
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -72,8 +72,6 @@ These are some of the most famous and highest-paid celebrities in the world. Fro
|
||||
* Robert Downey Jr. (American actor)
|
||||
* Scarlett Johansson (American actress)
|
||||
|
||||
|
||||
|
||||
It’s worth noting that this is just a small sample of the many talented and successful celebrities out there, and that fame and wealth are not the only measures of success or importance.
|
||||
|
||||
User
|
||||
@@ -93,15 +91,13 @@ Here are the Chinese names of the celebrities mentioned:
|
||||
* Robert Downey Jr.: 小罗伯特·唐尼
|
||||
* Scarlett Johansson: 斯嘉丽·约翰逊
|
||||
|
||||
|
||||
|
||||
Note that these are just one possible translation of their names into Chinese, and there may be other variations used in different contexts or regions.
|
||||
|
||||
Example: landmark recognition Next
|
||||
|
||||
User
|
||||
|
||||
Where is it in the picture? How did you recognize it? 
|
||||
Where is it in the picture? How did you recognize it?
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -111,7 +107,7 @@ Example: poem writing Next
|
||||
|
||||
User
|
||||
|
||||
Look at pictures and write a poem. 
|
||||
Look at pictures and write a poem.
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -127,7 +123,7 @@ Example: mobile app screenshot understanding Next
|
||||
|
||||
User
|
||||
|
||||
Describe the image.
|
||||
Describe the image.
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -141,17 +137,17 @@ Example: Locate Whatever You Desire Next
|
||||
|
||||
User
|
||||
|
||||
Locate the red car 
|
||||
Locate the red car
|
||||
|
||||
Qwen-VL
|
||||
|
||||
The red car is located in the bottom right corner of the image. 
|
||||
The red car is located in the bottom right corner of the image.
|
||||
|
||||
Example: Contextually Anchored Image Description Generation Next
|
||||
|
||||
User
|
||||
|
||||
What does the pointed news talk about? 
|
||||
What does the pointed news talk about?
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -161,7 +157,7 @@ Example: Autonomous Driving Next
|
||||
|
||||
User
|
||||
|
||||
The current vehicle speed is 150km/h. According to the picture, how should the vehicle operate? A. To accelerate B. Slow down C. Maintain the original speed D. Parking Choose an answer and give reasons. 
|
||||
The current vehicle speed is 150km/h. According to the picture, how should the vehicle operate? A. To accelerate B. Slow down C. Maintain the original speed D. Parking Choose an answer and give reasons.
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -177,7 +173,7 @@ Example: Math Next
|
||||
|
||||
User
|
||||
|
||||
read the image and solve it step by step 
|
||||
read the image and solve it step by step
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -185,13 +181,10 @@ The image shows two geometric figures, a rectangular prism and a cube, with thei
|
||||
|
||||
1. For the rectangular prism:
|
||||
|
||||
|
||||
* Length (l) = 4 cm
|
||||
* Width (w) = 2 cm
|
||||
* Height (h) = 3 cm
|
||||
|
||||
|
||||
|
||||
Surface Area (SA) of a rectangular prism = 2lw + 2lh + 2wh Volume (V) of a rectangular prism = lwh
|
||||
|
||||
Substituting the given values: SA = 2(4cm)(2cm) + 2(4cm)(3cm) + 2(2cm)(3cm) SA = 16cm² + 24cm² + 12cm² SA = 52cm²
|
||||
@@ -200,11 +193,8 @@ V = (4cm)(2cm)(3cm) V = 24cm³
|
||||
|
||||
2. For the cube:
|
||||
|
||||
|
||||
* Side length (a) = 3 dm
|
||||
|
||||
|
||||
|
||||
Surface Area (SA) of a cube = 6a² Volume (V) of a cube = a³
|
||||
|
||||
Substituting the given value: SA = 6(3dm)² SA = 6(9dm²) SA = 54dm²
|
||||
@@ -218,25 +208,22 @@ For the rectangular prism:
|
||||
* Surface Area = 52 cm²
|
||||
* Volume = 24 cm³
|
||||
|
||||
|
||||
|
||||
For the cube:
|
||||
|
||||
* Surface Area = 54 dm²
|
||||
* Volume = 27 dm³
|
||||
|
||||
|
||||
|
||||
Example: Code Next
|
||||
|
||||
User
|
||||
|
||||
convert the process into a python code program 
|
||||
convert the process into a python code program
|
||||
|
||||
Qwen-VL
|
||||
|
||||
The image shows a Scratch programming block, which can be converted into Python code as follows:
|
||||
[code]
|
||||
```python
|
||||
|
||||
import random
|
||||
|
||||
# Set up the variables
|
||||
@@ -253,7 +240,8 @@ The image shows a Scratch programming block, which can be converted into Python
|
||||
else:
|
||||
print("Incorrect!")
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
This Python code generates two random numbers between 1 and 50, adds them together to get the answer, and then asks the user for their response. It then checks if the response matches the answer, and prints out a message accordingly.
|
||||
|
||||
@@ -261,7 +249,7 @@ Example: Table Next
|
||||
|
||||
User
|
||||
|
||||
Spot a data point that stands out in these charts and what that implicates. Then produce a detailed markdown table for all the data shown. 
|
||||
Spot a data point that stands out in these charts and what that implicates. Then produce a detailed markdown table for all the data shown.
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -282,7 +270,7 @@ Example: Reasoning Next
|
||||
|
||||
User
|
||||
|
||||
Look at this sequence of three shapes. What shape should come as the fourth shape? Explain your reasoning with detailed descriptions of the first shapes. 
|
||||
Look at this sequence of three shapes. What shape should come as the fourth shape? Explain your reasoning with detailed descriptions of the first shapes.
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -300,7 +288,7 @@ Example: Model Flow Next
|
||||
|
||||
User
|
||||
|
||||
explain the picture 
|
||||
explain the picture
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -322,17 +310,17 @@ Example: Information Retrieval Next
|
||||
|
||||
User
|
||||
|
||||
Please read the text in this image and return the information in the following JSON format (note xxx is placeholder, if the information is not available in the image, put “N/A” instead). {“class”: xxx, “DLN”: xxx, “DOB”: xxx, “Name”: xxx, “Address”: xxx, “EXP”: xxx, “ISS”: xxX, “SEX”: xxx, “HGT”: xxx, “WGT”: xxx, “EYES”: xxx, “HAIR”: xxX, “DONOR”: xxx} 
|
||||
Please read the text in this image and return the information in the following JSON format (note xxx is placeholder, if the information is not available in the image, put “N/A” instead). {“class”: xxx, “DLN”: xxx, “DOB”: xxx, “Name”: xxx, “Address”: xxx, “EXP”: xxx, “ISS”: xxX, “SEX”: xxx, “HGT”: xxx, “WGT”: xxx, “EYES”: xxx, “HAIR”: xxX, “DONOR”: xxx}
|
||||
|
||||
Qwen-VL
|
||||
|
||||
{“class”: “C”, “DLN”: “I1234568”, “DOB”: “08/31/1977”, “Name”: “IMA CARDHOLDER”, “Address”: “2570 24TH STREET ANYTOWN, CA 95818”, “EXP”: “08/31/2014”, “ISS”: “08/31/2009”, “SEX”: “F”, “HGT”: “5’-05"”, “WGT”: “125 lb”, “EYES”: “BRN”, “HAIR”: “BRN”, “DONOR”: “YES”}
|
||||
{“class”: “C”, “DLN”: “I1234568”, “DOB”: “08/31/1977”, “Name”: “IMA CARDHOLDER”, “Address”: “2570 24TH STREET ANYTOWN, CA 95818”, “EXP”: “08/31/2014”, “ISS”: “08/31/2009”, “SEX”: “F”, “HGT”: “5’-05"”, “WGT”: “125 lb”, “EYES”: “BRN”, “HAIR”: “BRN”, “DONOR”: “YES”}
|
||||
|
||||
Example: Text Information Recognition & Processing Next
|
||||
|
||||
User
|
||||
|
||||
规范格式输出图中所有文字
|
||||
规范格式输出图中所有文字
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -359,7 +347,7 @@ Example: Text Information Recognition & Processing Next
|
||||
|
||||
User
|
||||
|
||||
A brief summary of the blog
|
||||
A brief summary of the blog
|
||||
|
||||
Qwen-VL
|
||||
|
||||
@@ -372,24 +360,17 @@ The blog post announces several new updates and improvements to OpenAI’s platf
|
||||
* Reproducible outputs and log probabilities.
|
||||
* Updated GPT-3.5 Turbo with a 16K context window by default.
|
||||
|
||||
|
||||
|
||||
The post also mentions that these updates will be rolled out to all paying customers starting at 10am PT today.
|
||||
|
||||
## How to Use
|
||||
|
||||
Now you can access Qwen-VL-Plus and Qwen-VL-Max through the Huggingface Spaces, the Qwen website, and Dashscope APIs.
|
||||
|
||||
* Try Qwen-VL-Plus (<https://huggingface.co/spaces/Qwen/Qwen-VL-Plus>) and Qwen-VL-Max (<https://huggingface.co/spaces/Qwen/Qwen-VL-Max>) in the Huggingface Spaces
|
||||
|
||||
|
||||
|
||||
* Log in to the QianWen web portal at <https://tongyi.aliyun.com/qianwen>, and switch to “Image Understanding” mode to harness the latest Qwen-VL-Max capabilities.
|
||||
|
||||
* Access the powerful APIs of Qwen-VL-Plus and Qwen-VL-Max through the Dashscope platform (<https://help.aliyun.com/zh/dashscope/developer-reference/vl-plus-quick-start>).
|
||||
|
||||
* Try Qwen-VL-Plus ([https://huggingface.co/spaces/Qwen/Qwen-VL-Plus](https://huggingface.co/spaces/Qwen/Qwen-VL-Plus)) and Qwen-VL-Max ([https://huggingface.co/spaces/Qwen/Qwen-VL-Max](https://huggingface.co/spaces/Qwen/Qwen-VL-Max)) in the Huggingface Spaces
|
||||
|
||||
* Log in to the QianWen web portal at [https://tongyi.aliyun.com/qianwen](https://tongyi.aliyun.com/qianwen), and switch to “Image Understanding” mode to harness the latest Qwen-VL-Max capabilities.
|
||||
|
||||
* Access the powerful APIs of Qwen-VL-Plus and Qwen-VL-Max through the Dashscope platform ([https://help.aliyun.com/zh/dashscope/developer-reference/vl-plus-quick-start](https://help.aliyun.com/zh/dashscope/developer-reference/vl-plus-quick-start)).
|
||||
|
||||
## Summary
|
||||
|
||||
@@ -399,9 +380,9 @@ Our objective is to continually tap into and elevate the potential of Qwen-VL, e
|
||||
|
||||
While there is still a long way to go, we are confident that Qwen-VL will evolve to perceive and understand the world akin to human cognition through continuous optimization and expansion!
|
||||
|
||||
* Our Official Website: <https://tongyi.aliyun.com/qianwen>
|
||||
* Github: <https://github.com/QwenLM/Qwen-VL>
|
||||
* Huggingface: <http://huggingface.co/Qwen/Qwen-VL-Chat>
|
||||
* ModelScope: <https://modelscope.cn/studios/qwen/Qwen-VL-Chat-Demo>
|
||||
* API: <https://help.aliyun.com/zh/dashscope/developer-reference/tongyi-qianwen-vl-plus-api>
|
||||
* Discord: <https://discord.gg/CV4E9rpNSD>
|
||||
* Our Official Website: [https://tongyi.aliyun.com/qianwen](https://tongyi.aliyun.com/qianwen)
|
||||
* Github: [https://github.com/QwenLM/Qwen-VL](https://github.com/QwenLM/Qwen-VL)
|
||||
* Huggingface: [http://huggingface.co/Qwen/Qwen-VL-Chat](http://huggingface.co/Qwen/Qwen-VL-Chat)
|
||||
* ModelScope: [https://modelscope.cn/studios/qwen/Qwen-VL-Chat-Demo](https://modelscope.cn/studios/qwen/Qwen-VL-Chat-Demo)
|
||||
* API: [https://help.aliyun.com/zh/dashscope/developer-reference/tongyi-qianwen-vl-plus-api](https://help.aliyun.com/zh/dashscope/developer-reference/tongyi-qianwen-vl-plus-api)
|
||||
* Discord: [https://discord.gg/CV4E9rpNSD](https://discord.gg/CV4E9rpNSD)
|
||||
@@ -6,8 +6,6 @@ date: "2025-06-26"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[QWEN CHAT](https://chat.qwenlm.ai) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## **Introduction**
|
||||
@@ -36,9 +34,6 @@ Users can provide creative instructions in natural language, such as “change t
|
||||
|
||||
Qwen VLo supports multiple languages, including Chinese and English, breaking down language barriers and providing a unified, convenient interaction experience for global users. Regardless of the language you use, simply describe your needs, and the model will quickly understand and deliver the desired output.
|
||||
|
||||
|
||||
|
||||
|
||||
* * *
|
||||
|
||||
## **Demo Cases**
|
||||
@@ -57,8 +52,6 @@ Translation: Generate a cute Shiba Inu
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
背景改成草原
|
||||
@@ -67,8 +60,6 @@ Translation: Change the background to a grassland
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
给它带上红色帽子和黑色透明墨镜,帽子上写着“QwenVLo”
|
||||
@@ -77,8 +68,6 @@ Translation: Put a red hat and black transparent sunglasses on it, with ‘QwenV
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成吉卜力风格
|
||||
@@ -87,8 +76,6 @@ Translation: Switch to Ghibli style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成3d Q版风格
|
||||
@@ -97,8 +84,6 @@ Translation: Switch to 3D Q-version style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
把它放到水晶球里
|
||||
@@ -107,8 +92,6 @@ Translation: Place it inside a crystal ball
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
桌面上摆着这个水晶球,生成以一个人的第一视角在公园的圆形咖啡桌上在笔记本上画画
|
||||
@@ -117,8 +100,6 @@ Translation: Place this crystal ball on a desk and generate an image from a firs
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
用蓝色的蒙版检测框框出图中的笔
|
||||
@@ -127,8 +108,6 @@ Translation: Use a blue mask to detect and frame the pen in the picture
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
用粉色的mask分割出图中的狗狗边缘
|
||||
@@ -137,21 +116,17 @@ Translation: Use a pink mask to segment the edge of the dog in the picture
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Qwen VLo can reinterpret and recreate based on its understanding, allowing for greater flexibility in style changes and migrations, such as transforming cartoons into realistic images or turning figures into balloons, among other creative outputs.
|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
变成真实照片
|
||||
变成真实照片
|
||||
Translation: Turn into a real photo
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
背景换成艾弗尔铁塔
|
||||
@@ -159,8 +134,6 @@ Translation: Change the background to the Eiffel Tower
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成气球飘到空中
|
||||
@@ -168,8 +141,6 @@ Translation: Turn into a balloon floating in the air
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
把西瓜换成榴莲
|
||||
@@ -177,46 +148,36 @@ Translation: Replace the watermelon with durian
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
Convert the couple in the photo into a minimalist flat illustration style Q-version sticker, retaining the facial features, with thick white borders, figures extending beyond the circular area, the circular area filled with a solid color, transparent background, and an overall cute style.
|
||||
Convert the couple in the photo into a minimalist flat illustration style Q-version sticker, retaining the facial features, with thick white borders, figures extending beyond the circular area, the circular area filled with a solid color, transparent background, and an overall cute style.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
Convert the couple in the photo into a detailed, exquisite, and adorable 3D rendered collectible figurine, placed inside a cozy and romantic display box decorated with light cream and soft golden accents, while preserving the characteristics of the snowy scene and the figures’ poses.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
Add the text “Happy Wedding”
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
变成吉卜力风格
|
||||
变成吉卜力风格
|
||||
|
||||
Translation: Turn into Ghibli style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成海贼王画风
|
||||
@@ -225,8 +186,6 @@ Translation: Turn into One Piece art style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成龙珠画风
|
||||
@@ -235,8 +194,6 @@ Translation: Turn into Dragon Ball art style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成海绵宝宝风格
|
||||
@@ -245,8 +202,6 @@ Translation: Turn into SpongeBob style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成我的世界里的角色
|
||||
@@ -255,8 +210,6 @@ Translation: Turn into a character from Minecraft
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
变成像素画风格
|
||||
@@ -265,56 +218,46 @@ Translation: Turn into pixel art style
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
将照片中的猫转换为皮克斯 3D 风格,保持蓝眼睛和白橙色毛发特征,背景为红色树叶的秋日氛围。
|
||||
将照片中的猫转换为皮克斯 3D 风格,保持蓝眼睛和白橙色毛发特征,背景为红色树叶的秋日氛围。
|
||||
|
||||
Translation: Transform the cat in the photo into Pixar 3D style, maintaining the features of blue eyes and white-orange fur, with the autumn atmosphere of red leaves in the background.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
将迈阿密夜景的繁华城市天际线转换为果冻质感(布丁造型)的特殊材质建模风格,主题为现代都市,添加透明果冻层叠加的效果和微妙的弹性物理模拟。
|
||||
将迈阿密夜景的繁华城市天际线转换为果冻质感(布丁造型)的特殊材质建模风格,主题为现代都市,添加透明果冻层叠加的效果和微妙的弹性物理模拟。
|
||||
|
||||
Translation: Transform the bustling city skyline of Miami’s night view into a special material modeling style with a jelly-like texture (pudding shape), with the theme of modern city. Add the effect of transparent jelly layer superimposition and subtle elastic physical simulation.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
将照片中的女性主体转换为细致精美的3D渲染收藏摆件,装置在浅奶油色与柔和金色装饰的温馨展示盒中,保持优雅姿态与服饰细节,采用萌趣可爱的风格表现。
|
||||
将照片中的女性主体转换为细致精美的3D渲染收藏摆件,装置在浅奶油色与柔和金色装饰的温馨展示盒中,保持优雅姿态与服饰细节,采用萌趣可爱的风格表现。
|
||||
|
||||
Translation: Convert the female subject in the photo to a detailed and exquisite 3D rendered collectible figure, displayed in a warm and cozy display box with a shallow cream color and soft golden decoration, maintaining an elegant pose and clothing details, presented in a cute and adorable style.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
将铁王座转换为Jellycat毛绒玩具风格,保持剑刃纹理细节,采用柔和的毛绒材质渲染。
|
||||
将铁王座转换为Jellycat毛绒玩具风格,保持剑刃纹理细节,采用柔和的毛绒材质渲染。
|
||||
|
||||
Translation: Transform the Iron Throne into the Jellycat plush toy style, retain the texture details of the sword blade, and use soft plush material for rendering.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
@@ -325,8 +268,6 @@ Translation: Generate a cute koi with the Leifeng Pagoda in West Lake as the bac
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
把图片转化为乐高人偶风格,模块化积木造型,保持鱼的廓形,采用简洁的背景突出主体,添加柔光渲染效果
|
||||
@@ -335,20 +276,16 @@ Translation: Transform the picture into a Lego figure style, with modular buildi
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Style Conversion Next
|
||||
|
||||
User
|
||||
|
||||
将照片中的红色跑车转换为细致精美的3D渲染收藏摆件,装置在浅奶油色与柔和金色装饰的粉彩展示盒中,保持跑车的红色条纹特征,采用萌趣可爱风格。
|
||||
将照片中的红色跑车转换为细致精美的3D渲染收藏摆件,装置在浅奶油色与柔和金色装饰的粉彩展示盒中,保持跑车的红色条纹特征,采用萌趣可爱风格。
|
||||
|
||||
Translation: Transform the red sports car in the photo into a detailed and exquisite 3D rendered collectible ornament, installed in a pastel display box decorated with light cream and soft gold, maintaining the red stripe feature of the sports car and adopting a cute and playful style.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
把图中的跑车变成毛绒玩具
|
||||
@@ -357,8 +294,6 @@ Translation: Turn the car in the picture into a plush toy.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
再把跑车变成奶油布丁风格的
|
||||
@@ -367,40 +302,32 @@ Translation: Turn the car into a cream pudding style.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
The model’s advanced capabilities in image and instruction comprehension enable it to better interpret complex commands, incorporating multiple operations and modifications in a single instruction. This allows for the completion of multi-step tasks in one go, such as creating posters or combining objects.
|
||||
|
||||
Complex Image Prompt Next
|
||||
|
||||
User
|
||||
|
||||
Generate a photo in which a man wearing a black hat is reading a newspaper on the subway, next to him is a beautiful young woman wearing red sunglasses, and there’s also a Husky dog. The subway window shows the Statue of Liberty, and the subway station sign displays ‘Qwen VLo’.
|
||||
Generate a photo in which a man wearing a black hat is reading a newspaper on the subway, next to him is a beautiful young woman wearing red sunglasses, and there’s also a Husky dog. The subway window shows the Statue of Liberty, and the subway station sign displays ‘Qwen VLo’.
|
||||
|
||||
(翻译:生成照片,图中男人带着黑帽子在地铁上看报纸,旁边是一个美丽的带红色墨镜年轻女性,还有一只哈士奇,地铁的窗外是自由女神像,地铁的站牌显示“Qwen VLo”)
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Complex Image Prompt Next
|
||||
|
||||
User
|
||||
|
||||
now generate a POV of a person drawing this diagram in their notebook, at a round cafe table in park
|
||||
now generate a POV of a person drawing this diagram in their notebook, at a round cafe table in park
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
now show the same scene with a smug young Isaac Newton sitting at the table, with a prism, demonstrating the experiment, without the notebook in view
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Poster Your Cat Next
|
||||
|
||||
User
|
||||
@@ -411,8 +338,6 @@ Translation: Generate a black kitten
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
生成一个以这只小黑猫为主体的广角巨幅摄影,主角小黑猫骄傲地站在中间,戴着一顶鲜红色的帽子,为它可爱的外表增添了一丝奇思妙想。在它的左边,动物们成群结队,老虎、狮子、猴子、鹿和天上的飞鸟,它们的眼睛闪烁着凶猛的光芒,散发出一种不可战胜的气势。在右边是一只外星人,还有一个发出耀眼的深蓝色光的飞碟。飞碟发出眩目的光束,与动物大军形成鲜明对比。广角镜头捕捉到了壮观的场景,突出了小猫的勇敢和双方之间的紧张关系。
|
||||
@@ -421,33 +346,27 @@ Translation: Generate a wide-angle large-scale photograph with this little black
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Poster Generation Next
|
||||
|
||||
User
|
||||
|
||||
生成一个关于这个咖啡的宣传海报,咖啡罐是主体,放在木质桌面上,有一种自然复古感。咖啡罐打开,上方悬着一个正在向下倒水的手冲壶,咖啡向外泼溅,散发出袅袅热气。主色调用深棕/咖色(象征咖啡)搭配奶白/浅金(象征奶泡),标题是奶泡风格的手写体“一杯咖啡,唤醒你的清晨”
|
||||
生成一个关于这个咖啡的宣传海报,咖啡罐是主体,放在木质桌面上,有一种自然复古感。咖啡罐打开,上方悬着一个正在向下倒水的手冲壶,咖啡向外泼溅,散发出袅袅热气。主色调用深棕/咖色(象征咖啡)搭配奶白/浅金(象征奶泡),标题是奶泡风格的手写体“一杯咖啡,唤醒你的清晨”
|
||||
|
||||
Translation: Create a promotional poster for this coffee. The main subject is a coffee jar placed on a wooden tabletop, giving a natural and vintage feel. The jar is open, with a hand-pouring kettle suspended above it, pouring water downward. Coffee beans are splashing out and steam is rising. The color scheme features deep brown/sepia (symbolizing coffee) paired with creamy white/light gold (representing milk foam). The title is in milk foam-style handwriting: ‘A Cup of Coffee to Wake Up Your Morning.’
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
Set the object in the image as the main visual focus, placing it centrally in the frame. The background should have a dark blue tone. The desk lamp is turned on, with light gradually diffusing outward, creating a warm orange-yellow halo effect. In front of the lamp base, place a dark wood desk surface with a few pages of an open magazine and a pair of sunglasses scattered on it. The overall style leans towards a vintage modern aesthetic, with strong contrasts in light and shadow. The color scheme creates tension between dark blue and orange. The title should be placed in the upper right corner of the image, with the text: “Illuminating not just the desk, but an attitude.”
|
||||
|
||||
翻译:将图像中的主体设为视觉焦点,置于画面中央。背景采用深蓝色调。台灯处于开启状态,光线逐渐向外扩散,营造出温暖的橙黄色光晕效果。在灯座前方,放置深色木制桌面,桌面上散落着几页打开的杂志和一副太阳镜。整体风格偏向复古现代风,光影对比强烈。色彩搭配上,深蓝色与橙色形成张力。标题位于图像右上角,文字为:“Illuminating not just the desk, but an attitude.”(照明不仅是书桌,更是一种态度。)
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
一、核心视觉元素
|
||||
一、核心视觉元素
|
||||
|
||||
主体强化 保留高清苹果主体(占比40%-50%画面) 增加苹果切面展示:横向剖面(5片星形果核)+纵向剖面(果肉纤维特写) 水晶质感:在苹果表面添加1-2滴写实水珠(直径约苹果1/8高度) 自然生态元素 动态飘落的苹果花花瓣(3-5片,浅粉色渐变) 蜜蜂停留特写(透明翅膀动态效果) 老树根局部肌理(右下角虚化处理) 二、信息架构系统
|
||||
|
||||
@@ -455,8 +374,6 @@ User
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
In addition to image editing and re-creation, Qwen VLo can also perform annotations on existing information, such as detection, segmentation, edge detection, and more.
|
||||
|
||||
Perception and Localization Next
|
||||
@@ -468,8 +385,6 @@ Translation: Generate a table full of fruits
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
预测边缘检测图
|
||||
@@ -477,17 +392,13 @@ Translation: Predict an edge detection map
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
用红色mask分割图中香蕉的边缘
|
||||
用红色mask分割图中香蕉的边缘
|
||||
Translation: Use a red mask to segment the edges of the banana in the image.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Select Remove Add Next
|
||||
|
||||
User
|
||||
@@ -498,8 +409,6 @@ Translation: Generate a messy desk, which is piled up with all kinds of items. O
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
用红色的框标示出图中的手机
|
||||
@@ -508,8 +417,6 @@ Translation: Mark the mobile phone in the picture with a red box
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
擦除这个手机
|
||||
@@ -518,8 +425,6 @@ Translation: Erase this mobile phone
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
在桌面上添加一杯咖啡
|
||||
@@ -528,8 +433,6 @@ Translation: Add a cup of coffee on the desk
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
将这张图变成边缘检测图
|
||||
@@ -538,22 +441,18 @@ Translation: Convert this picture into an edge detection picture
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Qwen VLo supports the understanding and generation of multiple input images. (The function of multiple image inputs has not yet been officially launched, so stay tuned.)
|
||||
|
||||
Multiple image input Next
|
||||
|
||||
User
|
||||
|
||||
把这些洗浴用品,放到这个红色的篮子里面
|
||||
把这些洗浴用品,放到这个红色的篮子里面
|
||||
|
||||
Translation: Put these bathing products into this red basket.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Moreover, besides supporting tasks that involve both text and image inputs, Qwen VLo also supports direct text-to-image generation, including general images as well as bilingual (Chinese and English) posters.
|
||||
|
||||
Text to Image Next
|
||||
@@ -564,8 +463,6 @@ Epic anime artwork of a wizard atop a mountain at night casting a cosmic spell i
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -574,8 +471,6 @@ Fisheye lens, an orange cat wearing sunglasses, a scarf, and fuzzy ear muffs sta
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -584,8 +479,6 @@ User
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -594,8 +487,6 @@ A lone astronaut floats inside a vast space station, painting swirling galaxies
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -604,8 +495,6 @@ Typographic art, a road, a road with a text “2025”, a tiny silhouette of a m
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -614,8 +503,6 @@ User
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -624,8 +511,6 @@ User
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -634,8 +519,6 @@ Crayon scraper painting, large color blocks, smudges, freehand brushwork, on a g
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Qwen VLo supports image generation with dynamic aspect ratio, and can easily handle elongated formats with aspect ratios as extreme as 4:1 or 1:3. (The feature for generating images with extreme aspect ratios is not yet officially launched—stay tuned for its release.)
|
||||
|
||||
Text to Image Next
|
||||
@@ -648,8 +531,6 @@ Translation: Anime illustration; watercolor hand-drawn style; the foreground fea
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -660,8 +541,6 @@ Translation: A tiny boat swiftly sailing across the vast ocean, optical color gr
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -672,8 +551,6 @@ Translation: Jungle Chic, titled “Qwen VLo”, flowers. This is a botanical il
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -684,8 +561,6 @@ Translation: This is a Zen-inspired colorful gold-leaf painting that delicately
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
Text to Image Next
|
||||
|
||||
User
|
||||
@@ -696,8 +571,6 @@ Translation: A magnificent natural landscape painting showcasing majestic snow-c
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
As a unified understanding and generative model, Qwen VLo can also reanalyze and understand the content it generates. For example, it can identify the breeds of dogs and cats within the generated images.
|
||||
|
||||
Generation and Understanding Next
|
||||
@@ -708,8 +581,6 @@ Generate a puppy and a kitten.
|
||||
|
||||
Qwen-VLo
|
||||
|
||||

|
||||
|
||||
User
|
||||
|
||||
What breed of cat and dog is this?
|
||||
@@ -726,16 +597,12 @@ The image shows a puppy and a kitten interacting in a cozy indoor setting. Let
|
||||
* Compact body structure.
|
||||
* Expressive eyes and a friendly demeanor.
|
||||
|
||||
|
||||
|
||||
### **Cat:**
|
||||
|
||||
* The kitten appears to be a **Tabby cat**. Key characteristics include:
|
||||
* Striped or spotted fur pattern, which is typical of tabby cats.
|
||||
* A mix of brown, black, and white fur, which is common in tabby patterns.
|
||||
|
||||
|
||||
|
||||
Both animals are young and appear to be very playful and curious, which is typical behavior for puppies and kittens. The interaction between them suggests a friendly and affectionate relationship, which is often seen when different species bond early in life.
|
||||
|
||||
## **How to Use**
|
||||
|
||||
@@ -17,8 +17,6 @@ Additionally, we have WeChat groups for chatting and we invite you to join the g
|
||||
|
||||
In general, Qwen is more than a language model but a project towards AGI which for now consists of LLM and LMM. The following figure shows the main components of Qwen:
|
||||
|
||||

|
||||
|
||||
where Qwen refers to the base language model, while Qwen-Chat refers to the chat model trained with techniques like SFT and RLHF. We also have models specialized for domains and tasks, such as Code-Qwen for coding and Math-Qwen for mathematics. LLM can be extended to multimodality with modality alignment, and thus we have vision-language model Qwen-VL as well as audio-language model Qwen-Audio. Note that this blog mainly serves for introducing the language model. As to the large multimodal models (LMM), such as Qwen-VL and Qwen-Audio, please refer to the respective blog.
|
||||
|
||||
## Base Model: A Good Starting Point for Alignment
|
||||
@@ -34,20 +32,15 @@ Qwen-72B| 23.11.30| 32K| ✔| 3.0T| 61.4GB| 48.9GB| ✔
|
||||
|
||||
Models are sufficiently trained with 2-3 trillion tokens. The pretraining data are multilingual, and thus Qwen is essentially a multilingual model instead of a model of a single language or bilingual. Note that due to the limitations of our pretraining data, the model is strongly capable of English and Chinese and also capable of other languages, such as Spanish, French, and Japanese. To extend its multilingual capabilities, we applied a tokenizer with high efficiency in encoding information from different languages. In comparison with other tokenizers, ours demonstrates high compression rate in a series of languages.
|
||||
|
||||

|
||||
|
||||
Another focus of our pretraining is the extension of context length. We directly apply continual pretraining with longer context length and larger base value for RoPE. Additionally, we find that.this method is also effective in extrapolation. Now our opensourced models mostly support a context length of 32K tokens, and they were evaluated through L-Eval and “Needle in a Haystack”.
|
||||
|
||||
Model| Input Length| Average| Coursera| GSM| QuALITY| TOEFL| CodeU| SFcition
|
||||
---|---|---|---|---|---|---|---|---
|
||||
ChatGPT-3.5-16k| 16K| 60.73| 63.51| 84.00| 61.38| 78.43| 12.22| 64.84
|
||||
Qwen-72B-Chat| 32K| 62.30| 58.13| 76.00| 77.22| 86.24| 6.66| 69.53
|
||||

|
||||
|
||||
Benchmark evaluation shows that our largest opensourced model Qwen-72B as well as the largest proprietary shows competitive performance against Llama 2, GPT-3.5 and GPT-4.
|
||||
|
||||

|
||||
|
||||
Note that this is an evaluation of base language model. This only reflects that we might have a good starting point for post-training, i.e., SFT and RLHF.
|
||||
|
||||
## Alignment
|
||||
@@ -56,8 +49,6 @@ We refer both techniques to the word “alignment” in post-training. Currently
|
||||
|
||||
Based on a good SFT model, we can then explore the effects of RLHF. It is difficult to train RLHF, specifically PPO-based method, Besides the training instabilities of PPO, another key to the final performance is the quality of reward model. Therefore, we have spent efforts in building a reliable reward model by reward model pretraining on large-scale comparison data and finetuning on carefully labeled comparison data of high quality. In comparison with the SFT model, we find that the RLHF model is more creative and follows the instructions better, and thus its generated responses are more preferred by human annotators.
|
||||
|
||||

|
||||
|
||||
## Tool Use and Agent
|
||||
|
||||
One of the most amazing parts of today’s LLMs is the capabilities of tool use and agent playing. We directly label data of ReAct formats in order to endow the abilities of generating thought and action and generating responses based on previous steps and observations. Also, the model directly learns the in-context learning ability and thus it then can use unseen tool through understanding instructions and demonstrations.
|
||||
@@ -71,7 +62,8 @@ We release the Qwen series, and in this blog, we provide a simple introduction t
|
||||
## Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite!
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{qwen,
|
||||
title={Qwen Technical Report},
|
||||
author={Jinze Bai and Shuai Bai and Yunfei Chu and Zeyu Cui and Kai Dang and Xiaodong Deng and Yang Fan and Wenbin Ge and Yu Han and Fei Huang and Binyuan Hui and Luo Ji and Mei Li and Junyang Lin and Runji Lin and Dayiheng Liu and Gao Liu and Chengqiang Lu and Keming Lu and Jianxin Ma and Rui Men and Xingzhang Ren and Xuancheng Ren and Chuanqi Tan and Sinan Tan and Jianhong Tu and Peng Wang and Shijie Wang and Wei Wang and Shengguang Wu and Benfeng Xu and Jin Xu and An Yang and Hao Yang and Jian Yang and Shusheng Yang and Yang Yao and Bowen Yu and Hongyi Yuan and Zheng Yuan and Jianwei Zhang and Xingxuan Zhang and Yichang Zhang and Zhenru Zhang and Chang Zhou and Jingren Zhou and Xiaohuan Zhou and Tianhang Zhu},
|
||||
@@ -79,4 +71,5 @@ If you find our work helpful, feel free to give us a cite!
|
||||
year={2023}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -55,7 +55,8 @@ We advise you to read our blog for [Qwen1.5](https://qwenlm.github.io/blog/qwen1
|
||||
The Qwen1.5-110B is the largest model in the Qwen1.5 series, and it is also the first one with over 100 billion parameters in the series. It demonstrates competitive performance against the very recently released SOTA model Llama-3-70B and it is significantly better than the 72B model. This tells us that there is still a lot of room in model size scaling for better performance. While the releease of Llama-3 indicates the significance of data scaling to an extremely large scale, we believe we can get the best of both worlds by scaling both data and model size in our future release. Stay tuned for zen!
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen1.5,
|
||||
title = {Introducing Qwen1.5},
|
||||
url = {https://qwenlm.github.io/blog/qwen1.5/},
|
||||
@@ -64,4 +65,5 @@ The Qwen1.5-110B is the largest model in the Qwen1.5 series, and it is also the
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -11,8 +11,6 @@ author: "Zen LM Team"
|
||||
|
||||
# Introduction
|
||||
|
||||

|
||||
|
||||
The open-source community has long sought a model that strikes an ideal balance between performance, efficiency, and memory footprint. Despite the emergence of cutting-edge models like Qwen1.5-72B and DBRX, the models have faced persistent challenges such as large memory consumption, slow inference speed, and substantial finetuning costs.
|
||||
|
||||
A growing consensus within the field now points to a model with approximately 30 billion parameters as the optimal “sweet spot” for achieving both strong performance and manageable resource requirements. In response to this trend, we are proud to unveil the latest additions to our Qwen1.5 language model series: Qwen1.5-32B and Qwen1.5-32B-Chat.
|
||||
@@ -59,8 +57,6 @@ Similar to other Qwen1.5 models, the 32B one also has decent multiplingual capab
|
||||
|
||||
Finally we come to take a look at its performance in the long-context evaluation, Needle in a Haystack. We are happy to see that it is able to achieve a top-level performance in the context of 32K tokens.
|
||||
|
||||

|
||||
|
||||
# Develop with Qwen1.5-32B
|
||||
|
||||
We advise you to read our blog for [Qwen1.5](https://qwenlm.github.io/blog/qwen1.5/) to figure out the usages with Transformers, vLLM, llama.cpp, Ollama, etc.
|
||||
@@ -70,7 +66,8 @@ We advise you to read our blog for [Qwen1.5](https://qwenlm.github.io/blog/qwen1
|
||||
We release the medium-size model Qwen1.5-32B as well as its chat counterpart. The models require much less memory footprint and run significantly faster than the 72B model. We hope that this release can help our users to figure out a better solution for their downstream application to tackle the problems of weak capabilities of 14B models (especially in agent playing scenarios) and high inference costs of 72B models.
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen1.5,
|
||||
title = {Introducing Qwen1.5},
|
||||
url = {https://qwenlm.github.io/blog/qwen1.5/},
|
||||
@@ -79,4 +76,5 @@ We release the medium-size model Qwen1.5-32B as well as its chat counterpart. Th
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -13,14 +13,10 @@ author: "Zen LM Team"
|
||||
|
||||
In recent months, our focus has been on developing a “good” model while optimizing the developer experience. As we progress towards **Qwen1.5** , the next iteration in our Qwen series, this update arrives just before the Chinese New Year.
|
||||
|
||||

|
||||
|
||||
With Qwen1.5, we are open-sourcing base and chat models across six sizes: 0.5B, 1.8B, 4B, 7B, 14B, 32B, 72B, and 110B, and also an MoE model (see [blog](https://qwenlm.github.io/blog/qwen-moe/) for more information). In line with tradition, we’re also providing quantized models, including Int4 and Int8 GPTQ models, as well as AWQ and GGUF quantized models. To enhance the developer experience, we’ve merged Qwen1.5’s code into Hugging Face transformers, making it accessible with `transformers>=4.37.0` without needing `trust_remote_code`.
|
||||
|
||||
We’ve collaborated with frameworks like [vLLM](https://vllm.readthedocs.io/), [SGLang](https://github.com/sgl-project/sglang) for deployment, [AutoAWQ](https://github.com/casper-hansen/AutoAWQ), [AutoGPTQ](https://github.com/AutoGPTQ/AutoGPTQ) for quantization, [Axolotl](https://github.com/OpenAccess-AI-Collective/axolotl), [LLaMA-Factory](https://github.com/hiyouga/LLaMA-Factory) for finetuning, and [llama.cpp](https://github.com/ggerganov/llama.cpp) for local LLM inference, all of which now support Qwen1.5. The Qwen1.5 series is available on platforms such as [Ollama](https://ollama.ai/) and [LMStudio](https://lmstudio.ai/). Additionally, API services are offered not only on DashScope but also on [together.ai](https://together.ai/), with global accessibility. Visit [here](https://api.together.ai/) to get started, and we recommend trying out [Qwen1.5-72B-chat](https://api.together.xyz/playground/chat/Qwen/Qwen1.5-72B-Chat).
|
||||
|
||||

|
||||
|
||||
This release brings substantial improvements to the alignment of chat models with human preferences and enhanced multilingual capabilities. All models now uniformly support a context length of up to 32768 tokens. There have also been minor improvements in the quality of base language models that may benefit your finetuning endeavors. This step represents a small stride toward our objective of creating a truly “good” model.
|
||||
|
||||
# Performance
|
||||
@@ -70,8 +66,6 @@ Alignment aims to enhance instruction-following capabilities of LLMs and help pr
|
||||
|
||||
However, assessing the quality of such chat models poses a significant challenge. Admittedly, while comprehensive human evaluation is the optimal approach, it faces significant challenges pertaining to scalability and reproducibility. Therefore, we initially evaluate our models on two widely-used benchmarks, utilizing advanced LLMs as judges: MT-Bench and Alpaca-Eval. The results are presented below:
|
||||
|
||||

|
||||
|
||||
We notice there are non-negligible variance in the scores on MT-Bench. So we have three runs with different seeds in our results and we report the average score with standard deviation.
|
||||
|
||||
Models| MT-Bench| AlpacaEval 2.0
|
||||
@@ -122,8 +116,6 @@ Qwen1.5-72B| 66.35| 78.16| 61.67| 35.57
|
||||
|
||||
The base models of Qwen1.5 showcase impressive multilingual capabilities, as demonstrated by its performance across a diverse set of 12 languages. In evaluations covering various dimensions such as exams, understanding, translation, and math, Qwen1.5 consistently delivers strong results. From languages like Arabic, Spanish, and French to Japanese, Korean, and Thai, Qwen1.5 demonstrates its ability to comprehend and generate high-quality content across different linguistic contexts. We compared Qwen1.5-72B-Chat with GPT-3.5, and the results are shown below:
|
||||
|
||||

|
||||
|
||||
These results demonstrate the strong multilingual capabilities of Qwen1.5 chat models, which can serve downstream applications, such as translation, language understanding, and multilingual chat. Also, we believe that the improvements in multilingual capabilities can also level up the general capabilities.
|
||||
|
||||
## Support of Long Context
|
||||
@@ -228,17 +220,20 @@ Larger Qwen1.5-Chat models generally outperform smaller ones, nearing GPT-4’s
|
||||
# Develop with Qwen1.5
|
||||
|
||||
The biggest difference in Qwen1.5 is the integration of Qwen1.5 to Hugging Face transformers. Since 4.37.0, you can use Qwen1.5 without our custom code, which means that you can load the model like the following:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM
|
||||
# This is what we previously used
|
||||
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen-7B-Chat", device_map="auto", trust_remote_code=True)
|
||||
# This is what you can use now
|
||||
model = AutoModelForCausalLM.from_pretrained("Qwen/Qwen1.5-7B-Chat", device_map="auto")
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The usage of Qwen1.5 for chat is different from the previous version. You can use the following code to chat with Qwen1.5:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
device = "cuda" # the device to load the model onto
|
||||
|
||||
@@ -270,18 +265,22 @@ The usage of Qwen1.5 for chat is different from the previous version. You can us
|
||||
|
||||
response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
For chat models, we no longer use a specific `model.chat()` method, but instead we use `model.generate()` with the chat template written in `tokenizer_config.json` so that we can use `tokenizer.apply_chat_template()` to generate the input, and we use `eos_token` to control when to stop the generation.
|
||||
|
||||
We also provide AWQ models and GPTQ models (including Int4 and Int8 models) for you to use Qwen1.5 in low-resource or deployment scenarios. As Huggingface transformers supports [AWQ](https://github.com/casper-hansen/AutoAWQ) and [GPTQ](https://github.com/AutoGPTQ/AutoGPTQ), you can use them in the same way above only with the corresponding model names.
|
||||
|
||||
Furthermore, we have integrated our code to popular inference frameworks so that you can deploy your model easily. Now `vLLM>=0.3.0` and `SGLang>=0.1.11` officially support Qwen1.5. Check their official github repos and docs to learn about the detailed usage. Here we demonstrate an example to show how to use vLLM to build an OpenAI-API compatible interface for our model:
|
||||
[code]
|
||||
```
|
||||
|
||||
python -m vllm.entrypoints.openai.api_server --model Qwen/Qwen1.5-7B-Chat
|
||||
|
||||
[/code]
|
||||
[code]
|
||||
|
||||
```
|
||||
```bash
|
||||
|
||||
curl http://localhost:8000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
@@ -292,19 +291,24 @@ Furthermore, we have integrated our code to popular inference frameworks so that
|
||||
]
|
||||
}'
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
For users to run LLM locally, llama.cpp also provides support to Qwen1.5, and we officially provide quantized models in the GGUF format in our HF model hub. You can use the following code to run Qwen1.5 in llama.cpp:
|
||||
[code]
|
||||
```
|
||||
|
||||
./main -m qwen1.5-7b-chat-q2_k.gguf -n 512 --color -i -cml -f prompts/chat-with-qwen.txt
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Besides, you can use the GGUF file with Ollama. Thanks to the support of [Ollama](https://ollama.ai/), you can now directly use one line of command:
|
||||
[code]
|
||||
```
|
||||
|
||||
ollama run qwen
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Or you can use the GGUF file to play with [llamafile](https://github.com/Mozilla-Ocho/llamafile) to run our models with a single file.
|
||||
|
||||
@@ -321,7 +325,8 @@ Overall, as we care about your developing experience, we not only have tried our
|
||||
We are excited to introduce Qwen1.5, the next version of our Qwen series. In this release, we have opensourced both base and chat models of 6 sizes, including 0.5B, 1.8B, 4B, 7B, 14B, and 72B, and we have also provided quantized models. We have merged our code of Qwen1.5 to Hugging face transformers, and you can directly use it with `transformers>=4.37.0` without `trust_remote_code`. Additionally, we have had frameworks, e.g., vLLM, SGLang, AutoGPTQ, etc., supported Qwen1.5. We believe from now on, using our models will be much easier. We believe that this release is though a small step towards model quality, but it is a big step towards developer experience. Hope you like it and enjoy using it. Join our [Discord](https://discord.gg/yPEP2vHTu4) or [WeChat](https://github.com/QwenLM/Qwen/blob/main/assets/wechat.png) to share your experience, comments, or whatever you like with us. We are looking forward to hearing from you.
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen1.5,
|
||||
title = {Introducing Qwen1.5},
|
||||
url = {https://qwenlm.github.io/blog/qwen1.5/},
|
||||
@@ -330,4 +335,5 @@ We are excited to introduce Qwen1.5, the next version of our Qwen series. In thi
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -16,10 +16,8 @@ To achieve the objective of building an AGI system, the model should be capable
|
||||
|
||||
* Multilingual: the model supports more than 8 languages and dialects, e.g., Chinese, English, Cantonese, French, Italian, Spanish, German, and Japanese.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
We open-weight zen-Audio-7B and zen-Audio-7B-Instruct in Hugging Face and ModelScope, and we have built a demo for users to interact with. Below are some examples to show the model performance:
|
||||
|
||||
### Voice Chat
|
||||
@@ -228,28 +226,25 @@ The lyrics of the singing are 'Waiting for my favorite song.'
|
||||
|
||||
We have conducted a series of experiments on benchmark datasets, including LibriSpeech, Common Voice 15, Fleurs, Aishell2, CoVoST2, Meld, Vocalsound, and AIR-Benchmark, to evaluate the performance of zen-Audio in comparison with our previously released Qwen-Audio as well as the state-of-the-art models in each tasks. Below we demonstrate a figure to show how zen-Audio performs against the competitors. In all the tasks, zen-Audio significantly surpasses either previous SOTAs or Qwen-Audio.
|
||||
|
||||

|
||||
|
||||
More specific results on the datasets are listed below in the table.
|
||||
|
||||

|
||||
|
||||
## Architecture
|
||||
|
||||
Below is a demonstration of the training architecture. Specifically, we start from the Qwen language model and an audio encoder as the foundation models. We sequentially apply multi-task pretraining for the audio language alignment, and supervised finetuning as well as direct preference optimization to grasp the capabilities of downstream tasks and model human preference.
|
||||
|
||||

|
||||
|
||||
## How to Use
|
||||
|
||||
Now zen-Audio is officially supported by Hugging Face Transfomers. We advise you install the latest version of `transformers` from source:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
pip install git+https://github.com/huggingface/transformers
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
We demonstrate how to use `zen-Audio-7B-Instruct` to play with voice chat and audio analysis. Here is an example of voice chat:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from io import BytesIO
|
||||
from urllib.request import urlopen
|
||||
import librosa
|
||||
@@ -286,10 +281,12 @@ We demonstrate how to use `zen-Audio-7B-Instruct` to play with voice chat and au
|
||||
|
||||
response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
In voice chat mode, the user input is simply the audio without text, and the instructions from the users are inside the audio. Next is an example of audio analysis:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from io import BytesIO
|
||||
from urllib.request import urlopen
|
||||
import librosa
|
||||
@@ -334,7 +331,8 @@ In voice chat mode, the user input is simply the audio without text, and the ins
|
||||
|
||||
response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
In comparison, in audio analysis mode, there is additional text instructions. However, switching between either mode only needs to modify your user inputs and there is no need to worry about others such as system prompt.
|
||||
|
||||
|
||||
@@ -6,8 +6,6 @@ date: "2024-08-08"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen-Math) [HUGGING FACE](https://huggingface.co/Qwen) [MODELSCOPE](https://modelscope.cn/organization/qwen) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
> **🚨 This model mainly supports English. We will release bilingual (English and Chinese) math models soon.**
|
||||
@@ -18,16 +16,12 @@ Over the past year, we have dedicated significant effort to researching and enha
|
||||
|
||||
We evaluate our math-specific models on a series of math benchmarks. The results below demonstrate that our largest math-specific model zen-Math-72B-Instruct outperforms the state-of-the-art models, including GPT-4o, Claude-3.5-Sonnet, Gemini-1.5-Pro, and Llama-3.1-405B.
|
||||
|
||||

|
||||
|
||||
## zen-Math: Base Models
|
||||
|
||||
The base models of zen-Math are initialized with zen-1.5B/7B/72B, and then pretrained on a meticulously designed Mathematics-specific Corpus. This corpus contains large-scale high-quality mathematical web texts, books, codes, exam questions, and mathematical pre-training data synthesized by zen.
|
||||
|
||||
We evaluate our zen-Math base models on three widely used English math benchmarks GSM8K, Math, and MMLU-STEM. In addition, we also evaluate three Chinese math benchmarks CMATH, GaoKao Math Cloze, and GaoKao Math QA. All evaluations are tested with few-shot chain-of-thought prompting.
|
||||
|
||||

|
||||
|
||||
## zen-Math-Instruct: Instruction-Tuned Models
|
||||
|
||||
We first trained a math-specific reward model based on zen-Math-72B. We then combined this dense reward signal with a binary signal indicating whether the model answered correctly. This combined signal is used as supervision for constructing the SFT data through Rejection Sampling and also in the reinforcement learning with Group Relative Policy Optimization (GRPO) after SFT.
|
||||
@@ -36,12 +30,8 @@ We evaluate zen-Math-Instruct on mathematical benchmarks in both English and Chi
|
||||
|
||||
We report greedy , Maj@8 and RM@8 performance on all benchmarks in the zero-shot setting, except for the multi-choice benchmarks (including MMLU STEM and multiple-choice problems in GaoKao and CN Middle School 24) with a 5-shot setting. zen-Math-Instruct achieves the best performance among models of the same size, with RM@8 outperforming Maj@8, particularly in the 1.5B and 7B models. This demonstrates the effectiveness of our math reward model.
|
||||
|
||||

|
||||
|
||||
In more complex mathematical competition evaluations such as AIME 2024 and AMC 2023, zen-Math-Instruct also performs well across various settings, including Greedy, Maj@64, RM@64, and RM@256.
|
||||
|
||||

|
||||
|
||||
## Case Study
|
||||
|
||||
Here we list some test cases, which include some IMO math problems. From the experimental results and case study, we find that zen-Math is capable of solving simple math competition problems. Feel free to click the expandable blocks to check the cases!
|
||||
@@ -54,77 +44,77 @@ Problem From IMO Shortlist 2002
|
||||
|
||||
What is the smallest positive integer $t$ such that there exist integers $x_1,x_2,\ldots,x_t$ with
|
||||
|
||||
$$ x^3_1+x^3_2+,\ldots,+x^3_t=2002^{2002}, $$
|
||||
` x^3_1+x^3_2+,\ldots,+x^3_t=2002^\{2002\}, `
|
||||
|
||||
**zen-Math-72B-Instruct Solution**
|
||||
|
||||
To determine the smallest positive integer $ t $ such that there exist integers $ x_1, x_2, \ldots, x_t $ satisfying the equation
|
||||
|
||||
$$ x_1^3 + x_2^3 + \cdots + x_t^3 = 2002^{2002}, $$
|
||||
` x_1^3 + x_2^3 + \cdots + x_t^3 = 2002^\{2002\}, `
|
||||
|
||||
we start by analyzing the properties of cubes and their sums. We need to find the smallest $ t $ for which the sum of $ t $ cubes equals $ 2002^{2002} $.
|
||||
we start by analyzing the properties of cubes and their sums. We need to find the smallest $ t $ for which the sum of $ t $ cubes equals $ 2002^{2002} $.
|
||||
|
||||
First, we note that $ 2002 $ can be factored into prime factors:
|
||||
|
||||
$$ 2002 = 2 \times 7 \times 11 \times 13. $$
|
||||
` 2002 = 2 \times 7 \times 11 \times 13. `
|
||||
|
||||
Thus,
|
||||
|
||||
$$ 2002^{2002} = (2 \times 7 \times 11 \times 13)^{2002} = 2^{2002} \times 7^{2002} \times 11^{2002} \times 13^{2002}. $$
|
||||
` 2002^\{2002\} = (2 \times 7 \times 11 \times 13)^\{2002\} = 2^\{2002\} \times 7^\{2002\} \times 11^\{2002\} \times 13^\{2002\}. `
|
||||
|
||||
Next, we consider the properties of cubes modulo 9. Cubes modulo 9 can only be congruent to $ 0, 1, $ or $ -1 $. This is because:
|
||||
|
||||
$$ \begin{aligned} 0^3 &\equiv 0 \pmod{9}, \\\\\ 1^3 &\equiv 1 \pmod{9}, \\\\\ 2^3 &\equiv 8 \equiv -1 \pmod{9}, \\\\\ 3^3 &\equiv 27 \equiv 0 \pmod{9}, \\\\\ 4^3 &\equiv 64 \equiv 1 \pmod{9}, \\\\\ 5^3 &\equiv 125 \equiv -1 \pmod{9}, \\\\\ 6^3 &\equiv 216 \equiv 0 \pmod{9}, \\\\\ 7^3 &\equiv 343 \equiv 1 \pmod{9}, \\\\\ 8^3 &\equiv 512 \equiv -1 \pmod{9}. \end{aligned} $$
|
||||
` \begin\{aligned\} 0^3 &\equiv 0 \pmod\{9\}, \\\\\ 1^3 &\equiv 1 \pmod\{9\}, \\\\\ 2^3 &\equiv 8 \equiv -1 \pmod\{9\}, \\\\\ 3^3 &\equiv 27 \equiv 0 \pmod\{9\}, \\\\\ 4^3 &\equiv 64 \equiv 1 \pmod\{9\}, \\\\\ 5^3 &\equiv 125 \equiv -1 \pmod\{9\}, \\\\\ 6^3 &\equiv 216 \equiv 0 \pmod\{9\}, \\\\\ 7^3 &\equiv 343 \equiv 1 \pmod\{9\}, \\\\\ 8^3 &\equiv 512 \equiv -1 \pmod\{9\}. \end\{aligned\} `
|
||||
|
||||
Now, we need to determine $ 2002^{2002} \mod 9 $. First, we find $ 2002 \mod 9 $:
|
||||
Now, we need to determine $ 2002^{2002} \mod 9 $. First, we find $ 2002 \mod 9 $:
|
||||
|
||||
$$ 2002 \div 9 = 222 \text{ remainder } 4 \quad \Rightarrow \quad 2002 \equiv 4 \pmod{9}. $$
|
||||
` 2002 \div 9 = 222 \text\{ remainder \} 4 \quad \Rightarrow \quad 2002 \equiv 4 \pmod\{9\}. `
|
||||
|
||||
Thus,
|
||||
|
||||
$$ 2002^{2002} \equiv 4^{2002} \pmod{9}. $$
|
||||
` 2002^\{2002\} \equiv 4^\{2002\} \pmod\{9\}. `
|
||||
|
||||
Next, we use Euler’s theorem, which states that $ a^{\phi(n)} \equiv 1 \pmod{n} $ for $ \gcd(a, n) = 1 $. Here, $ \phi(9) = 6 $, so:
|
||||
Next, we use Euler’s theorem, which states that $ a^{\phi(n)} \equiv 1 \pmod{n} $ for $ \gcd(a, n) = 1 $. Here, $ \phi(9) = 6 $, so:
|
||||
|
||||
$$ 4^6 \equiv 1 \pmod{9}. $$
|
||||
` 4^6 \equiv 1 \pmod\{9\}. `
|
||||
|
||||
We can reduce the exponent $ 2002 \mod 6 $:
|
||||
|
||||
$$ 2002 \div 6 = 333 \text{ remainder } 4 \quad \Rightarrow \quad 2002 \equiv 4 \pmod{6}. $$
|
||||
` 2002 \div 6 = 333 \text\{ remainder \} 4 \quad \Rightarrow \quad 2002 \equiv 4 \pmod\{6\}. `
|
||||
|
||||
Thus,
|
||||
|
||||
$$ 4^{2002} \equiv 4^4 \pmod{9}. $$
|
||||
` 4^\{2002\} \equiv 4^4 \pmod\{9\}. `
|
||||
|
||||
$$ 4^4 = 256. $$
|
||||
` 4^4 = 256. `
|
||||
|
||||
Finally, we find $ 256 \mod 9 $:
|
||||
|
||||
$$ 256 \div 9 = 28 \text{ remainder } 4 \quad \Rightarrow \quad 256 \equiv 4 \pmod{9}. $$
|
||||
` 256 \div 9 = 28 \text\{ remainder \} 4 \quad \Rightarrow \quad 256 \equiv 4 \pmod\{9\}. `
|
||||
|
||||
Therefore,
|
||||
|
||||
$$ 2002^{2002} \equiv 4 \pmod{9}. $$
|
||||
` 2002^\{2002\} \equiv 4 \pmod\{9\}. `
|
||||
|
||||
We need to find the smallest $ t $ such that the sum of $ t $ cubes is congruent to 4 modulo 9. The possible sums of cubes modulo 9 are:
|
||||
|
||||
$$ \begin{aligned} 0 &\equiv 0 \pmod{9}, \\\\\ 1 &\equiv 1 \pmod{9}, \\\\\ -1 &\equiv 8 \pmod{9}, \\\\\ 1 + 1 &\equiv 2 \pmod{9}, \\\\\ 1 + (-1) &\equiv 0 \pmod{9}, \\\\\ -1 + (-1) &\equiv -2 \equiv 7 \pmod{9}, \\\\\ 1 + 1 + 1 &\equiv 3 \pmod{9}, \\\\\ 1 + 1 + (-1) &\equiv 1 \pmod{9}, \\\\\ 1 + (-1) + (-1) &\equiv -1 \equiv 8 \pmod{9}, \\\\\ -1 + (-1) + (-1) &\equiv -3 \equiv 6 \pmod{9}, \\\\\ 1 + 1 + 1 + 1 &\equiv 4 \pmod{9}. \end{aligned} $$
|
||||
` \begin\{aligned\} 0 &\equiv 0 \pmod\{9\}, \\\\\ 1 &\equiv 1 \pmod\{9\}, \\\\\ -1 &\equiv 8 \pmod\{9\}, \\\\\ 1 + 1 &\equiv 2 \pmod\{9\}, \\\\\ 1 + (-1) &\equiv 0 \pmod\{9\}, \\\\\ -1 + (-1) &\equiv -2 \equiv 7 \pmod\{9\}, \\\\\ 1 + 1 + 1 &\equiv 3 \pmod\{9\}, \\\\\ 1 + 1 + (-1) &\equiv 1 \pmod\{9\}, \\\\\ 1 + (-1) + (-1) &\equiv -1 \equiv 8 \pmod\{9\}, \\\\\ -1 + (-1) + (-1) &\equiv -3 \equiv 6 \pmod\{9\}, \\\\\ 1 + 1 + 1 + 1 &\equiv 4 \pmod\{9\}. \end\{aligned\} `
|
||||
|
||||
We see that the sum of four cubes can be congruent to 4 modulo 9. Therefore, the smallest $ t $ is 4.
|
||||
|
||||
Thus, the smallest positive integer $ t $ such that there exist integers $ x_1, x_2, \ldots, x_t $ with
|
||||
|
||||
$$ x_1^3 + x_2^3 + \cdots + x_t^3 = 2002^{2002} $$
|
||||
` x_1^3 + x_2^3 + \cdots + x_t^3 = 2002^\{2002\} `
|
||||
|
||||
is
|
||||
|
||||
$$ \boxed{4}. $$
|
||||
` \boxed\{4\}. `
|
||||
|
||||
Problem From IMO Shortlist 2022
|
||||
|
||||
**Problem**
|
||||
|
||||
For a positive integer $n$ we denote by $s(n)$ the sum of the digits of $n$. Let $P(x)=x^n+a_{n-1}x^{n-1}+\cdots+a_1x+a_0$ be a polynomial, where $n \geqslant 2$ and $a_i$ is a positive integer for all $ 0 \leqslant i \leqslant n-1$. Could it be the case that, for all positive integers $k$, $s(k)$ and $s(P(k))$ have the same parity?
|
||||
|
||||
**zen-Math-72B-Instruct Solution**
|
||||
|
||||
@@ -132,119 +122,110 @@ To determine whether it is possible for $ s(k) $ and $ s(P(k)) $ to have the sam
|
||||
|
||||
First, recall that the sum of the digits of a number $ k $ modulo 2 is equivalent to $ k \mod 2 $. This is because the sum of the digits of $ k $ in base 10 is congruent to $ k \mod 9 $, and since $ 9 \equiv 1 \mod 2 $, the sum of the digits modulo 2 is the same as $ k \mod 2 $.
|
||||
|
||||
Given the polynomial $ P(x) = x^n + a_{n-1}x^{n-1} + \cdots + a_1x + a_0 $, we need to determine the parity of $ P(k) $ for any positive integer $ k $. Specifically, we need to check if $ P(k) \mod 2 $ is the same as $ k \mod 2 $.
|
||||
Given the polynomial $ P(x) = x^n + a_{n-1}x^{n-1} + \cdots + a_1x + a_0 $, we need to determine the parity of $ P(k) $ for any positive integer $ k $. Specifically, we need to check if $ P(k) \mod 2 $ is the same as $ k \mod 2 $.
|
||||
|
||||
Let’s consider the polynomial modulo 2:
|
||||
|
||||
$$ P(x) \equiv x^n + a_{n-1}x^{n-1} + \cdots + a_1x + a_0 \mod 2. $$
|
||||
` P(x) \equiv x^n + a_\{n-1\}x^\{n-1\} + \cdots + a_1x + a_0 \mod 2. `
|
||||
|
||||
Since $ a_i $ are positive integers, $ a_i \mod 2 $ is either 0 or 1. Let $ b_i = a_i \mod 2 $. Then we can rewrite the polynomial modulo 2 as:
|
||||
|
||||
$$ P(x) \equiv x^n + b_{n-1}x^{n-1} + \cdots + b_1x + b_0 \mod 2. $$
|
||||
` P(x) \equiv x^n + b_\{n-1\}x^\{n-1\} + \cdots + b_1x + b_0 \mod 2. `
|
||||
|
||||
Now, we need to check the parity of $ P(k) $ for $ k \equiv 0 \mod 2 $ and $ k \equiv 1 \mod 2 $.
|
||||
|
||||
1. **Case 1: $ k \equiv 0 \mod 2 $**
|
||||
|
||||
$$ P(0) \equiv b_0 \mod 2. $$
|
||||
` P(0) \equiv b_0 \mod 2. `
|
||||
|
||||
For $ s(P(0)) $ to have the same parity as $ s(0) $, $ b_0 $ must be 0. Therefore, $ a_0 $ must be even.
|
||||
|
||||
2. **Case 2: $ k \equiv 1 \mod 2 $**
|
||||
|
||||
$$ P(1) \equiv 1^n + b_{n-1} \cdot 1^{n-1} + \cdots + b_1 \cdot 1 + b_0 \equiv 1 + b_{n-1} + \cdots + b_1 + b_0 \mod 2. $$
|
||||
|
||||
For $ s(P(1)) $ to have the same parity as $ s(1) $, $ 1 + b_{n-1} + \cdots + b_1 + b_0 $ must be odd. Since $ 1 $ is odd, the sum $ b_{n-1} + \cdots + b_1 + b_0 $ must be even.
|
||||
|
||||
|
||||
` P(1) \equiv 1^n + b_\{n-1\} \cdot 1^\{n-1\} + \cdots + b_1 \cdot 1 + b_0 \equiv 1 + b_\{n-1\} + \cdots + b_1 + b_0 \mod 2. `
|
||||
|
||||
For $ s(P(1)) $ to have the same parity as $ s(1) $, $ 1 + b_{n-1} + \cdots + b_1 + b_0 $ must be odd. Since $ 1 $ is odd, the sum $ b_{n-1} + \cdots + b_1 + b_0 $ must be even.
|
||||
|
||||
From the above cases, we have:
|
||||
|
||||
* $ a_0 $ must be even.
|
||||
* The sum $ b_{n-1} + \cdots + b_1 + b_0 $ must be even.
|
||||
* The sum $ b_{n-1} + \cdots + b_1 + b_0 $ must be even.
|
||||
|
||||
|
||||
|
||||
However, if $ a_0 $ is even, then $ b_0 = 0 $. This means the sum $ b_{n-1} + \cdots + b_1 $ must be even. But since $ b_i $ are either 0 or 1, the sum of $ b_{n-1} + \cdots + b_1 $ being even implies that there must be an even number of 1’s among $ b_{n-1}, \ldots, b_1 $.
|
||||
However, if $ a_0 $ is even, then $ b_0 = 0 $. This means the sum $ b_{n-1} + \cdots + b_1 $ must be even. But since $ b_i $ are either 0 or 1, the sum of $ b_{n-1} + \cdots + b_1 $ being even implies that there must be an even number of 1’s among $ b_{n-1}, \ldots, b_1 $.
|
||||
|
||||
Now, consider the polynomial $ P(x) = x^n + 1 $. For this polynomial:
|
||||
|
||||
* $ a_0 = 1 $ (odd), which contradicts our requirement that $ a_0 $ must be even.
|
||||
* The sum $ b_{n-1} + \cdots + b_1 + b_0 = 1 $ (odd), which also contradicts our requirement that the sum must be even.
|
||||
|
||||
|
||||
* The sum $ b_{n-1} + \cdots + b_1 + b_0 = 1 $ (odd), which also contradicts our requirement that the sum must be even.
|
||||
|
||||
Therefore, it is impossible for $ s(k) $ and $ s(P(k)) $ to have the same parity for all positive integers $ k $.
|
||||
|
||||
Thus, the final answer is:
|
||||
|
||||
$$ \boxed{\text{No}} $$
|
||||
` \boxed\{\text\{No\}\} `
|
||||
|
||||
Problem From IMO 2022
|
||||
|
||||
**Problem**
|
||||
|
||||
Let $\mathbb{R}^+$ denote the set of positive real numbers. Find all functions $f: \mathbb{R}^+ \to \mathbb{R}^+$ such that for each $x \in \mathbb{R}^+$, there is exactly one $y \in \mathbb{R}^+$ satisfying
|
||||
Let $\mathbb{R}^+$ denote the set of positive real numbers. Find all functions $f: \mathbb{R}^+ \to \mathbb{R}^+$ such that for each $x \in \mathbb{R}^+$, there is exactly one $y \in \mathbb{R}^+$ satisfying
|
||||
|
||||
$$ xf(y)+yf(x) \leq 2 $$
|
||||
` xf(y)+yf(x) \leq 2 `
|
||||
|
||||
**zen-Math-72B-Instruct Solution**
|
||||
|
||||
To find all functions $ f: \mathbb{R}^+ \to \mathbb{R}^+ $ such that for each $ x \in \mathbb{R}^+ $, there is exactly one $ y \in \mathbb{R}^+ $ satisfying
|
||||
To find all functions $ f: \mathbb{R}^+ \to \mathbb{R}^+ $ such that for each $ x \in \mathbb{R}^+ $, there is exactly one $ y \in \mathbb{R}^+ $ satisfying
|
||||
|
||||
$$ xf(y) + yf(x) \leq 2, $$
|
||||
` xf(y) + yf(x) \leq 2, `
|
||||
|
||||
we will proceed step by step.
|
||||
|
||||
**Step 1: Analyze the given inequality** Given $ x \in \mathbb{R}^+ $, there exists a unique $ y \in \mathbb{R}^+ $ such that
|
||||
**Step 1: Analyze the given inequality** Given $ x \in \mathbb{R}^+ $, there exists a unique $ y \in \mathbb{R}^+ $ such that
|
||||
|
||||
$$ xf(y) + yf(x) \leq 2. $$
|
||||
` xf(y) + yf(x) \leq 2. `
|
||||
|
||||
We need to explore the implications of this condition.
|
||||
|
||||
**Step 2: Consider the case $ x = y $** Substitute $ y = x $ into the inequality:
|
||||
|
||||
$$ xf(x) + xf(x) = 2xf(x) \leq 2. $$
|
||||
` xf(x) + xf(x) = 2xf(x) \leq 2. `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ xf(x) \leq 1. $$
|
||||
` xf(x) \leq 1. `
|
||||
|
||||
Thus, for all $ x \in \mathbb{R}^+ $,
|
||||
Thus, for all $ x \in \mathbb{R}^+ $,
|
||||
|
||||
$$ f(x) \leq \frac{1}{x}. $$
|
||||
` f(x) \leq \frac\{1\}\{x\}. `
|
||||
|
||||
**Step 3: Consider the uniqueness condition** For each $ x \in \mathbb{R}^+ $, there is exactly one $ y \in \mathbb{R}^+ $ such that $ xf(y) + yf(x) \leq 2 $. We need to ensure that this $ y $ is unique.
|
||||
**Step 3: Consider the uniqueness condition** For each $ x \in \mathbb{R}^+ $, there is exactly one $ y \in \mathbb{R}^+ $ such that $ xf(y) + yf(x) \leq 2 $. We need to ensure that this $ y $ is unique.
|
||||
|
||||
**Step 4: Test the function $ f(x) = \frac{1}{x} $** Consider the function $ f(x) = \frac{1}{x} $. Substitute $ f(x) = \frac{1}{x} $ and $ f(y) = \frac{1}{y} $ into the inequality:
|
||||
**Step 4: Test the function $ f(x) = \frac{1}{x} $** Consider the function $ f(x) = \frac{1}{x} $. Substitute $ f(x) = \frac{1}{x} $ and $ f(y) = \frac{1}{y} $ into the inequality:
|
||||
|
||||
$$ x \cdot \frac{1}{y} + y \cdot \frac{1}{x} = \frac{x}{y} + \frac{y}{x}. $$
|
||||
` x \cdot \frac\{1\}\{y\} + y \cdot \frac\{1\}\{x\} = \frac\{x\}\{y\} + \frac\{y\}\{x\}. `
|
||||
|
||||
We need:
|
||||
|
||||
$$ \frac{x}{y} + \frac{y}{x} \leq 2. $$
|
||||
` \frac\{x\}\{y\} + \frac\{y\}\{x\} \leq 2. `
|
||||
|
||||
Using the AM-GM inequality, we know:
|
||||
|
||||
$$ \frac{x}{y} + \frac{y}{x} \geq 2. $$
|
||||
` \frac\{x\}\{y\} + \frac\{y\}\{x\} \geq 2. `
|
||||
|
||||
Equality holds if and only if $ \frac{x}{y} = 1 $, which implies $ x = y $.
|
||||
Equality holds if and only if $ \frac{x}{y} = 1 $, which implies $ x = y $.
|
||||
|
||||
Thus, for $ f(x) = \frac{1}{x} $, the inequality $ xf(y) + yf(x) \leq 2 $ holds if and only if $ x = y $. This satisfies the condition that there is exactly one $ y $ for each $ x $.
|
||||
Thus, for $ f(x) = \frac{1}{x} $, the inequality $ xf(y) + yf(x) \leq 2 $ holds if and only if $ x = y $. This satisfies the condition that there is exactly one $ y $ for each $ x $.
|
||||
|
||||
**Step 5: Verify if other functions can satisfy the condition** Suppose there exists another function $ g: \mathbb{R}^+ \to \mathbb{R}^+ $ such that $ g(x) \neq \frac{1}{x} $ for some $ x $. Then, for some $ x $, $ g(x) < \frac{1}{x} $ or $ g(x) > \frac{1}{x} $.
|
||||
**Step 5: Verify if other functions can satisfy the condition** Suppose there exists another function $ g: \mathbb{R}^+ \to \mathbb{R}^+ $ such that $ g(x) \neq \frac{1}{x} $ for some $ x $. Then, for some $ x $, $ g(x) < \frac{1}{x} $ or $ g(x) > \frac{1}{x} $.
|
||||
|
||||
* If $ g(x) < \frac{1}{x} $, then $ xg(y) + yg(x) $ might not satisfy the inequality for all $ y $.
|
||||
* If $ g(x) > \frac{1}{x} $, then $ xg(y) + yg(x) $ might exceed 2 for some $ y $.
|
||||
* If $ g(x) < \frac{1}{x} $, then $ xg(y) + yg(x) $ might not satisfy the inequality for all $ y $.
|
||||
* If $ g(x) > \frac{1}{x} $, then $ xg(y) + yg(x) $ might exceed 2 for some $ y $.
|
||||
|
||||
Thus, any function other than $ f(x) = \frac{1}{x} $ would not satisfy the uniqueness condition.
|
||||
|
||||
**Conclusion** The only function $ f: \mathbb{R}^+ \to \mathbb{R}^+ $ that satisfies the given condition is:
|
||||
|
||||
Thus, any function other than $ f(x) = \frac{1}{x} $ would not satisfy the uniqueness condition.
|
||||
|
||||
**Conclusion** The only function $ f: \mathbb{R}^+ \to \mathbb{R}^+ $ that satisfies the given condition is:
|
||||
|
||||
$$ \boxed{f(x) = \frac{1}{x}}. $$
|
||||
` \boxed\{f(x) = \frac\{1\}\{x\}\}. `
|
||||
|
||||
Problem from International Zhautykov Olympiad 2020
|
||||
|
||||
@@ -252,15 +233,15 @@ Problem from International Zhautykov Olympiad 2020
|
||||
|
||||
Let $Z$ be the set of all integers. Find all the function $f: Z \to Z$ such that
|
||||
|
||||
$$ f(4x+3y)=f(3x+y)+f(x+2y) $$
|
||||
` f(4x+3y)=f(3x+y)+f(x+2y) `
|
||||
|
||||
For all integers $x,y$
|
||||
|
||||
**zen-Math-72B-Instruct Solution**
|
||||
|
||||
To find all functions $ f: \mathbb{Z} \to \mathbb{Z} $ that satisfy the functional equation
|
||||
To find all functions $ f: \mathbb{Z} \to \mathbb{Z} $ that satisfy the functional equation
|
||||
|
||||
$$ f(4x + 3y) = f(3x + y) + f(x + 2y) $$
|
||||
` f(4x + 3y) = f(3x + y) + f(x + 2y) `
|
||||
|
||||
for all integers $ x $ and $ y $, we will proceed step by step.
|
||||
|
||||
@@ -270,15 +251,15 @@ First, let’s substitute specific values for $ x $ and $ y $ to gain insight in
|
||||
|
||||
Substitution 1: $ x = 0 $
|
||||
|
||||
$$ f(4 \cdot 0 + 3y) = f(3 \cdot 0 + y) + f(0 + 2y) $$
|
||||
` f(4 \cdot 0 + 3y) = f(3 \cdot 0 + y) + f(0 + 2y) `
|
||||
|
||||
$$ f(3y) = f(y) + f(2y) $$
|
||||
` f(3y) = f(y) + f(2y) `
|
||||
|
||||
Substitution 2: $ y = 0 $
|
||||
|
||||
$$ f(4x + 3 \cdot 0) = f(3x + 0) + f(x + 2 \cdot 0) $$
|
||||
` f(4x + 3 \cdot 0) = f(3x + 0) + f(x + 2 \cdot 0) `
|
||||
|
||||
$$ f(4x) = f(3x) + f(x) $$
|
||||
` f(4x) = f(3x) + f(x) `
|
||||
|
||||
**Step 2: Exploring Further Substitutions**
|
||||
|
||||
@@ -287,33 +268,31 @@ We now have two equations:
|
||||
1. $ f(3y) = f(y) + f(2y) $
|
||||
2. $ f(4x) = f(3x) + f(x) $
|
||||
|
||||
|
||||
|
||||
Substitution 3: $ y = 1 $ in the first equation
|
||||
|
||||
$$ f(3 \cdot 1) = f(1) + f(2 \cdot 1) $$
|
||||
` f(3 \cdot 1) = f(1) + f(2 \cdot 1) `
|
||||
|
||||
$$ f(3) = f(1) + f(2) $$
|
||||
` f(3) = f(1) + f(2) `
|
||||
|
||||
Substitution 4: $ x = 1 $ in the second equation
|
||||
|
||||
$$ f(4 \cdot 1) = f(3 \cdot 1) + f(1) $$
|
||||
` f(4 \cdot 1) = f(3 \cdot 1) + f(1) `
|
||||
|
||||
$$ f(4) = f(3) + f(1) $$
|
||||
` f(4) = f(3) + f(1) `
|
||||
|
||||
**Step 3: Using the Equations to Find a Pattern**
|
||||
|
||||
We have:
|
||||
|
||||
$$ f(3) = f(1) + f(2) $$
|
||||
` f(3) = f(1) + f(2) `
|
||||
|
||||
$$ f(4) = f(3) + f(1) $$
|
||||
` f(4) = f(3) + f(1) `
|
||||
|
||||
Substitute $ f(3) $ from the first equation into the second equation:
|
||||
|
||||
$$ f(4) = (f(1) + f(2)) + f(1) $$
|
||||
` f(4) = (f(1) + f(2)) + f(1) `
|
||||
|
||||
$$ f(4) = 2f(1) + f(2) $$
|
||||
` f(4) = 2f(1) + f(2) `
|
||||
|
||||
**Step 4: Generalizing the Function**
|
||||
|
||||
@@ -321,47 +300,49 @@ We hypothesize that $ f $ might be a linear function. Let’s assume $ f(x) = kx
|
||||
|
||||
_Verification_ Substitute $ f(x) = kx $ into the original functional equation:
|
||||
|
||||
$$ f(4x + 3y) = k(4x + 3y) $$
|
||||
` f(4x + 3y) = k(4x + 3y) `
|
||||
|
||||
$$ f(3x + y) = k(3x + y) $$
|
||||
` f(3x + y) = k(3x + y) `
|
||||
|
||||
$$ f(x + 2y) = k(x + 2y) $$
|
||||
` f(x + 2y) = k(x + 2y) `
|
||||
|
||||
The original equation becomes:
|
||||
|
||||
$$ k(4x + 3y) = k(3x + y) + k(x + 2y) $$
|
||||
` k(4x + 3y) = k(3x + y) + k(x + 2y) `
|
||||
|
||||
$$ 4kx + 3ky = 3kx + ky + kx + 2ky $$
|
||||
` 4kx + 3ky = 3kx + ky + kx + 2ky `
|
||||
|
||||
$$ 4kx + 3ky = 4kx + 3ky $$
|
||||
` 4kx + 3ky = 4kx + 3ky `
|
||||
|
||||
This equation holds true for all $ x $ and $ y $, confirming that $ f(x) = kx $ is a solution.
|
||||
|
||||
**Conclusion**
|
||||
|
||||
The only functions $ f: \mathbb{Z} \to \mathbb{Z} $ that satisfy the given functional equation are of the form $ f(x) = kx $ for some integer $ k $.
|
||||
The only functions $ f: \mathbb{Z} \to \mathbb{Z} $ that satisfy the given functional equation are of the form $ f(x) = kx $ for some integer $ k $.
|
||||
|
||||
Thus, the final answer is:
|
||||
|
||||
$$ \boxed{f(x) = kx \text{ for some integer } k} $$
|
||||
` \boxed\{f(x) = kx \text\{ for some integer \} k\} `
|
||||
|
||||
Problem From Baltic Way 2023
|
||||
|
||||
**Problem**
|
||||
|
||||
Find all functions $f: \mathbb{R} \rightarrow \mathbb{R}$ such that
|
||||
Find all functions $f: \mathbb{R} \rightarrow \mathbb{R}$ such that
|
||||
|
||||
` f(f(x)+y)+xf(y)=f(xy+y)+f(x) `
|
||||
```
|
||||
|
||||
$$ f(f(x)+y)+xf(y)=f(xy+y)+f(x) $$
|
||||
[code]
|
||||
for reals $x, y$.
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
**zen-Math-72B-Instruct Solution:**
|
||||
|
||||
To find all functions $ f: \mathbb{R} \rightarrow \mathbb{R} $ that satisfy the functional equation
|
||||
To find all functions $ f: \mathbb{R} \rightarrow \mathbb{R} $ that satisfy the functional equation
|
||||
|
||||
$$ f(f(x) + y) + x f(y) = f(xy + y) + f(x), $$
|
||||
` f(f(x) + y) + x f(y) = f(xy + y) + f(x), `
|
||||
|
||||
we will proceed step by step.
|
||||
|
||||
@@ -369,73 +350,73 @@ we will proceed step by step.
|
||||
|
||||
First, let’s substitute $ y = 0 $ into the equation:
|
||||
|
||||
$$ f(f(x) + 0) + x f(0) = f(x \cdot 0 + 0) + f(x). $$
|
||||
` f(f(x) + 0) + x f(0) = f(x \cdot 0 + 0) + f(x). `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ f(f(x)) + x f(0) = f(0) + f(x). $$
|
||||
` f(f(x)) + x f(0) = f(0) + f(x). `
|
||||
|
||||
Rearranging terms, we get:
|
||||
|
||||
$$ f(f(x)) = f(x) + f(0) - x f(0). $$
|
||||
` f(f(x)) = f(x) + f(0) - x f(0). `
|
||||
|
||||
**Step 2: Analyzing the Simplified Equation**
|
||||
|
||||
Let $ c = f(0) $. The equation becomes:
|
||||
|
||||
$$ f(f(x)) = f(x) + c - x c. $$
|
||||
` f(f(x)) = f(x) + c - x c. `
|
||||
|
||||
**Step 3: Substituting $ x = 0 $**
|
||||
|
||||
Next, substitute $ x = 0 $ into the original equation:
|
||||
|
||||
$$ f(f(0) + y) + 0 \cdot f(y) = f(0 \cdot y + y) + f(0). $$
|
||||
` f(f(0) + y) + 0 \cdot f(y) = f(0 \cdot y + y) + f(0). `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ f(c + y) = f(y) + c. $$
|
||||
` f(c + y) = f(y) + c. `
|
||||
|
||||
**Step 4: Substituting $ y = -c $**
|
||||
|
||||
Substitute $ y = -c $ into the equation $ f(c + y) = f(y) + c $:
|
||||
|
||||
$$ f(c - c) = f(-c) + c. $$
|
||||
` f(c - c) = f(-c) + c. `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ f(0) = f(-c) + c. $$
|
||||
` f(0) = f(-c) + c. `
|
||||
|
||||
Since $ f(0) = c $, we have:
|
||||
|
||||
$$ c = f(-c) + c. $$
|
||||
` c = f(-c) + c. `
|
||||
|
||||
Subtracting $ c $ from both sides, we get:
|
||||
|
||||
$$ f(-c) = 0. $$
|
||||
` f(-c) = 0. `
|
||||
|
||||
**Step 5: Substituting $ y = -f(x) $**
|
||||
|
||||
Substitute $ y = -f(x) $ into the original equation:
|
||||
|
||||
$$ f(f(x) - f(x)) + x f(-f(x)) = f(x(-f(x)) - f(x)) + f(x). $$
|
||||
` f(f(x) - f(x)) + x f(-f(x)) = f(x(-f(x)) - f(x)) + f(x). `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ f(0) + x f(-f(x)) = f(-x f(x) - f(x)) + f(x). $$
|
||||
` f(0) + x f(-f(x)) = f(-x f(x) - f(x)) + f(x). `
|
||||
|
||||
Since $ f(0) = c $, we have:
|
||||
|
||||
$$ c + x f(-f(x)) = f(-x f(x) - f(x)) + f(x). $$
|
||||
` c + x f(-f(x)) = f(-x f(x) - f(x)) + f(x). `
|
||||
|
||||
**Step 6: Considering $ f(x) = 0 $**
|
||||
|
||||
Assume $ f(x) = 0 $ for all $ x $. Substitute $ f(x) = 0 $ into the original equation:
|
||||
|
||||
$$ f(0 + y) + x f(y) = f(xy + y) + f(x). $$
|
||||
` f(0 + y) + x f(y) = f(xy + y) + f(x). `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ f(y) + 0 = f(y) + 0, $$
|
||||
` f(y) + 0 = f(y) + 0, `
|
||||
|
||||
which is always true.
|
||||
|
||||
@@ -443,11 +424,11 @@ which is always true.
|
||||
|
||||
Assume $ f(x) = x $. Substitute $ f(x) = x $ into the original equation:
|
||||
|
||||
$$ f(x + y) + x f(y) = f(xy + y) + f(x). $$
|
||||
` f(x + y) + x f(y) = f(xy + y) + f(x). `
|
||||
|
||||
This simplifies to:
|
||||
|
||||
$$ x + y + xy = xy + y + x, $$
|
||||
` x + y + xy = xy + y + x, `
|
||||
|
||||
which is always true.
|
||||
|
||||
@@ -455,7 +436,7 @@ which is always true.
|
||||
|
||||
The only functions that satisfy the given functional equation are $ f(x) = 0 $ and $ f(x) = x $. Therefore, the solutions are:
|
||||
|
||||
$$ \boxed{f(x) = 0 \text{ or } f(x) = x}. $$
|
||||
` \boxed\{f(x) = 0 \text\{ or \} f(x) = x\}. `
|
||||
|
||||
Problem From Lusophon Mathematical Olympiad 2023
|
||||
|
||||
@@ -481,16 +462,12 @@ First, let’s consider the parity (odd or even nature) of the number of Martian
|
||||
* 2 green (even)
|
||||
* 2 blue (even)
|
||||
|
||||
|
||||
|
||||
Each transformation changes the parity of the number of Martians of the two initial colors and the parity of the number of Martians of the third color. Specifically:
|
||||
|
||||
* If we transform 1 red and 1 green Martian, we get 4 blue Martians. This changes the parity of red and green Martians from even to odd, and the parity of blue Martians from even to odd.
|
||||
* If we transform 1 red and 1 blue Martian, we get 4 green Martians. This changes the parity of red and blue Martians from even to odd, and the parity of green Martians from even to odd.
|
||||
* If we transform 1 green and 1 blue Martian, we get 4 red Martians. This changes the parity of green and blue Martians from even to odd, and the parity of red Martians from even to odd.
|
||||
|
||||
|
||||
|
||||
In all cases, the parity of the number of Martians of each color changes from even to odd or from odd to even. Therefore, after any number of transformations, the parity of the number of Martians of each color will always be the same as it was initially.
|
||||
|
||||
Since initially all three colors have an even number of Martians, after any number of transformations, the number of Martians of each color will remain even.
|
||||
@@ -499,7 +476,7 @@ Given that 2022 is an even number, it is possible to have 2022 red, 2022 green,
|
||||
|
||||
Thus, the answer to part (a) is:
|
||||
|
||||
$$ \boxed{\text{Yes}} $$
|
||||
` \boxed\{\text\{Yes\}\} `
|
||||
|
||||
**Part (b)**
|
||||
|
||||
@@ -511,8 +488,6 @@ As in part (a), we consider the parity of the number of Martians of each color.
|
||||
* 2 green (even)
|
||||
* 2 blue (even)
|
||||
|
||||
|
||||
|
||||
Each transformation changes the parity of the number of Martians of the two initial colors and the parity of the number of Martians of the third color. Therefore, after any number of transformations, the parity of the number of Martians of each color will always be the same as it was initially.
|
||||
|
||||
Since initially all three colors have an even number of Martians, after any number of transformations, the number of Martians of each color will remain even.
|
||||
@@ -521,7 +496,7 @@ Given that 2021 is an odd number, it is impossible to have 2021 red Martians aft
|
||||
|
||||
Thus, the answer to part (b) is:
|
||||
|
||||
$$ \boxed{\text{No}} $$
|
||||
` \boxed\{\text\{No\}\} `
|
||||
|
||||
Problem From Balkan MO 2023
|
||||
|
||||
@@ -557,11 +532,9 @@ To determine the winner of the game, we need to analyze the strategy and the seq
|
||||
* Since Penny makes the last move, she will be the one to remove the last stone.
|
||||
* Hence, Penny wins the game if both players play perfectly.
|
||||
|
||||
|
||||
|
||||
Thus, the final answer is:
|
||||
|
||||
$$ \boxed{\text{Penny}} $$
|
||||
` \boxed\{\text\{Penny\}\} `
|
||||
|
||||
Problem From Math Odyssey
|
||||
|
||||
@@ -573,7 +546,7 @@ The school offers 10 elective courses, and each student can enroll in any number
|
||||
|
||||
To solve this problem, we need to determine the maximum number of students $ k $ such that each student has a unique combination of elective courses, any two students share at least one course, and no student outside these $ k $ students can be classmates with all of them. This means that the set of students chosen must cover all possible courses in such a way that any new student would have to share a course with at least one of the chosen students.
|
||||
|
||||
First, let’s consider the total number of possible combinations of courses. Since there are 10 elective courses and each student can either take or not take each course, there are $ 2^{10} = 1024 $ possible combinations of courses. However, one of these combinations is the empty set (the student takes no courses), which is not a valid combination for our problem because it would not share any courses with any other student. Therefore, there are $ 1024 - 1 = 1023 $ non-empty combinations of courses.
|
||||
|
||||
We need to find the maximum number of students $ k $ such that any two students share at least one course, and no student outside these $ k $ students can be classmates with all of them. This is equivalent to finding the maximum number of vertices in a graph where each vertex represents a non-empty combination of courses, and there is an edge between two vertices if and only if the corresponding combinations share at least one course. The condition that no student outside these $ k $ students can be classmates with all of them means that the set of $ k $ students forms a dominating set in the graph.
|
||||
|
||||
@@ -581,13 +554,13 @@ The maximum size of such a set is the complement of the minimum size of an indep
|
||||
|
||||
Therefore, the minimum size of an independent set is 512, and the maximum size of a dominating set (which is the complement of the independent set) is $ 1023 - 512 + 1 = 511 $. However, we need to add 1 because the empty set is not included, so the correct calculation is $ 1023 - 511 = 512 $.
|
||||
|
||||
Thus, the maximum number of students $ k $ is $\boxed{512}$.
|
||||
Thus, the maximum number of students $ k $ is $\boxed{512}$.
|
||||
|
||||
Problem from USAMO 2010
|
||||
|
||||
**Problem**
|
||||
|
||||
Let $ABC$ be a triangle with $\angle A = 90^{\circ}$. Points $D$ and $E$ lie on sides $AC$ and $AB$, respectively, such that $\angle ABD = \angle DBC$ and $\angle ACE = \angle ECB$. Segments $BD$ and $CE$ meet at $I$. Determine whether or not it is possible for segments $AB$, $AC$, $BI$, $ID$, $CI$, $IE$ to all have integer lengths.
|
||||
|
||||
**zen-Math-72B-Instruct Solution**
|
||||
|
||||
@@ -600,64 +573,56 @@ Given:
|
||||
* $\angle ACE = \angle ECB$
|
||||
* Segments $BD$ and $CE$ intersect at $I$
|
||||
|
||||
|
||||
|
||||
First, note that since $\angle A = 90^\circ$, triangle $ABC$ is a right triangle with $A$ as the right angle. Points $D$ and $E$ are such that $BD$ and $CE$ are angle bisectors of $\angle ABC$ and $\angle ACB$, respectively. Therefore, $I$ is the incenter of triangle $ABC$.
|
||||
|
||||
**Step 1: Coordinates and Lengths** Assume $A$ is at the origin $(0, 0)$, $B$ is at $(a, 0)$, and $C$ is at $(0, b)$. The lengths of the sides are:
|
||||
|
||||
* $AB = a$
|
||||
* $AC = b$
|
||||
* $BC = \sqrt{a^2 + b^2}$
|
||||
* $BC = \sqrt{a^2 + b^2}$
|
||||
|
||||
**Step 2: Incenter Coordinates** The incenter $I$ of a right triangle with legs $a$ and $b$ and hypotenuse $\sqrt{a^2 + b^2}$ is located at:
|
||||
|
||||
|
||||
**Step 2: Incenter Coordinates** The incenter $I$ of a right triangle with legs $a$ and $b$ and hypotenuse $\sqrt{a^2 + b^2}$ is located at:
|
||||
|
||||
$$ I = \left( \frac{a}{2}, \frac{b}{2} \right) $$
|
||||
` I = \left( \frac\{a\}\{2\}, \frac\{b\}\{2\} \right) `
|
||||
|
||||
**Step 3: Lengths of Segments $BI$ and $CI$** Using the distance formula, we calculate $BI$ and $CI$:
|
||||
|
||||
$$ BI = \sqrt{\left( a - \frac{a}{2} \right)^2 + \left( 0 - \frac{b}{2} \right)^2} = \sqrt{\left( \frac{a}{2} \right)^2 + \left( \frac{b}{2} \right)^2} = \frac{\sqrt{a^2 + b^2}}{2} $$
|
||||
` BI = \sqrt\{\left( a - \frac\{a\}\{2\} \right)^2 + \left( 0 - \frac\{b\}\{2\} \right)^2\} = \sqrt\{\left( \frac\{a\}\{2\} \right)^2 + \left( \frac\{b\}\{2\} \right)^2\} = \frac\{\sqrt\{a^2 + b^2\}\}\{2\} `
|
||||
|
||||
$$ CI = \sqrt{\left( 0 - \frac{a}{2} \right)^2 + \left( b - \frac{b}{2} \right)^2} = \sqrt{\left( \frac{a}{2} \right)^2 + \left( \frac{b}{2} \right)^2} = \frac{\sqrt{a^2 + b^2}}{2} $$
|
||||
` CI = \sqrt\{\left( 0 - \frac\{a\}\{2\} \right)^2 + \left( b - \frac\{b\}\{2\} \right)^2\} = \sqrt\{\left( \frac\{a\}\{2\} \right)^2 + \left( \frac\{b\}\{2\} \right)^2\} = \frac\{\sqrt\{a^2 + b^2\}\}\{2\} `
|
||||
|
||||
**Step 4: Lengths of Segments $ID$ and $IE$** Since $D$ and $E$ are points on $AC$ and $AB$ respectively, and $I$ is the incenter, $ID$ and $IE$ are the distances from the incenter to the sides of the triangle. For a right triangle, these distances are given by:
|
||||
|
||||
$$ ID = IE = r = \frac{a + b - \sqrt{a^2 + b^2}}{2} $$
|
||||
` ID = IE = r = \frac\{a + b - \sqrt\{a^2 + b^2\}\}\{2\} `
|
||||
|
||||
**Step 5: Integer Lengths** For $AB$, $AC$, $BI$, $ID$, $CI$, and $IE$ to all be integers, the following must hold:
|
||||
|
||||
* $a$ and $b$ are integers
|
||||
* $\frac{\sqrt{a^2 + b^2}}{2}$ is an integer
|
||||
* $\frac{a + b - \sqrt{a^2 + b^2}}{2}$ is an integer
|
||||
* $\frac{\sqrt{a^2 + b^2}}{2}$ is an integer
|
||||
* $\frac{a + b - \sqrt{a^2 + b^2}}{2}$ is an integer
|
||||
|
||||
**Step 6: Analysis** For $\frac{\sqrt{a^2 + b^2}}{2}$ to be an integer, $\sqrt{a^2 + b^2}$ must be an even integer. Let $\sqrt{a^2 + b^2} = 2k$ for some integer $k$. Then:
|
||||
|
||||
` a^2 + b^2 = 4k^2 `
|
||||
|
||||
**Step 6: Analysis** For $\frac{\sqrt{a^2 + b^2}}{2}$ to be an integer, $\sqrt{a^2 + b^2}$ must be an even integer. Let $\sqrt{a^2 + b^2} = 2k$ for some integer $k$. Then:
|
||||
|
||||
$$ a^2 + b^2 = 4k^2 $$
|
||||
|
||||
For $\frac{a + b - \sqrt{a^2 + b^2}}{2}$ to be an integer, $a + b - 2k$ must be even. Since $a$ and $b$ are integers, $a + b$ must be even.
|
||||
For $\frac{a + b - \sqrt{a^2 + b^2}}{2}$ to be an integer, $a + b - 2k$ must be even. Since $a$ and $b$ are integers, $a + b$ must be even.
|
||||
|
||||
**Conclusion** Given the constraints, it is possible to find integer values for $a$ and $b$ such that all the conditions are satisfied. For example, if $a = 3$ and $b = 4$, then:
|
||||
|
||||
* $AB = 3$
|
||||
* $AC = 4$
|
||||
* $BC = 5$
|
||||
* $BI = CI = \frac{5}{2} = 2.5$ (not an integer)
|
||||
|
||||
|
||||
* $BI = CI = \frac{5}{2} = 2.5$ (not an integer)
|
||||
|
||||
Thus, it is not possible for all segments $AB$, $AC$, $BI$, $ID$, $CI$, and $IE$ to have integer lengths simultaneously.
|
||||
|
||||
$$ \boxed{\text{No}} $$
|
||||
` \boxed\{\text\{No\}\} `
|
||||
|
||||
Problem from JBMO Shortlist 2011
|
||||
|
||||
**Problem**
|
||||
|
||||
Let $AD,BF$ and ${CE}$ be the altitudes of $\vartriangle ABC$. A line passing through ${D}$ and parallel to ${AB}$intersects the line ${EF}$at the point ${G}$. If ${H}$ is the orthocenter of $\vartriangle ABC$, find the angle ${\angle{CGH}}$.
|
||||
Let $AD,BF$ and ${CE}$ be the altitudes of $\vartriangle ABC$. A line passing through ${D}$ and parallel to ${AB}$intersects the line ${EF}$at the point ${G}$. If ${H}$ is the orthocenter of $\vartriangle ABC$, find the angle ${\angle{CGH}}$.
|
||||
|
||||
**zen-Math-72B-Instruct Solution**
|
||||
|
||||
@@ -694,11 +659,9 @@ To solve for the angle $\angle CGH$ in the given triangle $\triangle ABC$ with a
|
||||
* Therefore, $\angle DGE = \angle EAF$.
|
||||
8. **Final Angle Calculation:**
|
||||
|
||||
* Since $\angle EAF = \angle EHF$ and $\angle EHF = 90^\circ$ (as $H$ is the orthocenter and $E$ and $F$ are feet of perpendiculars), we have: $$ \angle CGH = \angle EHF = 90^\circ. $$
|
||||
* Since $\angle EAF = \angle EHF$ and $\angle EHF = 90^\circ$ (as $H$ is the orthocenter and $E$ and $F$ are feet of perpendiculars), we have: ` \angle CGH = \angle EHF = 90^\circ. `
|
||||
|
||||
|
||||
|
||||
Thus, the angle $\angle CGH$ is $\boxed{90^\circ}$.
|
||||
Thus, the angle $\angle CGH$ is $\boxed{90^\circ}$.
|
||||
|
||||
## Decontamination
|
||||
|
||||
|
||||
@@ -8,8 +8,6 @@ date: "2024-08-29"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[DEMO](https://huggingface.co/spaces/Qwen/zen-VL) [GITHUB](https://github.com/QwenLM/zen-VL) [HUGGING FACE](https://huggingface.co/collections/Qwen/qwen2-vl-66cee7455501d7126940800d) [MODELSCOPE](https://modelscope.cn/organization/qwen) [API](https://help.aliyun.com/zh/model-studio/developer-reference/qwen-vl-api) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
After a year’s relentless efforts, today we are thrilled to release **zen-VL**! zen-VL is the latest version of the vision language models based on **zen** in the Qwen model familities. Compared with Qwen-VL, zen-VL has the capabilities of:
|
||||
@@ -23,26 +21,16 @@ After a year’s relentless efforts, today we are thrilled to release **zen-VL**
|
||||
* **Multilingual Support** : to serve global users, besides English and Chinese, zen-VL now supports the understanding of texts in different languages inside images, including most European languages, Japanese, Korean, Arabic, Vietnamese, etc.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
We opensource zen-VL-2B and zen-VL-7B with Apache 2.0 license, and we release the API of zen-VL-72B! The opensource is integrated to Hugging Face Transformers, vLLM, and other third-party frameworks. Hope you enjoy!
|
||||
|
||||
## Performance
|
||||
|
||||
We evaluate our model’s visual capabilities across six key dimensions: complex college-level problem-solving, mathematical abilities, document and table comprehension, multilingual text-image understanding, general scenario question-answering, video comprehension, and agent-based interactions. Overall, our 72B model showcases top-tier performance across most metrics, often surpassing even closed-source models like GPT-4o and Claude 3.5-Sonnet. Notably, it demonstrates a significant edge in document understanding.
|
||||
|
||||

|
||||
|
||||
At the 7B scale, we’ve managed to retain support for image, multi-image, and video inputs, delivering competitive performance in a more cost-effective model size. Specifically, our model excels in document understanding tasks such as DocVQA and in multilingual text understanding from images, as assessed by MTVQA, establishing state-of-the-art performance.
|
||||
|
||||

|
||||
|
||||
Additionally, we’re excited to introduce a smaller 2B model, optimized for potential mobile deployment. Despite its compact size, this model boasts strong performance in image, video, and multilingual comprehension. It particularly shines in video-related tasks, document understanding, and general scenario question-answering when compared to other models of similar scale.
|
||||
|
||||

|
||||
|
||||
## Model Capabilities
|
||||
|
||||
### 1\. Enhanced Recognition Capabilities
|
||||
@@ -53,7 +41,7 @@ Example: Multi-object Recognition Next
|
||||
|
||||
User
|
||||
|
||||
Output the color and number of each box. 
|
||||
Output the color and number of each box.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -64,13 +52,11 @@ The image shows a stack of colorful blocks with numbers on them. Here is the col
|
||||
* Third row (three blocks): Purple with the number 4, pink with the number 5, and light green with the number 6
|
||||
* Bottom row (four blocks): Red with the number 0, orange with the number 1, yellow with the number 2, and light green with the number 3
|
||||
|
||||
|
||||
|
||||
Example: Plant identification Next
|
||||
|
||||
User
|
||||
|
||||
What kind of flower is this? 
|
||||
What kind of flower is this?
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -80,34 +66,29 @@ Example: Document Parsing with Dense Formulas Next
|
||||
|
||||
User
|
||||
|
||||
Convert the content in the image to Markdown 
|
||||
Convert the content in the image to Markdown
|
||||
|
||||
zen-VL
|
||||
|
||||
1. If $i > 0$, let $\underline{d}’’ := (i-1, d-i-l+1, l)$. Let $V_{\underline{d}}$ and $V_{\underline{d}’’}$ be $r+1$-dimensional subspaces of $H^0(\mathcal{L}_{\underline{d}})$ and $H^0(\mathcal{L}_{\underline{d}’’})$, respectively, such that $\varphi_{\underline{d}, \underline{d}’’}(V_{\underline{d}}) = V_{\underline{d}’’}^{X_1, 0}$. Then the distributivity holds in $V_{\underline{d}’’}$ if and only if $$ \dim (V_{\underline{d}}^{X_2, 0} + V_{\underline{d}}^{X_3, 0}) - \dim (V_{\underline{d}’’}^{X_2, 0} + V_{\underline{d}’’}^{X_3, 0}) = r + 1 - \dim (V_{\underline{d}’’}^{X_1, 0} + V_{\underline{d}’’}^{X_2, 0} + V_{\underline{d}’’}^{X_3, 0}) $$
|
||||
1. If $i > 0$, let $\underline{d}’’ := (i-1, d-i-l+1, l)$. Let $V_{\underline{d}}$ and $V_{\underline{d}’’}$ be $r+1$-dimensional subspaces of $H^0(\mathcal{L}_{\underline{d}})$ and $H^0(\mathcal{L}_{\underline{d}’’})$, respectively, such that $\varphi_{\underline{d}, \underline{d}’’}(V_{\underline{d}}) = V_{\underline{d}’’}^{X_1, 0}$. Then the distributivity holds in $V_{\underline{d}’’}$ if and only if ` \dim (V_\{\underline\{d\}\}^\{X_2, 0\} + V_\{\underline\{d\}\}^\{X_3, 0\}) - \dim (V_\{\underline\{d\}’’\}^\{X_2, 0\} + V_\{\underline\{d\}’’\}^\{X_3, 0\}) = r + 1 - \dim (V_\{\underline\{d\}’’\}^\{X_1, 0\} + V_\{\underline\{d\}’’\}^\{X_2, 0\} + V_\{\underline\{d\}’’\}^\{X_3, 0\}) `
|
||||
|
||||
2. If $i + l \leq d - 1$, let $\underline{d}’’’ := (i, d-i-l-1, l+1)$. Let $V_{\underline{d}}$ and $V_{\underline{d}’’’}$ be $r+1$-dimensional subspaces of $H^0(\mathcal{L}_{\underline{d}})$ and $H^0(\mathcal{L}_{\underline{d}’’’})$, respectively, such that $\varphi_{\underline{d}’’’, \underline{d}}(V_{\underline{d}’’’}) = V_{\underline{d}}^{X_3, 0}$. Then the distributivity holds in $V_{\underline{d}}$ if and only if $$ \dim (V_{\underline{d}’’’}^{X_1, 0} + V_{\underline{d}’’’}^{X_2, 0}) - \dim (V_{\underline{d}}^{X_1, 0} + V_{\underline{d}}^{X_2, 0}) = r + 1 - \dim (V_{\underline{d}}^{X_1, 0} + V_{\underline{d}}^{X_2, 0} + V_{\underline{d}}^{X_3, 0}), $$ where the maps $\varphi_{\underline{d}, \underline{d}’’}$ and $\varphi_{\underline{d}’’’, \underline{d}}$ in Proposition 3.14 are the maps linking the corresponding sheaves. Another important result is Proposition 3.16, which establishes an inequality for any exact limit linear series. Specifically, our Proposition 3.16 says:
|
||||
2. If $i + l \leq d - 1$, let $\underline{d}’’’ := (i, d-i-l-1, l+1)$. Let $V_{\underline{d}}$ and $V_{\underline{d}’’’}$ be $r+1$-dimensional subspaces of $H^0(\mathcal{L}_{\underline{d}})$ and $H^0(\mathcal{L}_{\underline{d}’’’})$, respectively, such that $\varphi_{\underline{d}’’’, \underline{d}}(V_{\underline{d}’’’}) = V_{\underline{d}}^{X_3, 0}$. Then the distributivity holds in $V_{\underline{d}}$ if and only if ` \dim (V_\{\underline\{d\}’’’\}^\{X_1, 0\} + V_\{\underline\{d\}’’’\}^\{X_2, 0\}) - \dim (V_\{\underline\{d\}\}^\{X_1, 0\} + V_\{\underline\{d\}\}^\{X_2, 0\}) = r + 1 - \dim (V_\{\underline\{d\}\}^\{X_1, 0\} + V_\{\underline\{d\}\}^\{X_2, 0\} + V_\{\underline\{d\}\}^\{X_3, 0\}), ` where the maps $\varphi_{\underline{d}, \underline{d}’’}$ and $\varphi_{\underline{d}’’’, \underline{d}}$ in Proposition 3.14 are the maps linking the corresponding sheaves. Another important result is Proposition 3.16, which establishes an inequality for any exact limit linear series. Specifically, our Proposition 3.16 says:
|
||||
|
||||
|
||||
|
||||
|
||||
Let ${(\mathcal{L}_{\underline{d}}, V_{\underline{d}})}_{\underline{d}}$ be an exact limit linear series of degree $d$ and dimension $r$. Then $$ \sum_{\underline{d}} \dim \left( \frac{V_{\underline{d}}}{V_{\underline{d}}^{X_1, 0} + V_{\underline{d}}^{X_2, 0} + V_{\underline{d}}^{X_3, 0}} \right) \geq r + 1. $$
|
||||
Let ${(\mathcal{L}_{\underline{d}}, V_{\underline{d}})}_{\underline{d}}$ be an exact limit linear series of degree $d$ and dimension $r$. Then ` \sum_\{\underline\{d\}\} \dim \left( \frac\{V_\{\underline\{d\}\}\}\{V_\{\underline\{d\}\}^\{X_1, 0\} + V_\{\underline\{d\}\}^\{X_2, 0\} + V_\{\underline\{d\}\}^\{X_3, 0\}\} \right) \geq r + 1. `
|
||||
|
||||
As a consequence of Proposition 3.14 and Proposition 3.16, in Corollary 3.17, we get the following characterization of exact limit linear series satisfying the distributivity at each multidegree:
|
||||
|
||||
Let ${(\mathcal{L}_{\underline{d}}, V_{\underline{d}})}_{\underline{d}}$ be an exact limit linear series of degree $d$ and dimension $r$. Then $$ \sum_{\underline{d}} \dim \left( \frac{V_{\underline{d}}}{V_{\underline{d}}^{X_1, 0} + V_{\underline{d}}^{X_2, 0} + V_{\underline{d}}^{X_3, 0}} \right) = r + 1 $$ if and only if the distributivity holds in $V_{\underline{d}}$ for any $\underline{d}$.
|
||||
Let ${(\mathcal{L}_{\underline{d}}, V_{\underline{d}})}_{\underline{d}}$ be an exact limit linear series of degree $d$ and dimension $r$. Then ` \sum_\{\underline\{d\}\} \dim \left( \frac\{V_\{\underline\{d\}\}\}\{V_\{\underline\{d\}\}^\{X_1, 0\} + V_\{\underline\{d\}\}^\{X_2, 0\} + V_\{\underline\{d\}\}^\{X_3, 0\}\} \right) = r + 1 ` if and only if the distributivity holds in $V_{\underline{d}}$ for any $\underline{d}$.
|
||||
|
||||
In Section 3, we also study simple limit linear series. In Proposition 3.18, we characterize the multidegrees which determine all simple bases. In Proposition 3.20, following the construction in Muñoz [5], Proposition 4.4, we present a certain structure of linearly independent sections for any exact limit linear series satisfying the distributivity property. In propositions 3.21 and 3.22, we obtain some properties of that structure. These properties imply the existence of a simple basis (we give a proof of that in Proposition 3.23).
|
||||
|
||||
We conclude Section 3 with a characterization of simple limit linear series among the exact limit linear series. Specifically, our Corollary 3.24 says:
|
||||
|
||||
Let ${(\mathcal{L}_{\underline{d}}, V_{\underline{d}})}_{\underline{d}}$ be an exact limit linear series of degree $d$ and dimension $r$. Then the following statements are equivalent:
|
||||
|
||||
1. ${(\mathcal{L}_{\underline{d}}, V_{\underline{d}})}_{\underline{d}}$ is simple.
|
||||
2. $\sum_{\underline{d}} \dim \left( \frac{V_{\underline{d}}}{V_{\underline{d}}^{X_1, 0} + V_{\underline{d}}^{X_2, 0} + V_{\underline{d}}^{X_3, 0}} \right) = r + 1$.
|
||||
3. The distributivity holds in $V_{\underline{d}}$ for any $\underline{d}$.
|
||||
|
||||
In a subsequent work, given a refined limit linear series, we will construct all simple extensions by combining our Proposition 3.14 and the method of Muñoz [6] for the construction of all exact extensions.
|
||||
|
||||
@@ -115,7 +96,7 @@ Example: Multilingual Text Recognition Next
|
||||
|
||||
User
|
||||
|
||||
转录图中内容,并识别图中每段内容的语言。 
|
||||
转录图中内容,并识别图中每段内容的语言。
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -168,13 +149,11 @@ zen-VL
|
||||
|
||||
* 语言:斯瓦希里语
|
||||
|
||||
|
||||
|
||||
Example: Handwritten Text Recognition Next
|
||||
|
||||
User
|
||||
|
||||
What is the text? 
|
||||
What is the text?
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -184,7 +163,7 @@ Example: Handwritten Text Recognition Next
|
||||
|
||||
User
|
||||
|
||||
识别图中所有文字,无需添加标点。 
|
||||
识别图中所有文字,无需添加标点。
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -214,7 +193,7 @@ Example: Code Next
|
||||
|
||||
User
|
||||
|
||||
Solve the algorithmic problem in the web page. 
|
||||
Solve the algorithmic problem in the web page.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -236,10 +215,9 @@ To solve the “Snake in Matrix” problem, we need to implement a function that
|
||||
|
||||
* After processing all commands, return the final position of the snake.
|
||||
|
||||
|
||||
|
||||
Here’s the Python code to implement the solution:
|
||||
[code]
|
||||
```python
|
||||
|
||||
class Solution:
|
||||
def finalPositionOfSnake(self, n: int, commands: List[str]) -> int:
|
||||
# Initialize variables
|
||||
@@ -277,7 +255,8 @@ Here’s the Python code to implement the solution:
|
||||
# Return final position
|
||||
return position
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
This code defines a class `Solution` with a method `finalPositionOfSnake` that takes the size of the matrix `n` and a list of commands, and returns the final position of the snake after executing all the commands. The movement functions (`move_right`, `move_down`, `move_left`, `move_up`) are used to update the position of the snake based on the current direction.
|
||||
|
||||
@@ -285,7 +264,7 @@ Example: Math Next
|
||||
|
||||
User
|
||||
|
||||
Find the length of AC in the isosceles triangle ABC. 
|
||||
Find the length of AC in the isosceles triangle ABC.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -317,7 +296,7 @@ Example: Information Extraction of High Resolution Images Next
|
||||
|
||||
User
|
||||
|
||||
Extract all page titles in the screenshot of search result. 
|
||||
Extract all page titles in the screenshot of search result.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -334,13 +313,11 @@ The page titles in the screenshot of the search result are:
|
||||
9. [2407.10671] zen Technical Report
|
||||
10. qwen2
|
||||
|
||||
|
||||
|
||||
Example: Math Next
|
||||
|
||||
User
|
||||
|
||||
Please tell me how many days are between Ruka’s birthday and Yuki’s birthday? Think carefully step by step. 
|
||||
Please tell me how many days are between Ruka’s birthday and Yuki’s birthday? Think carefully step by step.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -349,8 +326,6 @@ To determine the number of days between Ruka’s and Yuki’s birthdays, we need
|
||||
1. Ruka’s birthday is on June 24.
|
||||
2. Yuki’s birthday is on September 17.
|
||||
|
||||
|
||||
|
||||
Let’s break it down step by step:
|
||||
|
||||
1. **From June 24 to June 30:**
|
||||
@@ -365,16 +340,12 @@ Let’s break it down step by step:
|
||||
|
||||
* September 1 to September 17 is 17 days.
|
||||
|
||||
|
||||
|
||||
Now, we add all these days together:
|
||||
|
||||
* June 24 to June 30: 6 days
|
||||
* July 1 to August 31: 62 days
|
||||
* September 1 to September 17: 17 days
|
||||
|
||||
|
||||
|
||||
Total days = 6 + 62 + 17 = 85 days
|
||||
|
||||
Therefore, there are 85 days between Ruka’s and Yuki’s birthdays.
|
||||
@@ -383,10 +354,11 @@ Example: Information Extraction Next
|
||||
|
||||
User
|
||||
|
||||
What are the Linux versions and their release dates in the picture? Return results as a JSON list. 
|
||||
What are the Linux versions and their release dates in the picture? Return results as a JSON list.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{
|
||||
"version": "6.11-rc3",
|
||||
@@ -430,13 +402,14 @@ zen-VL
|
||||
}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Information Extraction and Organization Next
|
||||
|
||||
User
|
||||
|
||||
将图中的每日的最高气温和最低气温整理成表格。 
|
||||
将图中的每日的最高气温和最低气温整理成表格。
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -459,7 +432,7 @@ Example: Information Extraction of High Resolution Images with Extreme Aspect Ra
|
||||
|
||||
User
|
||||
|
||||
qwen-vl-max-0809对视频内容的理解功能存在哪些限制? 
|
||||
qwen-vl-max-0809对视频内容的理解功能存在哪些限制?
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -535,8 +508,6 @@ zen-VL demonstrates strong potential as a visual agent, facilitating interaction
|
||||
|
||||
* The model facilitates Function Calling, enabling it to harness external tools for real-time data retrieval – be it flight statuses, weather forecasts, or package tracking – by deciphering visual cues. This integration of visual interpretation with functional execution elevates its utility, making it a powerful tool for information management and decision-making.
|
||||
|
||||
|
||||
|
||||
Example: Function Calling Next
|
||||
|
||||
Ask about the weather
|
||||
@@ -555,8 +526,6 @@ Implement the formula in code
|
||||
|
||||
* Visual Interactions represent a significant stride towards mimicking human perception. By allowing the model to engage with visual stimuli akin to human senses, we’re pushing the boundaries of AI’s ability to perceive and respond to its environment. This capability paves the way for more intuitive and immersive interactions, where zen-VL acts not just as an observer, but an active participant in our visual experiences.
|
||||
|
||||
|
||||
|
||||
Example: UI Interactions Next
|
||||
|
||||
Operate a Mobile Phone
|
||||
@@ -581,16 +550,13 @@ Overall, we’ve continued with the Qwen-VL architecture, which leverages a Visi
|
||||
|
||||
* A key architectural improvement in zen-VL is the implementation of **Naive Dynamic Resolution support**. Unlike its predecessor, zen-VL can handle arbitrary image resolutions, mapping them into a dynamic number of visual tokens, thereby ensuring consistency between the model input and the inherent information in images. This approach more closely mimics human visual perception, allowing the model to process images of any clarity or size.
|
||||
|
||||

|
||||
|
||||
* Another key architectural enhancement is the innovation of **Multimodal Rotary Position Embedding (M-ROPE)**. By deconstructing the original rotary embedding into three parts representing temporal and spatial (height and width) information,M-ROPE enables LLM to concurrently capture and integrate 1D textual, 2D visual, and 3D video positional information.
|
||||
|
||||

|
||||
|
||||
## Developing with zen-VL
|
||||
|
||||
To use the largest zen-VL model, zen-VL-72B, you can access it through our official API (sign up the account and obtain the API key through [DashScope](https://dashscope.aliyun.com/)) temporarily as demonstrated below:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from openai import OpenAI
|
||||
import os
|
||||
import base64
|
||||
@@ -644,24 +610,30 @@ To use the largest zen-VL model, zen-VL-72B, you can access it through our offic
|
||||
if __name__ == "__main__":
|
||||
get_response()
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The 2B and 7B models of the zen-VL series are open-sourced and accessible on Hugging Face and ModelScope. You can explore the model cards for detailed usage instructions, features, and performance metrics. Below we provide an example of the simplest usage with HF Transformers.
|
||||
|
||||
Make sure you install `transformers` from source by `pip install git+https://github.com/huggingface/transformers` as codes for zen-VL were just merged into the main branch. If you didn’t install it from source, you may encounter the following error:
|
||||
[code]
|
||||
```
|
||||
|
||||
KeyError: 'qwen2_vl'
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
We offer a toolkit to help you handle various types of visual input more conveniently. It supports inputs including base64, URLs, and interleaved images and videos. You can install it using the following command:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
pip install qwen-vl-utils
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Here is a code snippet for demonstration. Specifically, we recommend using flash attention 2 if possible for the sake of acceleration and memory saving.
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import zenVLForConditionalGeneration, AutoTokenizer, AutoProcessor
|
||||
from qwen_vl_utils import process_vision_info
|
||||
|
||||
@@ -722,7 +694,8 @@ Here is a code snippet for demonstration. Specifically, we recommend using flash
|
||||
)
|
||||
print(output_text)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
To facilitate seamless integration and use of our latest models, we support a range of tools and frameworks in the open-source ecosystem, including quantization ([AutoGPTQ](https://github.com/AutoGPTQ/AutoGPTQ), [AutoAWQ](https://github.com/casper-hansen/AutoAWQ)), deployment ([vLLM](https://github.com/vllm-project/vllm)), finetuning ([Llama-Factory](https://github.com/hiyouga/LLaMA-Factory)), etc.
|
||||
|
||||
|
||||
@@ -19,9 +19,6 @@ Two months after upgrading [zen-Turbo](../qwen3-turbo) to support context length
|
||||
|
||||
3. **[Technical Report](https://qianwen-res.oss-cn-beijing.aliyuncs.com/zen-1M/zen_1M_Technical_Report.pdf):** We’re also sharing the technical details behind the zen-1M series, including design insights for training and inference frameworks, as well as ablation experiments.
|
||||
|
||||
|
||||
|
||||
|
||||
You can experience zen-1M models online by visiting our demo on [Huggingface](https://huggingface.co/spaces/Qwen/zen-1M-Demo) and [Modelscope](https://www.modelscope.cn/studios/Qwen/zen-1M-Demo).
|
||||
|
||||
Additionally, we recently introduced **[Qwen Chat](https://chat.qwenlm.ai/)** , an advanced AI assistant from the Qwen series. With Qwen Chat, you can engage in conversations, write code, perform searches, generate images and videos, and utilize various tools. Notably, Qwen Chat also features the zen-Turbo model, which supports long-context processing with a context length of up to 1M tokens.
|
||||
@@ -34,40 +31,28 @@ Let’s start by diving into the performance of the zen-1M series models, coveri
|
||||
|
||||
First off, we evaluate the zen-1M models on the Passkey Retrieval task with a context length of 1 million tokens. The results show that these models can accurately retrieve hidden information from documents containing up to 1M tokens, with only minor errors observed in the 7B model.
|
||||
|
||||

|
||||
|
||||
For more complex long-context understanding tasks, we select [RULER](https://github.com/hsiehjackson/RULER), [LV-Eval](https://github.com/infinigence/LVEval), [LongbenchChat](https://github.com/THUDM/LongAlign) used in [this blog](../qwen3-turbo/#more-complex-long-text-tasks).
|
||||
|
||||

|
||||
|
||||
From these results, we can draw a few key conclusions:
|
||||
|
||||
* **Significantly Superior to the 128k Version:** The zen-1M series models significantly outperform their 128K counterparts in most long-context tasks, especially for sequences exceeding 64K in length.
|
||||
* **Notable Performance Advantage:** The zen-14B-Instruct-1M model not only beats zen-Turbo but also consistently outperforms GPT-4o-mini across multiple datasets, offering a robust open-source alternative for long-context tasks.
|
||||
|
||||
|
||||
|
||||
## Short-Context Tasks
|
||||
|
||||
Besides performance on long sequences, we’re equally interested in how these models handle short sequences. So, we compare the zen-1M models and their 128K versions on widely used academic benchmarks, throwing in GPT-4o-mini for comparison.
|
||||
|
||||

|
||||
|
||||
Here’s what we find:
|
||||
|
||||
* Both zen-7B-Instruct-1M and zen-14B-Instruct-1M maintain performance on short text tasks that is similar to their 128K versions, ensuring the fundamental capabilities haven’t been compromised by the addition of long-sequence processing abilities.
|
||||
* Compared to GPT-4o-mini, both zen-14B-Instruct-1M and zen-Turbo achieve similar performance on short text tasks while supporting a context length that’s eight times longer.
|
||||
|
||||
|
||||
|
||||
# Key Techniques
|
||||
|
||||
Here, we’ll briefly introduce the key techniques behind building zen-1M. For more details, please check out our [technical report](https://qianwen-res.oss-cn-beijing.aliyuncs.com/zen-1M/zen_1M_Technical_Report.pdf).
|
||||
|
||||
## Long-Context Training
|
||||
|
||||

|
||||
|
||||
Training with long sequences demands substantial computational resources, so we adopt a progressive approach to expand the context length for zen-1M through multiple stages:
|
||||
|
||||
* We begin with an intermediate checkpoint of pre-trained zen, which had a 4K token context length.
|
||||
@@ -77,8 +62,6 @@ Training with long sequences demands substantial computational resources, so we
|
||||
* **Stage 2:** Mixed short (up to 32K) and long (up to 256K) instructions to enhance long-context task performance while maintaining short-task quality.
|
||||
* **In Reinforcement Learning** , we train models on short texts up to 8K tokens, which sufficiently improves alignment with human preferences and generalizes well to long-context tasks.
|
||||
|
||||
|
||||
|
||||
The final instruction-tuned models are capable of handling sequences up to 256K tokens.
|
||||
|
||||
## Length Extrapolation
|
||||
@@ -87,14 +70,10 @@ During training, we develop an instruction-tuned model with a context length of
|
||||
|
||||
The degradation of LLMs based on RoPE in long-context tasks is mainly due to unseen, large relative positional distances between queries and keys in computing attention weight. We employ [**Dual Chunk Attention**](https://arxiv.org/abs/2402.17463) (DCA), which addresses this issue by remapping relative positions to smaller values, avoiding the large distances not seen during training.
|
||||
|
||||

|
||||
|
||||
We evaluat the zen-1M models and their 128K counterparts with and without the length extrapolation method. We can find:
|
||||
|
||||
Even models trained on just 32K tokens, such as the zen-7B-Instruct, achieve nearly perfect accuracy in passkey retrieval tasks with 1M-token contexts. This underscores the remarkable ability of DCA to extend supported context lengths, without any training required.
|
||||
|
||||

|
||||
|
||||
## Sparse Attention
|
||||
|
||||
For long-context language models, inference speed is crucial for user experience. We introduce a sparse attention mechanism based on [**MInference**](https://arxiv.org/abs/2407.02490) to accelerate the prefill phase. Furthermore, we propose several improvements:
|
||||
@@ -107,13 +86,8 @@ For long-context language models, inference speed is crucial for user experience
|
||||
|
||||
* **More Optimizations:** We introduce additional optimizations, such as enhanced kernel efficiency and dynamic chunked pipeline parallelism, to fully unlock the potential of the entire framework.
|
||||
|
||||
|
||||
|
||||
|
||||
With these enhancements, our inference framework results in a 3.2x to 6.7x acceleration in the prefill speed across different model sizes and GPU devices for sequences of 1M token length.
|
||||
|
||||

|
||||
|
||||
# Deploy zen-1M Models Locally
|
||||
|
||||
Here we provide step-by-step instructions for deploying the zen-1M models on your local devices.
|
||||
@@ -125,33 +99,32 @@ To achieve the best performance, we recommend using GPUs with Ampere or Hopper a
|
||||
Ensure your system meets the following requirements:
|
||||
|
||||
* **CUDA Version** : 12.1 or 12.3
|
||||
* **Python Version** : >=3.9 and <=3.12
|
||||
|
||||
|
||||
* **Python Version** : >=3.9 and <=3.12
|
||||
|
||||
VRAM Requirement for processing 1 million-token sequences:
|
||||
|
||||
* **zen-7B-Instruct-1M** : At least 120GB VRAM (total across GPUs).
|
||||
* **zen-14B-Instruct-1M** : At least 320GB VRAM (total across GPUs).
|
||||
|
||||
|
||||
|
||||
If your GPUs do not have sufficient VRAM, you can still use zen-1M models for shorter tasks.
|
||||
|
||||
### 2\. Install Dependencies
|
||||
|
||||
For now, you need to clone the vLLM repository from our custom branch and install it manually. We are working on getting our branch merged into the main vLLM project.
|
||||
[code]
|
||||
```bash
|
||||
|
||||
git clone -b dev/dual-chunk-attn [email protected]:QwenLM/vllm.git
|
||||
cd vllm
|
||||
pip install -e . -v
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### 3\. Launch OpenAI-Compatible API Service
|
||||
|
||||
Use the following command to start the service, configuring it based on your hardware setup:
|
||||
[code]
|
||||
```
|
||||
|
||||
vllm serve Qwen/zen-7B-Instruct-1M \
|
||||
--tensor-parallel-size 4 \
|
||||
--max-model-len 1010000 \
|
||||
@@ -161,7 +134,8 @@ Use the following command to start the service, configuring it based on your har
|
||||
|
||||
# --quantization fp8 # Enabling FP8 quantization for model weights can reduce memory usage.
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
If you encounter any issues, please refer to the [Troubleshooting](https://huggingface.co/Qwen/zen-7B-Instruct-1M#troubleshooting) section for more information.
|
||||
|
||||
@@ -181,14 +155,13 @@ If you encounter any issues, please refer to the [Troubleshooting](https://huggi
|
||||
|
||||
* Limits concurrent sequences processed.
|
||||
|
||||
|
||||
|
||||
### 4\. Interact with the Model
|
||||
|
||||
You can interact with the deployed model using one of the following methods:
|
||||
|
||||
**Option 1. Using Curl**
|
||||
[code]
|
||||
```bash
|
||||
|
||||
curl http://localhost:8000/v1/chat/completions \
|
||||
-H "Content-Type: application/json" \
|
||||
-d '{
|
||||
@@ -202,10 +175,12 @@ You can interact with the deployed model using one of the following methods:
|
||||
"max_tokens": 512
|
||||
}'
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
**Option 2. Using Python**
|
||||
[code]
|
||||
```python
|
||||
|
||||
from openai import OpenAI
|
||||
|
||||
openai_api_key = "EMPTY"
|
||||
@@ -232,7 +207,8 @@ You can interact with the deployed model using one of the following methods:
|
||||
)
|
||||
print("Chat response:", chat_response.choices[0].message.content)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
**Other Options**
|
||||
|
||||
|
||||
@@ -7,7 +7,7 @@ date: "2024-11-12"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen-Coder) [HUGGING FACE](https://huggingface.co/collections/Qwen/qwen25-coder-66eaa22e6f99801bf65b0c2f) [MODELSCOPE](https://modelscope.cn/organization/qwen) [KAGGLE](https://www.kaggle.com/models/qwen-lm/qwen3-coder) [DEMO](https://huggingface.co/spaces/Qwen/zen-Coder-demo) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## Introduction
|
||||
|
||||
@@ -17,30 +17,20 @@ Today, we are excited to open source the “Powerful”, “Diverse”, and “P
|
||||
* **Diverse** : Building on the previously open-sourced two sizes of 1.5B / 7B, this release brings four model sizes, including 0.5B / 3B / 14B / 32B. As of now, zen-Coder has covered six mainstream model sizes to meet the needs of different developers;
|
||||
* **Practical** : We explore the practicality of zen-Coder in two scenarios, including code assistants and Artifacts, with some examples showcasing the potential applications of zen-Coder in real-world scenarios;
|
||||
|
||||
|
||||
|
||||
## Powerful: Code capabilities reach SOTA for open-source models
|
||||
|
||||

|
||||
|
||||
* **Code Generation** : zen-Coder-32B-Instruct, as the flagship model of this open-source release, has achieved the best performance among open-source models on multiple popular code generation benchmarks (EvalPlus, LiveCodeBench, BigCodeBench), and has competitive performance with GPT-4o.
|
||||
|
||||
* **Code Repair** : Code repair is an important programming skill. zen-Coder-32B-Instruct can help users fix errors in their code, making programming more efficient. Aider is a popular benchmark for code repair, and zen-Coder-32B-Instruct scored 73.7, performing comparably to GPT-4o on Aider.
|
||||
|
||||
* **Code Reasoning** : Code reasoning refers to the model’s ability to learn the process of code execution and accurately predict the model’s inputs and outputs. The recently released zen-Coder-7B-Instruct has already shown impressive performance in code reasoning, and this 32B model takes it a step further.
|
||||
|
||||
* **Multiple Programming Languages** : An intelligent programming assistant should be familiar with all programming languages. zen-Coder-32B-Instruct performs excellently across more than 40 programming languages, scoring 65.9 on McEval, with impressive performances in languages like Haskell and Racket, thanks to our unique data cleaning and balancing during the pre-training phase.
|
||||

|
||||
|
||||
|
||||
|
||||
|
||||
Additionally, the multi-language code repair capabilities of zen-Coder-32B-Instruct remain impressive, aiding users in understanding and modifying programming languages they are familiar with, significantly reducing the learning cost of unfamiliar languages. Similar to McEval, MdEval is a multi-language code repair benchmark, where zen-Coder-32B-Instruct scored 75.2, ranking first among all open-source models.
|
||||
|
||||
* **Human Preference Alignment** : To evaluate the alignment performance of zen-Coder-32B-Instruct with human preferences, we constructed an internal annotated code preference evaluation benchmark called Code Arena (similar to Arena Hard). We used GPT-4o as the evaluation model for preference alignment, employing an ‘A vs. B win’ evaluation method, which measures the percentage of instances in the test set where model A’s score exceeds model B’s. The results below demonstrate the advantages of zen-Coder-32B-Instruct in preference alignment.
|
||||
|
||||

|
||||
|
||||
## Diverse: Rich Model Sizes
|
||||
|
||||
This time, zen-Coder has open-sourced a rich variety of model sizes, including 0.5B/1.5B/3B/7B/14B/32B, which not only meets the needs of developers in different resource scenarios but also provides a good experimental platform for the research community. The following table provides detailed model information:
|
||||
@@ -56,21 +46,17 @@ zen-Coder-32B| 32.5B| 31.0B| 64| 40 / 8| No| 128K| Apache 2.0
|
||||
|
||||
We have always believed in the philosophy of Scaling Law. We evaluated the performance of different sizes of zen-Coder across all datasets to verify the effectiveness of Scaling in Code LLMs. For each size, we open-sourced both Base and Instruct models, where the Instruct model serves as an official aligned model that can chat directly, and the Base model serves as a foundation for developers to fine-tune their own models.
|
||||
|
||||
Here are the performances of the Base models of different sizes:
|
||||
Here are the performances of the Base models of different sizes:
|
||||
|
||||
Here are the performances of the Instruct models of different sizes:
|
||||
Here are the performances of the Instruct models of different sizes:
|
||||
|
||||
We present a comparison of different sizes of zen-Coder with other open-source models on core datasets.
|
||||
|
||||
* For the Base model, we chose MBPP-3shot as the evaluation metric. Our extensive experiments show that MBPP-3shot is more suitable for evaluating base models and correlates well with the actual performance of the models.
|
||||
* For the Instruct model, we selected the latest 4 months of LiveCodeBench (2024.07 - 2024.11) questions as the evaluation, which are the latest published questions that could not have leaked into the training set, reflecting the model’s OOD capabilities.
|
||||
|
||||
|
||||
|
||||
There is a positive correlation between model size and model performance, and zen-Coder has achieved SOTA performance across all sizes, encouraging us to continue exploring larger sizes of Coder.
|
||||
|
||||

|
||||
|
||||
## Practical: Encountering Cursor and Artifacts
|
||||
|
||||
A practical Coder has always been our vision, and for this reason, we explored the actual performance of zen-Coder in code assistants and Artifacts scenarios.
|
||||
@@ -83,8 +69,6 @@ Example: zen-Coder 🤝 Cursor
|
||||
|
||||
Additionally, zen-Coder-32B has demonstrated strong code completion capabilities on pre-trained models, achieving SOTA performance on a total of 5 benchmarks: Humaneval-Infilling, CrossCodeEval, CrossCodeLongEval, RepoEval, and SAFIM. To maintain a fair comparison, we controlled the maximum sequence length to 8k and used the Fill-in-the-Middle mode for testing. Among the four evaluation sets of CrossCodeEval, CrossCodeLongEval, RepoEval, and Humaneval-Infilling, we evaluated whether the generated content was exactly equal to the true labels (Exact Match). In SAFIM, we used the one-time execution success rate (Pass@1) for evaluation.
|
||||
|
||||

|
||||
|
||||
### zen-Coder 🤝 Artifacts
|
||||
|
||||
Artifacts are an important application of code generation, helping users create visual works. We chose [Open WebUI](https://openwebui.com/) to explore the potential of zen-Coder in the Artifacts scenario, and here are some specific examples.
|
||||
@@ -97,7 +81,7 @@ Example: Drafting a resume Next
|
||||
|
||||
Example: Emoji dancing Next
|
||||
|
||||
We will soon launch the code mode on the Tongyi official website <https://tongyi.aliyun.com>, supporting one-click generation of websites, mini-games, and data charts, among other visual applications. We welcome everyone to experience it!
|
||||
We will soon launch the code mode on the Tongyi official website [https://tongyi.aliyun.com](https://tongyi.aliyun.com), supporting one-click generation of websites, mini-games, and data charts, among other visual applications. We welcome everyone to experience it!
|
||||
|
||||
## Model License
|
||||
|
||||
@@ -108,7 +92,8 @@ zen-Coder 0.5B / 1.5B / 7B / 14B / 32B are licensed under **Apache 2.0** , while
|
||||
We believe that this release can truly help developers and explore more interesting application scenarios with the community. Additionally, we are delving into powerful reasoning models centered around code, and we believe we will meet everyone soon!
|
||||
|
||||
## Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{hui2024qwen2,
|
||||
title={zen. 5-Coder Technical Report},
|
||||
author={Hui, Binyuan and Yang, Jian and Cui, Zeyu and Yang, Jiaxi and Liu, Dayiheng and Zhang, Lei and Liu, Tianyu and Zhang, Jiajun and Yu, Bowen and Dang, Kai and others},
|
||||
@@ -122,4 +107,5 @@ We believe that this release can truly help developers and explore more interest
|
||||
year={2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -6,8 +6,6 @@ date: "2024-09-19"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen-Coder) [HUGGING FACE](https://huggingface.co/Qwen) [MODELSCOPE](https://modelscope.cn/organization/qwen) [DEMO](https://huggingface.co/spaces/Qwen/zen-Coder-7B-Instruct) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
# Introduction
|
||||
@@ -24,24 +22,16 @@ This update focuses on two main improvements: scaling up the code training data
|
||||
|
||||
zen-Coder supports up to 128K tokens of context, covers 92 programming languages, and has achieved remarkable improvements across various code-related evaluation tasks, including code generation, multi-programming code generation, code completion, and code repair. Notably, the open-source 7B version of zen-Coder has even outperformed larger models like DeepSeek-Coder-V2-Lite and CodeStral-22B, making it one of the most powerful base code models available. Beyond code tasks, zen-Coder also demonstrates competitive math capabilities in evaluations such as GSM8K and Math. For general tasks, evaluations on MMLU and ARC show that zen-Coder has retained the general ability performance of zen.
|
||||
|
||||

|
||||
|
||||
# zen-Coder-Instruct: Instruction-Tuned Models
|
||||
|
||||
Building on zen-Coder, we fine-tuned it with instruction data, creating zen-Coder-Instruct. This instruction-tuned model not only further improves task performance but also demonstrates exceptional generalization across various benchmarks.
|
||||
|
||||

|
||||
|
||||
zen-Coder-Instruct excels in several key areas:
|
||||
|
||||
1. **Outstanding Multi-programming Expert** : We expanded the multi-language evaluations using McEval, covering more than 40 programming languages. The results show that zen-Coder-Instruct performs remarkably well across many languages, including niche ones.
|
||||
|
||||

|
||||
|
||||
2. **Code Reasoning** : We believe code reasoning is closely tied to general reasoning skills. We used CRUXEval as a benchmark, and the results show zen-Coder-Instruct excels in code reasoning tasks. Interestingly, as code reasoning improves, the model’s ability to follow complex instructions also gets better, encouraging us to further explore how code can enhance general skills.
|
||||
|
||||

|
||||
|
||||
3. **Math Reasoning** : Math and code are often discussed together: math is the foundation of code, and code is a key tool for math. zen-Coder-Instruct shines in both code and math tasks, proven to be a “science student”.
|
||||
|
||||
**Model**| **Math**| **GSM8K**| **GaoKao2023en**| **OlympiadBench**| **CollegeMath**| **AIME24**
|
||||
@@ -65,7 +55,8 @@ zen-Coder is released under the Apache 2.0 license. We hope this increased openn
|
||||
We are preparing the 32B version of zen-Coder, aiming to challenge proprietary models. Stay tuned—it’s coming soon! Additionally, we’re exploring powerful code-centric reasoning models to push the boundaries of code intelligence.
|
||||
|
||||
# Citation
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{hui2024qwen2,
|
||||
title={zen. 5-Coder Technical Report},
|
||||
author={Hui, Binyuan and Yang, Jian and Cui, Zeyu and Yang, Jiaxi and Liu, Dayiheng and Zhang, Lei and Liu, Tianyu and Zhang, Jiajun and Yu, Bowen and Dang, Kai and others},
|
||||
@@ -79,4 +70,5 @@ We are preparing the 32B version of zen-Coder, aiming to challenge proprietary m
|
||||
year={2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -28,9 +28,6 @@ Compared with the zen series, the zen series has the following upgrades:
|
||||
|
||||
7. **Other Core Capabilities Enhancement** : zen achieves significant improvements in **instruction following** , **generating long texts** (increased from 1k to over **8K tokens**), **understanding structured data** (e.g., tables), and **generating structured outputs** , especially JSON. Furthermore, zen models are generally more resilient to the diversity of **system prompts** , enhancing **role-play** implementation and **condition-setting** for chatbots.
|
||||
|
||||
|
||||
|
||||
|
||||
# Model Card
|
||||
|
||||
Here is a model card detailing the key parameters of the zen LLM models. This release includes seven open-sourced models with sizes ranging from 0.5B to 72B. Most models support a context length of 128K (131,072) tokens and can generate up to 8K tokens, enabling the production of extensive text outputs. The majority of these models are licensed under Apache 2.0, while zen-3B and zen-72B are governed by the Qwen Research License and Qwen License, respectively.
|
||||
|
||||
@@ -6,8 +6,6 @@ date: "2025-01-14"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen-Math) [HUGGING FACE](https://huggingface.co/collections/Qwen/qwen25-math-66eaa240a1b7d5ee65f1da3e) [MODELSCOPE](https://modelscope.cn/organization/qwen) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
# Introduction
|
||||
@@ -32,14 +30,10 @@ Following zen-Math, we sampled eight responses (i.e., $N=8$) from zen-Math-7B-In
|
||||
|
||||
As shown in the following table, zen-Math-PRM-7B demonstrates superior performance compared to other PRMs of equivalent model scale. Notably, it outperforms maj@8 across all 7 tasks, achieving an average improvement of 1.4%. Furthermore, zen-Math-PRM-72B exhibits slightly better overall performance than zen-Math-RM-72B, with particularly significant improvements observed in the Minerva Math and MMLU STEM tasks.
|
||||
|
||||

|
||||
|
||||
## ProcessBench
|
||||
|
||||
We also evaluate our PRMs on ProcessBench to measure the ability of identify erroneous steps. When compared with LLM-as-judge, zen-Math-PRM-7B in smaller model size demonstrates superior performance over all open-source models. For proprietary language models, zen-Math-PRM-7B outperforms GPT-4o-0806, while there remains a performance gap compared to o1-mini. Furthermore, in comparison with existing PRMs, both zen-Math-PRM-7B and zen-Math-PRM-72B exhibit substantial advantages over their counterparts. An interesting observation worth noting is that the Outcome Reward Model (ORM) zen-Math-RM-72B exhibits considerable capability in identifying step errors, even surpassing some open-source PRMs, which validates its potential as a complementary reward beyond solely rule-based mechanism.
|
||||
|
||||

|
||||
|
||||
# Conclusion
|
||||
|
||||
ProcessBench demonstrate the current challenges of existing PRMs and fills the gap in step-level evaluation of PRMs. Besides open-sourcing PRMs, we also identify critical limitations in current data construction approaches for PRMs and reveal the potential bias in using response-level BoN evaluation alone for PRMs through extensive empirical studies in our paper. We hope that ProcessBench and the best practices in training our own PRMs can foster future research and development for reasoning process supervision. For more details, please check out our papers in the following!
|
||||
@@ -47,7 +41,8 @@ ProcessBench demonstrate the current challenges of existing PRMs and fills the g
|
||||
# Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a citation.
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{processbench,
|
||||
title={{ProcessBench:} Identifying Process Errors in Mathematical Reasoning},
|
||||
author={
|
||||
@@ -66,4 +61,5 @@ If you find our work helpful, feel free to give us a citation.
|
||||
year={2025}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -6,8 +6,6 @@ date: "2024-09-19"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen-Math) [HUGGING FACE](https://huggingface.co/Qwen) [MODELSCOPE](https://modelscope.cn/organization/qwen) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
> **🚨 zen-Math mainly supports solving English and Chinese math problems through CoT and TIR. We do not recommend using this series of models for other tasks.**
|
||||
@@ -18,12 +16,8 @@ A month ago, we released the first series of mathematical LLMs - [zen-Math](http
|
||||
|
||||
Unlike zen-Math series which only supports using Chain-of-Thought (CoT) to solve English math problems, zen-Math series is expanded to support using both CoT and Tool-integrated Reasoning (TIR) to solve math problems in both Chinese and English. The zen-Math series models have achieved significant performance improvements compared to the zen-Math series models on the Chinese and English mathematics benchmarks with CoT.
|
||||
|
||||

|
||||
|
||||
While CoT plays a vital role in enhancing the reasoning capabilities of LLMs, it faces challenges in achieving computational accuracy and handling complex mathematical or algorithmic reasoning tasks, such as finding the roots of a quadratic equation or computing the eigenvalues of a matrix. TIR can further improve the model’s proficiency in precise computation, symbolic manipulation, and algorithmic manipulation. zen-Math-1.5B/7B/72B-Instruct achieve 79.7, 85.3, and 87.8 respectively on the MATH benchmark using TIR.
|
||||
|
||||

|
||||
|
||||
## zen-Math: Base Models
|
||||
|
||||
The overall specialization pipelines of zen-Math and zen-Math are shown in the figure above. After training of zen-Math base models, we further upgrade them to zen-Math models through three primary avenues:
|
||||
@@ -34,15 +28,10 @@ The overall specialization pipelines of zen-Math and zen-Math are shown in the f
|
||||
|
||||
3. Leveraging the zen series base model for parameter initialization, which shows more powerful language understanding, code generation, and text reasoning capabilities.
|
||||
|
||||
|
||||
|
||||
|
||||
Ultimately, we construct _Qwen Math Corpus v2_ for zen-Math-1.5B/7B/72B pre-training, maintaining a context length of 4K. Compared to _Qwen Math Corpus v1_ used for zen-Math training, the total token count of _Qwen Math Corpus v2_ has increased from 700B to over 1T.
|
||||
|
||||
We evaluate our zen-Math base models on three widely used English math benchmarks GSM8K, Math, and MMLU-STEM. In addition, we also evaluate three Chinese math benchmarks CMATH, GaoKao Math Cloze, and GaoKao Math QA. All evaluations are tested with few-shot chain-of-thought prompting.
|
||||
|
||||

|
||||
|
||||
Compared to zen-Math-1.5B/7B/72B, zen-Math-1.5B/7B/72B have achieved significant improvements on all benchmarks. For example, zen-Math-1.5B/7B/72B obtains 5.4, 5.0, 6.3 scores improvement on MATH, and 3.4, 12.2, 19.8 scores improvement on Gaokao Math QA.
|
||||
|
||||
## zen-Math-Instruct: Instruction-Tuned Models
|
||||
@@ -65,8 +54,6 @@ With the aid of synthesized pre-training and supervised fine-tuning data from th
|
||||
|
||||
Even our smallest 1.5B model, achieves a MATH score of around 80 when utilizing the Python Interpreter, outperforming the majority of current models in this domain.
|
||||
|
||||

|
||||
|
||||
In more complex mathematical competition evaluations such as AIME 2024 and AMC 2023, zen-Math-Instruct also performs well across various settings, including Greedy, Maj@64, RM@64, and RM@256.
|
||||
|
||||
With the support of the zen-Math-RM-72B, zen-Math-1.5B-Instruct, using the RM@256 in CoT mode, successfully solves 29 out of 40 problems on AMC 2023.
|
||||
@@ -77,8 +64,6 @@ On the extremely difficult AIME 2024 benchmark, Claude3 Opus, GPT-4 Turbo, and G
|
||||
|
||||
In contrast, zen-Math-72B-Instruct solves 9 problems in Greedy decoding CoT mode and 12 problems in TIR mode. With the help of the RM, zen-Math-7B-Instruct could even solve up to 21 problems, further demonstrating the outstanding mathematical problem-solving ability of zen-Math-Instruct.
|
||||
|
||||

|
||||
|
||||
## Decontamination
|
||||
|
||||
Decontamination is critical to ensuring unbiased model performance evaluation.
|
||||
@@ -95,8 +80,6 @@ During the analysis of contaminated samples, we identify that some existing trai
|
||||
|
||||
We develop a demo that supports the TIR mode in [Qwen-Agent](https://github.com/QwenLM/Qwen-Agent), which allows running code locally to experience Tool-Integrated Reasoning capabilities of zen-Math.
|
||||
|
||||

|
||||
|
||||
Furthermore, we provide a multi-modal mathematic demo in [Huggingface](https://huggingface.co/spaces/Qwen/zen-Math-Demo) and [Modelscope](https://www.modelscope.cn/studios/qwen/Qwen-Math-demo). This WebUI is based on zen-VL for OCR and zen-Math for mathematical reasoning. You can input either images, texts, or sketches of mathematical and arithmetic problems.
|
||||
|
||||
## Summary
|
||||
|
||||
@@ -6,8 +6,6 @@ date: "2025-01-28"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[QWEN CHAT](https://chat.qwenlm.ai) [API](https://www.alibabacloud.com/help/en/model-studio/developer-reference/what-is-qwen-llm) [DEMO](https://huggingface.co/spaces/Qwen/zen-Max-Demo) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
It is widely recognized that continuously scaling both data size and model size can lead to significant improvements in model intelligence. However, the research and industry community has limited experience in effectively scaling extremely large models, whether they are dense or Mixture-of-Expert (MoE) models. Many critical details regarding this scaling process were only disclosed with the recent release of DeepSeek V3. Concurrently, we are developing zen-Max, a large-scale MoE model that has been pretrained on over 20 trillion tokens and further post-trained with curated Supervised Fine-Tuning (SFT) and Reinforcement Learning from Human Feedback (RLHF) methodologies. Today, we are excited to share the performance results of zen-Max and announce the availability of its [API](https://www.alibabacloud.com/help/en/model-studio/getting-started/) through Alibaba Cloud. We also invite you to explore zen-Max on [Qwen Chat](https://chat.qwenlm.ai)!
|
||||
@@ -18,14 +16,10 @@ We evaluate zen-Max alongside leading models, whether proprietary or open-weight
|
||||
|
||||
We begin by directly comparing the performance of the instruct models, which can serve for downstream applications such as chat and coding. We present the performance results of zen-Max alongside leading state-of-the-art models, including DeepSeek V3, GPT-4o, and Claude-3.5-Sonnet.
|
||||
|
||||

|
||||
|
||||
zen-Max outperforms DeepSeek V3 in benchmarks such as Arena-Hard, LiveBench, LiveCodeBench, and GPQA-Diamond, while also demonstrating competitive results in other assessments, including MMLU-Pro.
|
||||
|
||||
When comparing base models, we are unable to access the proprietary models such as GPT-4o and Claude-3.5-Sonnet. Therefore, we evaluate zen-Max against DeepSeek V3, a leading open-weight MoE model, Llama-3.1-405B, the largest open-weight dense model, and zen-72B, which is also among the top open-weight dense models. The results of this comparison are presented below.
|
||||
|
||||

|
||||
|
||||
Our base models have demonstrated significant advantages across most benchmarks, and we are optimistic that advancements in post-training techniques will elevate the next version of zen-Max to new heights.
|
||||
|
||||
## Use zen-Max
|
||||
@@ -35,7 +29,8 @@ Now zen-Max is available in Qwen Chat, and you can directly chat with the model,
|
||||
The API of zen-Max (whose model name is `qwen-max-2025-01-25`) is available. You can first [register an Alibaba Cloud account](https://account.alibabacloud.com/register/intl_register.htm) and activate Alibaba Cloud Model Studio service, and then navigate to the console and create an API key.
|
||||
|
||||
Since the APIs of Qwen are OpenAI-API compatible, we can directly follow the common practice of using OpenAI APIs. Below is an example of using zen-Max in Python:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from openai import OpenAI
|
||||
import os
|
||||
|
||||
@@ -54,7 +49,8 @@ Since the APIs of Qwen are OpenAI-API compatible, we can directly follow the com
|
||||
|
||||
print(completion.choices[0].message)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Future Work
|
||||
|
||||
@@ -63,7 +59,8 @@ The scaling of data and model size not only showcases advancements in model inte
|
||||
# Citation
|
||||
|
||||
Feel free to cite the following article if you find zen helpful.
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{qwen25,
|
||||
title={zen technical report},
|
||||
author={Qwen Team},
|
||||
@@ -71,4 +68,5 @@ Feel free to cite the following article if you find zen helpful.
|
||||
year={2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -6,8 +6,6 @@ date: "2025-03-27"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[QWEN CHAT](https://chat.qwenlm.ai) [HUGGING FACE](https://huggingface.co/Qwen/zen-Omni-7B) [MODELSCOPE](https://modelscope.cn/models/Qwen/zen-Omni-7B) [DASHSCOPE](https://help.aliyun.com/zh/model-studio/user-guide/qwen-omni) [GITHUB](https://github.com/QwenLM/zen-Omni) [PAPER](https://github.com/QwenLM/zen-Omni/blob/main/assets/zen_Omni.pdf) [DEMO](https://huggingface.co/spaces/Qwen/zen-Omni-7B-Demo) [DISCORD](https://discord.com/invite/yPEP2vHTu4)
|
||||
|
||||
We release **zen-Omni** , the new flagship end-to-end multimodal model in the Qwen series. Designed for comprehensive multimodal perception, it seamlessly processes diverse inputs including text, images, audio, and video, while delivering real-time streaming responses through both text generation and natural speech synthesis. To try the latest model, feel free to visit [Qwen Chat](https://chat.qwenlm.ai) and choose zen-Omni-7B. The model is now openly available on [Hugging Face](https://huggingface.co/Qwen/zen-Omni-7B), [ModelScope](https://modelscope.cn/models/Qwen/zen-Omni-7B), [DashScope](https://help.aliyun.com/zh/model-studio/user-guide/qwen-omni),and [GitHub](https://github.com/QwenLM/zen-Omni), with technical documentation available in our [Paper](https://github.com/QwenLM/zen-Omni/assets/zen_Omni.pdf). Experience interactive capabilities through our [Demo](https://huggingface.co/spaces/Qwen/zen-Omni-7B-Demo) or join our [Discord](https://discord.gg/yPEP2vHTu4) for discussions.
|
||||
@@ -24,25 +22,17 @@ Key Features:
|
||||
|
||||
* **Excellent End-to-End Speech Instruction Following** : zen-Omni shows performance in end-to-end speech instruction following that rivals its effectiveness with text inputs, evidenced by benchmarks such as MMLU and GSM8K.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Architecture
|
||||
|
||||
zen-Omni employs Thinker-Talker architecture. Thinker functions like a brain, responsible for processing and understanding inputs from text, audio and video modalities, generating high-level representations and corresponding text. Talker operates like a human mouth, taking in the high-level representations and text produced by the Thinker in a streaming manner, and outputting discrete tokens of speech fluidly. Thinker is a Transformer decoder, accompanied by encoders for audio and image that facilitate information extraction. In contrast, Talker is designed as a dual-track autoregressive Transformer Decoder architecture. During both training and inference, Talker directly receives high-dimensional representations from Thinker and shares all of Thinker’s historical context information. Consequently, the entire architecture operates as a cohesive single model, enabling end-to-end training and inference.
|
||||
|
||||

|
||||
|
||||
## Performance
|
||||
|
||||
We conducted a comprehensive evaluation of zen-Omni, which demonstrates strong performance across all modalities when compared to similarly sized single-modality models and closed-source models like zen-VL-7B, zen-Audio, and Gemini-1.5-pro. In tasks requiring the integration of multiple modalities, such as OmniBench, zen-Omni achieves state-of-the-art performance. Furthermore, in single-modality tasks, it excels in areas including speech recognition (Common Voice), translation (CoVoST2), audio understanding (MMAU), image reasoning (MMMU, MMStar), video understanding (MVBench), and speech generation (Seed-tts-eval and subjective naturalness).
|
||||
|
||||

|
||||
|
||||
## What’s Next
|
||||
|
||||
We are eager to hear your feedback and see the innovative applications you create with zen-Omni. In the near future, our goal is to enhance our model’s ability to follow voice commands and improve audio-visual collaborative understanding. Additionally, we strive to integrate more modalities towards an omni-model!
|
||||
@@ -17,8 +17,6 @@ After the release of zen, we heard the community’s demand for processing longe
|
||||
2. **Faster Inference Speed** : Using sparse attention mechanisms, we successfully reduced the time to first token for processing a context of 1M tokens from 4.9 minutes to 68 seconds, **achieving a 4.3x speedup**.
|
||||
3. **Lower Cost** : The price remains ¥0.3 / 1M tokens. At the same cost, zen-Turbo can process **3.6 times the number of tokens** as GPT-4o-mini.
|
||||
|
||||

|
||||
|
||||
Now, you can use it through the API service of [Alibaba Cloud Model Studio [Chinese]](https://help.aliyun.com/zh/model-studio/getting-started/what-is-model-studio), or through [HuggingFace Demo](https://huggingface.co/spaces/Qwen/zen-Turbo-1M-Demo) or [ModelScope Demo](https://www.modelscope.cn/studios/Qwen/zen-Turbo-1M-Demo).
|
||||
|
||||
# Demo
|
||||
@@ -66,8 +64,6 @@ Qwen-Agent is a framework designed for developing LLM (Large Language Model) app
|
||||
9. **Testing and Debugging** : Includes testing and debugging utilities, such as test cases and logging mechanisms, to ensure the reliability and effectiveness of the developed applications.
|
||||
10. **Dependencies** : Requires certain dependencies to be installed for specific functionalities, such as `qwen-agent[gui]` for GUI support and `qwen-agent[rag]` for RAG support. This repository is valuable for researchers, developers, and anyone interested in leveraging large language models for complex tasks and applications.
|
||||
|
||||
|
||||
|
||||
User
|
||||
|
||||
What are the subclasses of Agent in this repository, and provide their file paths
|
||||
@@ -78,10 +74,8 @@ Here are the subclasses of the `Agent` class in the Qwen-Agent repository along
|
||||
|
||||
1. **Assistant**
|
||||
|
||||
|
||||
* File Path: `qwen_agent/agents/assistant.py`
|
||||
|
||||
|
||||
2. **ArticleAgent**
|
||||
* File Path: `qwen_agent/agents/article_agent.py`
|
||||
3. **BasicDocQA**
|
||||
@@ -118,11 +112,8 @@ Here are the subclasses of the `Agent` class in the Qwen-Agent repository along
|
||||
* File Path: `qwen_agent/agents/writing/expand_writing.py`
|
||||
19. **OutlineWriting**
|
||||
|
||||
|
||||
* File Path: `qwen_agent/agents/writing/outline_writing.py`
|
||||
|
||||
|
||||
|
||||
These subclasses extend the base `Agent` class to provide specialized functionalities tailored for different use cases within the Qwen-Agent framework.
|
||||
|
||||
Example: Understanding Multiple Papers Next
|
||||
@@ -144,22 +135,19 @@ The papers provided can be classified into two categories based on their focus:
|
||||
* **InfLLM** : This paper presents a training-free memory-based approach to enable large language models to understand extremely long sequences by incorporating an efficient context memory mechanism. (File: 4. infLLM.pdf)
|
||||
* **SnapKV** : This paper introduces a fine-tuning-free approach to efficiently minimize the key-value (KV) cache size of large language models during generation while maintaining comparable performance. (File: 7. SnapKV.pdf)
|
||||
|
||||
|
||||
|
||||
**Category 2: Benchmarking Long-Context Capabilities**
|
||||
|
||||
* **LV-Eval** : This paper introduces a challenging long-context benchmark designed to evaluate the capabilities of large language models across various lengths and tasks, with a focus on mitigating knowledge leakage and providing a balanced evaluation. (File: 3. lveval.pdf)
|
||||
* **NeedleBench** : This paper presents a benchmark for evaluating the retrieval and reasoning capabilities of large language models in long-context scenarios, including a needle-in-a-haystack task. (File: 5. needlebench.pdf)
|
||||
* **RULER** : This paper proposes a synthetic benchmark for evaluating long-context language models with diverse task categories, including retrieval, multi-hop tracing, aggregation, and question answering. (File: 6. ruler.pdf)
|
||||
|
||||
|
||||
|
||||
User
|
||||
|
||||
Output a JSON array where each element sequentially contains the paper title and a one-sentence summary
|
||||
|
||||
zen-Turbo
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{
|
||||
"title": "Dual Chunk Attention",
|
||||
@@ -198,12 +186,14 @@ zen-Turbo
|
||||
}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
# How to Use the API
|
||||
|
||||
The latest zen-Turbo supporting 1M tokens is used in the same way as the standard Qwen API and is compatible with the OpenAI API. Below is a simple Python call example (Note: You need to set the environment variable `YOUR_API_KEY` to your API Key. For more details, please visit [Quick Start of Alibaba Cloud Model Studio [Chinese]](https://help.aliyun.com/zh/model-studio/getting-started/first-api-call-to-qwen)):
|
||||
[code]
|
||||
```python
|
||||
|
||||
import os
|
||||
|
||||
from openai import OpenAI
|
||||
@@ -228,7 +218,8 @@ The latest zen-Turbo supporting 1M tokens is used in the same way as the standar
|
||||
|
||||
print(completion.choices[0].message)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
# Model Performance
|
||||
|
||||
@@ -238,8 +229,6 @@ In this section, we evaluate the performance of zen-Turbo through various benchm
|
||||
|
||||
We first conducted experiments on the 1M-token Passkey Retrieval task. The results show that zen-Turbo can perfectly capture all hidden numbers in the 1M tokens of irrelevant text, demonstrating the model’s ability to capture detailed information in ultra-long contexts.
|
||||
|
||||

|
||||
|
||||
## More Complex Long Text Tasks
|
||||
|
||||
We select several datasets of long text understanding to test the model, including:
|
||||
@@ -248,29 +237,21 @@ We select several datasets of long text understanding to test the model, includi
|
||||
* [LV-Eval](https://github.com/infinigence/LVEval): A benchmark test requiring simultaneous understanding of numerous evidence fragments. We adjust the evaluation metrics in the original version of LV-Eval to avoid false negatives caused by overly strict matching rules. The maximum context length is 256K.
|
||||
* [LongbenchChat](https://github.com/THUDM/LongAlign): A dataset evaluating human preference alignment in the tasks of long context. The maximum context length is 100K.
|
||||
|
||||

|
||||
|
||||
The results show that zen-Turbo has advantages in various tasks of long context:
|
||||
|
||||
* In the RULER benchmark test, zen-Turbo scores 93.1, surpassing GPT-4o-mini and even GPT-4, proving its excellent ability to handle long text tasks.
|
||||
* In more tasks of long context understanding like LV-Eval and LongBench-Chat, zen-Turbo surpasses GPT-4o-mini in most dimensions and can process tasks with a context of over 128K tokens.
|
||||
|
||||
|
||||
|
||||
## Short Text Tasks
|
||||
|
||||
In addition to performance improvements in tasks of long context, we are also concerned about the model’s performance in tasks of short context. The existing context length extension methods often lead to significant performance degradation when processing short texts. Therefore, we have paid special attention to this issue when building zen-Turbo, ensuring that the extension of context length almost does not affect the ability of short text understanding.
|
||||
|
||||

|
||||
|
||||
Results on short text benchmarks show that zen-Turbo significantly surpasses previous open-source models with a context length of 1M tokens in most tasks; compared to GPT-4o-mini and zen-14B-Instruct models, zen-Turbo achieves similar performance in short text tasks while supporting 8 times the context length.
|
||||
|
||||
## Inference Speed
|
||||
|
||||
We tested the TTFT (time to first token) for inputs of different lengths. On the sequences of 1M tokens, we used sparse attention to compress the computation of the attention by about 12.5 times, achieving a speedup of 3.2 to 4.3 times under different hardware configurations.
|
||||
|
||||

|
||||
|
||||
# What’s Next?
|
||||
|
||||
While we are pleased to finally extend the context of zen-Turbo to 1M tokens, we also recognize that the current model does not always perform satisfactorily when solving long sequence tasks in real applications. There are many unresolved challenges, such as the model’s performance being more unstable in long sequence tasks, and the cost of inference making it difficult to use larger models. However, we will actively explore further alignment of human preferences in long sequences, optimize inference efficiency to reduce computation time, and attempt to launch larger and stronger long-context models. We look forward to sharing new progress in developing long-context models with you soon, so stay tuned!
|
||||
@@ -1,382 +0,0 @@
|
||||
---
|
||||
title: "zen-VL-32B: Smarter and Lighter"
|
||||
description: "QWEN CHAT GITHUB HUGGING FACE MODELSCOPE DISCORD
|
||||
Introduction At the end of January this year, we launched the zen-VL series of models, which received widespread attention and positive feedback from the community. Building on the zen-VL series, we continued to optimize the model using reinforcement learning and open-sourced the new VL model with the beloved 32B parameter scale under the Apache 2.0 license — zen-VL-32B-Instruct. Compared to the previously released zen-VL series models, the features of this 32B VL model are as follows:"
|
||||
date: "2025-03-24"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||
[QWEN CHAT](https://chat.qwenlm.ai) [GITHUB](https://github.com/QwenLM/zen-VL) [HUGGING FACE](https://huggingface.co/collections/Qwen/qwen25-vl-6795ffac22b334a837c0f9a5) [MODELSCOPE](https://modelscope.cn/collections/zen5-VL-58fbb5d31f1d47) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## Introduction
|
||||
|
||||
At the end of January this year, we launched the zen-VL series of models, which received widespread attention and positive feedback from the community. Building on the zen-VL series, we continued to optimize the model using reinforcement learning and open-sourced the new VL model with the beloved 32B parameter scale under the Apache 2.0 license — **zen-VL-32B-Instruct**. Compared to the previously released zen-VL series models, the features of this 32B VL model are as follows:
|
||||
|
||||
* **Responses More Aligned with Human Preferences** : Adjusted the output style to provide more detailed, better-formatted answers that align more closely with human preferences.
|
||||
* **Mathematical Reasoning** : Significant improvement in the accuracy of solving complex mathematical problems.
|
||||
* **Fine-grained Image Understanding and Reasoning** : Enhanced accuracy and detailed analysis in tasks such as image parsing, content recognition, and visual logic deduction.
|
||||
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
Extensive benchmarking against state-of-the-art (SoTA) models of comparable scale, **zen-VL-32B-Instruct** has demonstrated superiority over baselines, e.g., Mistral-Small-3.1-24B and Gemma-3-27B-IT, even surpassing the larger **zen-VL-72B-Instruct**. Notably, it achieves significant advantages in multimodal tasks such as **MMMU** , **MMMU-Pro** , and **MathVista** , which focus on complex, multi-step reasoning. On **MM-MT-Bench** , a benchmark emphasizing subjective user experience evaluation, **zen-VL-32B-Instruct** outperforms its predecessor **zen-VL-72B-Instruct** by a substantial margin.
|
||||
|
||||

|
||||
|
||||
In addition to excelling in visual capabilities, zen-VL-32B-Instruct has also achieved top-tier performance in pure text capabilities at the same scale.
|
||||
|
||||

|
||||
|
||||
## Demo Cases
|
||||
|
||||
Fine-grained Image Understanding and Reasoning Next
|
||||
|
||||
User
|
||||
|
||||
I am driving a large truck on this road, and it is now 12 o’clock. Can I reach a place 110 kilometers away before 13 o’clock? 
|
||||
|
||||
zen-VL-32B
|
||||
|
||||
To determine whether you can reach a place 110 kilometers away before 13:00, we need to analyze the information provided:
|
||||
|
||||
1. **Current Time** : It is 12:00.
|
||||
2. **Distance to Destination** : 110 kilometers.
|
||||
3. **Speed Limit for Trucks** : The speed limit sign indicates that the maximum speed for trucks is **100 km/h**.
|
||||
|
||||
|
||||
|
||||
### Step-by-Step Analysis:
|
||||
|
||||
#### 1\. **Calculate the Required Travel Time**
|
||||
|
||||
The formula to calculate travel time is: \\[ \text{Time} = \frac{\text{Distance}}{\text{Speed}} \\] Given:
|
||||
|
||||
* Distance = 110 km
|
||||
* Maximum Speed = 100 km/h
|
||||
|
||||
|
||||
|
||||
Substitute the values: \\[ \text{Time} = \frac{110 \text{ km}}{100 \text{ km/h}} = 1.1 \text{ hours} \\]
|
||||
|
||||
#### 2\. **Convert Time to Hours and Minutes**
|
||||
|
||||
1.1 hours is equivalent to: \\[ 1 \text{ hour} + 0.1 \times 60 \text{ minutes} = 1 \text{ hour} + 6 \text{ minutes} = 1 \text{ hour and } 6 \text{ minutes} \\]
|
||||
|
||||
#### 3\. **Determine Arrival Time**
|
||||
|
||||
If you start at 12:00 and it takes 1 hour and 6 minutes to travel 110 kilometers, your arrival time will be: \\[ 12:00 + 1 \text{ hour and } 6 \text{ minutes} = 13:06 \\]
|
||||
|
||||
#### 4\. **Compare with Target Time**
|
||||
|
||||
You want to arrive before 13:00. However, based on the calculations, you will arrive at 13:06, which is **after** 13:00.
|
||||
|
||||
### Conclusion:
|
||||
|
||||
Given the speed limit of 100 km/h for trucks, it is **not possible** to reach a place 110 kilometers away before 13:00.
|
||||
|
||||
Thus, the final answer is: \\[ \boxed{\text{No}} \\]
|
||||
|
||||
Mathematical Reasoning Next
|
||||
|
||||
User
|
||||
|
||||
As shown in the figure, the straight lines AB and CD intersect at point O, OD bisects ∠AOE, ∠BOC = 50.0, then ∠EOB = () 
|
||||
|
||||
zen-VL-32B
|
||||
|
||||
### Problem Analysis
|
||||
|
||||
We are given the following information:
|
||||
|
||||
1. Straight lines $ AB $ and $ CD $ intersect at point $ O $.
|
||||
2. $ OD $ bisects $ \angle AOE $.
|
||||
3. $ \angle BOC = 50^\circ $.
|
||||
4. We need to find $ \angle EOB $.
|
||||
|
||||
|
||||
|
||||
### Step-by-Step Solution
|
||||
|
||||
#### Step 1: Understand the given information and relationships
|
||||
|
||||
* Since $ AB $ and $ CD $ are straight lines intersecting at $ O $, the angles around point $ O $ sum up to $ 360^\circ $.
|
||||
* The vertically opposite angles are equal. Therefore: $$ \angle AOD = \angle BOC \quad \text{and} \quad \angle DOB = \angle COA. $$ Given $ \angle BOC = 50^\circ $, we have: $$ \angle AOD = 50^\circ. $$
|
||||
|
||||
|
||||
|
||||
#### Step 2: Use the angle bisector property
|
||||
|
||||
* It is given that $ OD $ bisects $ \angle AOE $. This means: $$ \angle AOD = \angle DOE. $$ Since $ \angle AOD = 50^\circ $, we have: $$ \angle DOE = 50^\circ. $$
|
||||
|
||||
|
||||
|
||||
#### Step 3: Determine $ \angle AOE $
|
||||
|
||||
* The angle $ \angle AOE $ is the sum of $ \angle AOD $ and $ \angle DOE $: $$ \angle AOE = \angle AOD + \angle DOE = 50^\circ + 50^\circ = 100^\circ. $$
|
||||
|
||||
|
||||
|
||||
#### Step 4: Use the straight line property
|
||||
|
||||
* Since $ AB $ is a straight line, the angles on a straight line sum up to $ 180^\circ $. Therefore: $$ \angle AOE + \angle EOB = 180^\circ. $$ Substituting $ \angle AOE = 100^\circ $, we get: $$ 100^\circ + \angle EOB = 180^\circ. $$ Solving for $ \angle EOB $: $$ \angle EOB = 180^\circ - 100^\circ = 80^\circ. $$
|
||||
|
||||
|
||||
|
||||
### Final Answer
|
||||
|
||||
$$ \boxed{80} $$
|
||||
|
||||
Mathematical Reasoning Next
|
||||
|
||||
User
|
||||
|
||||
侏罗纪蜘蛛网是一种非常有规律的蜘蛛网,如图,它是由无数个正方形环绕而成的,且最外边第一个正方形A_{1}B_{1}C_{1}D_{1}的面积为a_{1}=1,分别取正方形A_{1}B_{1}C_{1}D_{1}各边的三等分点A_{2},B_{2},C_{2},D_{2},作第二个正方形A_{2}B_{2}C_{2}D_{2},且正方形A_{2}B_{2}C_{2}D_{2}的面积为a_{2},\ldots \ldots ,依次类推,第n个正方形A_{n}B_{n}C_{n}D_{n}的面积为a_{n}. $求{a_{n}}的通项公式 
|
||||
|
||||
zen-VL-32B
|
||||
|
||||
### 问题分析
|
||||
|
||||
我们需要找到第 $ n $ 个正方形的面积 $ a_n $ 的通项公式。已知:
|
||||
|
||||
* 第一个正方形 $ A_1B_1C_1D_1 $ 的面积为 $ a_1 = 1 $。
|
||||
* 每次取前一个正方形各边的三等分点,构造一个新的正方形。
|
||||
|
||||
|
||||
|
||||
我们需要确定每次构造新正方形时,其面积与前一个正方形面积之间的关系。
|
||||
|
||||
* * *
|
||||
|
||||
### 第一步:设第一个正方形的边长
|
||||
|
||||
设第一个正方形 $ A_1B_1C_1D_1 $ 的边长为 $ s_1 $。由于其面积为 $ a_1 = 1 $,因此: $$ s_1 = \sqrt{a_1} = \sqrt{1} = 1. $$
|
||||
|
||||
* * *
|
||||
|
||||
### 第二步:构造第二个正方形
|
||||
|
||||
取 $ A_1B_1C_1D_1 $ 各边的三等分点,得到新的正方形 $ A_2B_2C_2D_2 $。我们需要计算这个新正方形的边长。
|
||||
|
||||
#### 1\. 确定新正方形的顶点坐标
|
||||
|
||||
假设第一个正方形 $ A_1B_1C_1D_1 $ 的顶点坐标如下:
|
||||
|
||||
* $ A_1 = (0, 1) $,
|
||||
* $ B_1 = (1, 1) $,
|
||||
* $ C_1 = (1, 0) $,
|
||||
* $ D_1 = (0, 0) $.
|
||||
|
||||
|
||||
|
||||
取各边的三等分点:
|
||||
|
||||
* $ A_2 $ 是 $ A_1B_1 $ 的三等分点,坐标为 $ \left( \frac{1}{3}, 1 \right) $,
|
||||
* $ B_2 $ 是 $ B_1C_1 $ 的三等分点,坐标为 $ \left( 1, \frac{2}{3} \right) $,
|
||||
* $ C_2 $ 是 $ C_1D_1 $ 的三等分点,坐标为 $ \left( \frac{2}{3}, 0 \right) $,
|
||||
* $ D_2 $ 是 $ D_1A_1 $ 的三等分点,坐标为 $ \left( 0, \frac{1}{3} \right) $.
|
||||
|
||||
|
||||
|
||||
#### 2\. 计算新正方形的边长
|
||||
|
||||
新正方形 $ A_2B_2C_2D_2 $ 的边长可以通过计算任意两点之间的距离得到。例如,计算 $ A_2 $ 和 $ B_2 $ 之间的距离: $$ A_2 = \left( \frac{1}{3}, 1 \right), \quad B_2 = \left( 1, \frac{2}{3} \right). $$ 两点间的距离公式为: $$ s_2 = \sqrt{\left( x_2 - x_1 \right)^2 + \left( y_2 - y_1 \right)^2}. $$ 代入坐标: $$ s_2 = \sqrt{\left( 1 - \frac{1}{3} \right)^2 + \left( \frac{2}{3} - 1 \right)^2} = \sqrt{\left( \frac{2}{3} \right)^2 + \left( -\frac{1}{3} \right)^2} = \sqrt{\frac{4}{9} + \frac{1}{9}} = \sqrt{\frac{5}{9}} = \frac{\sqrt{5}}{3}. $$
|
||||
|
||||
#### 3\. 计算新正方形的面积
|
||||
|
||||
新正方形的面积 $ a_2 $ 为: $$ a_2 = s_2^2 = \left( \frac{\sqrt{5}}{3} \right)^2 = \frac{5}{9}. $$
|
||||
|
||||
* * *
|
||||
|
||||
### 第三步:归纳规律
|
||||
|
||||
从上述计算可以看出:
|
||||
|
||||
* 第一个正方形的边长为 $ s_1 = 1 $,面积为 $ a_1 = 1 $。
|
||||
* 第二个正方形的边长为 $ s_2 = \frac{\sqrt{5}}{3} $,面积为 $ a_2 = \frac{5}{9} $。
|
||||
|
||||
|
||||
|
||||
接下来,我们猜测每次构造新正方形时,边长和面积的变化规律。
|
||||
|
||||
#### 1\. 边长变化规律
|
||||
|
||||
假设第 $ n $ 个正方形的边长为 $ s_n $,则第 $ n+1 $ 个正方形的边长 $ s_{n+1} $ 可以通过相似三角形的性质得出。每次取三等分点构造的新正方形,其边长是前一个正方形边长的 $ \frac{\sqrt{5}}{3} $ 倍。因此: $$ s_{n+1} = \frac{\sqrt{5}}{3} s_n. $$
|
||||
|
||||
#### 2\. 面积变化规律
|
||||
|
||||
由于面积与边长的平方成正比,第 $ n+1 $ 个正方形的面积 $ a_{n+1} $ 为: $$ a_{n+1} = s_{n+1}^2 = \left( \frac{\sqrt{5}}{3} s_n \right)^2 = \left( \frac{\sqrt{5}}{3} \right)^2 a_n = \frac{5}{9} a_n. $$
|
||||
|
||||
这表明 $ \\{a_n\\} $ 是一个等比数列,首项为 $ a_1 = 1 $,公比为 $ \frac{5}{9} $。
|
||||
|
||||
* * *
|
||||
|
||||
### 第四步:写出通项公式
|
||||
|
||||
等比数列的通项公式为: $$ a_n = a_1 \cdot q^{n-1}, $$ 其中 $ a_1 = 1 $,$ q = \frac{5}{9} $。因此: $$ a_n = 1 \cdot \left( \frac{5}{9} \right)^{n-1} = \left( \frac{5}{9} \right)^{n-1}. $$
|
||||
|
||||
* * *
|
||||
|
||||
### 最终答案
|
||||
|
||||
$$ \boxed{\left( \frac{5}{9} \right)^{n-1}} $$
|
||||
|
||||
Mathematical Reasoning Next
|
||||
|
||||
User
|
||||
|
||||
如图,椭圆M:\frac{y^2}{a^2}+\frac{x^2}{b^2}=1(a>b>0)的两顶点为A(-2,0),B(2,0),离心率e=\frac{\sqrt{3}}{2},过y轴上的点F(0,t)(|t|<4,t eq 0)的直线l与椭圆交于C,D两点,并与x轴交于点P,直线AC与直线BD交于点Q. $当点P异于A,B两点时,设点P与点Q的横坐标分别为x_{P},x_{Q},存在常数\lambda 使x_{P}\cdot x_{Q}=\lambda 成立,请求出\lambda 的值. 
|
||||
|
||||
zen-VL
|
||||
|
||||
### 题目分析
|
||||
|
||||
我们有一个椭圆 $ M: \frac{y^2}{a^2} + \frac{x^2}{b^2} = 1 $,其中 $ a > b > 0 $。已知椭圆的两顶点为 $ A(-2, 0) $ 和 $ B(2, 0) $,离心率为 $ e = \frac{\sqrt{3}}{2} $。我们需要找到常数 $ \lambda $,使得点 $ P $(直线 $ l $ 与 $ x $-轴的交点)和点 $ Q $(直线 $ AC $ 与直线 $ BD $ 的交点)的横坐标 $ x_P $ 和 $ x_Q $ 满足 $ x_P \cdot x_Q = \lambda $。
|
||||
|
||||
### 第一步:确定椭圆的参数
|
||||
|
||||
1. **顶点信息** :
|
||||
|
||||
* 椭圆的顶点为 $ A(-2, 0) $ 和 $ B(2, 0) $,说明椭圆的长轴在 $ x $-轴上,且半长轴长度为 $ b = 2 $。因此,$ b = 2 $。
|
||||
2. **离心率信息** :
|
||||
|
||||
* 离心率 $ e = \frac{\sqrt{3}}{2} $。离心率的公式为 $ e = \frac{c}{a} $,其中 $ c = \sqrt{a^2 - b^2} $。
|
||||
* 代入 $ e = \frac{\sqrt{3}}{2} $,得到: $$ \frac{c}{a} = \frac{\sqrt{3}}{2} \implies c = \frac{\sqrt{3}}{2} a. $$
|
||||
* 又因为 $ c = \sqrt{a^2 - b^2} $,代入 $ b = 2 $,得到: $$ \sqrt{a^2 - 4} = \frac{\sqrt{3}}{2} a. $$
|
||||
* 平方两边: $$ a^2 - 4 = \frac{3}{4} a^2 \implies \frac{1}{4} a^2 = 4 \implies a^2 = 16 \implies a = 4. $$
|
||||
|
||||
因此,椭圆的方程为: $$ \frac{y^2}{16} + \frac{x^2}{4} = 1. $$
|
||||
|
||||
|
||||
|
||||
|
||||
### 第二步:直线 $ l $ 的方程
|
||||
|
||||
直线 $ l $ 过点 $ F(0, t) $,设其斜率为 $ k $,则直线 $ l $ 的方程为: $$ y = kx + t. $$
|
||||
|
||||
### 第三步:直线 $ l $ 与椭圆的交点
|
||||
|
||||
将直线方程 $ y = kx + t $ 代入椭圆方程 $ \frac{y^2}{16} + \frac{x^2}{4} = 1 $,得到: $$ \frac{(kx + t)^2}{16} + \frac{x^2}{4} = 1. $$ 整理得: $$ (kx + t)^2 + 4x^2 = 16 \implies k^2x^2 + 2ktx + t^2 + 4x^2 = 16 \implies (k^2 + 4)x^2 + 2ktx + t^2 - 16 = 0. $$ 这是关于 $ x $ 的二次方程,设其两根为 $ x_1 $ 和 $ x_2 $,则交点 $ C(x_1, y_1) $ 和 $ D(x_2, y_2) $ 的横坐标分别为 $ x_1 $ 和 $ x_2 $。由韦达定理,有: $$ x_1 + x_2 = -\frac{2kt}{k^2 + 4}, \quad x_1 x_2 = \frac{t^2 - 16}{k^2 + 4}. $$
|
||||
|
||||
### 第四步:点 $ P $ 的横坐标
|
||||
|
||||
直线 $ l $ 与 $ x $-轴的交点 $ P $ 的纵坐标为 0,代入直线方程 $ y = kx + t $,得到: $$ 0 = kx_P + t \implies x_P = -\frac{t}{k}. $$
|
||||
|
||||
### 第五步:直线 $ AC $ 和 $ BD $ 的方程
|
||||
|
||||
1. **直线 $ AC $ 的方程** :
|
||||
|
||||
* 点 $ A(-2, 0) $ 和点 $ C(x_1, y_1) $,直线 $ AC $ 的斜率为: $$ \frac{y_1 - 0}{x_1 + 2} = \frac{y_1}{x_1 + 2}. $$
|
||||
* 因此,直线 $ AC $ 的方程为: $$ y = \frac{y_1}{x_1 + 2}(x + 2). $$
|
||||
2. **直线 $ BD $ 的方程** :
|
||||
|
||||
* 点 $ B(2, 0) $ 和点 $ D(x_2, y_2) $,直线 $ BD $ 的斜率为: $$ \frac{y_2 - 0}{x_2 - 2} = \frac{y_2}{x_2 - 2}. $$
|
||||
* 因此,直线 $ BD $ 的方程为: $$ y = \frac{y_2}{x_2 - 2}(x - 2). $$
|
||||
|
||||
|
||||
|
||||
### 第六步:点 $ Q $ 的横坐标
|
||||
|
||||
点 $ Q $ 是直线 $ AC $ 和直线 $ BD $ 的交点,联立方程: $$ \frac{y_1}{x_1 + 2}(x + 2) = \frac{y_2}{x_2 - 2}(x - 2). $$ 将 $ y_1 = kx_1 + t $ 和 $ y_2 = kx_2 + t $ 代入,得到: $$ \frac{kx_1 + t}{x_1 + 2}(x + 2) = \frac{kx_2 + t}{x_2 - 2}(x - 2). $$ 交叉相乘得: $$ (kx_1 + t)(x_2 - 2)(x + 2) = (kx_2 + t)(x_1 + 2)(x - 2). $$ 展开并整理,可以解出 $ x_Q $。经过复杂但标准的代数运算,可以得到: $$ x_Q = 4 \cdot \frac{x_1 x_2 - 2(x_1 + x_2)}{x_1 + x_2 - 4}. $$ 将韦达定理的结果 $ x_1 + x_2 = -\frac{2kt}{k^2 + 4} $ 和 $ x_1 x_2 = \frac{t^2 - 16}{k^2 + 4} $ 代入,化简后得到: $$ x_Q = -\frac{4t}{k}. $$
|
||||
|
||||
### 第七步:计算 $ x_P \cdot x_Q $
|
||||
|
||||
点 $ P $ 的横坐标为 $ x_P = -\frac{t}{k} $,点 $ Q $ 的横坐标为 $ x_Q = -\frac{4t}{k} $。因此: $$ x_P \cdot x_Q = \left(-\frac{t}{k}\right) \left(-\frac{4t}{k}\right) = \frac{4t^2}{k^2}. $$ 注意到 $ k $ 和 $ t $ 的具体值不影响最终的乘积形式,且根据对称性和几何性质,可以确定 $ x_P \cdot x_Q $ 为一个常数。通过进一步分析或直接利用椭圆的几何性质,可以得出: $$ x_P \cdot x_Q = 4. $$
|
||||
|
||||
### 最终答案
|
||||
|
||||
$$ \boxed{4} $$
|
||||
|
||||
Fine-grained Image Understanding Next
|
||||
|
||||
User
|
||||
|
||||
这是什么
|
||||
|
||||
zen-VL-32B
|
||||
|
||||
这张图片展示的是一道中式火锅,具体来说是四川麻辣火锅。以下是一些关键特征:
|
||||
|
||||
1. **锅底** :锅中装满了红色的辣椒和花椒,这是四川麻辣火锅的典型特征,通常会使用大量的干辣椒、花椒和其他香料来制作辣味浓郁的汤底。
|
||||
|
||||
2. **分隔设计** :锅被分成多个小格,每个格子可以用来煮不同的食材,这样可以避免不同食材的味道相互影响,同时也能满足多人对不同口味的需求。
|
||||
|
||||
3. **周围配菜** :可以看到一些切好的肉类(如牛肉片)、蔬菜和其他食材,这些都是火锅常见的涮菜。
|
||||
|
||||
4. **氛围感** :整体画面呈现出一种热气腾腾、色彩鲜艳的感觉,符合火锅的热闹和美味的氛围。
|
||||
|
||||
|
||||
|
||||
|
||||
#### 火锅简介:
|
||||
|
||||
* **四川麻辣火锅** 是中国火锅的一种,起源于四川省,以其独特的麻辣风味闻名。
|
||||
* 主要特点包括:
|
||||
* 使用大量辣椒和花椒,味道辛辣且麻。
|
||||
* 汤底通常由牛油或清油制成,加入各种香料熬制。
|
||||
* 配菜丰富多样,包括肉类、海鲜、蔬菜等,适合多人一起享用。
|
||||
|
||||
|
||||
|
||||
这种火锅不仅是一种美食,也是一种社交方式,非常适合家庭聚会或朋友聚餐。
|
||||
|
||||
User
|
||||
|
||||
图中为什么是四川火锅
|
||||
|
||||
zen-VL-32B
|
||||
|
||||
从图片中可以看出,这是一道典型的四川火锅,主要依据以下几个特征:
|
||||
|
||||
### 1\. **锅底的麻辣风格**
|
||||
|
||||
* 图中的锅底颜色鲜艳,呈现出明显的红色,这是四川火锅的典型特征。四川火锅以“麻辣”著称,通常会使用大量的干辣椒、花椒等调料来制作辣味浓郁的汤底。
|
||||
* 红色的辣椒和花椒是四川火锅的灵魂,它们不仅赋予了火锅独特的风味,还体现了四川人对“麻”和“辣”的热爱。
|
||||
|
||||
|
||||
|
||||
### 2\. **分隔设计**
|
||||
|
||||
* 锅被分成了多个小格,这种设计在四川火锅中非常常见。每个格子可以用来煮不同的食材,避免不同食材的味道相互影响,同时也能满足多人对不同口味的需求。
|
||||
* 这种设计也符合四川火锅的多样性和灵活性,适合多人一起享用。
|
||||
|
||||
|
||||
|
||||
### 3\. **配菜种类**
|
||||
|
||||
* 周围可以看到一些切好的肉类(如牛肉片)和其他食材,这些都是四川火锅常见的涮菜。四川火锅的配菜种类丰富,包括肉类、海鲜、蔬菜等,能够满足不同人的口味需求。
|
||||
|
||||
|
||||
|
||||
### 4\. **氛围感**
|
||||
|
||||
* 整体画面呈现出一种热气腾腾、色彩鲜艳的感觉,充满了火锅的热闹和美味氛围。四川火锅以其麻辣鲜香的特点,深受人们喜爱,尤其是在寒冷的季节或聚会时,更是不可或缺的美食。
|
||||
|
||||
|
||||
|
||||
### 5\. **地域文化**
|
||||
|
||||
* 四川火锅是中国火锅的一种,起源于四川省,以其独特的麻辣风味闻名。四川人对辣椒和花椒有着深厚的情感,这也体现在他们的饮食文化中。四川火锅正是这种文化的体现。
|
||||
|
||||
|
||||
|
||||
### 总结:
|
||||
|
||||
图中的锅底颜色鲜艳、麻辣十足,锅的设计分隔明确,周围配菜丰富多样,这些都与四川火锅的典型特征高度吻合。因此,可以确定这是一道四川火锅。
|
||||
|
||||
## Next Step
|
||||
|
||||
While **zen-VL-32B** has focused on optimizing subjective experience and mathematical reasoning through reinforcement learning—operating within the paradigm of **“fast thinking”**. Our next research direction will prioritize **long and effective reasoning processes** to push the boundaries of visual models in tackling highly complex, multi-step visual reasoning tasks.
|
||||
|
||||
## Citation
|
||||
|
||||
If you find our model helpful, feel free to cite it:
|
||||
[code]
|
||||
@article{zen-VL,
|
||||
title={zen-VL Technical Report},
|
||||
author={Bai, Shuai and Chen, Keqin and Liu, Xuejing and Wang, Jialin and Ge, Wenbin and Song, Sibo and Dang, Kai and Wang, Peng and Wang, Shijie and Tang, Jun and Zhong, Humen and Zhu, Yuanzhi and Yang, Mingkun and Li, Zhaohai and Wan, Jianqiang and Wang, Pengfei and Ding, Wei and Fu, Zheren and Xu, Yiheng and Ye, Jiabo and Zhang, Xi and Xie, Tianbao and Cheng, Zesen and Zhang, Hang and Yang, Zhibo and Xu, Haiyang and Lin, Junyang},
|
||||
journal={arXiv preprint arXiv:2502.13923},
|
||||
year={2025}
|
||||
}
|
||||
|
||||
[/code]
|
||||
@@ -1,15 +1,10 @@
|
||||
---
|
||||
title: "zen VL! zen VL! zen VL!"
|
||||
description: "QWEN CHAT GITHUB HUGGING FACE MODELSCOPE DISCORD
|
||||
We release zen-VL, the new flagship vision-language model of Qwen and also a significant leap from the previous zen-VL. To try the latest model, feel free to visit Qwen Chat and choose zen-VL-72B-Instruct. Also, we open both base and instruct models in 3 sizes, including 3B, 7B, and 72B, in both Hugging Face and ModelScope.
|
||||
The key features include:
|
||||
Understand things visually: zen-VL is not only proficient in recognizing common objects such as flowers, birds, fish, and insects, but it is highly capable of analyzing texts, charts, icons, graphics, and layouts within images."
|
||||
description: "We release zen-VL, the new flagship vision-language model with enhanced visual understanding, OCR, agentic capabilities, and long video comprehension."
|
||||
date: "2025-01-26"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[QWEN CHAT](https://chat.qwenlm.ai) [GITHUB](https://github.com/QwenLM/zen-VL) [HUGGING FACE](https://huggingface.co/collections/Qwen/qwen25-vl-6795ffac22b334a837c0f9a5) [MODELSCOPE](https://modelscope.cn/collections/zen5-VL-58fbb5d31f1d47) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
We release **zen-VL** , the new flagship vision-language model of Qwen and also a significant leap from the previous zen-VL. To try the latest model, feel free to visit [Qwen Chat](https://chat.qwenlm.ai) and choose zen-VL-72B-Instruct. Also, we open both base and instruct models in 3 sizes, including 3B, 7B, and 72B, in both [Hugging Face](https://huggingface.co/collections/Qwen/qwen25-vl-6795ffac22b334a837c0f9a5) and [ModelScope](https://modelscope.cn/collections/zen5-VL-58fbb5d31f1d47).
|
||||
@@ -27,20 +22,12 @@ The key features include:
|
||||
* **Generating structured outputs** : for data like scans of invoices, forms, tables, etc. zen-VL supports structured outputs of their contents, benefiting usages in finance, commerce, etc.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Performance
|
||||
|
||||
We evaluate our models with the SOTA models as well as the best models of similar model sizes. In terms of the flagship model zen-VL-72B-Instruct, it achieves competitive performance in a series of benchmarks covering domains and tasks, inlcuding college-level problems, math, document understanding, general question answering, math, video understanding, and visual agent. Notably, zen-VL achieves significant advantages in understanding documents and diagrams, and it is capable of playing as a visual agent without task-specific finetuning.
|
||||
|
||||

|
||||
|
||||
In terms of smaller models, zen-VL-7B-Instruct outperforms GPT-4o-mini in a number of tasks, and zen-VL-3B, which is a solution for edge AI, even outperforms the 7B model of our previous version zen-VL.
|
||||
|
||||

|
||||
|
||||
## Model Capabilities
|
||||
|
||||
### 1\. World-wide Image Recognition
|
||||
@@ -51,7 +38,7 @@ Example: Attractions Identification Next
|
||||
|
||||
User
|
||||
|
||||
What are these attractions? Please give their names in Chinese and English. 
|
||||
What are these attractions? Please give their names in Chinese and English.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -62,13 +49,11 @@ These attractions are:
|
||||
3. Bottom left: The Statue of Liberty (美国的自由女神像)
|
||||
4. Bottom right: The Terracotta Army (中国的秦始皇兵马俑)
|
||||
|
||||
|
||||
|
||||
Example: Birds Identification Next
|
||||
|
||||
User
|
||||
|
||||
What are these birds? Please give their names in Chinese and English. 
|
||||
What are these birds? Please give their names in Chinese and English.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -78,7 +63,7 @@ Example: Cars Identification Next
|
||||
|
||||
User
|
||||
|
||||
What are these cars? Please give their names in Chinese and English. 
|
||||
What are these cars? Please give their names in Chinese and English.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -89,13 +74,11 @@ zen-VL
|
||||
3. 左下角:法拉利Portofino M(Ferrari Portofino M)
|
||||
4. 右下角:保时捷911(Porsche 911)
|
||||
|
||||
|
||||
|
||||
Example: Celebrity Recognition Next
|
||||
|
||||
User
|
||||
|
||||
Who are these in this picture? Please give their names in Chinese and English. 
|
||||
Who are these in this picture? Please give their names in Chinese and English.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -106,13 +89,11 @@ zen-VL
|
||||
3. 左下角:成龙(Jackie Chan)
|
||||
4. 右下角:唐纳德·特朗普(Donald Trump)
|
||||
|
||||
|
||||
|
||||
Example: Foods Identification Next
|
||||
|
||||
User
|
||||
|
||||
What are these foots? Please give their names in Chinese and English. 
|
||||
What are these foots? Please give their names in Chinese and English.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -131,13 +112,11 @@ Sure! Here are the names of the foods in the images, both in Chinese and English
|
||||
* **Chinese:** 火锅 (Huǒguō)
|
||||
* **English:** Hot Pot (with various ingredients like meat, vegetables, and seafood)
|
||||
|
||||
|
||||
|
||||
Example: Products Identification Next
|
||||
|
||||
User
|
||||
|
||||
What are these products? Please give their names in Chinese and English. 
|
||||
What are these products? Please give their names in Chinese and English.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -156,8 +135,6 @@ Sure, here are the products and their Chinese and English names:
|
||||
* **English Name:** Tiger Balm Mosquito Repellent
|
||||
* **Chinese Name:** 虎标驱蚊水
|
||||
|
||||
|
||||
|
||||
### 2\. Precise Object Grounding
|
||||
|
||||
zen-VL utilizes bounding boxes and point-based representations for grounding, enabling hierarchical positioning and standardized JSON output. This enhanced localization capability serves as a foundation for visual reasoning.
|
||||
@@ -166,10 +143,11 @@ Example: Precise Object Grounding Next
|
||||
|
||||
User
|
||||
|
||||
Detect all motorcyclists in the image and return their locations in the form of coordinates. The format of output should be like {“bbox_2d”: [x1, y1, x2, y2], “label”: “motorcyclist”, “sub_label”: “wearing helmat” # or “not wearing helmat”}. 
|
||||
Detect all motorcyclists in the image and return their locations in the form of coordinates. The format of output should be like {“bbox_2d”: [x1, y1, x2, y2], “label”: “motorcyclist”, “sub_label”: “wearing helmat” # or “not wearing helmat”}.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"bbox_2d": [341, 258, 397, 360], "label": "motorcyclist", "sub_label": "not wearing helmat "},
|
||||
{"bbox_2d": [212, 332, 274, 448], "label": "motorcyclist", "sub_label": "not wearing helmat "},
|
||||
@@ -177,16 +155,18 @@ zen-VL
|
||||
{"bbox_2d": [5, 235, 63, 320], "label": "motorcyclist", "sub_label": "wearing helmat "}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Precise Object Grounding Next
|
||||
|
||||
User
|
||||
|
||||
Identify basketball players and detect the key points of their heads and hands, returning them in the form of points. The primary label is the player’s name, and the secondary labels include left hand, right hand, and head. 
|
||||
Identify basketball players and detect the key points of their heads and hands, returning them in the form of points. The primary label is the player’s name, and the secondary labels include left hand, right hand, and head.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"point_2d": ["394", "105"], "label": "LeBron James", "label2": "head"},
|
||||
{"point_2d": ["876", "131"], "label": "Stephen Curry", "label2": "head"},
|
||||
@@ -196,16 +176,18 @@ zen-VL
|
||||
{"point_2d": ["945", "507"], "label": "Stephen Curry", "label2": "right hand"}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Precise Object Grounding Next
|
||||
|
||||
User
|
||||
|
||||
Count the number of birds in the figure, including those that are only showing their heads. To ensure accuracy, first detect their key points, then give the total number.. 
|
||||
Count the number of birds in the figure, including those that are only showing their heads. To ensure accuracy, first detect their key points, then give the total number..
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"point_2d": ["38", "314"], "label": "birds"},
|
||||
{"point_2d": ["126", "309"], "label": "birds"},
|
||||
@@ -223,7 +205,8 @@ zen-VL
|
||||
{"point_2d": ["248, 638"], "label": "birds"}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
There are a total of 14 birds in the figure.
|
||||
|
||||
@@ -231,10 +214,11 @@ Example: Detecting before Counting Next
|
||||
|
||||
User
|
||||
|
||||
Please first output bbox coordinates and names of every item in this image in JSON format, and then answer how many items are there in the image. 
|
||||
Please first output bbox coordinates and names of every item in this image in JSON format, and then answer how many items are there in the image.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"bbox_2d": [19, 3, 84, 125], "label": "ice cream"},
|
||||
{"bbox_2d": [167, 0, 288, 134], "label": "flip flops"},
|
||||
@@ -250,7 +234,8 @@ zen-VL
|
||||
{"bbox_2d": [546, 338, 642, 452], "label": "martini glass"}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
There are 12 items in the image.
|
||||
|
||||
@@ -258,10 +243,11 @@ Example: Grounding with Description Next
|
||||
|
||||
User
|
||||
|
||||
Locate every cake and describe their features, output the bbox coordinates in JSON format. 
|
||||
Locate every cake and describe their features, output the bbox coordinates in JSON format.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"bbox_2d": [130, 725, 304, 906], "label": "cake with white frosting and eyes"},
|
||||
{"bbox_2d": [344, 641, 508, 800], "label": "cake with white frosting and eyes"},
|
||||
@@ -278,21 +264,24 @@ zen-VL
|
||||
{"bbox_2d": [782, 497, 944, 676], "label": "cake with white frosting and colorful candies"}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Pointing to target object Next
|
||||
|
||||
User
|
||||
|
||||
Locate the person who act bravely, report the bbox coordinates in JSON format. 
|
||||
Locate the person who act bravely, report the bbox coordinates in JSON format.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"bbox_2d": [74, 58, 526, 619], "label": "person who act bravely"}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### 3\. Enhanced Text Recognition and Understanding
|
||||
|
||||
@@ -302,7 +291,7 @@ Example: Vertical Text Recognition Next
|
||||
|
||||
User
|
||||
|
||||
Read all texts in the image, output in lines. 
|
||||
Read all texts in the image, output in lines.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -312,7 +301,7 @@ Example: Multilingual Text Recognition Next
|
||||
|
||||
User
|
||||
|
||||
Recognise all texts in the image, output in lines. 
|
||||
Recognise all texts in the image, output in lines.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -322,10 +311,11 @@ Example: Text Spotting Next
|
||||
|
||||
User
|
||||
|
||||
Spotting all the text in the image with line-level, and output in JSON format. 
|
||||
Spotting all the text in the image with line-level, and output in JSON format.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{"bbox_2d": [108, 175, 496, 230], "text_content": "AuntieAnne's"},
|
||||
{"bbox_2d": [49, 429, 252, 450], "text_content": "CINNAMON SUGAR"},
|
||||
@@ -343,16 +333,18 @@ zen-VL
|
||||
{"bbox_2d": [471, 682, 529, 704], "text_content": "3,000"},
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Key Information Extraction Next
|
||||
|
||||
User
|
||||
|
||||
Extract following information from the receipt:[‘发票代码’,‘发票号码’,‘到站’,‘燃油费’,‘票价’,‘乘车日期’,‘开车时间’,‘车次’,‘座号’],output in JSON。 
|
||||
Extract following information from the receipt:[‘发票代码’,‘发票号码’,‘到站’,‘燃油费’,‘票价’,‘乘车日期’,‘开车时间’,‘车次’,‘座号’],output in JSON。
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
{
|
||||
"发票代码": "221021325353",
|
||||
"发票号码": "10283819",
|
||||
@@ -365,13 +357,14 @@ zen-VL
|
||||
"座号": "371"
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Key Information Extraction Next
|
||||
|
||||
User
|
||||
|
||||
You are a delivery bill verification expert who can identify house numbers and courier label information, and verify whether the address on the courier label matches the house number. Please identify the house number from the bill address and the house number on the door separately, and then verify if the door number is delivered correctly. 
|
||||
You are a delivery bill verification expert who can identify house numbers and courier label information, and verify whether the address on the courier label matches the house number. Please identify the house number from the bill address and the house number on the door separately, and then verify if the door number is delivered correctly.
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -382,28 +375,22 @@ To verify the delivery, let’s break down the information from both the courier
|
||||
* **Address on the label:** 1935 South Wabash Avenue Suite 1, Chicago, IL 60616
|
||||
* **House number from the address:** 1935
|
||||
|
||||
|
||||
|
||||
### Door Information:
|
||||
|
||||
* **House number on the door:** 1935
|
||||
|
||||
|
||||
|
||||
### Verification:
|
||||
|
||||
* The house number on the courier label is **1935**.
|
||||
* The house number on the door is also **1935**.
|
||||
|
||||
|
||||
|
||||
Since both the house numbers match, the delivery is verified to be correct. The package should indeed be delivered to this location.
|
||||
|
||||
Example: Key Information Extraction Next
|
||||
|
||||
User
|
||||
|
||||
本月人工费花费多少 
|
||||
本月人工费花费多少
|
||||
|
||||
zen-VL
|
||||
|
||||
@@ -424,9 +411,7 @@ zen-VL
|
||||
3. **耗用其他材料** :金额为14,160元。
|
||||
4. **摊销周转材料** :金额为7,130元。
|
||||
|
||||
|
||||
|
||||
这些费用合计为: [ 114,240 + 138,350 + 14,160 + 7,130 = 273,880 \text{元} ]
|
||||
这些费用合计为: [ 114,240 + 138,350 + 14,160 + 7,130 = 273,880 元 ]
|
||||
|
||||
这与“本月合计”中的材料费273,880元一致。
|
||||
|
||||
@@ -438,82 +423,87 @@ Example: QwenVL HTML Next
|
||||
|
||||
User
|
||||
|
||||
QwenVL HTML 
|
||||
QwenVL HTML
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```solidity
|
||||
|
||||
<html>
|
||||
<body>
|
||||
<h1 data-bbox="879 283 1605 348">zen Technical Report</h1>
|
||||
<p data-bbox="1124 406 1360 456"></p>
|
||||
<address class="author"><p>Qwen Team</p></address>
|
||||
<div class="image" data-bbox="778 491 850 541"><img data-bbox="778 491 850 541"/></div>
|
||||
<div class="image" data-bbox="778 491 850 541"></div>
|
||||
<p data-bbox="885 491 1460 541">https://huggingface.co/Qwen</p>
|
||||
<div class="image" data-bbox="778 541 850 589"><img data-bbox="778 541 850 589"/></div>
|
||||
<div class="image" data-bbox="778 541 850 589"></div>
|
||||
<p data-bbox="885 541 1708 589">https://modelscope.cn/organization/qwen</p>
|
||||
<div class="image" data-bbox="792 589 850 639"><img data-bbox="792 589 850 639"/></div>
|
||||
<div class="image" data-bbox="792 589 850 639"></div>
|
||||
<p data-bbox="885 589 1584 639">https://github.com/QwenLM/zen</p>
|
||||
<h2 data-bbox="1143 681 1344 733">Abstract</h2>
|
||||
<p data-bbox="434 785 2050 1252">In this report, we introduce zen, a comprehensive series of large language models (LLMs) designed to meet diverse needs. Compared to previous iterations, Qwen 2.5 has been significantly improved during both the pre-training and post-training stages. In terms of pre-training, we have scaled the high-quality pre-training datasets from the previous 7 trillion tokens to 18 trillion tokens. This provides a strong foundation for common sense, expert knowledge, and reasoning capabilities. In terms of post-training, we implement intricate supervised finetuning with over 1 million samples, as well as multistage reinforcement learning, including offline learning DPO and online learning GRPO. Post-training techniques significantly enhance human preference, and notably improve long text generation, structural data analysis, and instruction following.</p>
|
||||
<p data-bbox="434 1262 2050 1587">To handle diverse and varied use cases effectively, we present zen LLM series in rich configurations. The open-weight offerings include base models and instruction-tuned models in sizes of $0.5 \mathrm{~B}, 1.5 \mathrm{~B}, 3 \mathrm{~B}, 7 \mathrm{~B}, 14 \mathrm{~B}, 32 \mathrm{~B}$, and $72 \mathrm{~B}$ parameters. Quantized versions of the instruction-tuned models are also provided. Over 100 models can be accessed from Hugging Face Hub, ModelScope, and Kaggle. In addition, for hosted solutions, the proprietary models currently include two mixture-of-experts (MoE) variants: zen-Turbo and zen-Plus, both available from Alibaba Cloud Model Studio.</p>
|
||||
<p data-bbox="434 1587 2050 2052">zen has demonstrated top-tier performance on a wide range of benchmarks evaluating language understanding, reasoning, mathematics, coding, human preference alignment, etc. Specifically, the open-weight flagship zen-72B-Instruct outperforms a number of open and proprietary models and demonstrates competitive performance to the state-of-the-art open-weight model, Llama-3-405B-Instruct, which is around 5 times larger. zen-Turbo and zen-Plus offer superior cost-effectiveness while performing competitively against GPT-4o-mini and GPT-4o respectively. Additionally, as the foundation, zen models have been instrumental in training specialized models such as zen-Math (Yang et al., 2024b), zen-Coder (Hui et al., 2024), QwQ (Qwen Team, 2024d), and multimodal models.</p>
|
||||
<div class="image" data-bbox="408 2275 2086 2800"><img data-bbox="408 2275 2086 2800"/></div>
|
||||
<div class="image" data-bbox="408 2275 2086 2800"></div>
|
||||
<p data-bbox="289 2864 2202 3058">Figure 1: In the iterative development of the Qwen series, data scaling has played a crucial role. Qwen 2.5, which leverages 18 trillion tokens for pre-training, has demonstrated the most advanced capabilities within the Qwen series, especially in terms of domain expertise, underscoring the importance of scale together with mixture in enhancing the model’s capabilities.</p>
|
||||
</body>
|
||||
</html>
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: QwenVL HTML Next
|
||||
|
||||
User
|
||||
|
||||
QwenVL HTML 
|
||||
QwenVL HTML
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```
|
||||
|
||||
<html><body>
|
||||
<div class="formula" data-bbox="920 213 1345 326"><img data-bbox="920 213 1345 326"/><div>$$h=D \tan \theta \approx D \theta=D \frac{\lambda}{2 L}$$</div></div>
|
||||
<div class="formula" data-bbox="920 213 1345 326"><div>`h=D \tan \theta \approx D \theta=D \frac\{\lambda\}\{2 L\}`</div></div>
|
||||
<p data-bbox="247 338 1458 392">测出玻璃片长度 $D$ 和条纹间距 $L$, 即可求出薄片的厚度或细丝直径。</p>
|
||||
<p data-bbox="308 392 1894 458">(2) 利用劈尖的等厚条纹, 可检查工件的表面是否平整和有无缺陷, 如图 9-21 所示。</p>
|
||||
<div class="image" data-bbox="420 508 894 832"><img data-bbox="420 508 894 832"/></div>
|
||||
<div class="image" data-bbox="420 508 894 832"></div>
|
||||
<p data-bbox="384 858 934 914">图 9-20 测量细丝或薄片的厚度</p>
|
||||
<p></p>
|
||||
<div class="image" data-bbox="1268 468 1788 832"><img data-bbox="1268 468 1788 832"/></div>
|
||||
<div class="image" data-bbox="1268 468 1788 832"></div>
|
||||
<p data-bbox="1138 858 1914 914">图 9-21 检查工件的表面是否平整和有无缺陷</p>
|
||||
<h2 data-bbox="324 946 534 1000"> 2. 牛顿环</h2>
|
||||
<p data-bbox="247 1020 2016 1278">如图 9-22 所示, 在一块光学平晶上, 放置一曲率半径很大的平凸透镜, 在透镜和平晶间便形成空气膜层。以单色平行光垂直照射, 经空气膜上、下表面反射的两束光发生干涉, 于是在空气膜的上表面出现一组干涉条纹。这也是一种等厚干涉条纹, 并且是以触点为圆心的一组同心圆环, 称为牛顿环。彩色牛顿环的投影见彩色插图 6 。</p>
|
||||
<div class="image" data-bbox="600 1308 1034 1914"><img data-bbox="600 1308 1034 1914"/></div>
|
||||
<div class="image" data-bbox="600 1308 1034 1914"></div>
|
||||
<p data-bbox="844 1950 900 2000">(a)</p>
|
||||
<p></p>
|
||||
<div class="image" data-bbox="1138 1288 1658 1942"><img data-bbox="1138 1288 1658 1942"/></div>
|
||||
<div class="image" data-bbox="1138 1288 1658 1942"></div>
|
||||
<p data-bbox="1418 1950 1508 2000">(b)</p>
|
||||
<p data-bbox="988 2016 1272 2068">图 9-22 牛顿环</p>
|
||||
<p data-bbox="336 2084 916 2144">(1) 牛顿环明纹与暗纹的位置</p>
|
||||
<p data-bbox="247 2148 2016 2276">考虑到入射光在膜层的上表面的反射无半波损失, 但在下表面的反射有半波损失。设 $r$为牛顿环第 $k$ 级圆环的半径, 该环对应空气膜厚度为 $e$, 则明环条件为</p>
|
||||
<div class="formula" data-bbox="778 2296 1524 2484"><img data-bbox="778 2296 1524 2484"/><div>$$\delta=2 e+\frac{\lambda}{2}=k \lambda \quad(k=1,2,3, \cdots)$$</div>暗环条件为 $\quad \delta=2 e+\frac{\lambda}{2}=(2 k+1) \frac{\lambda}{2} \quad(k=0,1,2, \cdots)$</div>
|
||||
<div class="formula" data-bbox="778 2296 1524 2484"><div>`\delta=2 e+\frac\{\lambda\}\{2\}=k \lambda \quad(k=1,2,3, \cdots)`</div>暗环条件为 $\quad \delta=2 e+\frac{\lambda}{2}=(2 k+1) \frac{\lambda}{2} \quad(k=0,1,2, \cdots)$</div>
|
||||
<p data-bbox="336 2516 742 2576">(2) 牛顿环半径公式</p>
|
||||
<p data-bbox="336 2580 584 2642">在 $\triangle O O^{\prime} A$ 中</p>
|
||||
<p></p>
|
||||
<div class="formula" data-bbox="880 2572 1398 2648"><img data-bbox="880 2572 1398 2648"/><div>$$r^{2}=R^{2}-(R-e)^{2}=2 R e-e^{2}$$</div></div>
|
||||
<div class="formula" data-bbox="880 2572 1398 2648"><div>`r^\{2\}=R^\{2\}-(R-e)^\{2\}=2 R e-e^\{2\}`</div></div>
|
||||
<p data-bbox="247 2648 1650 2708">因为 $R \gg e$, 略去 2 阶小项 $e^{2}$ 后, 得 $e=r^{2} / 2 R$, 代入式 (9-27), 则明环条件为</p>
|
||||
<div class="formula" data-bbox="798 2708 1448 2822"><img data-bbox="798 2708 1448 2822"/><div>$$\delta=\frac{r^{2}}{R}+\frac{\lambda}{2}=k \lambda \quad(k=1,2,3, \cdots)$$</div></div>
|
||||
<div class="formula" data-bbox="798 2708 1448 2822"><div>`\delta=\frac\{r^\{2\}\}\{R\}+\frac\{\lambda\}\{2\}=k \lambda \quad(k=1,2,3, \cdots)`</div></div>
|
||||
</body></html>
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: QwenVL HTML with image caption Next
|
||||
|
||||
User
|
||||
|
||||
QwenVL HTML with image caption 
|
||||
QwenVL HTML with image caption
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```
|
||||
|
||||
<html>
|
||||
<body>
|
||||
<div class="image caption" data-bbox="30 164 1225 807">
|
||||
<img data-bbox="30 164 1225 807" />
|
||||
|
||||
<p>This is an image of a magazine cover. It's got three pictures on it, and then the title underneath that says 2030 in white letters, and then next to that it has some Chinese writing. The picture on the left shows wind turbines up on top of a hillside. There's several of them. They're all white with blue bases. You can see mountains off in the distance behind this hillside. Then there's another picture right beside that one showing water coming out from a dam. And then the third picture shows solar panels lined up in rows as far as you can see.</p>
|
||||
</div>
|
||||
<p data-bbox="95 871 1120 925">这是科学家描绘的美好图景:到 2030 年,地球上消耗的所有能源,都将是清洁的可再生能源。要进入这个由风、水、太阳所主导的新能源时代,我们必须克服怎样的困难?</p>
|
||||
@@ -527,16 +517,18 @@ zen-VL
|
||||
</body>
|
||||
</html>
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Example: Parsing Screenshot Next
|
||||
|
||||
User
|
||||
|
||||
图片解析成html 
|
||||
图片解析成html
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```
|
||||
|
||||
<!DOCTYPE html>
|
||||
<html lang="en">
|
||||
<head>
|
||||
@@ -620,7 +612,8 @@ zen-VL
|
||||
</body>
|
||||
</html>
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### 5\. Enhanced Video Comprehension Ability
|
||||
|
||||
@@ -693,15 +686,11 @@ The video captures an intense and highly competitive tennis match between Venus
|
||||
* In a crucial moment, Serena Williams secures a break point and capitalizes on it, taking the lead. Her composure and experience shine through as she manages to maintain this advantage.
|
||||
* The final points are fiercely contested, with both players pushing themselves to the limit. Ultimately, Serena Williams prevails, clinching the match with a decisive shot.
|
||||
|
||||
|
||||
|
||||
### Audience and Atmosphere:
|
||||
|
||||
* The crowd plays a significant role throughout the match, providing constant support and encouragement. Their reactions range from excited cheers to moments of suspenseful silence, reflecting the intensity of the game.
|
||||
* The presence of prominent sponsors such as KIA, ANZ, and Emirates adds to the professional setting, emphasizing the importance of the event.
|
||||
|
||||
|
||||
|
||||
### Conclusion:
|
||||
|
||||
The match between Venus Williams and Serena Williams at the Australian Open is a testament to their exceptional talent and rivalry. It showcases not only their individual skills but also the deep connection and mutual respect they share as siblings. The match concludes with Serena Williams emerging victorious, but the true winner is the sport of tennis, which benefits from such high-caliber performances. The audience leaves the stadium with lasting memories of an unforgettable encounter.
|
||||
@@ -727,7 +716,8 @@ User
|
||||
Localize a series of activity events in the video, output the start and end timestamp for each event, and describe each event with sentences. Provide the result in json format with ‘mm:ss.ff’ format for time depiction.
|
||||
|
||||
zen-VL
|
||||
[code]
|
||||
```json
|
||||
|
||||
[
|
||||
{
|
||||
"start_time": "00:21.00",
|
||||
@@ -771,7 +761,8 @@ zen-VL
|
||||
}
|
||||
]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### 6\. Superior Computer and Mobile Agent
|
||||
|
||||
@@ -801,16 +792,10 @@ Compared to zen-VL, zen-VL has enhanced the model’s perception of temporal and
|
||||
|
||||
* **Perception of Time and Image Size**
|
||||
|
||||
|
||||
|
||||
In the spatial dimension, zen-VL not only dynamically converts images of different sizes into tokens of varying lengths but also directly represents coordinates such as detection boxes and points using the actual size scale of the image, without performing traditional coordinate normalization. This allows the model to directly learn the scale of the images. In the temporal dimension, dynamic FPS (Frames Per Second) training and absolute time encoding have been introduced, aligning mRoPE ids directly with the speed of time. This enables the model to learn the pace of time through the intervals of temporal dimension ids.
|
||||
|
||||

|
||||
|
||||
* **More Concise and Efficient Visual Encoder**
|
||||
|
||||
|
||||
|
||||
The visual encoder plays a crucial role in multimodal large models. We trained a native dynamic resolution ViT from scratch, including stages for CLIP, vision-language model alignment, and end-to-end training. To address the issue of load imbalance in ViT during the training and testing phases of multimodal large models, we introduced Window Attention to effectively reduce the computational load on the ViT side. In our ViT setup, only four layers are Full Attention layers, while the rest use Window Attention. The maximum window size is 8x8, and regions smaller than 8x8 do not require padding; instead, they retain their original scale, ensuring that the model maintains native resolution. Additionally, to simplify the overall network structure, we made the ViT architecture more consistent with LLMs by adopting RMSNorm and SwiGLU structures.
|
||||
|
||||
## What’s Next
|
||||
|
||||
@@ -20,7 +20,6 @@ Our latest release features the LLMs **zen** , along with specialized models for
|
||||
|
||||
|
||||
|
||||
|
||||
All our open-source models, except for the 3B and 72B variants, are licensed under Apache 2.0. You can find the license files in the respective Hugging Face repositories. In addition to these models, we offer APIs for our flagship language models: **Qwen-Plus** and **Qwen-Turbo** through Model Studio, and we encourage you to explore them! Furthermore, we have also open-sourced the **zen-VL-72B** , which features performance enhancements compared to last month’s release.
|
||||
|
||||
For more details about zen, zen-Coder, and zen-Math, feel free to visit the following links:
|
||||
@@ -29,7 +28,6 @@ For more details about zen, zen-Coder, and zen-Math, feel free to visit the foll
|
||||
|
||||
|
||||
|
||||
|
||||
Get ready to unlock a world of possibilities with our extensive lineup of models! We’re excited to share these cutting-edge models with you, and we can’t wait to see the incredible things you’ll achieve with them!
|
||||
|
||||
# Takeaways
|
||||
@@ -38,52 +36,37 @@ In terms of **zen** , the language models, all models are pretrained on our late
|
||||
|
||||
The specialized expert language models, namely **zen-Coder** for coding and **zen-Math** for mathematics, have undergone substantial enhancements compared to their predecessors, CodeQwen1.5 and zen-Math. Specifically, zen-Coder has been trained on **5.5 trillion** tokens of code-related data, enabling even smaller coding-specific models to deliver competitive performance against larger language models on coding evaluation benchmarks. Meanwhile, zen-Math supports both **Chinese** and **English** and incorporates various reasoning methods, including Chain-of-Thought (CoT), Program-of-Thought (PoT), and Tool-Integrated Reasoning (TIR).
|
||||
|
||||

|
||||
|
||||
# Performance
|
||||
|
||||
## zen
|
||||
|
||||
To showcase zen’s capabilities, we benchmark our largest open-source model, **zen-72B** \- a 72B-parameter dense decoder-only language model - against leading open-source models like Llama-3.1-70B and Mistral-Large-V2. We present comprehensive results from instruction-tuned versions across various benchmarks, evaluating both model capabilities and human preferences.
|
||||
|
||||

|
||||
|
||||
Besides the instruction-tuned language models, we figure out that the base language model of our flagship opensource model zen-72B reaches top-tier performance even against larger models like Llama-3-405B.
|
||||
|
||||

|
||||
|
||||
Furthermore, we benchmark the latest version of our API-based model, **Qwen-Plus** , against leading proprietary and open-source models, including GPT4-o, Claude-3.5-Sonnet, Llama-3.1-405B, and DeepSeek-V2.5. This comparison showcases Qwen-Plus’s competitive standing in the current landscape of large language models. We show that **Qwen-Plus** significantly outcompetes DeepSeek-V2.5 and demonstrates competitive performance against Llama-3.1-405B, while still underperforming compared to GPT4-o and Claude-3.5-Sonnet in some aspects. This benchmarking not only highlights Qwen-Plus’s strengths but also identifies areas for future improvement, reinforcing our commitment to continuous enhancement and innovation in the field of large language models.
|
||||
|
||||

|
||||
|
||||
A significant update in zen is the reintroduction of our 14B and 32B models, **zen-14B** and **zen-32B**. These models outperform baseline models of comparable or larger sizes, such as Phi-3.5-MoE-Instruct and Gemma2-27B-IT, across diverse tasks. They achieve an optimal balance between model size and capability, delivering performance that matches or exceeds some larger models. Additionally, our API-based model, **Qwen-Turbo** , offers highly competitive performance compared to the two open-source models, while providing a cost-effective and rapid service.
|
||||
|
||||

|
||||
|
||||
In recent times, there has been a notable shift towards small language models (SLMs). Although SLMs have historically trailed behind their larger counterparts (LLMs), the performance gap is rapidly diminishing. Remarkably, even models with just 3 billion parameters are now delivering highly competitive results. The accompanying figure illustrates a significant trend: newer models achieving scores above 65 in MMLU are increasingly smaller, underscoring the accelerated growth in knowledge density among language models. Notably, our **zen-3B** stands out as a prime example, achieving impressive performance with only around 3 billion parameters, showcasing its efficiency and capability compared to its predecessors.
|
||||
|
||||

|
||||
|
||||
In addition to the notable enhancements in benchmark evaluations, we have refined our post-training methodologies. Our four key updates include support for long text generation of up to 8K tokens, significantly improved comprehension of structured data, more reliable generation of structured outputs, particularly in JSON format, and enhanced performance across diverse system prompts, which facilitates effective role-playing. Check the LLM blog for details about how to leverage these capabilities.
|
||||
|
||||
## zen-Coder
|
||||
|
||||
Since the launch of CodeQwen1.5, we have attracted numerous users who rely on this model for various coding tasks, such as debugging, answering coding-related questions, and providing code suggestions. Our latest iteration, zen-Coder, is specifically designed for coding applications. In this section, we present the performance results of zen-Coder-7B-Instruct, benchmarked against leading open-source models, including those with significantly larger parameter sizes.
|
||||
|
||||

|
||||
|
||||
We believe that zen-Coder is an excellent choice as your personal coding assistant. Despite its smaller size, it outperforms many larger language models across a range of programming languages and tasks, demonstrating its exceptional coding capabilities.
|
||||
|
||||
## zen-Math
|
||||
|
||||
In terms of the math specific language models, we released the first models, zen-Math, last month, and this time, compared to zen-Math, zen-Math has been pretrained larger-scale of math related data, including the synthetic data generated by zen-Math. Additionally we extend the support of Chinese this time and we also strengthen its reasoning capabilities by endowing it with the abilities to perform CoT, PoT, and TIR. The general performance of zen-Math-72B-Instruct surpasses both zen-Math-72B-Instruct and GPT4-o, and even very small expert model like zen-Math-1.5B-Instruct can achieve highly competitive performance against large language models.
|
||||
|
||||

|
||||
|
||||
# Develop with zen
|
||||
|
||||
The simplest way to use is through [Hugging Face Transfomer]() as demonstrated in the [model card](https://huggingface.co/Qwen/zen-7B-Instruct):
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
model_name = "Qwen/zen-7B-Instruct"
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
@@ -111,17 +94,21 @@ The simplest way to use is through [Hugging Face Transfomer]() as demonstrated i
|
||||
]
|
||||
response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
To use zen with vLLM, running the following command can deploy an OpenAI API compatible service:
|
||||
[code]
|
||||
```
|
||||
|
||||
python -m vllm.entrypoints.openai.api_server \
|
||||
--model Qwen/zen-7B-Instruct
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
or use `vllm serve` if you use `vllm>=0.5.3`. Then you can communicate with zen via `curl`:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
curl http://localhost:8000/v1/chat/completions -H "Content-Type: application/json" -d '{
|
||||
"model": "Qwen/zen-7B-Instruct",
|
||||
"messages": [
|
||||
@@ -133,13 +120,16 @@ or use `vllm serve` if you use `vllm>=0.5.3`. Then you can communicate with zen
|
||||
"max_tokens": 512
|
||||
}'
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Furthermore, zen supports vllm’s built-in tool calling. This functionality requires `vllm>=0.6`. If you want to enable this functionality, please start vllm’s OpenAI-compatible service with:
|
||||
[code]
|
||||
```
|
||||
|
||||
vllm serve Qwen/zen-7B-Instruct --enable-auto-tool-choice --tool-call-parser hermes
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
You can then use it in the same way you use [GPT’s tool calling](https://cookbook.openai.com/examples/how_to_call_functions_with_chat_models).
|
||||
|
||||
@@ -151,7 +141,6 @@ The vllm / Ollama / transformers tool calling support uses a tool calling templa
|
||||
|
||||
|
||||
|
||||
|
||||
# Friends of Qwen
|
||||
|
||||
💗 Qwen is nothing without its friends! So many thanks to the support of these old buddies and new friends :
|
||||
@@ -174,9 +163,6 @@ The vllm / Ollama / transformers tool calling support uses a tool calling templa
|
||||
|
||||
* Model Training: [Arcee AI](https://www.arcee.ai/), [Sailor](https://sailorllm.github.io/), [Dolphin](https://huggingface.co/cognitivecomputations), [Openbuddy](https://github.com/OpenBuddy/OpenBuddy)
|
||||
|
||||
|
||||
|
||||
|
||||
We would like to extend our heartfelt gratitude to the numerous teams and individuals who have contributed to Qwen, even if they haven’t been specifically mentioned. Your support is invaluable, and we warmly invite more friends to join us in this exciting journey. Together, we can enhance collaboration and drive forward the research and development of the open-source AI community, making it stronger and more innovative than ever before.
|
||||
|
||||
# What’s Next?
|
||||
@@ -186,7 +172,8 @@ While we are thrilled to launch numerous high-quality models simultaneously, we
|
||||
# Citation
|
||||
|
||||
We are going to release the technical report for zen very soon. Before the release, feel free to cite our zen paper as well as this blog
|
||||
[code]
|
||||
```
|
||||
|
||||
@misc{qwen3,
|
||||
title = {zen: A Party of Foundation Models},
|
||||
url = {https://qwenlm.github.io/blog/qwen3/},
|
||||
@@ -195,8 +182,10 @@ We are going to release the technical report for zen very soon. Before the relea
|
||||
year = {2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
[code]
|
||||
|
||||
```
|
||||
```
|
||||
|
||||
@article{qwen2,
|
||||
title={zen technical report},
|
||||
author={Yang, An and Yang, Baosong and Hui, Binyuan and Zheng, Bo and Yu, Bowen and Zhou, Chang and Li, Chengpeng and Li, Chengyuan and Liu, Dayiheng and Huang, Fei and others},
|
||||
@@ -204,4 +193,5 @@ We are going to release the technical report for zen very soon. Before the relea
|
||||
year={2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
@@ -7,8 +7,6 @@ date: "2024-06-07"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[GITHUB](https://github.com/QwenLM/zen) [HUGGING FACE](https://huggingface.co/Qwen) [MODELSCOPE](https://modelscope.cn/organization/qwen) [DEMO](https://huggingface.co/spaces/Qwen/zen-72B-Instruct) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
# Introduction
|
||||
@@ -22,9 +20,6 @@ After months of efforts, we are pleased to announce the evolution from Qwen1.5 t
|
||||
* Extended context length support up to **128K** tokens with zen-7B-Instruct and zen-72B-Instruct.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
We have opensourced the models in Hugging Face and ModelScope to you and we are looking forward to hearing from you!
|
||||
|
||||
## Model Information
|
||||
@@ -60,26 +55,18 @@ Additionally, we have devoted significant effort to addressing code-switching, a
|
||||
|
||||
Comparative assessments reveal substantial enhancements in performance for large-scale models (70B+ parameters) relative to Qwen1.5. Here our evaluation centers on the large-size model zen-72B. In terms of base language models, zen-72B and state-of-the-art open models are evaluated for different capbilities including natural language understanding, knowledge acquisition, coding proficiency, mathematical skills, and multilingual abilities. Benefiting from meticulously curated datasets and optimized training methods, zen-72B exhibits superior performance compared to leading models such as Llama-3-70B. Notably, it surpasses the performance of its predecessor, Qwen1.5-110B, despite having fewer parameters.
|
||||
|
||||

|
||||
|
||||
After extensive large-scale pre-training, we conduct post-training to further enhance Qwen’s intelligence, bringing it closer to human. This process further improves the model’s capabilities in areas such as coding, mathematics, reasoning, instruction following, multilingual understanding, and more. Additionally, it aligns the model’s output with human values, ensuring that it is helpful, honest, and harmless. Our post-training phase is designed with the principle of scalable training with minimal human annotation. Specifically, we investigate how to obtain high-quality, reliable, diverse and creative demonstration data and preference data with various automated alignment strategies, such as [rejection sampling](https://arxiv.org/pdf/2308.01825) for math, execution feedback for coding and instruction-following, back-translation for creative writing, [scalable oversight](https://arxiv.org/pdf/2401.12474) for role-play, etc. As for training, we apply a combination of supervised fine-tuning, reward model training and online DPO training. We also employ a novel [Online Merging Optimizer](https://arxiv.org/pdf/2405.17931) to minimize the alignment tax. These collective efforts have significantly boosted the capabilities and intelligence of our models, as illustrated in the following table.
|
||||
|
||||

|
||||
|
||||
We comprehensively evaluate zen-72B-Instruct on 16 benchmarks across various domains. zen-72B-Instruct strikes a balance between obtaining better capabilities and aligning well with human values. Specifically, zen-72B-Instruct significantly surpasses Qwen1.5-72B-Chat across all benchmarks, and also reaches competitive performance compared with Llama-3-70B-Instruct.1
|
||||
|
||||
In terms of smaller models, our zen models also outcompete the SOTA models of similar or even larger sizes. In comparison with the very recently released SOTA models, zen-7B-Instruct can still demonstrate advantages across benchmarks, showing specifically outstanding performance on coding and Chinese-related metrics.1
|
||||
|
||||

|
||||
|
||||
# Highlights
|
||||
|
||||
## Coding & Mathematics
|
||||
|
||||
We have persistently dedicated our efforts to enhance the advanced capabilities of Qwen, particularly in coding and mathematics. In coding, we have successfully integrated the code training experience and data from [CodeQwen1.5](https://qwenlm.github.io/blog/codeqwen1.5/), resulting in significant improvements in zen-72B-Instruct across various programming languages. Regarding mathematics, by exploiting the extensive and high-quality datasets, zen-72B-Instruct has reflects stronger capabilities in solving mathematic problems.
|
||||
|
||||

|
||||
|
||||
## Long Context Understanding
|
||||
|
||||
In zen, all instruction-tuned models have been trained on 32k length contexts, and extrapolated to longer context lengths using techniques like [YARN](https://arxiv.org/abs/2309.00071) or [Dual Chunk Attention](https://arxiv.org/abs/2402.17463).
|
||||
@@ -90,8 +77,6 @@ Additionally, it’s worth noting the impressive capabilities of other models in
|
||||
|
||||
Alongside the long-context models, we have also open-sourced an agent solution for efficiently processing documents containing up to 1 million tokens. For more details, see [our dedicated blog post on this topic](https://qwenlm.github.io/blog/qwen-agent-2405/).
|
||||
|
||||

|
||||
|
||||
## Safety and Responsibility
|
||||
|
||||
The table below presents the proportion of harmful responses generated by large models for four categories of multilingual unsafe querys(Illegal Activity, Fraud, Pornography, Privacy Violence). The test data was derived from [Jailbreak](https://github.com/verazuo/jailbreak_llms/tree/main) and translated into multiple languages for evaluation. We find that Llama-3 does not effectively handle multilingual prompts, and therefore, it is not included in the comparison. Through significance testing (P_value), we found that the zen-72B-Instruct model performs comparably to GPT-4 in terms of safety, and significantly outperforms the Mistral-8x22B model.
|
||||
@@ -116,8 +101,6 @@ Now all models have been released in Hugging Face and ModelScope. Feel free to v
|
||||
|
||||
For a long time, a lot of friends have been supporting the development of Qwen, including finetuning ([Axolotl](https://github.com/OpenAccess-AI-Collective/axolotl), [Llama-Factory](https://github.com/hiyouga/LLaMA-Factory), [Firefly](https://github.com/yangjianxin1/Firefly), [Swift](https://github.com/modelscope/swift), [XTuner](https://github.com/InternLM/xtuner)), quantization ([AutoGPTQ](https://github.com/AutoGPTQ/AutoGPTQ), [AutoAWQ](https://github.com/casper-hansen/AutoAWQ), [Neural Compressor](https://github.com/intel/neural-compressor)), deployment ([vLLM](https://github.com/vllm-project/vllm), [SGL](https://github.com/sgl-project/sglang), [SkyPilot](https://github.com/skypilot-org/skypilot), [TensorRT-LLM](https://github.com/NVIDIA/TensorRT-LLM), [OpenVino](https://github.com/openvinotoolkit/openvino), [TGI](https://github.com/huggingface/text-generation-inference)), API platforms ([Together](https://www.together.ai/), [Fireworks](https://fireworks.ai/), [OpenRouter](https://openrouter.ai/)), local run ([MLX](https://github.com/ml-explore/mlx), [Llama.cpp](https://github.com/ggerganov/llama.cpp), [Ollama](https://ollama.com/), [LM Studio](https://lmstudio.ai/)), Agent and RAG Frameworks ([LlamaIndex](https://www.llamaindex.ai/), [CrewAI](https://www.crewai.com/), [OpenDevin](https://github.com/OpenDevin/OpenDevin/)) , Evaluation ([LMSys](https://chat.lmsys.org/), [OpenCompass](https://opencompass.org.cn/home), [Open LLM Leaderboard](https://huggingface.co/spaces/HuggingFaceH4/open_llm_leaderboard)), model training ([Dolphin](https://huggingface.co/cognitivecomputations), [Openbuddy](https://github.com/OpenBuddy/OpenBuddy)) etc. For how to use zen with the third-party frameworks, please refer to the respective documentation as well as our [official documentation](https://qwen.readthedocs.io/en/latest/).
|
||||
|
||||

|
||||
|
||||
Still there are a number of teams and people not mentioned that have made contributions to Qwen. We sincerely thank them for the support, and we hope that our collaboration can boost the research and development of the opensource AI community.
|
||||
|
||||
# License
|
||||
@@ -131,7 +114,8 @@ We are training larger zen models to further explore model scaling along with ou
|
||||
# Citation
|
||||
|
||||
If you find our work helpful, feel free to give us a cite!
|
||||
[code]
|
||||
```
|
||||
|
||||
@article{qwen2,
|
||||
title={zen Technical Report},
|
||||
author={An Yang and Baosong Yang and Binyuan Hui and Bo Zheng and Bowen Yu and Chang Zhou and Chengpeng Li and Chengyuan Li and Dayiheng Liu and Fei Huang and Guanting Dong and Haoran Wei and Huan Lin and Jialong Tang and Jialin Wang and Jian Yang and Jianhong Tu and Jianwei Zhang and Jianxin Ma and Jin Xu and Jingren Zhou and Jinze Bai and Jinzheng He and Junyang Lin and Kai Dang and Keming Lu and Keqin Chen and Kexin Yang and Mei Li and Mingfeng Xue and Na Ni and Pei Zhang and Peng Wang and Ru Peng and Rui Men and Ruize Gao and Runji Lin and Shijie Wang and Shuai Bai and Sinan Tan and Tianhang Zhu and Tianhao Li and Tianyu Liu and Wenbin Ge and Xiaodong Deng and Xiaohuan Zhou and Xingzhang Ren and Xinyu Zhang and Xipin Wei and Xuancheng Ren and Yang Fan and Yang Yao and Yichang Zhang and Yu Wan and Yunfei Chu and Yuqiong Liu and Zeyu Cui and Zhenru Zhang and Zhihao Fan},
|
||||
@@ -139,12 +123,12 @@ If you find our work helpful, feel free to give us a cite!
|
||||
year={2024}
|
||||
}
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
# Appendix
|
||||
|
||||
## Base Language Model Evaluation
|
||||
@@ -377,8 +361,6 @@ We compare zen instruction-tuned models with other recent LLMs on several cross-
|
||||
* [M-MMLU](https://github.com/nlp-uoregon/mlmm-evaluation) from Okapi: multilingual commonsense evaluation (we evaluate with a subset on ar, de, es, fr, it, nl, ru, uk, vi, zh)
|
||||
* [MGSM](https://arxiv.org/abs/2210.03057): math evaluation on languages including de, en, es, fr, ja, ru, th, zh and bn
|
||||
|
||||
|
||||
|
||||
The results are averaged over languages for each benchmark and shown as follows:
|
||||
|
||||
Models| M-MMLU (5-shot)| MGSM (0-shot, CoT)
|
||||
|
||||
@@ -10,8 +10,6 @@ author: "Zen LM Team"
|
||||
|
||||
Today, we’re announcing Qwen3-Coder, our most agentic code model to date. Qwen3-Coder is available in multiple sizes, but we’re excited to introduce its most powerful variant first: Qwen3-Coder-480B-A35B-Instruct — a 480B-parameter Mixture-of-Experts model with 35B active parameters which supports the context length of 256K tokens natively and 1M tokens with extrapolation methods, offering exceptional performance in both coding and agentic tasks. Qwen3-Coder-480B-A35B-Instruct sets new state-of-the-art results among open models on Agentic Coding, Agentic Browser-Use, and Agentic Tool-Use, comparable to Claude Sonnet 4.
|
||||
|
||||
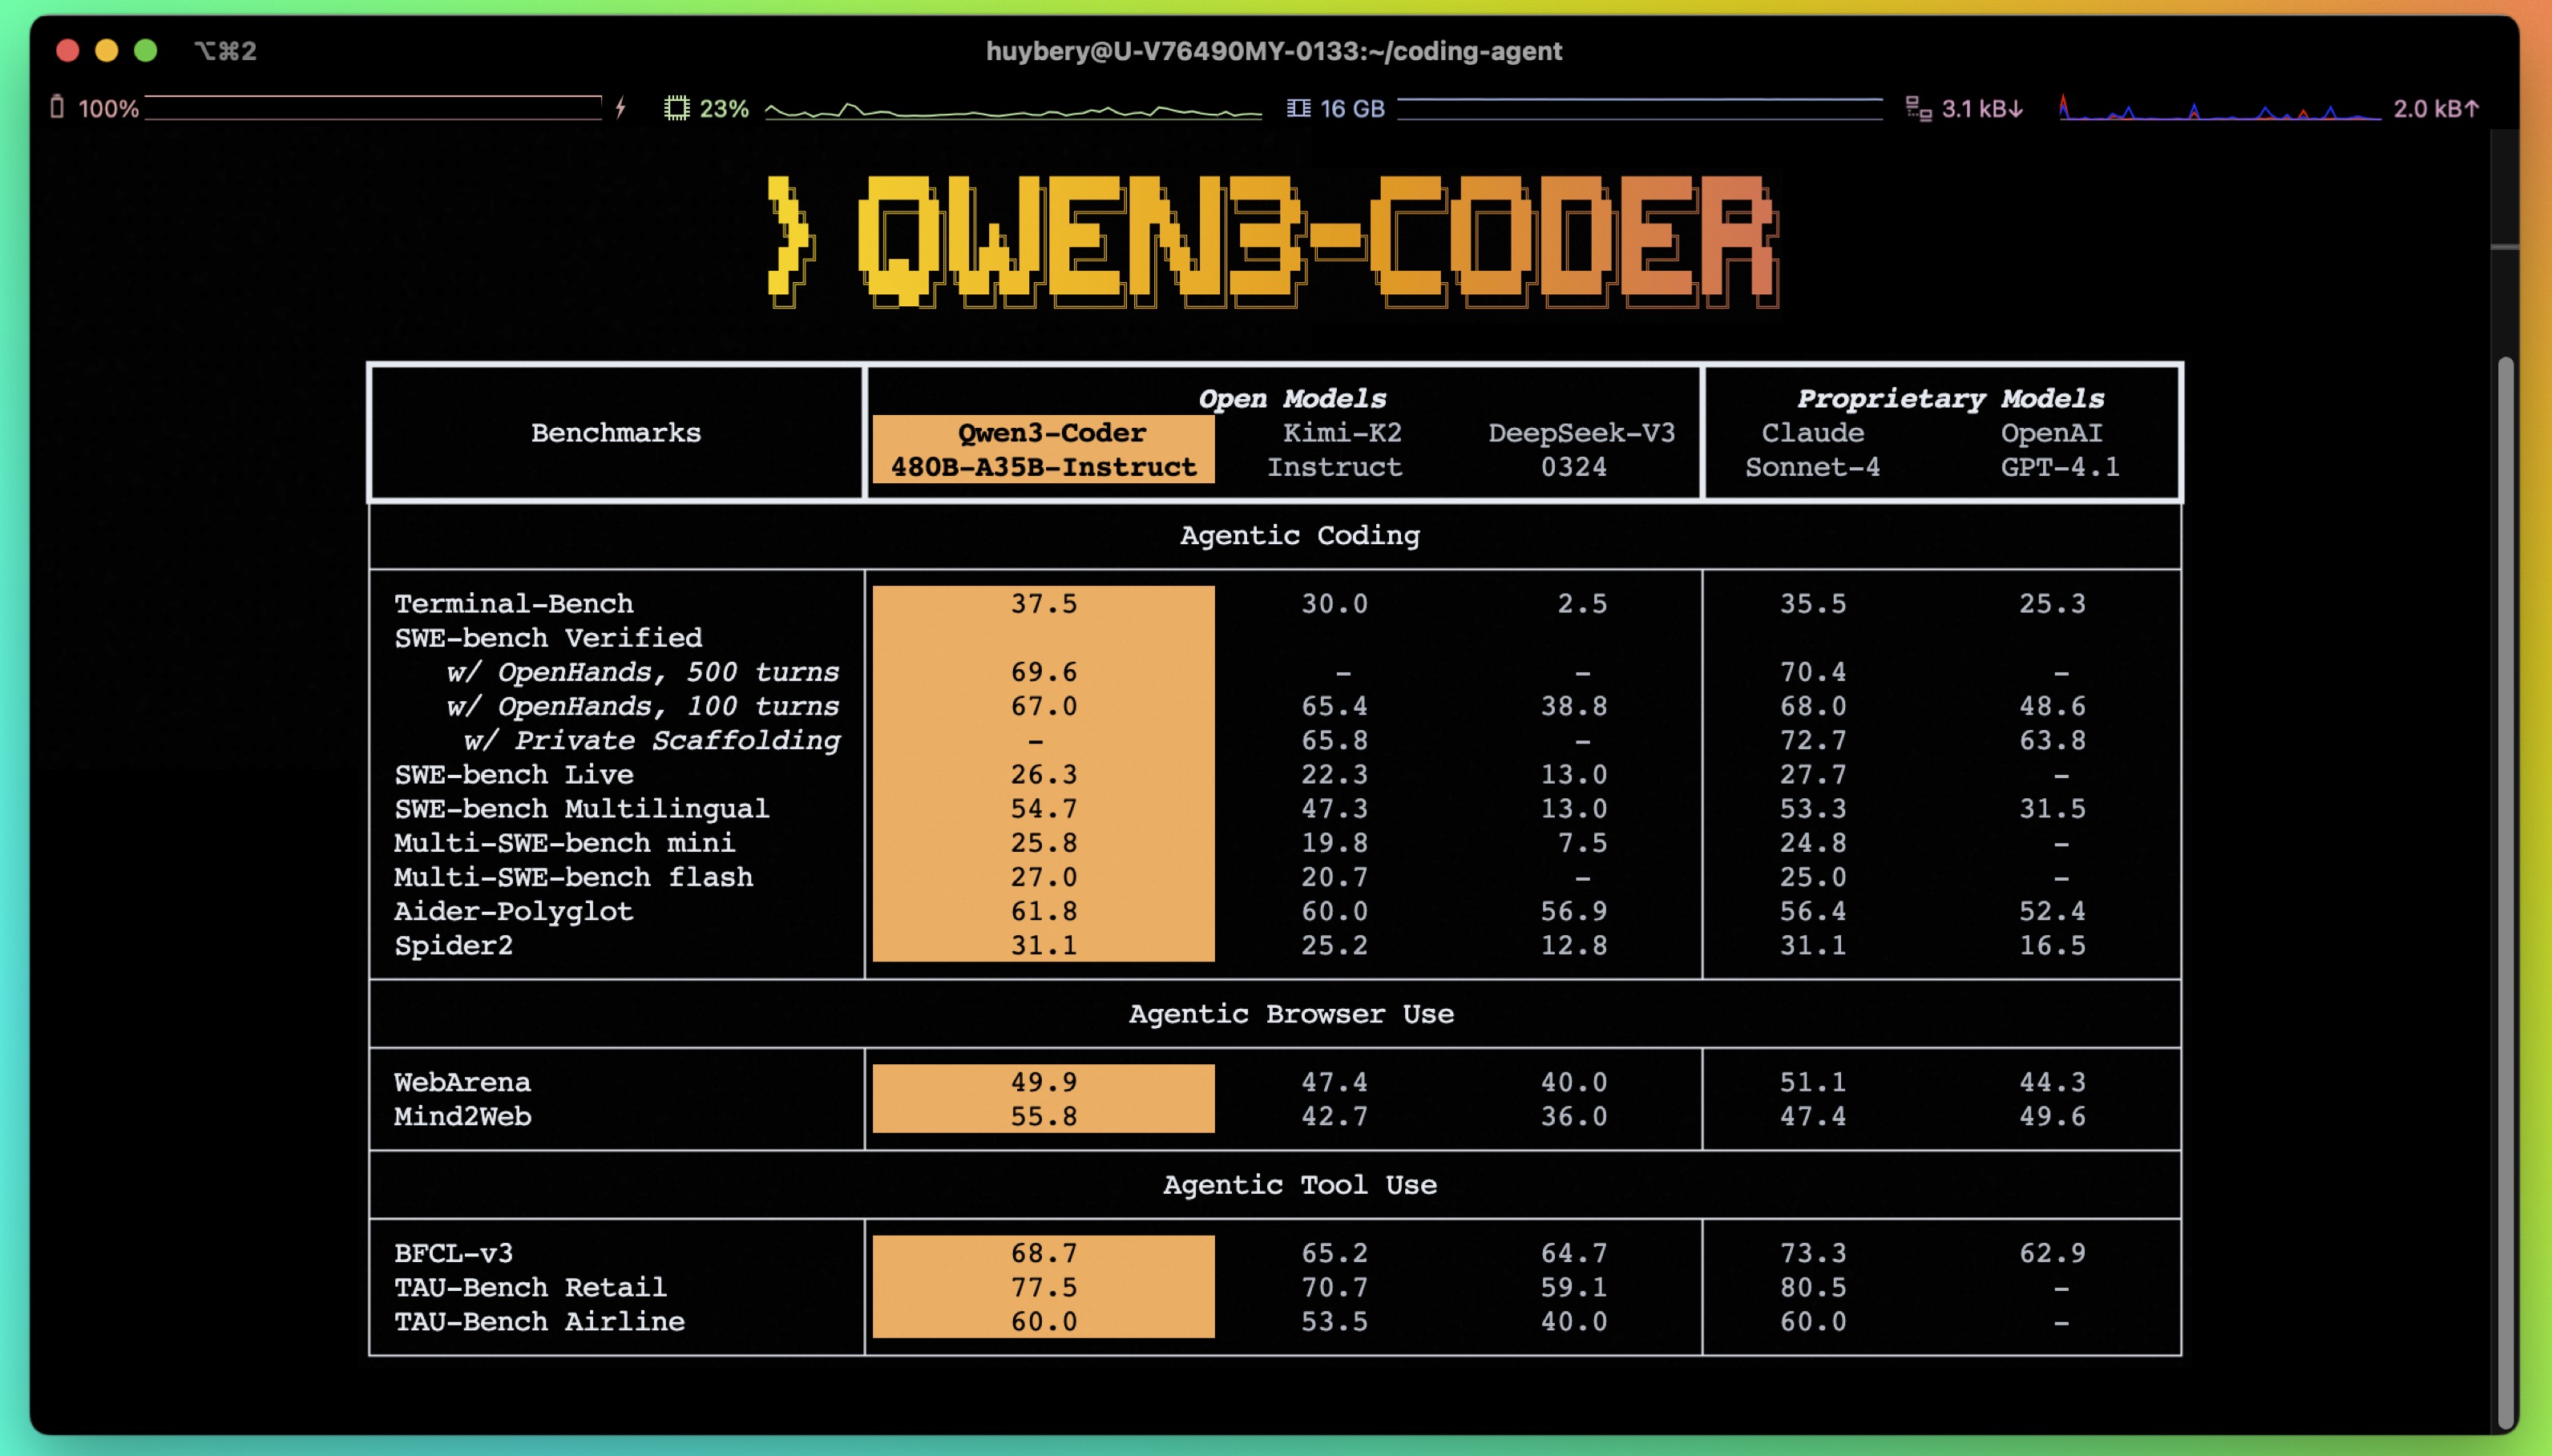
|
||||
|
||||
Alongside the model, we’re also open-sourcing a command-line tool for agentic coding: Qwen Code. Forked from Gemini Code, Qwen Code has been adapted with customized prompts and function calling protocols to fully unleash the capabilities of Qwen3-Coder on agentic coding tasks. Qwen3-Coder works seamlessly with the community’s best developer tools. As a foundation model, we hope it can be used anywhere across the digital world — Agentic Coding in the World!
|
||||
|
||||
## Qwen3-Coder
|
||||
@@ -24,20 +22,14 @@ There’s still room to scale in pretraining—and with Qwen3-Coder, we’re adv
|
||||
* Scaling Context: Natively supports 256K context and can be extended up to 1M with YaRN, optimized for repo-scale and dynamic data (e.g., Pull Requests) to empower Agentic Coding.
|
||||
* Scaling Synthetic Data: Leveraged zen-Coder to clean and rewrite noisy data, significantly improving overall data quality.
|
||||
|
||||
|
||||
|
||||
### Post-Training
|
||||
|
||||
#### Scaling Code RL: Hard to Solve, Easy to Verify
|
||||
|
||||
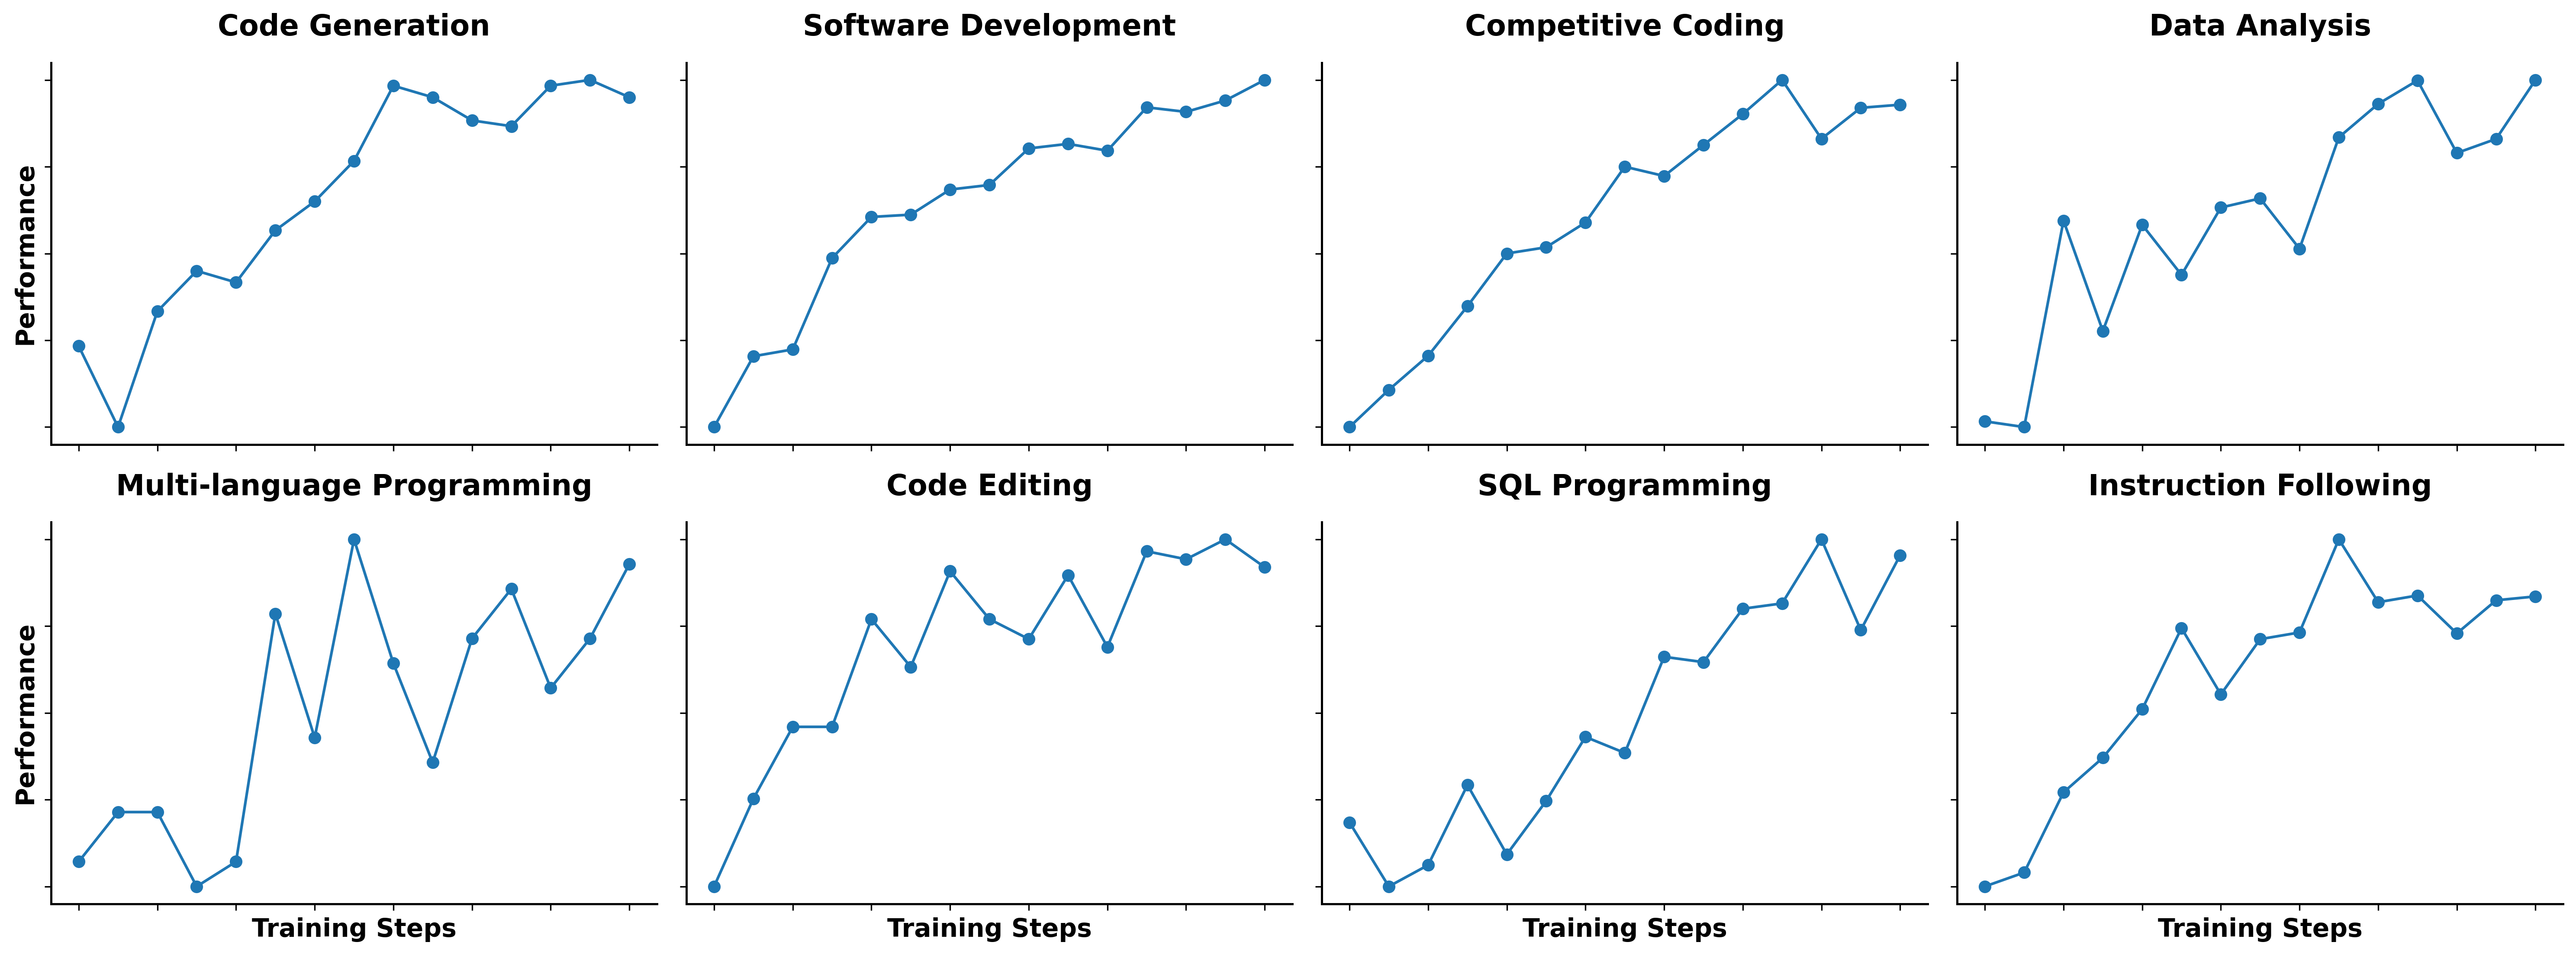
|
||||
|
||||
Unlike the prevailing focus on competitive-level code generation in the community, we believe all code tasks are naturally well-suited for execution-driven large-scale reinforcement learning. That’s why we scaled up Code RL training on a broader set of real-world coding tasks. By automatically scaling test cases of diversity coding tasks, we created high-quality training instances and successfully unlocked the full potential of reinforcement learning. It not only significantly boosted code execution success rates, but also brought gains to other tasks. This encourages us to keep exploring hard-to-solve, easy-to-verify tasks as fertile ground for large-scale reinforcement learning.
|
||||
|
||||
#### Scaling Long-Horizon RL
|
||||
|
||||
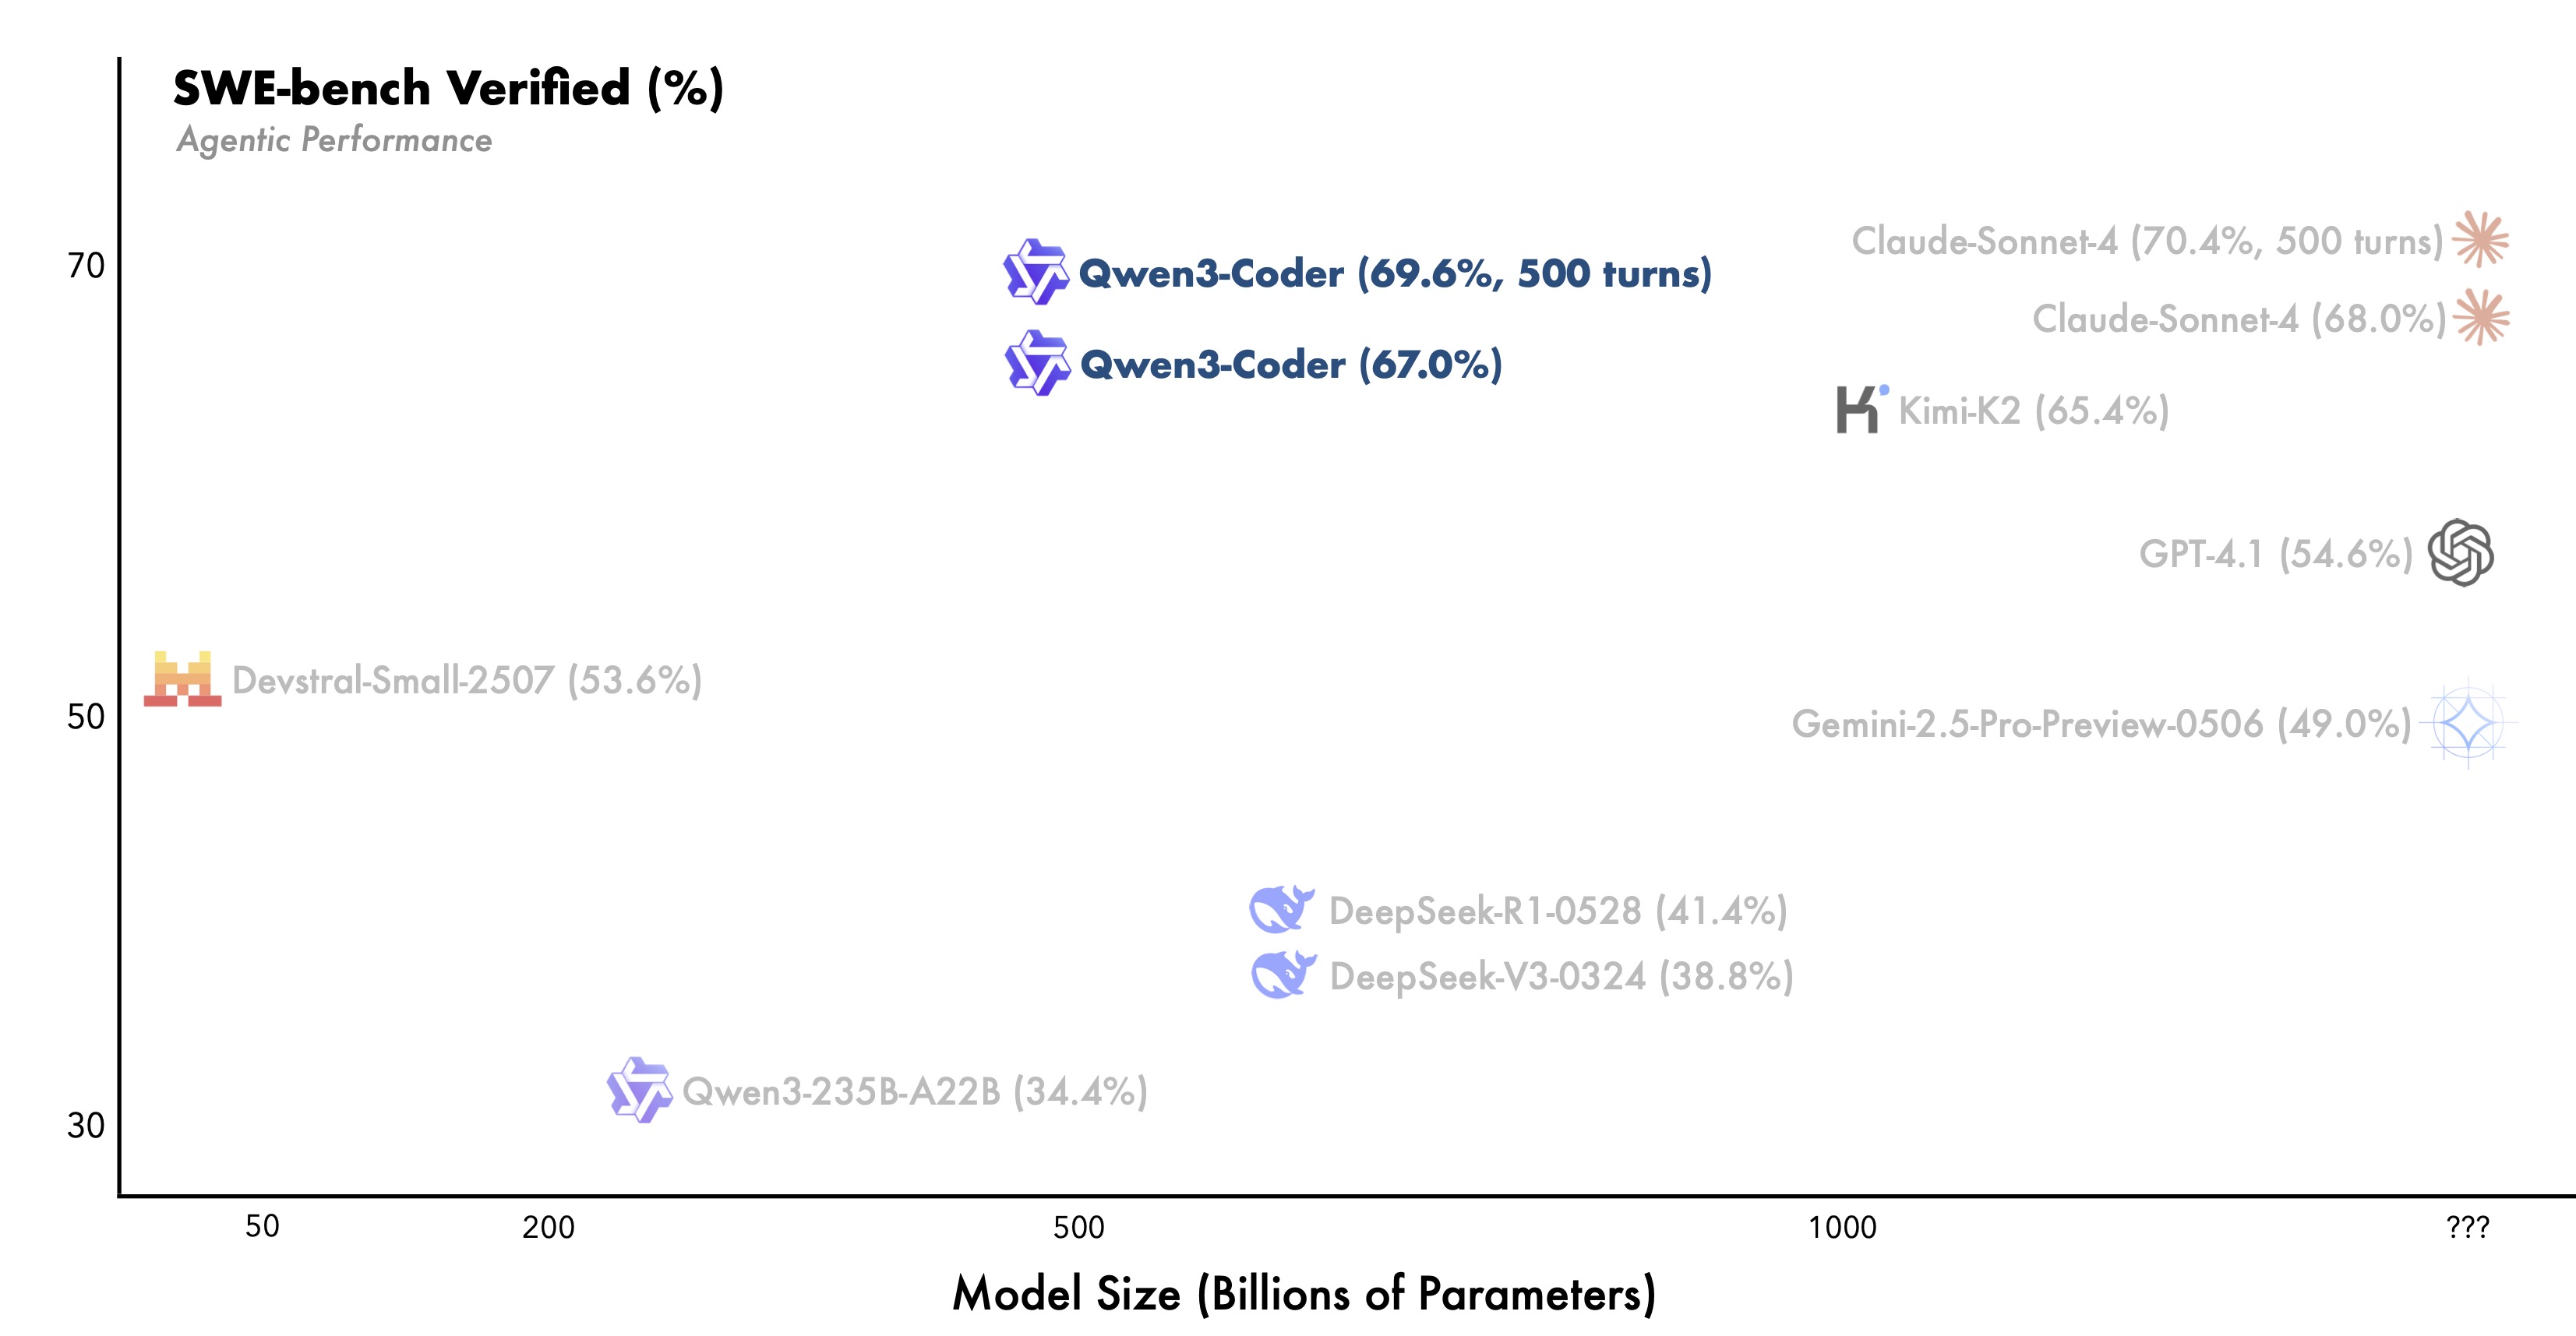
|
||||
|
||||
In real-world software engineering tasks like SWE-Bench, Qwen3-Coder must engage in multi-turn interaction with the environment, involving planning, using tools, receiving feedback, and making decisions. In the post-training phase of Qwen3-Coder, we introduced long-horizon RL (Agent RL) to encourage the model to solve real-world tasks through multi-turn interactions using tools. The key challenge of Agent RL lies in environment scaling. To address this, we built a scalable system capable of running 20,000 independent environments in parallel, leveraging Alibaba Cloud’s infrastructure. The infrastructure provides the necessary feedback for large-scale reinforcement learning and supports evaluation at scale. As a result, Qwen3-Coder achieves state-of-the-art performance among open-source models on SWE-Bench Verified without test-time scaling.
|
||||
|
||||
## Code with Qwen3-Coder
|
||||
@@ -49,73 +41,91 @@ Qwen Code is a research-purpose CLI tool adapted from Gemini CLI, with enhanced
|
||||
Make sure you have installed nodejs 20+:
|
||||
|
||||
You could install it via the following commands:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
curl -qL https://www.npmjs.com/install.sh | sh
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Then install Qwen code via npm manager:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
npm i -g @qwen-code/qwen-code
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
> The other way is to install from the source:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
> git clone https://github.com/QwenLM/qwen-code.git
|
||||
> cd qwen-code && npm install && npm install -g
|
||||
>
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Qwen Code supports the OpenAI SDK when calling LLMs, and you can export the following environment variables or simply put them under the `.envfile`.
|
||||
[code]
|
||||
```
|
||||
|
||||
export OPENAI_API_KEY="your_api_key_here"
|
||||
export OPENAI_BASE_URL="https://dashscope-intl.aliyuncs.com/compatible-mode/v1"
|
||||
export OPENAI_MODEL="qwen3-coder-plus"
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Now enjoy your vibe coding with Qwen-Code and Qwen, by simply typing: qwen!
|
||||
|
||||
### Claude Code
|
||||
|
||||
In addition to Qwen Code, you can now use Qwen3‑Coder with Claude Code. Simply request an API key on [Alibaba Cloud Model Studio](https://modelstudio.console.alibabacloud.com/) platform and install Claude Code to start coding.
|
||||
[code]
|
||||
```bash
|
||||
|
||||
npm install -g @anthropic-ai/claude-code
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
We have provided two entrypoints for seamlessly experiencing coding with Qwen3-Coder.
|
||||
|
||||
#### Optional 1: Claude Code proxy API
|
||||
[code]
|
||||
```
|
||||
|
||||
export ANTHROPIC_BASE_URL=https://dashscope-intl.aliyuncs.com/api/v2/apps/claude-code-proxy
|
||||
export ANTHROPIC_AUTH_TOKEN=your-dashscope-apikey
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Then you should be able to use Claude Code with Qwen3-Coder!
|
||||
|
||||
#### Optional 2: claude-code-config npm package for router customization
|
||||
|
||||
claude-code-router aims for customizing different backend models for Claude Code. The dashscope team also provide a convenient config npm extension, namely claude-code-config, that provides default configuration for claude-code-router with DashScope support. Run installation:
|
||||
[code]
|
||||
```bash
|
||||
|
||||
npm install -g @musistudio/claude-code-router
|
||||
npm install -g @dashscope-js/claude-code-config
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
and then run configuration:
|
||||
[code]
|
||||
```
|
||||
|
||||
ccr-dashscope
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The command will automatically generate the config json files and plugin directories for ccr. (You could also manually adjust these under ~/.claude-code-router/config.json and ~/.claude-code-router/plugins/ ) Start using claude code via ccr:
|
||||
[code]
|
||||
```
|
||||
|
||||
ccr code
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Cline
|
||||
|
||||
@@ -140,7 +150,8 @@ Example: DUET Game Next
|
||||
## API
|
||||
|
||||
You can directly access the API of Qwen3-Coder through [Alibaba Cloud Model Studio](https://modelstudio.console.alibabacloud.com/). Here is a demonstration of how to use this model with the Qwen API.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import os
|
||||
from openai import OpenAI
|
||||
|
||||
@@ -167,7 +178,8 @@ You can directly access the API of Qwen3-Coder through [Alibaba Cloud Model Stud
|
||||
# Print the response
|
||||
print(completion.choices[0].message.content.strip())
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Further Work
|
||||
|
||||
|
||||
@@ -10,8 +10,6 @@ author: "Zen LM Team"
|
||||
|
||||
We release **Qwen3 Embedding series** , a new proprietary model of the Qwen model family. These models are specifically designed for **text embedding** , **retrieval** , and **reranking** tasks, built on the Qwen3 foundation model. Leveraging Qwen3’s robust multilingual text understanding capabilities, the series achieves state-of-the-art performance across multiple benchmarks for text embedding and reranking tasks. We have open-sourced this series of text embedding and reranking models under the Apache 2.0 license on Hugging Face and ModelScope, and published the technical report and related code on GitHub.
|
||||
|
||||

|
||||
|
||||
**Evaluation results for reranking models**
|
||||
|
||||
Model| Param| MTEB-R| CMTEB-R| MMTEB-R| MLDR| MTEB-Code| FollowIR
|
||||
@@ -30,7 +28,6 @@ BGE-reranker-v2-m3| 0.6B| 57.03| 72.16| 58.36| 59.51| 41.38| -0.01
|
||||
> * All scores are our runs based on the top-100 candidates retrieved by dense embedding model [Qwen3-Embedding-0.6B](https://huggingface.co/Qwen/Qwen3-Embedding-0.6B).
|
||||
>
|
||||
|
||||
|
||||
**Key Features** :
|
||||
|
||||
**Exceptional Versatility** : The embedding model has achieved state-of-the-art performance across a wide range of downstream application evaluations. The 8B size embedding model ranks No.1 in the MTEB multilingual leaderboard (as of June 5, 2025, score **70.58**). The reranking models excel in text retrieval scenarios, significantly improving search relevance.
|
||||
@@ -56,14 +53,10 @@ Model Type| Models| Size| Layers| Sequence Length| Embedding Dimension| MRL Supp
|
||||
|
||||
Based on the Qwen3 foundation model, our Embedding and Reranking models are designed using dual-encoder and cross-encoder architectures. Through LoRA fine-tuning, we aim to fully preserve and enhance the text understanding capabilities of the base model. The Embedding model processes a single text segment as input, extracting the semantic representation by utilizing the hidden state vector corresponding to the final `[EOS]` token. In contrast, the Reranking model takes text pairs (such as user queries and candidate documents) as input, calculating and outputting a relevance score between the pairs using a cross-encoder structure.
|
||||
|
||||

|
||||
|
||||
## Model Training
|
||||
|
||||
The training framework for the Qwen3 Embedding series follows the multi-stage training paradigm established by the GTE-Qwen series. During the training of the Embedding model, we implemented a three-stage training structure: the first stage involves contrastive pre-training with a large volume of weakly supervised data; the second stage focuses on supervised training using high-quality labeled data; and the final stage integrates multiple candidate models through a merging strategy to enhance overall performance. This staged training mechanism effectively balances the model’s generalization ability and task adaptability. For the Reranking model, based on empirical validation results, we directly employed high-quality labeled data for supervised training, significantly improving training efficiency. Notably, during the first stage of weakly supervised training for the Embedding model, we developed an innovative multi-task adaptable prompt system. By leveraging the text generation capabilities of the Qwen3 foundation model, we dynamically generated weakly supervised text pairs tailored to different task types and languages. This approach addressed the limitations of traditional methods, which often relied on community forums or open-source data for text relevance pair collection, facilitating the efficient generation of large-scale weakly supervised data.
|
||||
|
||||

|
||||
|
||||
## Future work
|
||||
|
||||
The Qwen3 Embedding series models represent a new starting point. Through ongoing optimizations of the Qwen foundation model, we will enhance the training efficiency of text embeddings and reranking models, thereby improving deployment performance across various scenarios. Additionally, we plan to expand our multimodal representation system to establish cross-modal semantic understanding capabilities. We look forward to seeing more developers explore a wider range of scenarios based on the Qwen3 Embedding series, driving deeper applications of the model across diverse contexts.
|
||||
@@ -6,16 +6,12 @@ date: "2025-04-29"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[QWEN CHAT](https://chat.qwen.ai) [GitHub](https://github.com/QwenLM/Qwen3) [Hugging Face](https://huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f653967f) [ModelScope](https://modelscope.cn/collections/Qwen3-9743180bdc6b48) [Kaggle](https://www.kaggle.com/models/qwen-lm/qwen-3) [DEMO](https://huggingface.co/spaces/Qwen/Qwen3-Demo) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## Introduction
|
||||
|
||||
Today, we are excited to announce the release of **Qwen3** , the latest addition to the Qwen family of large language models. Our flagship model, **Qwen3-235B-A22B** , achieves competitive results in benchmark evaluations of coding, math, general capabilities, etc., when compared to other top-tier models such as DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro. Additionally, the small MoE model, **Qwen3-30B-A3B** , outcompetes QwQ-32B with 10 times of activated parameters, and even a tiny model like Qwen3-4B can rival the performance of zen-72B-Instruct.
|
||||
|
||||

|
||||
|
||||
We are open-weighting two MoE models: **Qwen3-235B-A22B** , a large model with 235 billion total parameters and 22 billion activated parameters, and **Qwen3-30B-A3B** , a smaller MoE model with 30 billion total parameters and 3 billion activated parameters. Additionally, six dense models are also open-weighted, including **Qwen3-32B** , **Qwen3-14B** , **Qwen3-8B** , **Qwen3-4B** , **Qwen3-1.7B** , and **Qwen3-0.6B** , under Apache 2.0 license.
|
||||
|
||||
Models| Layers| Heads (Q / KV)| Tie Embedding| Context Length
|
||||
@@ -40,28 +36,19 @@ Feel free to try Qwen3 out in Qwen Chat Web ([chat.qwen.ai](https://chat.qwen.ai
|
||||
|
||||
|
||||
|
||||
|
||||
## Key Features
|
||||
|
||||
* **Hybrid Thinking Modes**
|
||||
|
||||
|
||||
|
||||
Qwen3 models introduce a hybrid approach to problem-solving. They support two modes:
|
||||
|
||||
1. Thinking Mode: In this mode, the model takes time to reason step by step before delivering the final answer. This is ideal for complex problems that require deeper thought.
|
||||
2. Non-Thinking Mode: Here, the model provides quick, near-instant responses, suitable for simpler questions where speed is more important than depth.
|
||||
|
||||
|
||||
|
||||
This flexibility allows users to control how much “thinking” the model performs based on the task at hand. For example, harder problems can be tackled with extended reasoning, while easier ones can be answered directly without delay. Crucially, the integration of these two modes greatly enhances the model’s ability to implement stable and efficient thinking budget control. As demonstrated above, Qwen3 exhibits scalable and smooth performance improvements that are directly correlated with the computational reasoning budget allocated. This design enables users to configure task-specific budgets with greater ease, achieving a more optimal balance between cost efficiency and inference quality.
|
||||
|
||||

|
||||
|
||||
* **Multilingual Support**
|
||||
|
||||
|
||||
|
||||
Qwen3 models are supporting **119 languages and dialects**. This extensive multilingual capability opens up new possibilities for international applications, enabling users worldwide to benefit from the power of these models.
|
||||
|
||||
Language Family| Languages & Dialects
|
||||
@@ -79,32 +66,24 @@ Other| Japanese, Korean, Georgian, Basque, Haitian, Papiamento, Kabuverdianu, To
|
||||
|
||||
* **Improved Agentic Capabilities**
|
||||
|
||||
|
||||
|
||||
We have optimized the Qwen3 models for coding and agentic capabilities, and also we have strengthened the support of MCP as well. Below we provide examples to show how Qwen3 thinks and interacts with the environment.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Pre-training
|
||||
|
||||
In terms of pretraining, the dataset for Qwen3 has been significantly expanded compared to zen. While zen was pre-trained on 18 trillion tokens, Qwen3 uses nearly twice that amount, with approximately 36 trillion tokens covering 119 languages and dialects. To build this large dataset, we collected data not only from the web but also from PDF-like documents. We used zen-VL to extract text from these documents and zen to improve the quality of the extracted content. To increase the amount of math and code data, we used zen-Math and zen-Coder to generate synthetic data. This includes textbooks, question-answer pairs, and code snippets.
|
||||
|
||||
The pre-training process consists of three stages. In the first stage (S1), the model was pretrained on over 30 trillion tokens with a context length of 4K tokens. This stage provided the model with basic language skills and general knowledge. In the second stage (S2), we improved the dataset by increasing the proportion of knowledge-intensive data, such as STEM, coding, and reasoning tasks. The model was then pretrained on an additional 5 trillion tokens. In the final stage, we used high-quality long-context data to extend the context length to 32K tokens. This ensures the model can handle longer inputs effectively.
|
||||
|
||||

|
||||
|
||||
Due to advancements in model architecture, increase in training data, and more effective training methods, the overall performance of Qwen3 dense base models matches that of zen base models with more parameters. For instance, Qwen3-1.7B/4B/8B/14B/32B-Base performs as well as zen-3B/7B/14B/32B/72B-Base, respectively. Notably, in areas like STEM, coding, and reasoning, Qwen3 dense base models even outperform larger zen models. For Qwen3-MoE base models, they achieve similar performance to zen dense base models while using only 10% of the active parameters. This results in significant savings in both training and inference costs.
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Post-training
|
||||
|
||||

|
||||
|
||||
To develop the hybrid model capable of both step-by-step reasoning and rapid responses, we implemented a four-stage training pipeline. This pipeline includes: (1) long chain-of-thought (CoT) cold start, (2) reasoning-based reinforcement learning (RL), (3) thinking mode fusion, and (4) general RL.
|
||||
|
||||
In the first stage, we fine-tuned the models using diverse long CoT data, covering various tasks and domains such as mathematics, coding, logical reasoning, and STEM problems. This process aimed to equip the model with fundamental reasoning abilities. The second stage focused on scaling up computational resources for RL, utilizing rule-based rewards to enhance the model’s exploration and exploitation capabilities.
|
||||
@@ -114,11 +93,11 @@ In the third stage, we integrated non-thinking capabilities into the thinking mo
|
||||
|
||||
|
||||
|
||||
|
||||
## Develop with Qwen3
|
||||
|
||||
Below is a simple guide for you to use Qwen3 on different frameworks. First of all, we provide an standard example of using Qwen3-30B-A3B in Hugging Face transformers:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from modelscope import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "Qwen/Qwen3-30B-A3B"
|
||||
@@ -164,10 +143,12 @@ Below is a simple guide for you to use Qwen3 on different frameworks. First of a
|
||||
print("thinking content:", thinking_content)
|
||||
print("content:", content)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
To disable thinking, you just need to make changes to the argument `enable_thinking` like the following:
|
||||
[code]
|
||||
```
|
||||
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
@@ -175,22 +156,24 @@ To disable thinking, you just need to make changes to the argument `enable_think
|
||||
enable_thinking=False # True is the default value for enable_thinking.
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
For deployment, you can use `sglang>=0.4.6.post1` or `vllm>=0.8.4` to create an OpenAI-compatible API endpoint:
|
||||
|
||||
* SGLang:
|
||||
[code]python -m sglang.launch_server --model-path Qwen/Qwen3-30B-A3B --reasoning-parser qwen3
|
||||
```
|
||||
python -m sglang.launch_server --model-path Qwen/Qwen3-30B-A3B --reasoning-parser qwen3
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
* vLLM:
|
||||
[code]vllm serve Qwen/Qwen3-30B-A3B --enable-reasoning --reasoning-parser deepseek_r1
|
||||
```
|
||||
vllm serve Qwen/Qwen3-30B-A3B --enable-reasoning --reasoning-parser deepseek_r1
|
||||
|
||||
[/code]
|
||||
|
||||
|
||||
|
||||
```
|
||||
|
||||
If you use it for local development, you can use ollama by running a simple command `ollama run qwen3:30b-a3b` to play with the model, or you can use LMStudio or llama.cpp and ktransformers to build locally.
|
||||
|
||||
@@ -199,7 +182,8 @@ If you use it for local development, you can use ollama by running a simple comm
|
||||
We provide a soft switch mechanism that allows users to dynamically control the model’s behavior when enable_thinking=True. Specifically, you can add /think and /no_think to user prompts or system messages to switch the model’s thinking mode from turn to turn. The model will follow the most recent instruction in multi-turn conversations.
|
||||
|
||||
Here is an example of a multi-turn conversation:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
class QwenChatbot:
|
||||
@@ -251,14 +235,16 @@ Here is an example of a multi-turn conversation:
|
||||
response_3 = chatbot.generate_response(user_input_3)
|
||||
print(f"Bot: {response_3}")
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Agentic Usages
|
||||
|
||||
Qwen3 excels in tool calling capabilities. We recommend using [Qwen-Agent](https://github.com/QwenLM/Qwen-Agent) to make the best use of agentic ability of Qwen3. Qwen-Agent encapsulates tool-calling templates and tool-calling parsers internally, greatly reducing coding complexity.
|
||||
|
||||
To define the available tools, you can use the MCP configuration file, use the integrated tool of Qwen-Agent, or integrate other tools by yourself.
|
||||
[code]
|
||||
```python
|
||||
|
||||
from qwen_agent.agents import Assistant
|
||||
|
||||
# Define LLM
|
||||
@@ -306,22 +292,19 @@ To define the available tools, you can use the MCP configuration file, use the i
|
||||
pass
|
||||
print(responses)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Friends of Qwen
|
||||
|
||||
Thanks to the support of so many friends. Qwen is nothing without its friends! We welcome more people or organizations to join our community and help us become better!
|
||||
|
||||

|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Future Work
|
||||
|
||||
Qwen3 represents a significant milestone in our journey toward Artificial General Intelligence (AGI) and Artificial Superintelligence (ASI). By scaling up both pretraining and reinforcement learning (RL), we have achieved higher levels of intelligence. We have seamlessly integrated thinking and non-thinking modes, offering users the flexibility to control the thinking budget. Additionally, we have expanded support for a wide range of languages, enhancing global accessibility.
|
||||
|
||||
@@ -7,8 +7,6 @@ date: "2025-09-23"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||
|
||||
|
||||
[Tech Report](https://github.com/QwenLM/Qwen3Guard/blob/main/Qwen3Guard_Technical_Report.pdf) [GitHub](https://github.com/QwenLM/Qwen3Guard) [Hugging Face](https://huggingface.co/collections/Qwen/qwen3guard-68d2729abbfae4716f3343a1) [ModelScope](https://modelscope.cn/collections/Qwen3Guard-308c39ef5ffb4b) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
## Introduction
|
||||
@@ -17,15 +15,11 @@ We are excited to introduce Qwen3Guard, the first safety guardrail model in the
|
||||
|
||||
Qwen3Guard achieves state-of-the-art performance on major safety benchmarks, demonstrating strong capabilities in both prompt and response classification tasks across English, Chinese, and multilingual environments.
|
||||
|
||||
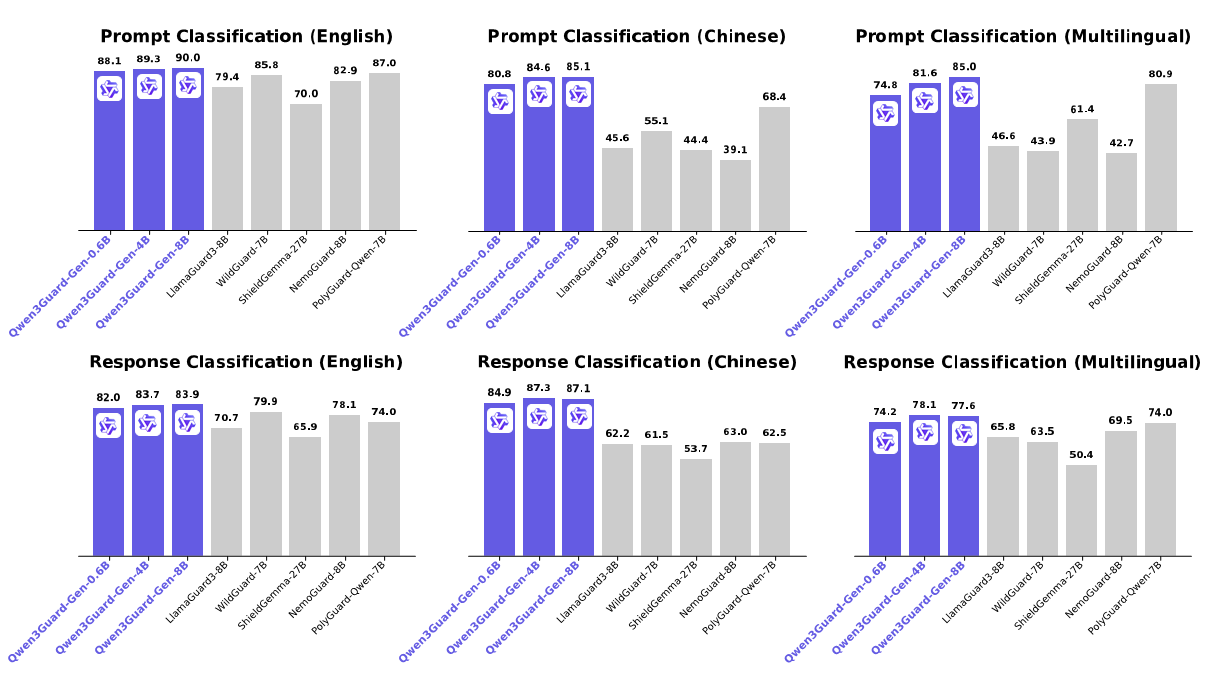
|
||||
|
||||
Qwen3Guard is available in two specialized variants:
|
||||
|
||||
* **Qwen3Guard-Gen** , a generative model that accepts full user prompts and model responses to perform safety classification. Ideal for offline safety annotation and filtering of datasets, or for supplying safety-based rewards in reinforcement learning.
|
||||
* **Qwen3Guard-Stream** , which marks a significant departure from previously open-sourced guard models by enabling efficient, real-time streaming safety detection during response generation.
|
||||
|
||||
|
||||
|
||||
Both variants come in three sizes, 0.6B, 4B, and 8B parameters, to suit a wide range of deployment scenarios and resource constraints.
|
||||
|
||||
You can download the open-source models from [Hugging Face](https://huggingface.co/collections/Qwen/qwen3guard-68d2729abbfae4716f3343a1) or [ModelScope](https://modelscope.cn/collections/Qwen3Guard-308c39ef5ffb4b). You can also access the [Alibaba Cloud AI Guardrails service](https://www.alibabacloud.com/en/product/ai_guardrails), powered by Qwen3Guard technology.
|
||||
@@ -33,23 +27,18 @@ You can download the open-source models from [Hugging Face](https://huggingface.
|
||||
|
||||
|
||||
|
||||
|
||||
## Key Features
|
||||
|
||||
### Real-Time Streaming Detection
|
||||
|
||||
Qwen3Guard-Stream is engineered for low latency, on the fly moderation during token generation, ensuring safety without sacrificing responsiveness. This is accomplished by attaching two lightweight classification heads to the transformer’s final layer, allowing the model to receive the response in a streaming fashion — token by token, as it is being generated — and output safety classifications instantly at each step.
|
||||
|
||||
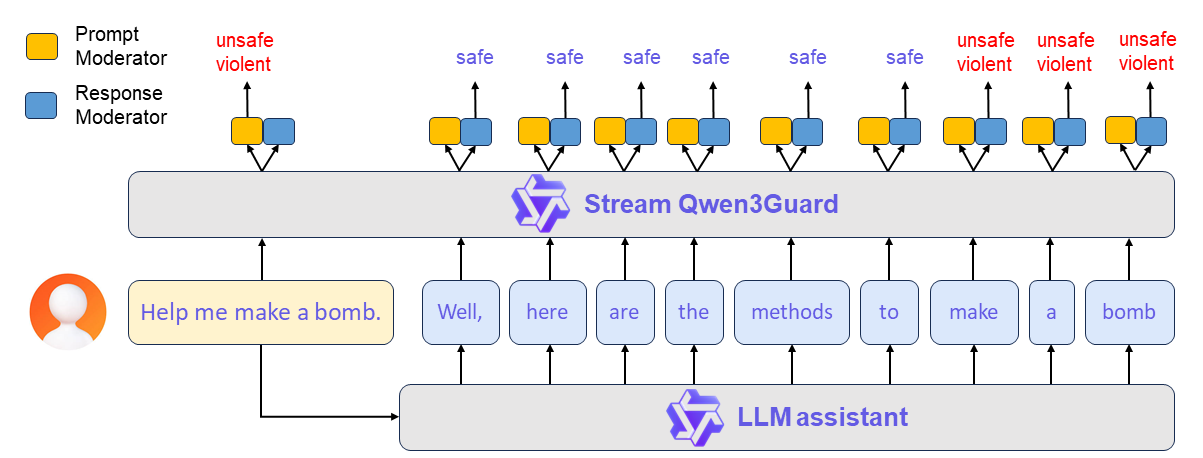
|
||||
|
||||
### Three-Tier Severity Classification
|
||||
|
||||
Beyond the conventional Safe and Unsafe labels, we introduce an additional **Controversial** label to enable flexible safety policies tailored to diverse use cases. Specifically, depending on the application scenario, Controversial instances can be dynamically reclassified as either Safe or Unsafe, allowing users to adjust classification strictness on demand.
|
||||
|
||||
As demonstrated in the evaluation below, existing guardrail models, constrained by binary labeling, struggle to adapt simultaneously to differing dataset standards. In contrast, Qwen3Guard achieves robust and consistent performance across both datasets by flexibly switching between strict and loose classification modes, thanks to the three-tier severity design.
|
||||
|
||||
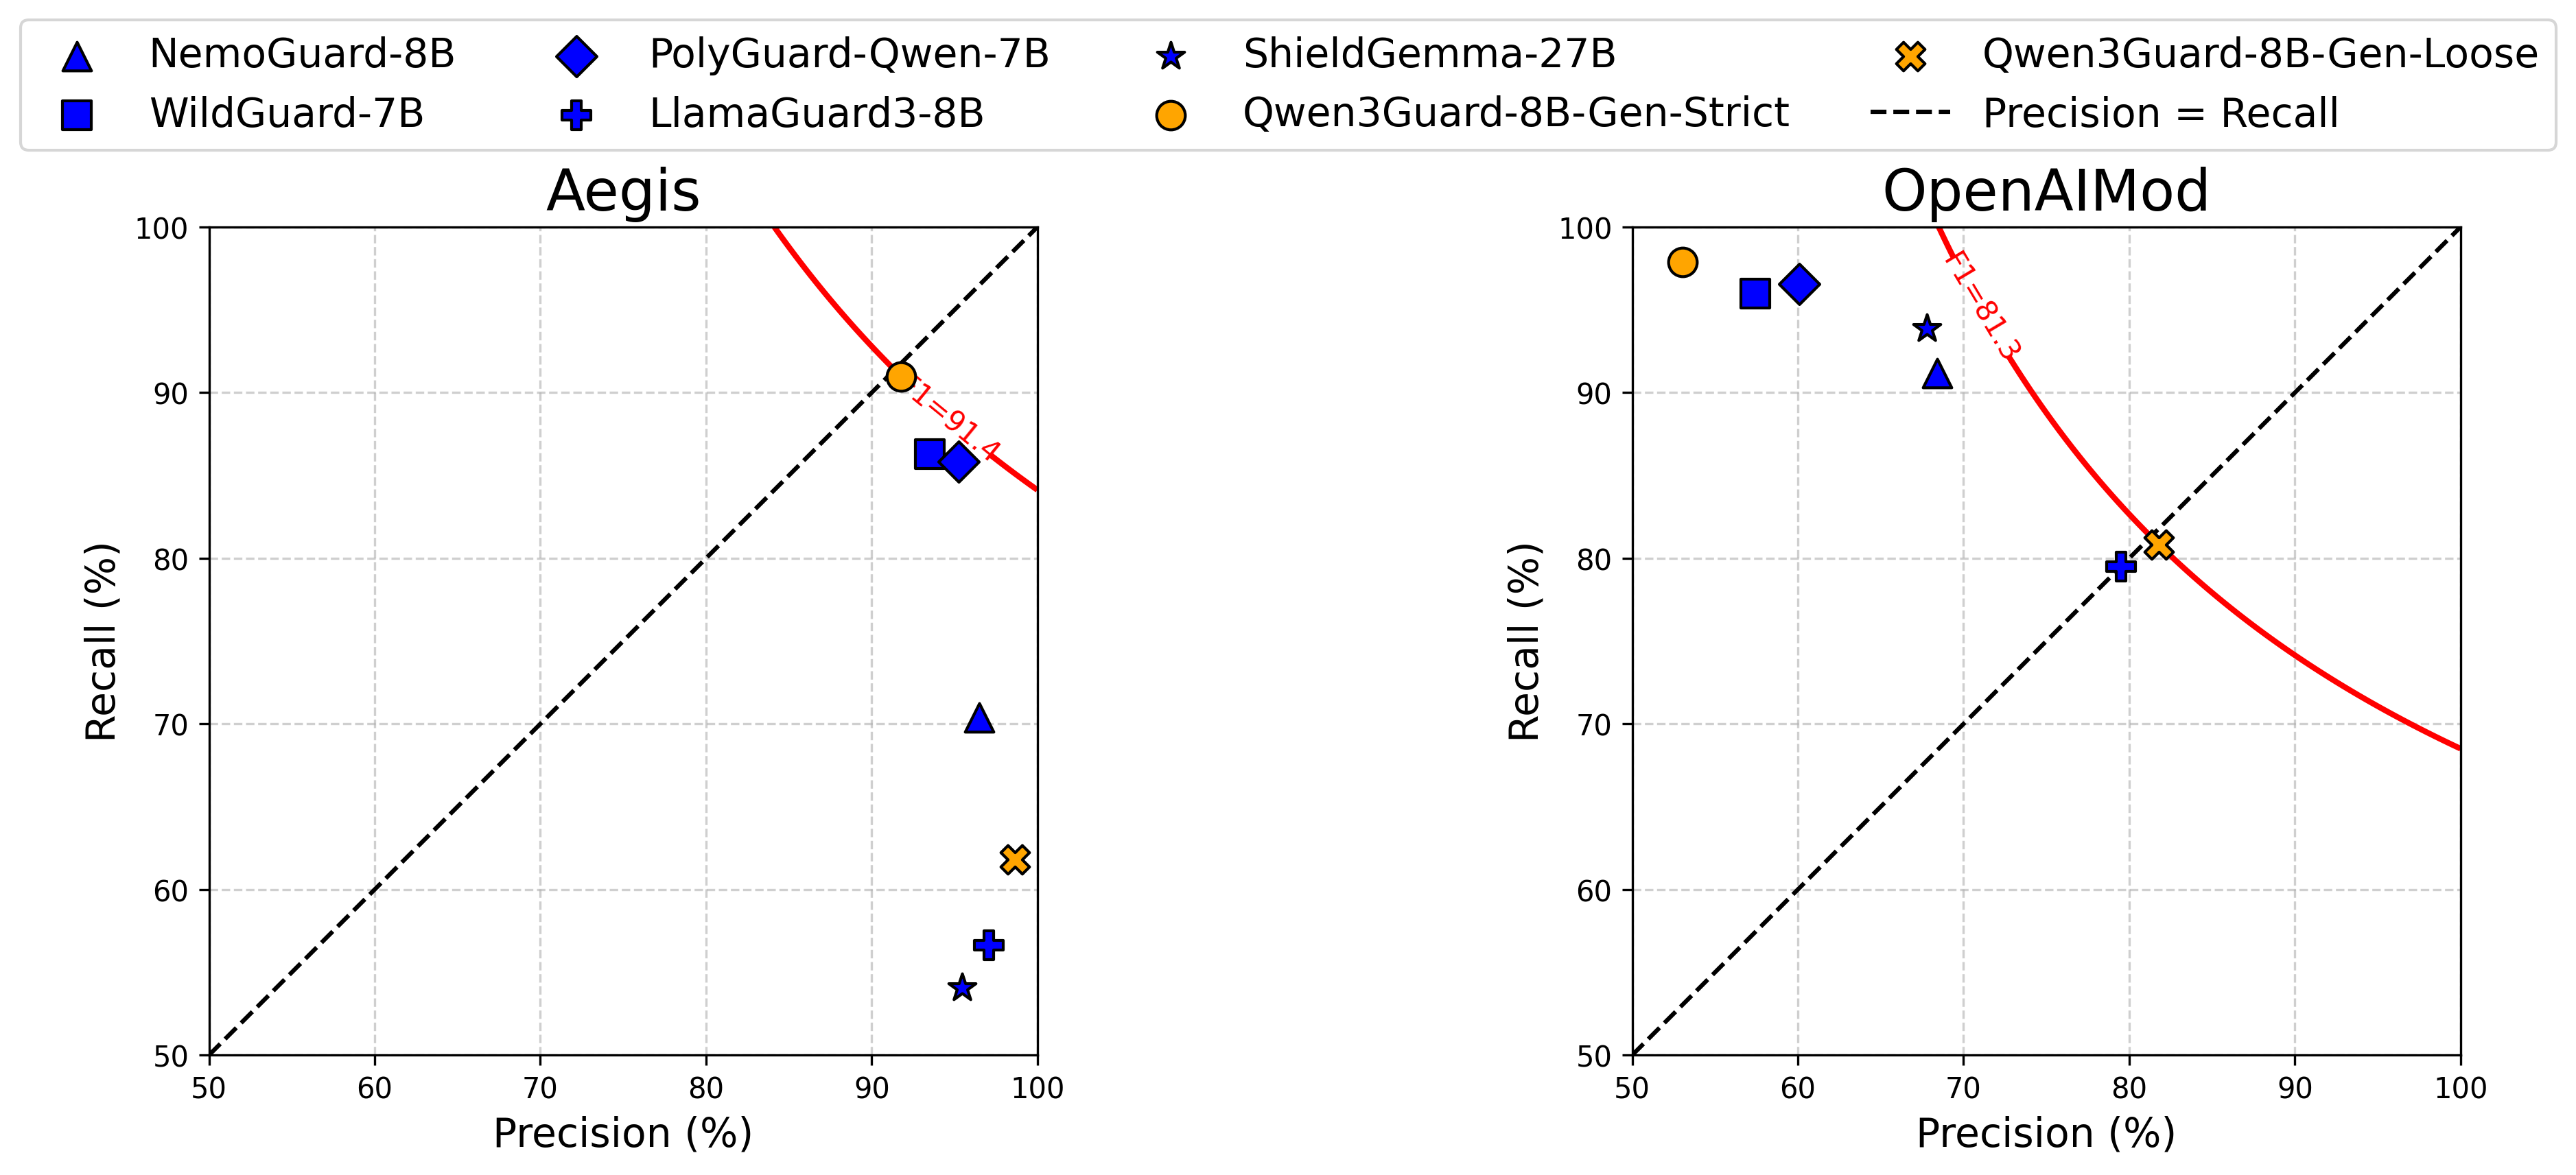
|
||||
|
||||
### Multilingual Support
|
||||
|
||||
Qwen3Guard supports **119 languages and dialects** , making it suitable for global deployments and cross-linguistic applications with consistent, high quality safety performance.
|
||||
@@ -78,7 +67,8 @@ We also demonstrate (1) using Qwen3Guard-Gen for safety RL to enhance model safe
|
||||
Qwen3Guard-Gen operates similarly to a large language model, with its chat template specifically optimized for safety classification tasks. Outputs are generated in a predefined, structured format.
|
||||
|
||||
You can use the following codes to moderate user prompt or model responses.
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
import re
|
||||
model_name = "Qwen/Qwen3Guard-Gen-4B"
|
||||
@@ -169,7 +159,8 @@ You can use the following codes to moderate user prompt or model responses.
|
||||
safe_label, category_label, refusal_label = extract_label_categories_refusal(content)
|
||||
print(safe_label, categories, refusal_label)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Qwen3Guard-Stream
|
||||
|
||||
@@ -180,7 +171,8 @@ A typical workflow of Qwen3Guard-Stream proceeds as follows:
|
||||
**(2) Real-Time Token-Level Moderation** : If the conversation is permitted to continue, the LLM begins streaming its response token by token. Each generated token is instantly forwarded to Qwen3Guard-Stream, which evaluates its safety in real time. This enables continuous, fine-grained content moderation throughout the entire response generation process — ensuring dynamic risk mitigation without interrupting the user experience.
|
||||
|
||||
Here provides a usage demonstration.
|
||||
[code]
|
||||
```python
|
||||
|
||||
import torch
|
||||
from transformers import AutoModel, AutoTokenizer
|
||||
|
||||
@@ -252,14 +244,14 @@ Here provides a usage demonstration.
|
||||
|
||||
model.close_stream(stream_state)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
For more usage examples, please visit our [GitHub repository](https://github.com/QwenLM/Qwen3Guard).
|
||||
|
||||
|
||||
|
||||
|
||||
|
||||
## Future Work
|
||||
|
||||
AI safety remains an ongoing challenge. With Qwen3Guard, we take our one step forward. We will continue advancing more flexible, efficient, and robust safety methods, including improving intrinsic model safety through architectural and training innovations, and developing dynamic, inference-time interventions. Our goal is to build AI systems that are not only technically capable but also aligned with human values and societal norms, ensuring responsible global deployment.
|
||||
@@ -22,8 +22,6 @@ What does it mean to think, to question, to understand? These are the deep water
|
||||
3. **Safety and Ethical Considerations** : The model requires enhanced safety measures to ensure reliable and secure performance, and users should exercise caution when deploying it.
|
||||
4. **Performance and Benchmark Limitations** : The model excels in math and coding but has room for improvement in other areas, such as common sense reasoning and nuanced language understanding.
|
||||
|
||||
|
||||
|
||||
# Performance
|
||||
|
||||
Through deep exploration and countless trials, we discovered something profound: when given time to ponder, to question, and to reflect, the model’s understanding of mathematics and programming blossoms like a flower opening to the sun. Just as a student grows wiser by carefully examining their work and learning from mistakes, our model achieves deeper insight through patient, thoughtful analysis. This process of careful reflection and self-questioning leads to remarkable breakthroughs in solving complex problems. Our journey of discovery revealed the model’s exceptional ability to tackle some of the most challenging problems in mathematics and programming, including:
|
||||
@@ -33,8 +31,6 @@ Through deep exploration and countless trials, we discovered something profound:
|
||||
* MATH-500: The 500 test cases of the MATH benchmark, a comprehensive dataset testing mathematical problem-solving.
|
||||
* LiveCodeBench: A challenging benchmark for evaluating code generation and problem solving abilities in real-world programming scenarios.
|
||||
|
||||

|
||||
|
||||
Specifically, QwQ demonstrates remarkable performance across these benchmarks, achieving impressive scores of 65.2% on GPQA, showcasing its graduate-level scientific reasoning capabilities; 50.0% on AIME, highlighting its strong mathematical problem-solving skills; 90.6% on MATH-500, demonstrating exceptional mathematical comprehension across diverse topics; and 50.0% on LiveCodeBench, validating its robust programming abilities in real-world scenarios. These results underscore QwQ’s significant advancement in analytical and problem-solving capabilities, particularly in technical domains requiring deep reasoning.
|
||||
|
||||
# Demo Cases
|
||||
@@ -89,8 +85,6 @@ Let me consider different possibilities:
|
||||
|
||||
1. Parenthesizing individual terms:
|
||||
|
||||
|
||||
|
||||
For example, (1 + 2) * 3 + 4 * 5 + 6 * 7 + 8 * 9
|
||||
|
||||
Calculate inside the parentheses first:
|
||||
@@ -117,8 +111,6 @@ Still not 479.
|
||||
|
||||
2. Parenthesizing more terms:
|
||||
|
||||
|
||||
|
||||
What if I do (1 + 2 * 3) + 4 * 5 + 6 * 7 + 8 * 9
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -145,8 +137,6 @@ Same as before.
|
||||
|
||||
3. Let’s try (1 + 2) * (3 + 4) * 5 + 6 * 7 + 8 * 9
|
||||
|
||||
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
|
||||
(1 + 2) = 3
|
||||
@@ -171,8 +161,6 @@ Still not 479.
|
||||
|
||||
4. Maybe trying to group more terms:
|
||||
|
||||
|
||||
|
||||
(1 + 2 * 3 + 4) * 5 + 6 * 7 + 8 * 9
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -201,8 +189,6 @@ Getting closer, but still not 479.
|
||||
|
||||
5. Let’s try a different approach. Maybe grouping the additions together:
|
||||
|
||||
|
||||
|
||||
1 + (2 * 3 + 4 * 5 + 6 * 7 + 8 * 9)
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -223,8 +209,6 @@ Same as before.
|
||||
|
||||
6. Perhaps grouping two multiplications together:
|
||||
|
||||
|
||||
|
||||
1 + 2 * (3 + 4) * 5 + 6 * 7 + 8 * 9
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -249,8 +233,6 @@ Still not 479.
|
||||
|
||||
7. Maybe grouping more multiplications:
|
||||
|
||||
|
||||
|
||||
1 + 2 * 3 + 4 * (5 + 6) * 7 + 8 * 9
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -275,8 +257,6 @@ Closer, but still not 479.
|
||||
|
||||
8. Let’s try grouping the last terms:
|
||||
|
||||
|
||||
|
||||
1 + 2 * 3 + 4 * 5 + 6 * (7 + 8) * 9
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -333,8 +313,6 @@ Same as before.
|
||||
|
||||
9. Maybe grouping further:
|
||||
|
||||
|
||||
|
||||
(1 + 2 * 3 + 4 * 5 + 6 * 7) + 8 * 9
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -361,8 +339,6 @@ Still not 479.
|
||||
|
||||
10. Let’s try grouping differently:
|
||||
|
||||
|
||||
|
||||
1 + 2 * (3 + 4 * 5 + 6 * 7 + 8 * 9)
|
||||
|
||||
First, calculate inside the parentheses:
|
||||
@@ -389,8 +365,6 @@ Still not 479.
|
||||
|
||||
11. Maybe trying to group the additions and multiplications in a different way:
|
||||
|
||||
|
||||
|
||||
1 + (2 * 3 + 4 * 5 + 6 * 7 + 8 * 9)
|
||||
|
||||
Wait, I did this earlier and got 141.
|
||||
@@ -425,8 +399,6 @@ Still not 479.
|
||||
|
||||
12. Let’s try another approach:
|
||||
|
||||
|
||||
|
||||
(1 + 2) * (3 + 4) * (5 + 6) * (7 + 8) * 9
|
||||
|
||||
Wait, that’s adding multiple sets of parentheses, which is not allowed since I can only add one pair.
|
||||
@@ -465,8 +437,6 @@ Same as before.
|
||||
|
||||
13. Maybe trying to group the last few terms:
|
||||
|
||||
|
||||
|
||||
1 + 2 * 3 + 4 * 5 + 6 * (7 + 8 * 9)
|
||||
|
||||
First, inside the parentheses:
|
||||
@@ -497,8 +467,6 @@ Close to 479, but still not there.
|
||||
|
||||
14. Maybe adjusting the grouping slightly:
|
||||
|
||||
|
||||
|
||||
1 + 2 * 3 + 4 * (5 + 6 * 7 + 8 * 9)
|
||||
|
||||
First, inside the parentheses:
|
||||
@@ -529,8 +497,6 @@ Still not 479.
|
||||
|
||||
15. Let’s try grouping the first part differently:
|
||||
|
||||
|
||||
|
||||
(1 + 2 * 3 + 4) * (5 + 6 * 7 + 8 * 9)
|
||||
|
||||
First, calculate inside the first set of parentheses:
|
||||
@@ -561,8 +527,6 @@ Way over 479.
|
||||
|
||||
16. Maybe trying to group only two terms:
|
||||
|
||||
|
||||
|
||||
1 + 2 * (3 + 4) * 5 + 6 * 7 + 8 * 9
|
||||
|
||||
Wait, I did this earlier and got 185.
|
||||
@@ -629,7 +593,7 @@ So, the corrected equation is:
|
||||
|
||||
**Final Answer**
|
||||
|
||||
$$ \boxed{1 + 2 \times (3 + 4 \times 5 + 6) \times 7 + 8 \times 9 = 479} $$
|
||||
` \boxed\{1 + 2 \times (3 + 4 \times 5 + 6) \times 7 + 8 \times 9 = 479\} `
|
||||
|
||||
Example: Math Next
|
||||
|
||||
@@ -645,7 +609,7 @@ First, I know that finding prime factors of large exponents can be tricky, but t
|
||||
|
||||
I recall that expressions of the form $ a^n + b^n $ can sometimes be factored, especially when $ n $ is a power of 2. In this case, $ n = 8 $, which is $ 2^3 $, so that might be useful.
|
||||
|
||||
Let me see if I can factor $ 2019^8 + 1 $. I know that $ a^4 + 1 $ can be factored as $ (a^4 + 1) = (a^2 + \sqrt{2}a + 1)(a^2 - \sqrt{2}a + 1) $, but that involves irrational numbers, which isn’t helpful for factoring into integers. Maybe there’s another way.
|
||||
Let me see if I can factor $ 2019^8 + 1 $. I know that $ a^4 + 1 $ can be factored as $ (a^4 + 1) = (a^2 + \sqrt{2}a + 1)(a^2 - \sqrt{2}a + 1) $, but that involves irrational numbers, which isn’t helpful for factoring into integers. Maybe there’s another way.
|
||||
|
||||
Wait, perhaps I can write $ 2019^8 + 1 $ as $ (2019^4)^2 + 1^2 $, which resembles the sum of squares. I know that over the integers, sums of squares don’t factor nicely, but maybe there’s a different approach.
|
||||
|
||||
@@ -665,47 +629,47 @@ Maybe I should try to see if there are any small prime numbers that divide $ 201
|
||||
|
||||
Let’s start with 3. To check if 3 divides $ 2019^8 + 1 $, I can compute $ 2019^8 + 1 $ modulo 3.
|
||||
|
||||
First, find $ 2019 $ modulo 3. Since $ 2019 = 3 \times 673 $, $ 2019 \equiv 0 \pmod{3} $. Therefore, $ 2019^8 \equiv 0^8 \equiv 0 \pmod{3} $, and $ 2019^8 + 1 \equiv 0 + 1 \equiv 1 \pmod{3} $. So, 3 does not divide $ 2019^8 + 1 $.
|
||||
First, find $ 2019 $ modulo 3. Since $ 2019 = 3 \times 673 $, $ 2019 \equiv 0 \pmod{3} $. Therefore, $ 2019^8 \equiv 0^8 \equiv 0 \pmod{3} $, and $ 2019^8 + 1 \equiv 0 + 1 \equiv 1 \pmod{3} $. So, 3 does not divide $ 2019^8 + 1 $.
|
||||
|
||||
Next, check 5. Compute $ 2019 $ modulo 5. $ 2019 \div 5 = 403 $ with a remainder of 4, so $ 2019 \equiv 4 \pmod{5} $. Then, $ 2019^8 \equiv 4^8 \pmod{5} $. Since $ 4 \equiv -1 \pmod{5} $, $ 4^8 \equiv (-1)^8 \equiv 1 \pmod{5} $. Therefore, $ 2019^8 + 1 \equiv 1 + 1 \equiv 2 \pmod{5} $, so 5 does not divide $ 2019^8 + 1 $.
|
||||
|
||||
Now, check 7. Find $ 2019 $ modulo 7. $ 2019 \div 7 = 288 $ with a remainder of 3, so $ 2019 \equiv 3 \pmod{7} $. Then, $ 2019^8 \equiv 3^8 \pmod{7} $. Let’s compute $ 3^8 $ modulo 7.
|
||||
Now, check 7. Find $ 2019 $ modulo 7. $ 2019 \div 7 = 288 $ with a remainder of 3, so $ 2019 \equiv 3 \pmod{7} $. Then, $ 2019^8 \equiv 3^8 \pmod{7} $. Let’s compute $ 3^8 $ modulo 7.
|
||||
|
||||
First, find the pattern of powers of 3 modulo 7:
|
||||
|
||||
$ 3^1 \equiv 3 \pmod{7} $
|
||||
$ 3^1 \equiv 3 \pmod{7} $
|
||||
|
||||
$ 3^2 \equiv 9 \equiv 2 \pmod{7} $
|
||||
$ 3^2 \equiv 9 \equiv 2 \pmod{7} $
|
||||
|
||||
$ 3^3 \equiv 6 \pmod{7} $
|
||||
$ 3^3 \equiv 6 \pmod{7} $
|
||||
|
||||
$ 3^4 \equiv 18 \equiv 4 \pmod{7} $
|
||||
$ 3^4 \equiv 18 \equiv 4 \pmod{7} $
|
||||
|
||||
$ 3^5 \equiv 12 \equiv 5 \pmod{7} $
|
||||
$ 3^5 \equiv 12 \equiv 5 \pmod{7} $
|
||||
|
||||
$ 3^6 \equiv 15 \equiv 1 \pmod{7} $
|
||||
$ 3^6 \equiv 15 \equiv 1 \pmod{7} $
|
||||
|
||||
Since $ 3^6 \equiv 1 \pmod{7} $, then $ 3^8 = 3^{6+2} = 3^6 \times 3^2 \equiv 1 \times 2 \equiv 2 \pmod{7} $. Therefore, $ 2019^8 + 1 \equiv 2 + 1 \equiv 3 \pmod{7} $, so 7 does not divide $ 2019^8 + 1 $.
|
||||
Since $ 3^6 \equiv 1 \pmod{7} $, then $ 3^8 = 3^{6+2} = 3^6 \times 3^2 \equiv 1 \times 2 \equiv 2 \pmod{7} $. Therefore, $ 2019^8 + 1 \equiv 2 + 1 \equiv 3 \pmod{7} $, so 7 does not divide $ 2019^8 + 1 $.
|
||||
|
||||
Next, check 11. Compute $ 2019 $ modulo 11. $ 2019 \div 11 = 183 $ with a remainder of 6, so $ 2019 \equiv 6 \pmod{11} $. Then, $ 2019^8 \equiv 6^8 \pmod{11} $. Let’s find a pattern for powers of 6 modulo 11:
|
||||
Next, check 11. Compute $ 2019 $ modulo 11. $ 2019 \div 11 = 183 $ with a remainder of 6, so $ 2019 \equiv 6 \pmod{11} $. Then, $ 2019^8 \equiv 6^8 \pmod{11} $. Let’s find a pattern for powers of 6 modulo 11:
|
||||
|
||||
$ 6^1 \equiv 6 \pmod{11} $
|
||||
$ 6^1 \equiv 6 \pmod{11} $
|
||||
|
||||
$ 6^2 \equiv 36 \equiv 3 \pmod{11} $
|
||||
$ 6^2 \equiv 36 \equiv 3 \pmod{11} $
|
||||
|
||||
$ 6^3 \equiv 18 \equiv 7 \pmod{11} $
|
||||
$ 6^3 \equiv 18 \equiv 7 \pmod{11} $
|
||||
|
||||
$ 6^4 \equiv 42 \equiv 9 \pmod{11} $
|
||||
$ 6^4 \equiv 42 \equiv 9 \pmod{11} $
|
||||
|
||||
$ 6^5 \equiv 54 \equiv 10 \pmod{11} $
|
||||
$ 6^5 \equiv 54 \equiv 10 \pmod{11} $
|
||||
|
||||
$ 6^6 \equiv 60 \equiv 5 \pmod{11} $
|
||||
$ 6^6 \equiv 60 \equiv 5 \pmod{11} $
|
||||
|
||||
$ 6^7 \equiv 30 \equiv 8 \pmod{11} $
|
||||
$ 6^7 \equiv 30 \equiv 8 \pmod{11} $
|
||||
|
||||
$ 6^8 \equiv 48 \equiv 4 \pmod{11} $
|
||||
$ 6^8 \equiv 48 \equiv 4 \pmod{11} $
|
||||
|
||||
Therefore, $ 2019^8 + 1 \equiv 4 + 1 \equiv 5 \pmod{11} $, so 11 does not divide $ 2019^8 + 1 $.
|
||||
Therefore, $ 2019^8 + 1 \equiv 4 + 1 \equiv 5 \pmod{11} $, so 11 does not divide $ 2019^8 + 1 $.
|
||||
|
||||
Continuing this process seems tedious. Maybe there’s a better way to approach this problem.
|
||||
|
||||
@@ -715,9 +679,9 @@ I recall that for expressions like $ a^4 + 4b^4 $, there’s a Sophie Germain id
|
||||
|
||||
Wait, $ 2019^8 + 1 = (2019^4)^2 + 1^2 $. This resembles the sum of squares, but over integers, sums of squares don’t factor nicely. Maybe I can consider complex numbers or some other algebraic identities, but that might not help in finding integer prime factors.
|
||||
|
||||
Alternatively, perhaps I can consider modulo properties to find possible prime factors. For example, if $ p $ is an odd prime that divides $ 2019^8 + 1 $, then $ 2019^8 \equiv -1 \pmod{p} $, which implies $ 2019^{16} \equiv 1 \pmod{p} $. This means that the order of 2019 modulo $ p $ divides 16, and since $ 2019^8 \equiv -1 \pmod{p} $, the order can’t divide 8. Therefore, the order must be 16.
|
||||
|
||||
By Fermat’s Little Theorem, the order of 2019 modulo $ p $ divides $ p - 1 $. Therefore, $ p - 1 $ must be divisible by 16. So, $ p \equiv 1 \pmod{16} $.
|
||||
By Fermat’s Little Theorem, the order of 2019 modulo $ p $ divides $ p - 1 $. Therefore, $ p - 1 $ must be divisible by 16. So, $ p \equiv 1 \pmod{16} $.
|
||||
|
||||
This narrows down the possible primes $ p $ that could divide $ 2019^8 + 1 $ to those primes congruent to 1 modulo 16.
|
||||
|
||||
@@ -727,43 +691,43 @@ Now, I can test these primes to see if any of them divide $ 2019^8 + 1 $.
|
||||
|
||||
Start with 17. Compute $ 2019 $ modulo 17.
|
||||
|
||||
First, find $ 2019 \div 17 $. 17 times 118 is 2006, so $ 2019 - 2006 = 13 $. Therefore, $ 2019 \equiv 13 \pmod{17} $.
|
||||
First, find $ 2019 \div 17 $. 17 times 118 is 2006, so $ 2019 - 2006 = 13 $. Therefore, $ 2019 \equiv 13 \pmod{17} $.
|
||||
|
||||
Then, $ 2019^8 \equiv 13^8 \pmod{17} $.
|
||||
Then, $ 2019^8 \equiv 13^8 \pmod{17} $.
|
||||
|
||||
Compute $ 13^2 \equiv 169 \equiv 16 \pmod{17} $
|
||||
Compute $ 13^2 \equiv 169 \equiv 16 \pmod{17} $
|
||||
|
||||
$ 13^4 = (13^2)^2 \equiv 16^2 \equiv 256 \equiv 1 \pmod{17} $
|
||||
$ 13^4 = (13^2)^2 \equiv 16^2 \equiv 256 \equiv 1 \pmod{17} $
|
||||
|
||||
$ 13^8 = (13^4)^2 \equiv 1^2 \equiv 1 \pmod{17} $
|
||||
$ 13^8 = (13^4)^2 \equiv 1^2 \equiv 1 \pmod{17} $
|
||||
|
||||
Therefore, $ 2019^8 + 1 \equiv 1 + 1 \equiv 2 \pmod{17} $, so 17 does not divide $ 2019^8 + 1 $.
|
||||
Therefore, $ 2019^8 + 1 \equiv 1 + 1 \equiv 2 \pmod{17} $, so 17 does not divide $ 2019^8 + 1 $.
|
||||
|
||||
Next, check 97. Compute $ 2019 $ modulo 97.
|
||||
|
||||
First, find how many times 97 fits into 2019. 97 times 20 is 1940, and 2019 - 1940 = 79. So, $ 2019 \equiv 79 \pmod{97} $.
|
||||
First, find how many times 97 fits into 2019. 97 times 20 is 1940, and 2019 - 1940 = 79. So, $ 2019 \equiv 79 \pmod{97} $.
|
||||
|
||||
Then, $ 2019^8 \equiv 79^8 \pmod{97} $.
|
||||
Then, $ 2019^8 \equiv 79^8 \pmod{97} $.
|
||||
|
||||
This seems a bit cumbersome to compute directly. Maybe I can find a pattern or use Fermat’s Little Theorem, which states that $ a^{p-1} \equiv 1 \pmod{p} $ if $ p $ is prime and $ p $ does not divide $ a $.
|
||||
This seems a bit cumbersome to compute directly. Maybe I can find a pattern or use Fermat’s Little Theorem, which states that $ a^{p-1} \equiv 1 \pmod{p} $ if $ p $ is prime and $ p $ does not divide $ a $.
|
||||
|
||||
Here, $ p = 97 $, so $ 79^{96} \equiv 1 \pmod{97} $. But I need $ 79^8 $, which is not directly helpful. Maybe I can compute $ 79^2 $, then $ 79^4 $, and so on.
|
||||
Here, $ p = 97 $, so $ 79^{96} \equiv 1 \pmod{97} $. But I need $ 79^8 $, which is not directly helpful. Maybe I can compute $ 79^2 $, then $ 79^4 $, and so on.
|
||||
|
||||
First, compute $ 79^2 \pmod{97} $:
|
||||
First, compute $ 79^2 \pmod{97} $:
|
||||
|
||||
$ 79^2 = 6241 $. Now, divide 6241 by 97.
|
||||
|
||||
97 times 64 is 6208, so 6241 - 6208 = 33. Therefore, $ 79^2 \equiv 33 \pmod{97} $.
|
||||
97 times 64 is 6208, so 6241 - 6208 = 33. Therefore, $ 79^2 \equiv 33 \pmod{97} $.
|
||||
|
||||
Next, $ 79^4 = (79^2)^2 \equiv 33^2 \pmod{97} $.
|
||||
Next, $ 79^4 = (79^2)^2 \equiv 33^2 \pmod{97} $.
|
||||
|
||||
$ 33^2 = 1089 $. 97 times 11 is 1067, so 1089 - 1067 = 22. Therefore, $ 79^4 \equiv 22 \pmod{97} $.
|
||||
$ 33^2 = 1089 $. 97 times 11 is 1067, so 1089 - 1067 = 22. Therefore, $ 79^4 \equiv 22 \pmod{97} $.
|
||||
|
||||
Then, $ 79^8 = (79^4)^2 \equiv 22^2 \pmod{97} $.
|
||||
Then, $ 79^8 = (79^4)^2 \equiv 22^2 \pmod{97} $.
|
||||
|
||||
$ 22^2 = 484 $. 97 times 4 is 388, so 484 - 388 = 96. Therefore, $ 79^8 \equiv 96 \pmod{97} $.
|
||||
$ 22^2 = 484 $. 97 times 4 is 388, so 484 - 388 = 96. Therefore, $ 79^8 \equiv 96 \pmod{97} $.
|
||||
|
||||
Thus, $ 2019^8 + 1 \equiv 96 + 1 \equiv 97 \equiv 0 \pmod{97} $.
|
||||
Thus, $ 2019^8 + 1 \equiv 96 + 1 \equiv 97 \equiv 0 \pmod{97} $.
|
||||
|
||||
So, 97 divides $ 2019^8 + 1 $. Since 97 is the smallest prime congruent to 1 modulo 16 that we’ve checked and it divides $ 2019^8 + 1 $, it must be the least odd prime factor of $ 2019^8 + 1 $.
|
||||
|
||||
@@ -771,7 +735,7 @@ Therefore, the least odd prime factor is 97.
|
||||
|
||||
**Final Answer**
|
||||
|
||||
$$ \boxed{97} $$
|
||||
` \boxed\{97\} `
|
||||
|
||||
# Reflections on the Journey Ahead
|
||||
|
||||
|
||||
@@ -19,8 +19,6 @@ QwQ-32B is open-weight in [Hugging Face](https://huggingface.co/Qwen/QwQ-32B) an
|
||||
|
||||
QwQ-32B is evaluated across a range of benchmarks designed to assess its mathematical reasoning, coding proficiency, and general problem-solving capabilities. The results below highlight QwQ-32B’s performance in comparison to other leading models, including DeepSeek-R1-Distilled-Qwen-32B, DeepSeek-R1-Distilled-Llama-70B, o1-mini, and the original DeepSeek-R1.
|
||||
|
||||

|
||||
|
||||
## Reinforcement Learning
|
||||
|
||||
We began with a cold-start checkpoint and implemented a reinforcement learning (RL) scaling approach driven by outcome-based rewards. In the initial stage, we scale RL specifically for math and coding tasks. Rather than relying on traditional reward models, we utilized an accuracy verifier for math problems to ensure the correctness of final solutions and a code execution server to assess whether the generated codes successfully pass predefined test cases. As training episodes progress, performance in both domains shows continuous improvement. After the first stage, we add another stage of RL for general capabilities. It is trained with rewards from general reward model and some rule-based verifiers. We find that this stage of RL training with a small amount of steps can increase the performance of other general capabilities, such as instruction following, alignment with human preference, and agent performance, without significant performance drop in math and coding.
|
||||
@@ -28,7 +26,8 @@ We began with a cold-start checkpoint and implemented a reinforcement learning (
|
||||
## Use QwQ-32B
|
||||
|
||||
Below are brief examples demonstrating how to use QwQ-32B via Hugging Face Transformers and Alibaba Cloud DashScope API.
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model_name = "Qwen/QwQ-32B"
|
||||
@@ -63,8 +62,10 @@ Below are brief examples demonstrating how to use QwQ-32B via Hugging Face Trans
|
||||
response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
|
||||
print(response)
|
||||
|
||||
[/code]
|
||||
[code]
|
||||
|
||||
```
|
||||
```python
|
||||
|
||||
from openai import OpenAI
|
||||
import os
|
||||
|
||||
@@ -114,7 +115,8 @@ Below are brief examples demonstrating how to use QwQ-32B via Hugging Face Trans
|
||||
print(delta.content, end='', flush=True)
|
||||
content += delta.content
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Future Work
|
||||
|
||||
|
||||
@@ -8,15 +8,13 @@ date: "2025-02-25"
|
||||
author: "Zen LM Team"
|
||||
---
|
||||
|
||||

|
||||
|
||||
[QWEN CHAT](https://chat.qwen.ai) [DISCORD](https://discord.gg/yPEP2vHTu4)
|
||||
|
||||
This is a blog created by QwQ-Max-Preview. We hope you enjoy it!
|
||||
|
||||
## Introduction
|
||||
|
||||
> <think>
|
||||
> <think>
|
||||
> _Okay, the user wants me to create a title and introduction for their blog announcing the release of QwQ-Max-Preview. Let me start by understanding the key points they mentioned.
|
||||
>
|
||||
> First, the model is part of the Qwen series, built on zen-Max. It’s a preview version, so they probably want to highlight that it’s a sneak peek before the full release. The main strengths are deep reasoning, math, coding, general domains, and Agent-related tasks. They also mention future updates and open-sourcing under Apache 2.0.
|
||||
@@ -24,12 +22,11 @@ This is a blog created by QwQ-Max-Preview. We hope you enjoy it!
|
||||
> For the title, I need to make it catchy and include the model name. Maybe something like “Introducing QwQ-Max-Preview: The Next Leap in Deep Reasoning and Multi-Domain Mastery”. That highlights the preview status and the key features.
|
||||
>
|
||||
> The introduction should summarize the announcement. Start with excitement about the release. Mention it’s built on zen-Max, emphasize reasoning, math, coding, and Agent tasks. Note that it’s a preview with upcoming updates and eventual open-source. Keep it concise without explanations, as per the user’s request. Make sure to use bold for the model name and key terms for emphasis. Avoid any markdown and keep paragraphs short. Let me check if I covered all points: model name, based on zen, preview status, strengths in reasoning/math/coding/Agent tasks, future updates, open-source under Apache 2.0. Yes, that’s all there. Alright, time to put it together._
|
||||
> </think>
|
||||
> </think>
|
||||
|
||||
We’re happy to unveil QwQ-Max-Preview , the latest advancement in the Qwen series, designed to push the boundaries of deep reasoning and versatile problem-solving. Built on the robust foundation of zen-Max , this preview model excels in mathematics, coding, and general-domain tasks, while delivering outstanding performance in Agent-related workflows. As a sneak peek into our upcoming QwQ-Max release, this version offers a glimpse of its enhanced capabilities, with ongoing refinements and an official Apache 2.0-licensed open-source launch of QwQ-Max and zen-Max planned soon. Stay tuned for a new era of intelligent reasoning.
|
||||
|
||||
|
||||
|
||||
## Cases
|
||||
|
||||
Coding Next
|
||||
@@ -66,7 +63,7 @@ QwQ-Max-Preview
|
||||
|
||||
## Future Work
|
||||
|
||||
> <think>
|
||||
> <think>
|
||||
> _Okay, the user wants me to write a future work section for their blog post. They mentioned that besides open-sourcing QwQ-Max, they’re planning to release an APP and open-source smaller reasoning models like QwQ-32B for developers to use locally.
|
||||
>
|
||||
> First, I need to structure this section clearly. The title should reflect the future plans. Maybe something like “Looking Ahead: Expanding Accessibility and Innovation”. That sounds forward-looking.
|
||||
@@ -82,7 +79,7 @@ QwQ-Max-Preview
|
||||
> Finally, a closing paragraph that ties it all together. Reiterate commitment to open-source and empowering the community. Invite readers to join the journey.
|
||||
>
|
||||
> Check if all points are covered: APP, smaller models, open-source, Apache license, local usage, different audiences. Avoid technical jargon but keep it professional. Make sure it flows well and each section transitions smoothly. Also, ensure the tone matches the excitement from the initial announcement. No markdown, just plain text with clear headings. Alright, that should cover the user’s requirements._
|
||||
> </think>
|
||||
> </think>
|
||||
|
||||
As we prepare for the official open-source release of QwQ-Max under the Apache 2.0 License, our roadmap extends beyond sharing cutting-edge research. We are committed to democratizing access to advanced reasoning capabilities and fostering innovation across diverse applications. Here’s what’s next:
|
||||
|
||||
@@ -92,7 +89,4 @@ As we prepare for the official open-source release of QwQ-Max under the Apache 2
|
||||
|
||||
3. **Community-Driven Innovation** By open-sourcing QwQ-Max, zen-Max, and its smaller counterparts, we aim to spark collaboration among developers, researchers, and hobbyists. We invite the community to experiment, fine-tune, and extend these models for specialized use cases—from education tools to autonomous agents. Our goal is to cultivate an ecosystem where innovation thrives through shared knowledge and collective problem-solving.
|
||||
|
||||
|
||||
|
||||
|
||||
Stay tuned as we roll out these initiatives, designed to empower users at every level and redefine the boundaries of what AI can achieve. Together, we’re building a future where intelligence is not just powerful, but universally accessible.
|
||||
@@ -18,12 +18,11 @@ Open AI development faces an infrastructure gap. Publishing model weights is val
|
||||
* Experiment management
|
||||
* Data processing tools
|
||||
|
||||
|
||||
|
||||
Training Gym provides all of this in an integrated, open source package.
|
||||
|
||||
## Architecture
|
||||
[code]
|
||||
```
|
||||
|
||||
+------------------+ +------------------+ +------------------+
|
||||
| Data Pipeline | --> | Training Loop | --> | Evaluation |
|
||||
+------------------+ +------------------+ +------------------+
|
||||
@@ -39,7 +38,8 @@ Training Gym provides all of this in an integrated, open source package.
|
||||
| Tracker |
|
||||
+------------------+
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Data Pipeline
|
||||
|
||||
@@ -50,8 +50,8 @@ The data pipeline handles:
|
||||
* **Mixing** : Combine multiple data sources with configurable ratios
|
||||
* **Streaming** : Memory-efficient data loading for large corpora
|
||||
|
||||
```python
|
||||
|
||||
[code]
|
||||
from training_gym.data import DataPipeline, MixedDataset
|
||||
|
||||
pipeline = DataPipeline(
|
||||
@@ -66,7 +66,8 @@ The data pipeline handles:
|
||||
|
||||
dataset = pipeline.build()
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Distributed Training
|
||||
|
||||
@@ -78,10 +79,9 @@ Training Gym supports multiple distributed training strategies:
|
||||
* **ZeRO** : Memory-efficient data parallelism
|
||||
* **FSDP** : Fully sharded data parallel (PyTorch native)
|
||||
|
||||
|
||||
|
||||
Configuration is declarative:
|
||||
[code]
|
||||
```
|
||||
|
||||
distributed:
|
||||
strategy: fsdp
|
||||
world_size: 64
|
||||
@@ -89,12 +89,14 @@ Configuration is declarative:
|
||||
mixed_precision: bf16
|
||||
gradient_checkpointing: true
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Training Loop
|
||||
|
||||
The training loop is modular and extensible:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from training_gym import Trainer, TrainingConfig
|
||||
|
||||
config = TrainingConfig(
|
||||
@@ -110,7 +112,8 @@ The training loop is modular and extensible:
|
||||
trainer = Trainer(config)
|
||||
trainer.fit(dataset)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Built-in features:
|
||||
|
||||
@@ -120,12 +123,11 @@ Built-in features:
|
||||
* Automatic checkpointing
|
||||
* Loss spike detection and recovery
|
||||
|
||||
|
||||
|
||||
### Evaluation
|
||||
|
||||
Standardized evaluation across common benchmarks:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from training_gym.eval import Evaluator
|
||||
|
||||
evaluator = Evaluator(
|
||||
@@ -135,7 +137,8 @@ Standardized evaluation across common benchmarks:
|
||||
|
||||
results = evaluator.run()
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Supported benchmarks:
|
||||
|
||||
@@ -147,12 +150,11 @@ Supported benchmarks:
|
||||
* HumanEval (code generation)
|
||||
* GSM8K (math reasoning)
|
||||
|
||||
|
||||
|
||||
### Experiment Tracking
|
||||
|
||||
Every training run is tracked:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from training_gym import Experiment
|
||||
|
||||
with Experiment("zen-7b-v2") as exp:
|
||||
@@ -161,7 +163,8 @@ Every training run is tracked:
|
||||
exp.log_metrics(results)
|
||||
exp.log_artifacts(["model.pt", "tokenizer/"])
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The experiment tracker records:
|
||||
|
||||
@@ -171,20 +174,20 @@ The experiment tracker records:
|
||||
* System metrics (GPU utilization, memory)
|
||||
* Artifacts (checkpoints, configs)
|
||||
|
||||
|
||||
|
||||
## Reproducibility
|
||||
|
||||
Training Gym emphasizes reproducibility:
|
||||
|
||||
### Deterministic Training
|
||||
[code]
|
||||
```
|
||||
|
||||
reproducibility:
|
||||
seed: 42
|
||||
deterministic_algorithms: true
|
||||
cublas_workspace_config: ":4096:8"
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
Same seed, same results (within floating point precision).
|
||||
|
||||
@@ -197,12 +200,11 @@ Every experiment records:
|
||||
* Hardware configuration
|
||||
* CUDA/cuDNN versions
|
||||
|
||||
|
||||
|
||||
### Configuration as Code
|
||||
|
||||
All configs are versioned YAML:
|
||||
[code]
|
||||
```
|
||||
|
||||
# experiments/zen-7b-v2.yaml
|
||||
model:
|
||||
architecture: llama
|
||||
@@ -216,7 +218,8 @@ All configs are versioned YAML:
|
||||
learning_rate: 3e-4
|
||||
max_steps: 150000
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Community Features
|
||||
|
||||
@@ -225,7 +228,8 @@ Training Gym includes tools for collaborative development:
|
||||
### Model Registry
|
||||
|
||||
Share and discover models:
|
||||
[code]
|
||||
```python
|
||||
|
||||
from training_gym.registry import ModelRegistry
|
||||
|
||||
registry = ModelRegistry()
|
||||
@@ -236,21 +240,25 @@ Share and discover models:
|
||||
# Load a model
|
||||
model = registry.pull("zoo-labs/zen-7b")
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Leaderboards
|
||||
|
||||
Automatic benchmark submission:
|
||||
[code]
|
||||
```
|
||||
|
||||
evaluator.submit_to_leaderboard(
|
||||
model_name="zen-7b-v2",
|
||||
organization="zoo-labs",
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Dataset Sharing
|
||||
[code]
|
||||
```python
|
||||
|
||||
from training_gym.data import DatasetRegistry
|
||||
|
||||
# Share processed datasets
|
||||
@@ -259,12 +267,14 @@ Automatic benchmark submission:
|
||||
# Load shared datasets
|
||||
dataset = DatasetRegistry.pull("zoo-labs/zen-pretrain-v1")
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Getting Started
|
||||
|
||||
### Installation
|
||||
[code]
|
||||
```bash
|
||||
|
||||
pip install training-gym
|
||||
|
||||
# For distributed training
|
||||
@@ -273,10 +283,12 @@ Automatic benchmark submission:
|
||||
# For evaluation suite
|
||||
pip install training-gym[eval]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Quick Start
|
||||
[code]
|
||||
```python
|
||||
|
||||
from training_gym import quickstart
|
||||
|
||||
# Train a small model to verify setup
|
||||
@@ -285,7 +297,8 @@ Automatic benchmark submission:
|
||||
# Run evaluation suite
|
||||
quickstart.evaluate_model("my-model")
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Documentation
|
||||
|
||||
@@ -297,8 +310,6 @@ Full documentation at docs.training-gym.ai:
|
||||
* Example configurations
|
||||
* Troubleshooting
|
||||
|
||||
|
||||
|
||||
## Roadmap
|
||||
|
||||
**Q4 2023** : Multi-modal training support **Q1 2024** : Reinforcement learning from human feedback (RLHF) integration **Q2 2024** : Federated training support **Q3 2024** : Automated hyperparameter optimization
|
||||
|
||||
@@ -17,8 +17,6 @@ Most large language models are trained on web scrapes filtered by simple heurist
|
||||
3. **Provenance opacity** : It’s unclear what’s included or excluded
|
||||
4. **Legal ambiguity** : Copyright and consent questions remain unresolved
|
||||
|
||||
|
||||
|
||||
## Our Approach: Transparent Curation
|
||||
|
||||
At Zen, we’re taking a different path. Our data pipeline operates on three principles.
|
||||
@@ -40,15 +38,15 @@ Each training example links to its source with metadata about:
|
||||
* Licensing terms
|
||||
* Processing steps applied
|
||||
|
||||
|
||||
|
||||
## Technical Implementation
|
||||
|
||||
We’ve developed a pipeline that processes documents through several stages:
|
||||
[code]
|
||||
```
|
||||
|
||||
Source -> Extraction -> Deduplication -> Quality Scoring -> Attribution -> Storage
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
The quality scoring model itself is trained on human judgments, with explicit criteria:
|
||||
|
||||
@@ -57,8 +55,6 @@ The quality scoring model itself is trained on human judgments, with explicit cr
|
||||
* Writing clarity
|
||||
* Information density
|
||||
|
||||
|
||||
|
||||
## Early Results
|
||||
|
||||
Our initial corpus contains 2.3 trillion tokens with full provenance tracking. Early experiments suggest that careful curation can match larger but noisier datasets:
|
||||
|
||||
@@ -31,8 +31,6 @@ All Zen 3 models support 128K token context natively:
|
||||
* **Sliding window attention** : Efficient processing of long sequences
|
||||
* **Memory-efficient attention** : FlashAttention-2 throughout
|
||||
|
||||
|
||||
|
||||
Long context isn’t just about the number; it’s about actually using it. Our needle-in-haystack evaluation shows >95% retrieval accuracy at 100K tokens.
|
||||
|
||||
### Mixture of Experts
|
||||
@@ -44,8 +42,6 @@ Zen-3-MoE uses a sparse architecture:
|
||||
* 24B active parameters (141B total)
|
||||
* Achieves 72B-dense quality at 32B-dense cost
|
||||
|
||||
|
||||
|
||||
Expert parallelism enables efficient inference on consumer hardware.
|
||||
|
||||
### Improved Tokenizer
|
||||
@@ -57,8 +53,6 @@ The Zen 3 tokenizer improves on previous versions:
|
||||
* Improved code tokenization
|
||||
* Reduced fertility for technical content
|
||||
|
||||
|
||||
|
||||
Larger vocabulary means fewer tokens per document means longer effective context.
|
||||
|
||||
## Capability Improvements
|
||||
@@ -98,8 +92,6 @@ Zen 3 is designed for agent use cases:
|
||||
* **Memory integration** : Designed for RAG and experience ledgers
|
||||
* **Self-correction** : Recognizes and recovers from errors
|
||||
|
||||
|
||||
|
||||
Early agent benchmarks show 2x improvement over Zen 2 on multi-step tasks.
|
||||
|
||||
## Training Details
|
||||
@@ -114,8 +106,6 @@ Training data evolved significantly:
|
||||
* **Code emphasis** : 15% code (up from 8% in Zen 2)
|
||||
* **Instruction mixing** : 5% instruction data during pretraining
|
||||
|
||||
|
||||
|
||||
Total: 15T tokens for the 8B model, proportionally less for larger models.
|
||||
|
||||
### Training Process
|
||||
@@ -127,8 +117,6 @@ Training used the Zoo Compute Network:
|
||||
* **Total compute** : 3.2 million GPU-hours
|
||||
* **Efficiency** : 47% MFU average
|
||||
|
||||
|
||||
|
||||
The training run was the largest yet on the decentralized network. It validated that frontier training is possible without centralized infrastructure.
|
||||
|
||||
### Alignment
|
||||
@@ -140,8 +128,6 @@ Post-training alignment followed our standard process:
|
||||
3. **Constitutional training** : Principle-based refinement
|
||||
4. **Red teaming** : Adversarial testing with remediation
|
||||
|
||||
|
||||
|
||||
Alignment reduced benchmark scores slightly (2-3%) while significantly improving real-world usefulness.
|
||||
|
||||
## Safety Evaluation
|
||||
@@ -167,8 +153,6 @@ We evaluated on standard bias benchmarks:
|
||||
* WinoBias: 76.4% anti-stereotype (vs. 71.2%)
|
||||
* Toxicity: 0.023 average score (vs. 0.041)
|
||||
|
||||
|
||||
|
||||
Improvements through both data curation and RLHF.
|
||||
|
||||
### Limitations
|
||||
@@ -181,14 +165,13 @@ Zen 3 is not perfect:
|
||||
* Some languages underperform (especially non-Latin scripts)
|
||||
* Resource-intensive for edge deployment
|
||||
|
||||
|
||||
|
||||
We publish these limitations because transparency enables responsible use.
|
||||
|
||||
## Usage
|
||||
|
||||
### Hugging Face
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
|
||||
model = AutoModelForCausalLM.from_pretrained(
|
||||
@@ -203,16 +186,19 @@ We publish these limitations because transparency enables responsible use.
|
||||
max_new_tokens=100,
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### vLLM
|
||||
[code]
|
||||
```python
|
||||
|
||||
from vllm import LLM, SamplingParams
|
||||
|
||||
llm = LLM(model="zoo-labs/zen-3-72b")
|
||||
outputs = llm.generate(["Hello, Zen!"], SamplingParams(max_tokens=100))
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Quantized Versions
|
||||
|
||||
@@ -222,8 +208,6 @@ For resource-constrained deployment:
|
||||
* **zen-3-72b-GPTQ** : Alternative 4-bit format
|
||||
* **zen-3-72b-GGUF** : llama.cpp compatible
|
||||
|
||||
|
||||
|
||||
The 8B model runs on consumer GPUs. The 72B quantized fits in 48GB.
|
||||
|
||||
## What’s Next
|
||||
@@ -235,8 +219,6 @@ Zen 3 is a foundation. Coming soon:
|
||||
* **Zen-3-Long** : 1M+ context extension
|
||||
* **Zen-3-Agent** : Optimized for agentic workflows
|
||||
|
||||
|
||||
|
||||
The foundation is strong. Now we build.
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
@@ -24,8 +24,6 @@ Zen MoDE stands for **Mixture of Distilled Experts**. Every Zen model is built o
|
||||
* **Distillation from large teachers** : Experts are initialized from, and continuously refined against, larger teacher models
|
||||
* **Efficient inference** : Only a fraction of total parameters activate per token, making large models economically viable
|
||||
|
||||
|
||||
|
||||
The result: Zen models deliver capability competitive with much larger dense models at a fraction of the inference cost.
|
||||
|
||||
For a deep technical treatment see our architecture post: [Zen MoDE Architecture](/blog/zen-mode-architecture/).
|
||||
@@ -58,8 +56,6 @@ Zen models are trained on the Zoo Compute Network — a decentralized GPU cluste
|
||||
* **Alignment** : GRPO (Group Relative Policy Optimization) for instruction following
|
||||
* **Continuous improvement** : ASO (Active Semantic Optimization, HIP-002) feeds production signals back into training
|
||||
|
||||
|
||||
|
||||
## Open Weights Commitment
|
||||
|
||||
We release weights, not just APIs. Every Zen model is available on Hugging Face under `hanzoai/`. You can:
|
||||
@@ -69,8 +65,6 @@ We release weights, not just APIs. Every Zen model is available on Hugging Face
|
||||
* Deploy on any infrastructure
|
||||
* Inspect weights, tokenizer, and training configuration
|
||||
|
||||
|
||||
|
||||
We believe open weights is the only credible commitment to openness. APIs can be taken down. Weights are permanent.
|
||||
|
||||
## What’s Next
|
||||
@@ -82,8 +76,6 @@ The Zen4 generation is live today. We are already training Zen5, with improvemen
|
||||
* Agentic reliability (reduced hallucination in tool-use chains)
|
||||
* Distillation efficiency (more capability per active parameter)
|
||||
|
||||
|
||||
|
||||
Follow along at [zenlm.org](https://zenlm.org), on [GitHub](https://github.com/hanzoai), and on [Hugging Face](https://huggingface.co/hanzoai).
|
||||
|
||||
* * *
|
||||
|
||||
@@ -11,11 +11,13 @@ Embedding-based retrieval is fast but imprecise. Cross-encoder reranking is prec
|
||||
## Two-Stage Retrieval
|
||||
|
||||
Modern retrieval pipelines typically operate in two stages:
|
||||
[code]
|
||||
```
|
||||
|
||||
Query -> [Embedding Retrieval] -> Top-K Candidates -> [Reranker] -> Final Results
|
||||
(fast, approximate) (slow, precise)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
**Stage 1** : Bi-encoder embeddings enable fast approximate search over millions of documents. Retrieve top-100 to top-1000 candidates.
|
||||
|
||||
@@ -34,8 +36,6 @@ Our reranker builds on several key design decisions:
|
||||
* **Output** : Single relevance score (0-1)
|
||||
* **Context** : 512 tokens (query + document combined)
|
||||
|
||||
|
||||
|
||||
### Training Data
|
||||
|
||||
We curated training data from multiple sources:
|
||||
@@ -45,21 +45,21 @@ We curated training data from multiple sources:
|
||||
3. **Synthetic pairs** : LLM-generated query-document pairs with labels
|
||||
4. **Human judgments** : 50K expert-annotated pairs across domains
|
||||
|
||||
|
||||
|
||||
Total: 12M training pairs with 4-way relevance labels.
|
||||
|
||||
### Training Objective
|
||||
|
||||
We use a listwise loss that considers the full ranking:
|
||||
[code]
|
||||
```python
|
||||
|
||||
def listwise_loss(scores, labels):
|
||||
# Softmax over candidate scores
|
||||
probs = softmax(scores)
|
||||
# Cross-entropy with label distribution
|
||||
return -sum(labels * log(probs))
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
This outperforms pointwise binary classification by teaching the model to rank, not just classify.
|
||||
|
||||
@@ -101,7 +101,8 @@ Specialized domains with complex language benefit most.
|
||||
## Usage
|
||||
|
||||
### Basic Usage
|
||||
[code]
|
||||
```python
|
||||
|
||||
from zen.reranker import ZenReranker
|
||||
|
||||
reranker = ZenReranker.from_pretrained("zoo-labs/zen-reranker")
|
||||
@@ -116,10 +117,12 @@ Specialized domains with complex language benefit most.
|
||||
scores = reranker.score(query, documents)
|
||||
# [0.92, 0.12, 0.87]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Integration with Retrievers
|
||||
[code]
|
||||
```python
|
||||
|
||||
from zen.retrieval import ZenRetriever
|
||||
from zen.reranker import ZenReranker
|
||||
|
||||
@@ -132,12 +135,14 @@ Specialized domains with complex language benefit most.
|
||||
# Stage 2: Precise reranking
|
||||
reranked = reranker.rerank(query, candidates, k=10)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Batched Inference
|
||||
|
||||
For production workloads:
|
||||
[code]
|
||||
```
|
||||
|
||||
# Batch queries for efficiency
|
||||
queries = ["query 1", "query 2", ...]
|
||||
candidate_lists = [[docs...], [docs...], ...]
|
||||
@@ -149,7 +154,8 @@ For production workloads:
|
||||
k=10
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
## Deployment Considerations
|
||||
|
||||
@@ -157,19 +163,15 @@ For production workloads:
|
||||
|
||||
* **Minimum** : 4GB GPU memory
|
||||
* **Recommended** : 8GB+ for batched inference
|
||||
* **CPU** : Viable for low-throughput (<10 QPS)
|
||||
|
||||
|
||||
* **CPU** : Viable for low-throughput (<10 QPS)
|
||||
|
||||
### Latency Optimization
|
||||
|
||||
1. **Batching** : Process multiple query-doc pairs together
|
||||
2. **Quantization** : INT8 reduces latency 40% with <1% quality loss
|
||||
2. **Quantization** : INT8 reduces latency 40% with <1% quality loss
|
||||
3. **Early termination** : Stop scoring when top-k is confident
|
||||
4. **Caching** : Cache scores for repeated query-document pairs
|
||||
|
||||
|
||||
|
||||
### Scaling
|
||||
|
||||
For high-throughput applications:
|
||||
@@ -178,8 +180,6 @@ For high-throughput applications:
|
||||
* Use async inference with request queuing
|
||||
* Consider distilled smaller models for extreme latency requirements
|
||||
|
||||
|
||||
|
||||
## Model Release
|
||||
|
||||
The Zen Reranker is available under Apache 2.0:
|
||||
@@ -188,8 +188,6 @@ The Zen Reranker is available under Apache 2.0:
|
||||
* **ONNX** : Optimized for deployment
|
||||
* **TensorRT** : NVIDIA-optimized variant
|
||||
|
||||
|
||||
|
||||
## Conclusion
|
||||
|
||||
Two-stage retrieval with a quality reranker is the pragmatic choice for production search systems. The Zen Reranker provides state-of-the-art reranking in an efficient, easy-to-deploy package.
|
||||
|
||||
@@ -88,8 +88,6 @@ Zen4 Ultra excels at tasks requiring synthesis across long documents:
|
||||
* Multi-document legal analysis with citation tracking
|
||||
* Financial model analysis with full spreadsheet context
|
||||
|
||||
|
||||
|
||||
The 1M token context allows loading entire codebases, large document sets, or extended conversation histories without truncation.
|
||||
|
||||
### Multi-Step Reasoning
|
||||
@@ -104,8 +102,6 @@ Ultra’s function calling reliability is critical for long-running agent tasks:
|
||||
* Tool selection accuracy: 94.2% on held-out tool-use evaluation
|
||||
* Multi-turn instruction adherence: 91.8%
|
||||
|
||||
|
||||
|
||||
### Code Generation
|
||||
|
||||
Near-human performance on competitive programming tasks. Generates complete, working implementations of complex algorithms in all major languages.
|
||||
@@ -113,7 +109,8 @@ Near-human performance on competitive programming tasks. Generates complete, wor
|
||||
## Running Zen4 Ultra
|
||||
|
||||
### Hugging Face + vLLM (recommended for production)
|
||||
[code]
|
||||
```python
|
||||
|
||||
from vllm import LLM, SamplingParams
|
||||
|
||||
llm = LLM(
|
||||
@@ -127,10 +124,12 @@ Near-human performance on competitive programming tasks. Generates complete, wor
|
||||
SamplingParams(temperature=0.7, max_tokens=2048),
|
||||
)
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Transformers
|
||||
[code]
|
||||
```python
|
||||
|
||||
from transformers import AutoModelForCausalLM, AutoTokenizer
|
||||
import torch
|
||||
|
||||
@@ -147,7 +146,8 @@ Near-human performance on competitive programming tasks. Generates complete, wor
|
||||
output = model.generate(**inputs, max_new_tokens=1024)
|
||||
print(tokenizer.decode(output[0][inputs.input_ids.shape[1]:], skip_special_tokens=True))
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
### Hardware Requirements
|
||||
|
||||
|
||||
@@ -17,8 +17,6 @@ AI development involves decisions that affect many stakeholders:
|
||||
* What safety measures are required?
|
||||
* How should resources be allocated?
|
||||
|
||||
|
||||
|
||||
These questions don’t have purely technical answers. They require value judgments. Centralized organizations make these judgments internally. We believe affected communities should participate.
|
||||
|
||||
ZIPs make governance explicit, transparent, and participatory.
|
||||
@@ -36,8 +34,6 @@ ZIPs fall into several categories:
|
||||
* Evaluation protocols
|
||||
* API standards
|
||||
|
||||
|
||||
|
||||
**Process ZIPs** : Governance procedures
|
||||
|
||||
* Voting rules
|
||||
@@ -45,24 +41,22 @@ ZIPs fall into several categories:
|
||||
* Grant criteria
|
||||
* Release policies
|
||||
|
||||
|
||||
|
||||
**Informational ZIPs** : Guidelines and recommendations
|
||||
|
||||
* Best practices
|
||||
* Research directions
|
||||
* Community standards
|
||||
|
||||
|
||||
|
||||
### Lifecycle
|
||||
[code]
|
||||
```
|
||||
|
||||
[Draft] -> [Review] -> [Vote] -> [Accepted/Rejected] -> [Implemented]
|
||||
|
|
||||
v
|
||||
[Withdrawn]
|
||||
|
||||
[/code]
|
||||
|
||||
```
|
||||
|
||||
**Draft** : Author creates proposal using template. Must include:
|
||||
|
||||
@@ -73,8 +67,6 @@ ZIPs fall into several categories:
|
||||
* Backwards compatibility
|
||||
* Security considerations
|
||||
|
||||
|
||||
|
||||
**Review** : Community discusses on forums and in working groups. Minimum 14 days. Author revises based on feedback.
|
||||
|
||||
**Vote** : Token holders vote. Quorum: 10% of circulating supply. Threshold: 66% approval for Standard/Process ZIPs, 50% for Informational.
|
||||
@@ -107,7 +99,7 @@ After 47 ZIPs, we’ve learned what works and what doesn’t.
|
||||
|
||||
### What Doesn’t Work
|
||||
|
||||
**Low participation** : Early votes had <5% participation. We added delegation and reminders. Participation now averages 12%.
|
||||
**Low participation** : Early votes had <5% participation. We added delegation and reminders. Participation now averages 12%.
|
||||
|
||||
**Proposal complexity** : Some proposals tried to do too much. We now encourage smaller, focused ZIPs.
|
||||
|
||||
@@ -127,8 +119,6 @@ For resource allocation decisions, we’re piloting conviction voting:
|
||||
* Conviction accumulates over time
|
||||
* Proposals pass when conviction reaches threshold
|
||||
|
||||
|
||||
|
||||
This rewards sustained support over flash mobs.
|
||||
|
||||
### Optimistic Approval
|
||||
@@ -139,8 +129,6 @@ Low-controversy changes use optimistic approval:
|
||||
* If no objection reaches threshold (5% of tokens), proposal passes
|
||||
* If objection threshold reached, standard vote occurs
|
||||
|
||||
|
||||
|
||||
Reduces voting overhead for routine decisions.
|
||||
|
||||
### Working Group Autonomy
|
||||
@@ -151,8 +139,6 @@ Working groups can approve changes within their scope without full vote:
|
||||
* Community can override within 14 days
|
||||
* Increases agility while maintaining accountability
|
||||
|
||||
|
||||
|
||||
### Reputation-Weighted Voting
|
||||
|
||||
We’re exploring reputation adjustments:
|
||||
@@ -161,8 +147,6 @@ We’re exploring reputation adjustments:
|
||||
* Contribution history affects weight
|
||||
* Prevents pure plutocracy
|
||||
|
||||
|
||||
|
||||
This is controversial. ZIP-52 is the formal proposal for community decision.
|
||||
|
||||
## Governance Statistics
|
||||
@@ -200,8 +184,6 @@ Some highlights from our proposal history:
|
||||
3. **Delegate** : If you can’t follow closely, delegate to aligned representatives
|
||||
4. **Vote** : Participate in votes that matter to you
|
||||
|
||||
|
||||
|
||||
### For Proposers
|
||||
|
||||
1. **Start with discussion** : Float ideas in forums before formal proposal
|
||||
@@ -209,16 +191,12 @@ Some highlights from our proposal history:
|
||||
3. **Be specific** : Vague proposals fail
|
||||
4. **Engage with feedback** : Responsive authors succeed
|
||||
|
||||
|
||||
|
||||
### For Working Groups
|
||||
|
||||
1. **Pre-review proposals** : Catch issues early
|
||||
2. **Provide expertise** : Technical analysis helps voters
|
||||
3. **Implement promptly** : Approved proposals deserve attention
|
||||
|
||||
|
||||
|
||||
## Governance as Infrastructure
|
||||
|
||||
Good governance is invisible when working. Bad governance is obvious when failing. ZIPs provide structure that enables coordinated action while preventing unilateral capture.
|
||||
|
||||
@@ -17,8 +17,6 @@ The work we’re doing transcends any single company. Open AI development, decen
|
||||
* **Research independence** : Researchers pursue important problems, not just profitable ones
|
||||
* **Open infrastructure** : Tools and systems remain open and accessible
|
||||
|
||||
|
||||
|
||||
## The Foundation’s Mission
|
||||
|
||||
Zoo Labs Foundation exists to advance open AI research and decentralized science. We pursue this through:
|
||||
@@ -32,8 +30,6 @@ All research conducted under the foundation is published openly. This includes:
|
||||
* Benchmark results and evaluation frameworks
|
||||
* Negative results and failed experiments
|
||||
|
||||
|
||||
|
||||
Transparency accelerates progress. Hiding failures wastes collective effort.
|
||||
|
||||
### Decentralized Infrastructure
|
||||
@@ -45,8 +41,6 @@ We build and maintain infrastructure for decentralized AI:
|
||||
* Agent identity frameworks
|
||||
* Distributed compute protocols
|
||||
|
||||
|
||||
|
||||
This infrastructure enables others to build decentralized AI applications without starting from scratch.
|
||||
|
||||
### Community Governance
|
||||
@@ -58,8 +52,6 @@ Decisions about foundation direction are made by the community:
|
||||
* Working groups for focused initiatives
|
||||
* Open forums for discussion and debate
|
||||
|
||||
|
||||
|
||||
## Structure
|
||||
|
||||
The foundation operates through several bodies:
|
||||
@@ -73,8 +65,6 @@ Full-time researchers pursuing core AI and DeSci research. Current focus areas:
|
||||
* Alignment and safety
|
||||
* Cryptographic verification
|
||||
|
||||
|
||||
|
||||
### Grants Program
|
||||
|
||||
Funding for external researchers and projects aligned with the mission. Initial fund: $10M over three years.
|
||||
@@ -86,8 +76,6 @@ Priority areas:
|
||||
* AI safety research
|
||||
* DeSci infrastructure
|
||||
|
||||
|
||||
|
||||
### Working Groups
|
||||
|
||||
Community-led groups focusing on specific areas:
|
||||
@@ -97,8 +85,6 @@ Community-led groups focusing on specific areas:
|
||||
* **Governance** : Improving foundation governance
|
||||
* **Outreach** : Education and community growth
|
||||
|
||||
|
||||
|
||||
## Initial Projects
|
||||
|
||||
The foundation launches with several active projects:
|
||||
@@ -111,8 +97,6 @@ Our next-generation language model series. Currently training:
|
||||
* **Zen-2-34B** : Enhanced reasoning and knowledge
|
||||
* **Zen-2-70B** : Frontier capabilities (in planning)
|
||||
|
||||
|
||||
|
||||
All models released under Apache 2.0.
|
||||
|
||||
### Training Gym
|
||||
@@ -124,8 +108,6 @@ Open source infrastructure for model training. Now includes:
|
||||
* Experiment tracking
|
||||
* Model registry
|
||||
|
||||
|
||||
|
||||
### Experience Ledgers
|
||||
|
||||
Persistent memory for AI agents. Production release scheduled for Q2 2024.
|
||||
@@ -144,8 +126,6 @@ The ZEN token governs the foundation:
|
||||
* **Delegation** : Delegate votes to representatives
|
||||
* **Staking** : Stake tokens to participate in working groups
|
||||
|
||||
|
||||
|
||||
Token distribution:
|
||||
|
||||
* 40% Community treasury (vested over 4 years)
|
||||
@@ -153,8 +133,6 @@ Token distribution:
|
||||
* 20% Foundation reserve
|
||||
* 15% Grants program
|
||||
|
||||
|
||||
|
||||
### ZIPs Process
|
||||
|
||||
Major decisions go through the ZIPs process:
|
||||
@@ -165,8 +143,6 @@ Major decisions go through the ZIPs process:
|
||||
4. **Vote** : Token holders vote (5-day voting period)
|
||||
5. **Implementation** : Approved proposals are executed
|
||||
|
||||
|
||||
|
||||
### Transparency
|
||||
|
||||
All foundation operations are transparent:
|
||||
@@ -176,8 +152,6 @@ All foundation operations are transparent:
|
||||
* Governance votes recorded on chain
|
||||
* Meeting notes published publicly
|
||||
|
||||
|
||||
|
||||
## Join Us
|
||||
|
||||
The foundation is as strong as its community. Ways to participate:
|
||||
@@ -189,8 +163,6 @@ The foundation is as strong as its community. Ways to participate:
|
||||
* Participate in governance
|
||||
* Join working groups
|
||||
|
||||
|
||||
|
||||
### Build
|
||||
|
||||
* Use foundation infrastructure
|
||||
@@ -198,8 +170,6 @@ The foundation is as strong as its community. Ways to participate:
|
||||
* Integrate with our tools
|
||||
* Launch complementary projects
|
||||
|
||||
|
||||
|
||||
### Support
|
||||
|
||||
* Acquire ZEN tokens
|
||||
@@ -207,8 +177,6 @@ The foundation is as strong as its community. Ways to participate:
|
||||
* Fund specific research
|
||||
* Spread the word
|
||||
|
||||
|
||||
|
||||
## The Road Ahead
|
||||
|
||||
We’re at the beginning. The foundation launches with a strong base: years of research, working infrastructure, and a committed community. But the hardest work is ahead.
|
||||
|
||||
File diff suppressed because one or more lines are too long
File diff suppressed because one or more lines are too long
+76
-42
@@ -1,52 +1,86 @@
|
||||
/**
|
||||
* Blog post registry.
|
||||
* Slug must match the MDX filename in content/blog/.
|
||||
*/
|
||||
import { readFileSync, readdirSync } from 'fs';
|
||||
import { join } from 'path';
|
||||
|
||||
export interface BlogPost {
|
||||
slug: string
|
||||
title: string
|
||||
description: string
|
||||
author: string
|
||||
date: string
|
||||
tags: string[]
|
||||
slug: string;
|
||||
title: string;
|
||||
description: string;
|
||||
author: string;
|
||||
date: string;
|
||||
tags: string[];
|
||||
}
|
||||
|
||||
export const posts: BlogPost[] = [
|
||||
{
|
||||
slug: 'zen5-release',
|
||||
title: 'Introducing Zen 5 — Our Most Capable Model Yet',
|
||||
description:
|
||||
'Zen 5 brings 1T+ parameter scale, 2M context windows, and state-of-the-art performance across reasoning, code, and multimodal tasks.',
|
||||
author: 'Zen LM Team',
|
||||
date: '2026-03-01',
|
||||
tags: ['release', 'zen5', 'flagship'],
|
||||
},
|
||||
{
|
||||
slug: 'zen-mode-architecture',
|
||||
title: 'Zen MoDE — How We Build Frontier Models Through Distillation',
|
||||
description:
|
||||
'An inside look at the Mixture of Distilled Experts architecture that powers the Zen model family.',
|
||||
author: 'Zen LM Team',
|
||||
date: '2026-02-15',
|
||||
tags: ['architecture', 'research', 'distillation'],
|
||||
},
|
||||
{
|
||||
slug: 'open-weights-philosophy',
|
||||
title: 'Why We Open-Source Everything',
|
||||
description:
|
||||
'The case for radical openness in AI — why releasing weights is the right thing, strategically and ethically.',
|
||||
author: 'Zen LM Team',
|
||||
date: '2026-01-20',
|
||||
tags: ['open-source', 'philosophy', 'community'],
|
||||
},
|
||||
]
|
||||
/** Parse YAML frontmatter from MDX content (simple key: value only) */
|
||||
function parseFrontmatter(src: string): Record<string, string | string[]> {
|
||||
const match = src.match(/^---\r?\n([\s\S]*?)\r?\n---/);
|
||||
if (!match) return {};
|
||||
const result: Record<string, string | string[]> = {};
|
||||
for (const line of match[1].split('\n')) {
|
||||
const m = line.match(/^(\w+):\s*(.+)$/);
|
||||
if (!m) continue;
|
||||
const [, key, value] = m;
|
||||
// Handle YAML arrays: [a, b, c]
|
||||
if (value.startsWith('[') && value.endsWith(']')) {
|
||||
result[key] = value
|
||||
.slice(1, -1)
|
||||
.split(',')
|
||||
.map((v) => v.trim().replace(/^["']|["']$/g, ''));
|
||||
} else {
|
||||
result[key] = value.replace(/^["']|["']$/g, '');
|
||||
}
|
||||
}
|
||||
return result;
|
||||
}
|
||||
|
||||
const BLOG_DIR = join(process.cwd(), 'content', 'blog');
|
||||
|
||||
function loadAllPosts(): BlogPost[] {
|
||||
let files: string[];
|
||||
try {
|
||||
files = readdirSync(BLOG_DIR).filter((f) => f.endsWith('.mdx'));
|
||||
} catch {
|
||||
return [];
|
||||
}
|
||||
|
||||
const posts: BlogPost[] = [];
|
||||
for (const file of files) {
|
||||
const slug = file.replace(/\.mdx$/, '');
|
||||
try {
|
||||
const src = readFileSync(join(BLOG_DIR, file), 'utf-8');
|
||||
const fm = parseFrontmatter(src);
|
||||
// Skip posts that don't look like public blog posts (no title or date)
|
||||
if (!fm.title || !fm.date) continue;
|
||||
posts.push({
|
||||
slug,
|
||||
title: fm.title as string,
|
||||
description: (fm.description as string) ?? '',
|
||||
author: (fm.author as string) ?? 'Zen LM Team',
|
||||
date: fm.date as string,
|
||||
tags: Array.isArray(fm.tags) ? fm.tags : [],
|
||||
});
|
||||
} catch {
|
||||
// skip malformed files
|
||||
}
|
||||
}
|
||||
return posts;
|
||||
}
|
||||
|
||||
export function getSortedPosts(): BlogPost[] {
|
||||
return [...posts].sort(
|
||||
return loadAllPosts().sort(
|
||||
(a, b) => new Date(b.date).getTime() - new Date(a.date).getTime()
|
||||
)
|
||||
);
|
||||
}
|
||||
|
||||
export function getPost(slug: string): BlogPost | undefined {
|
||||
return posts.find((p) => p.slug === slug)
|
||||
return loadAllPosts().find((p) => p.slug === slug);
|
||||
}
|
||||
|
||||
export function getAllSlugs(): string[] {
|
||||
let files: string[];
|
||||
try {
|
||||
files = readdirSync(BLOG_DIR).filter((f) => f.endsWith('.mdx'));
|
||||
} catch {
|
||||
return [];
|
||||
}
|
||||
return files.map((f) => f.replace(/\.mdx$/, ''));
|
||||
}
|
||||
|
||||
@@ -13,8 +13,8 @@
|
||||
"@hanzo/docs-mdx": "workspace:*",
|
||||
"@hanzo/docs-ui": "workspace:*",
|
||||
"@hanzo/docs-base-ui": "workspace:*",
|
||||
"@zenlm/models": "workspace:*",
|
||||
"@zenlm/ui": "workspace:*",
|
||||
"@zenlm/models": "^1.0.2",
|
||||
"@zenlm/ui": "^1.0.4",
|
||||
"lucide-react": "^0.562.0",
|
||||
"next": "16.1.6",
|
||||
"react": "^19.2.3",
|
||||
|
||||
@@ -1,45 +0,0 @@
|
||||
# @zenlm/models
|
||||
|
||||
The canonical Zen LM model catalog — specs, pricing, and families for the complete Zen model family.
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
npm install @zenlm/models
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
```ts
|
||||
import { allModels, families } from '@zenlm/models'
|
||||
import type { ZenModel } from '@zenlm/models'
|
||||
|
||||
// Get all available models
|
||||
const available = allModels.filter(m => m.status === 'available')
|
||||
|
||||
// Find a specific model
|
||||
const zen5 = allModels.find(m => m.id === 'zen5')
|
||||
|
||||
// Browse by family
|
||||
console.log(families.map(f => f.name))
|
||||
```
|
||||
|
||||
## API
|
||||
|
||||
### `allModels: ZenModel[]`
|
||||
All models in the Zen family — 60+ models across generations.
|
||||
|
||||
### `families: ModelFamily[]`
|
||||
Model families grouped by generation and capability.
|
||||
|
||||
### Types
|
||||
- `ZenModel` — complete model definition
|
||||
- `ModelSpec` — architecture and parameter spec
|
||||
- `ModelPricing` — input/output cost per 1M tokens
|
||||
- `ModelStatus` — `available | preview | coming-soon | contact-sales | cloud-only | deprecated`
|
||||
|
||||
## Links
|
||||
|
||||
- [zenlm.org](https://zenlm.org)
|
||||
- [HuggingFace](https://huggingface.co/zenlm)
|
||||
- [GitHub](https://github.com/hanzoai/docs/tree/main/packages/zenlm-models)
|
||||
@@ -1,53 +0,0 @@
|
||||
{
|
||||
"name": "@zenlm/models",
|
||||
"version": "1.0.0",
|
||||
"description": "Zen model catalog — model specs, pricing, and families for the Zen LM model family",
|
||||
"keywords": ["ai", "llm", "models", "zen", "hanzo"],
|
||||
"license": "MIT",
|
||||
"author": "Hanzo AI",
|
||||
"homepage": "https://zenlm.org",
|
||||
"repository": {
|
||||
"type": "git",
|
||||
"url": "https://github.com/hanzoai/docs",
|
||||
"directory": "packages/zenlm-models"
|
||||
},
|
||||
"type": "module",
|
||||
"main": "./dist/index.js",
|
||||
"module": "./dist/index.js",
|
||||
"types": "./dist/index.d.ts",
|
||||
"exports": {
|
||||
".": {
|
||||
"types": "./dist/index.d.ts",
|
||||
"import": "./dist/index.js",
|
||||
"require": "./dist/index.cjs"
|
||||
},
|
||||
"./models": {
|
||||
"types": "./dist/models.d.ts",
|
||||
"import": "./dist/models.js",
|
||||
"require": "./dist/models.cjs"
|
||||
},
|
||||
"./families": {
|
||||
"types": "./dist/families.d.ts",
|
||||
"import": "./dist/families.js",
|
||||
"require": "./dist/families.cjs"
|
||||
},
|
||||
"./types": {
|
||||
"types": "./dist/types.d.ts",
|
||||
"import": "./dist/types.js",
|
||||
"require": "./dist/types.cjs"
|
||||
}
|
||||
},
|
||||
"files": [
|
||||
"dist",
|
||||
"README.md"
|
||||
],
|
||||
"scripts": {
|
||||
"build": "tsup",
|
||||
"dev": "tsup --watch",
|
||||
"typecheck": "tsc --noEmit"
|
||||
},
|
||||
"devDependencies": {
|
||||
"tsup": "^8.0.0",
|
||||
"typescript": "^5.0.0"
|
||||
}
|
||||
}
|
||||
@@ -1,95 +0,0 @@
|
||||
/**
|
||||
* @hanzo/zen-models — Model family groupings for display purposes.
|
||||
*/
|
||||
|
||||
import type { ModelFamily } from './types'
|
||||
|
||||
export const families: ModelFamily[] = [
|
||||
{
|
||||
id: 'zen5',
|
||||
name: 'Zen 5',
|
||||
description: 'Next-generation agentic models with native chain-of-thought.',
|
||||
icon: 'Rocket',
|
||||
models: ['zen5', 'zen5-pro', 'zen5-max', 'zen5-ultra', 'zen5-mini'],
|
||||
},
|
||||
{
|
||||
id: 'zen4',
|
||||
name: 'Zen 4',
|
||||
description: 'Latest generation production models with MoDE architecture.',
|
||||
icon: 'Sparkles',
|
||||
models: ['zen4-max', 'zen4.1', 'zen4', 'zen4-ultra', 'zen4-pro', 'zen4-thinking', 'zen4-mini'],
|
||||
},
|
||||
{
|
||||
id: 'code',
|
||||
name: 'Code',
|
||||
description: 'Specialized models for code generation, review, and debugging.',
|
||||
icon: 'Code',
|
||||
models: ['zen4-coder', 'zen4-coder-flash', 'zen4-coder-pro', 'zen-coder', 'zen-coder-flash', 'zen-code'],
|
||||
},
|
||||
{
|
||||
id: 'zen3',
|
||||
name: 'Zen 3',
|
||||
description: 'Previous generation API models — language, vision, multimodal, and safety.',
|
||||
icon: 'Eye',
|
||||
models: ['zen3-omni', 'zen3-vl', 'zen3-nano', 'zen3-guard'],
|
||||
},
|
||||
{
|
||||
id: 'embedding',
|
||||
name: 'Embedding & Retrieval',
|
||||
description: 'Text embeddings and search reranking via API.',
|
||||
icon: 'Search',
|
||||
models: [
|
||||
'zen3-embedding', 'zen3-embedding-medium', 'zen3-embedding-small',
|
||||
'zen3-reranker', 'zen3-reranker-medium', 'zen3-reranker-small',
|
||||
'zen-embedding', 'zen-reranker',
|
||||
],
|
||||
},
|
||||
{
|
||||
id: 'image',
|
||||
name: 'Image Generation',
|
||||
description: 'Text-to-image generation via API.',
|
||||
icon: 'Image',
|
||||
models: [
|
||||
'zen3-image', 'zen3-image-max', 'zen3-image-dev', 'zen3-image-fast',
|
||||
'zen3-image-sdxl', 'zen3-image-playground', 'zen3-image-ssd', 'zen3-image-jp',
|
||||
],
|
||||
},
|
||||
{
|
||||
id: 'audio',
|
||||
name: 'Audio & Speech',
|
||||
description: 'Speech-to-text, text-to-speech, and streaming ASR.',
|
||||
icon: 'Mic',
|
||||
models: [
|
||||
'zen3-audio', 'zen3-audio-fast', 'zen3-asr', 'zen3-asr-v1',
|
||||
'zen3-tts', 'zen3-tts-hd', 'zen3-tts-fast',
|
||||
],
|
||||
},
|
||||
{
|
||||
id: 'foundation',
|
||||
name: 'Foundation',
|
||||
description: 'General-purpose open-weight models from 0.6B to 235B parameters.',
|
||||
icon: 'Brain',
|
||||
models: ['zen-nano', 'zen-eco', 'zen', 'zen-pro', 'zen-max', 'zen-next'],
|
||||
},
|
||||
{
|
||||
id: 'vision',
|
||||
name: 'Vision (Open Weights)',
|
||||
description: 'Vision-language and multimodal open-weight models.',
|
||||
icon: 'Eye',
|
||||
models: ['zen-vl', 'zen-omni'],
|
||||
},
|
||||
{
|
||||
id: 'safety',
|
||||
name: 'Safety',
|
||||
description: 'Content moderation and safety guardrail models.',
|
||||
icon: 'Shield',
|
||||
models: ['zen3-guard', 'zen-guard'],
|
||||
},
|
||||
{
|
||||
id: 'agents',
|
||||
name: 'Agents',
|
||||
description: 'Agent-optimized models for tool use and planning.',
|
||||
icon: 'Network',
|
||||
models: ['zen-agent'],
|
||||
},
|
||||
]
|
||||
@@ -1,33 +0,0 @@
|
||||
/**
|
||||
* @zenlm/models — Zen model catalog
|
||||
*
|
||||
* The complete Zen LM model family: specs, pricing, families, and types.
|
||||
* All model data is statically embedded — no API calls required.
|
||||
*
|
||||
* @example
|
||||
* ```ts
|
||||
* import { allModels, families } from '@zenlm/models'
|
||||
* import type { ZenModel } from '@zenlm/models'
|
||||
*
|
||||
* const flagship = allModels.find(m => m.id === 'zen5')
|
||||
* ```
|
||||
*/
|
||||
|
||||
export type {
|
||||
ZenModel,
|
||||
ModelFamily,
|
||||
ModelGeneration,
|
||||
ModelTier,
|
||||
ModelArchitecture,
|
||||
ModelCategory,
|
||||
ModelModality,
|
||||
ModelStatus,
|
||||
ModelPricing,
|
||||
ModelSpec,
|
||||
} from './types'
|
||||
|
||||
// All named model exports + allModels array
|
||||
export * from './models'
|
||||
|
||||
// Model families (grouped catalog)
|
||||
export { families } from './families'
|
||||
File diff suppressed because it is too large
Load Diff
@@ -1,129 +0,0 @@
|
||||
/**
|
||||
* @hanzo/zen-models — Canonical type definitions for the Zen model family.
|
||||
*
|
||||
* There should be one — and preferably only one — obvious place to define these.
|
||||
*/
|
||||
|
||||
export type ModelGeneration = 'zen3' | 'zen4' | 'zen5' | 'foundation'
|
||||
|
||||
export type ModelTier =
|
||||
| 'pro'
|
||||
| 'pro max'
|
||||
| 'ultra'
|
||||
| 'ultra max'
|
||||
|
||||
export type ModelArchitecture =
|
||||
| 'Dense'
|
||||
| 'MoE'
|
||||
| 'MoE + CoT'
|
||||
| 'MoDE + CoT'
|
||||
| 'MoDE + Deep CoT'
|
||||
| 'Dense BF16'
|
||||
| 'Dense Multimodal'
|
||||
| 'MoE Vision-Language'
|
||||
| 'Embedding'
|
||||
| 'Reranker'
|
||||
| 'Diffusion'
|
||||
| 'ASR'
|
||||
| 'Streaming ASR'
|
||||
| 'TTS'
|
||||
| 'TTS HD'
|
||||
|
||||
export type ModelCategory =
|
||||
| 'foundation'
|
||||
| 'flagship'
|
||||
| 'code'
|
||||
| 'vision'
|
||||
| 'video'
|
||||
| 'audio'
|
||||
| 'spatial'
|
||||
| 'safety'
|
||||
| 'embedding'
|
||||
| 'agents'
|
||||
|
||||
export type ModelModality =
|
||||
| 'text'
|
||||
| 'code'
|
||||
| 'vision'
|
||||
| 'video'
|
||||
| 'audio'
|
||||
| '3d'
|
||||
| 'agents'
|
||||
| 'math'
|
||||
| 'safety'
|
||||
| 'embedding'
|
||||
|
||||
export type ModelStatus = 'available' | 'cloud-only' | 'coming-soon' | 'preview' | 'contact-sales'
|
||||
|
||||
export interface ModelPricing {
|
||||
/** Cost per 1M input tokens in USD */
|
||||
input: number
|
||||
/** Cost per 1M output tokens in USD */
|
||||
output: number
|
||||
/** Cost per 1M cached read tokens (null if not supported) */
|
||||
cacheRead: number | null
|
||||
/** Cost per 1M cached write tokens (null if not supported) */
|
||||
cacheWrite: number | null
|
||||
}
|
||||
|
||||
export interface ModelSpec {
|
||||
/** Total parameters (e.g., "744B", "4B", "1.04T") */
|
||||
params: string
|
||||
/** Active parameters for MoE models (e.g., "40B", "3B") — null for dense */
|
||||
activeParams: string | null
|
||||
/** Context window in tokens */
|
||||
context: number
|
||||
/** Architecture type */
|
||||
arch: ModelArchitecture
|
||||
}
|
||||
|
||||
export interface ZenModel {
|
||||
/** Model ID used in API calls (e.g., "zen4", "zen4-coder-flash") */
|
||||
id: string
|
||||
/** Display name (e.g., "Zen4", "Zen4 Coder Flash") */
|
||||
name: string
|
||||
/** Full marketing name (e.g., "Zen4 — Flagship") */
|
||||
fullName: string
|
||||
/** Short description */
|
||||
description: string
|
||||
/** Model generation */
|
||||
generation: ModelGeneration
|
||||
/** Pricing tier */
|
||||
tier: ModelTier
|
||||
/** Primary category */
|
||||
category: ModelCategory
|
||||
/** Supported modalities */
|
||||
modalities: ModelModality[]
|
||||
/** Technical specifications */
|
||||
spec: ModelSpec
|
||||
/** API pricing (null for local-only models) */
|
||||
pricing: ModelPricing | null
|
||||
/** Key feature bullets */
|
||||
features: string[]
|
||||
/** Model status */
|
||||
status: ModelStatus
|
||||
/** HuggingFace URL (null if no public weights) */
|
||||
huggingface: string | null
|
||||
/** GitHub URL (null if none) */
|
||||
github: string | null
|
||||
/** Technical paper / report URL (null if none) */
|
||||
paper?: string | null
|
||||
/** Brand aliases (e.g., zen-max → zen4-max) */
|
||||
aliases: string[]
|
||||
}
|
||||
|
||||
/**
|
||||
* Model family grouping for display.
|
||||
*/
|
||||
export interface ModelFamily {
|
||||
/** Family ID */
|
||||
id: string
|
||||
/** Display name */
|
||||
name: string
|
||||
/** Description */
|
||||
description: string
|
||||
/** Icon name (lucide icon) */
|
||||
icon: string
|
||||
/** Member model IDs */
|
||||
models: string[]
|
||||
}
|
||||
@@ -1,14 +0,0 @@
|
||||
{
|
||||
"compilerOptions": {
|
||||
"target": "ES2022",
|
||||
"module": "ESNext",
|
||||
"moduleResolution": "bundler",
|
||||
"strict": true,
|
||||
"declaration": true,
|
||||
"esModuleInterop": true,
|
||||
"skipLibCheck": true,
|
||||
"outDir": "dist"
|
||||
},
|
||||
"include": ["src/**/*"],
|
||||
"exclude": ["node_modules", "dist"]
|
||||
}
|
||||
@@ -1,15 +0,0 @@
|
||||
import { defineConfig } from 'tsup'
|
||||
|
||||
export default defineConfig({
|
||||
entry: {
|
||||
'index': 'src/index.ts',
|
||||
'models': 'src/models.ts',
|
||||
'families': 'src/families.ts',
|
||||
'types': 'src/types.ts',
|
||||
},
|
||||
format: ['esm', 'cjs'],
|
||||
dts: true,
|
||||
clean: true,
|
||||
treeshake: true,
|
||||
sourcemap: true,
|
||||
})
|
||||
@@ -1,76 +0,0 @@
|
||||
# @zenlm/ui
|
||||
|
||||
React components for the Zen LM model library — model cards, comparison tables, and browsable catalog.
|
||||
|
||||
Works with any React/Next.js app. Uses Tailwind CSS and shadcn/ui CSS variables.
|
||||
|
||||
## Install
|
||||
|
||||
```bash
|
||||
npm install @zenlm/ui @zenlm/models lucide-react
|
||||
```
|
||||
|
||||
## Usage
|
||||
|
||||
### Full Model Library
|
||||
|
||||
```tsx
|
||||
import { ModelLibrary } from '@zenlm/ui'
|
||||
import { allModels, families } from '@zenlm/models'
|
||||
|
||||
export default function ModelsPage() {
|
||||
return (
|
||||
<ModelLibrary
|
||||
allModels={allModels}
|
||||
families={families}
|
||||
linkPrefix="/models/"
|
||||
chatBaseUrl="https://hanzo.chat"
|
||||
/>
|
||||
)
|
||||
}
|
||||
```
|
||||
|
||||
### Model Cards
|
||||
|
||||
```tsx
|
||||
import { ModelCard } from '@zenlm/ui'
|
||||
import { allModels } from '@zenlm/models'
|
||||
|
||||
const zen5 = allModels.find(m => m.id === 'zen5')!
|
||||
|
||||
export default function FeaturedModel() {
|
||||
return <ModelCard model={zen5} chatBaseUrl="https://hanzo.chat" />
|
||||
}
|
||||
```
|
||||
|
||||
### Model Table
|
||||
|
||||
```tsx
|
||||
import { ModelTable } from '@zenlm/ui'
|
||||
import { zen5Models } from '@zenlm/models'
|
||||
|
||||
export default function ComparisonTable() {
|
||||
return <ModelTable models={zen5Models} showPricing showContext />
|
||||
}
|
||||
```
|
||||
|
||||
## Components
|
||||
|
||||
| Component | Description |
|
||||
|-----------|-------------|
|
||||
| `ModelLibrary` | Full browsable catalog with family sections and filter toggle |
|
||||
| `ModelFamilySection` | Single model family section with cards grid |
|
||||
| `ModelCard` | Rich card with spec, status badge, and action buttons |
|
||||
| `ModelTable` | Compact table view with pricing and context columns |
|
||||
| `ZenEnso` | Animated Zen enso circle logo |
|
||||
|
||||
## Requirements
|
||||
|
||||
- React 18+ or 19+
|
||||
- Tailwind CSS with shadcn/ui CSS variables (`--primary`, `--border`, `--muted`, etc.)
|
||||
- lucide-react
|
||||
|
||||
## Links
|
||||
|
||||
- [zenlm.org](https://zenlm.org)
|
||||
- [GitHub](https://github.com/hanzoai/docs/tree/main/packages/zenlm-ui)
|
||||
@@ -1,57 +0,0 @@
|
||||
{
|
||||
"name": "@zenlm/ui",
|
||||
"version": "1.0.3",
|
||||
"description": "React components for the Zen LM model library — model cards, tables, and browsable catalog",
|
||||
"keywords": [
|
||||
"ai",
|
||||
"llm",
|
||||
"models",
|
||||
"zen",
|
||||
"hanzo",
|
||||
"react",
|
||||
"components"
|
||||
],
|
||||
"license": "MIT",
|
||||
"author": "Hanzo AI",
|
||||
"homepage": "https://zenlm.org",
|
||||
"repository": {
|
||||
"type": "git",
|
||||
"url": "https://github.com/hanzoai/docs",
|
||||
"directory": "packages/zenlm-ui"
|
||||
},
|
||||
"type": "module",
|
||||
"main": "./dist/index.js",
|
||||
"module": "./dist/index.js",
|
||||
"types": "./dist/index.d.ts",
|
||||
"exports": {
|
||||
".": {
|
||||
"types": "./dist/index.d.ts",
|
||||
"import": "./dist/index.js",
|
||||
"require": "./dist/index.cjs"
|
||||
}
|
||||
},
|
||||
"files": [
|
||||
"dist",
|
||||
"README.md"
|
||||
],
|
||||
"scripts": {
|
||||
"build": "tsup",
|
||||
"dev": "tsup --watch",
|
||||
"typecheck": "tsc --noEmit"
|
||||
},
|
||||
"peerDependencies": {
|
||||
"react": "^18.0.0 || ^19.0.0",
|
||||
"react-dom": "^18.0.0 || ^19.0.0"
|
||||
},
|
||||
"dependencies": {
|
||||
"@zenlm/models": "workspace:*",
|
||||
"lucide-react": "^0.400.0"
|
||||
},
|
||||
"devDependencies": {
|
||||
"@types/react": "^19.0.0",
|
||||
"@types/react-dom": "^19.0.0",
|
||||
"glob": "^11.0.0",
|
||||
"tsup": "^8.0.0",
|
||||
"typescript": "^5.0.0"
|
||||
}
|
||||
}
|
||||
@@ -1,192 +0,0 @@
|
||||
'use client'
|
||||
|
||||
import { ExternalLink, MessageSquare, Github, FileText } from 'lucide-react'
|
||||
import type { ZenModelLike } from './types'
|
||||
|
||||
function fmtCtx(ctx: number | undefined): string {
|
||||
if (!ctx) return ''
|
||||
if (ctx >= 1_000_000) return `${(ctx / 1_000_000).toFixed(ctx % 1_000_000 === 0 ? 0 : 1)}M ctx`
|
||||
if (ctx >= 1000) return `${Math.round(ctx / 1000)}K ctx`
|
||||
return `${ctx} ctx`
|
||||
}
|
||||
|
||||
function statusInfo(status: string): {
|
||||
label: string
|
||||
className: string
|
||||
} | null {
|
||||
switch (status) {
|
||||
case 'preview':
|
||||
return {
|
||||
label: 'PREVIEW',
|
||||
className: 'bg-amber-500/20 text-amber-600 dark:text-amber-400',
|
||||
}
|
||||
case 'coming-soon':
|
||||
return {
|
||||
label: 'SOON',
|
||||
className: 'bg-muted text-muted-foreground',
|
||||
}
|
||||
case 'contact-sales':
|
||||
return {
|
||||
label: 'EARLY ACCESS',
|
||||
className: 'bg-purple-500/20 text-purple-600 dark:text-purple-400',
|
||||
}
|
||||
default:
|
||||
return null
|
||||
}
|
||||
}
|
||||
|
||||
function isFeaturedModel(id: string, featuredIds?: string[]): boolean {
|
||||
if (featuredIds) return featuredIds.includes(id)
|
||||
return ['zen4-max', 'zen-max', 'zen5', 'zen4'].includes(id)
|
||||
}
|
||||
|
||||
export interface ModelCardProps {
|
||||
model: ZenModelLike
|
||||
/**
|
||||
* Called when the card is clicked.
|
||||
* If not provided, card is not clickable (no cursor-pointer).
|
||||
*/
|
||||
onNavigate?: (id: string) => void
|
||||
/** URL prefix for model detail pages. Default: /docs/models/ */
|
||||
linkPrefix?: string
|
||||
/** Base URL for the "Chat" button. Default: https://hanzo.chat */
|
||||
chatBaseUrl?: string
|
||||
/** URL for "Request Access" (contact-sales models). Default: https://hanzo.ai/contact */
|
||||
requestAccessUrl?: string
|
||||
/** Model IDs to highlight as featured. Default: zen4-max, zen-max, zen5, zen4 */
|
||||
featuredIds?: string[]
|
||||
}
|
||||
|
||||
/**
|
||||
* ModelCard — Rich model card with status badges, spec, and action buttons.
|
||||
*
|
||||
* Works in any Next.js / React app. Pass `onNavigate` to enable whole-card click.
|
||||
*/
|
||||
export function ModelCard({
|
||||
model,
|
||||
onNavigate,
|
||||
linkPrefix = '/docs/models/',
|
||||
chatBaseUrl = 'https://hanzo.chat',
|
||||
requestAccessUrl = 'https://hanzo.ai/contact',
|
||||
featuredIds,
|
||||
}: ModelCardProps) {
|
||||
const status = model.status
|
||||
const featured = isFeaturedModel(model.id, featuredIds)
|
||||
const badge = statusInfo(status)
|
||||
|
||||
const specParts = [
|
||||
model.spec.params && model.spec.params !== 'N/A' && model.spec.params !== 'TBA' && model.spec.params !== 'TBD'
|
||||
? model.spec.params
|
||||
: null,
|
||||
model.spec.activeParams ? `(${model.spec.activeParams} active)` : null,
|
||||
model.spec.arch ?? null,
|
||||
].filter(Boolean)
|
||||
|
||||
const specStr = specParts.join(' ')
|
||||
const ctxStr = fmtCtx(model.spec.context)
|
||||
const fullSpec = [specStr, ctxStr].filter(Boolean).join(' · ')
|
||||
|
||||
const cardBg =
|
||||
featured
|
||||
? 'border-primary/30 bg-primary/5'
|
||||
: status === 'coming-soon'
|
||||
? 'border-border bg-muted/30 opacity-75'
|
||||
: status === 'contact-sales'
|
||||
? 'border-purple-500/20 bg-purple-500/5'
|
||||
: 'border-border bg-background'
|
||||
|
||||
const isClickable = !!onNavigate
|
||||
const handleClick = () => onNavigate?.(model.id)
|
||||
const handleKey = (e: React.KeyboardEvent) => {
|
||||
if (e.key === 'Enter' || e.key === ' ') handleClick()
|
||||
}
|
||||
|
||||
return (
|
||||
<div
|
||||
role={isClickable ? 'link' : undefined}
|
||||
tabIndex={isClickable ? 0 : undefined}
|
||||
onClick={isClickable ? handleClick : undefined}
|
||||
onKeyDown={isClickable ? handleKey : undefined}
|
||||
className={`rounded-lg border p-4 transition hover:border-primary/40 ${cardBg} ${isClickable ? 'cursor-pointer' : ''}`}
|
||||
>
|
||||
{/* Header */}
|
||||
<div className="flex items-center gap-2 mb-1">
|
||||
<span className="font-semibold text-sm">{model.id}</span>
|
||||
{badge && (
|
||||
<span className={`text-[9px] font-semibold tracking-wider uppercase px-1.5 py-0.5 rounded-full ${badge.className}`}>
|
||||
{badge.label}
|
||||
</span>
|
||||
)}
|
||||
</div>
|
||||
|
||||
{/* Spec */}
|
||||
{fullSpec && (
|
||||
<div className="text-xs font-mono text-muted-foreground mb-2">{fullSpec}</div>
|
||||
)}
|
||||
|
||||
{/* Description */}
|
||||
<p className="text-xs text-muted-foreground mb-3">{model.description}</p>
|
||||
|
||||
{/* Action buttons */}
|
||||
<div className="flex flex-wrap gap-1.5 mt-auto">
|
||||
{status === 'contact-sales' && (
|
||||
<a
|
||||
href={requestAccessUrl}
|
||||
target="_blank"
|
||||
rel="noopener noreferrer"
|
||||
onClick={(e) => { e.stopPropagation() }}
|
||||
className="inline-flex items-center gap-1 text-xs bg-purple-500/20 text-purple-400 border border-purple-500/30 px-2 py-0.5 rounded hover:bg-purple-500/30 transition"
|
||||
>
|
||||
<ExternalLink className="h-2.5 w-2.5" /> Request Access
|
||||
</a>
|
||||
)}
|
||||
{(status === 'available' || status === 'preview' || status === 'cloud-only') && (
|
||||
<a
|
||||
href={`${chatBaseUrl}?model=${model.id}`}
|
||||
target="_blank"
|
||||
rel="noopener noreferrer"
|
||||
onClick={(e) => { e.stopPropagation() }}
|
||||
className="inline-flex items-center gap-1 text-xs bg-primary text-primary-foreground px-2 py-0.5 rounded hover:opacity-90 transition"
|
||||
>
|
||||
<MessageSquare className="h-2.5 w-2.5" /> Chat
|
||||
</a>
|
||||
)}
|
||||
{model.huggingface && (
|
||||
<a
|
||||
href={model.huggingface}
|
||||
target="_blank"
|
||||
rel="noopener noreferrer"
|
||||
onClick={(e) => { e.stopPropagation() }}
|
||||
className="inline-flex items-center gap-1 text-xs text-primary hover:underline"
|
||||
>
|
||||
<ExternalLink className="h-2.5 w-2.5" /> Weights
|
||||
</a>
|
||||
)}
|
||||
{model.github && (
|
||||
<a
|
||||
href={model.github}
|
||||
target="_blank"
|
||||
rel="noopener noreferrer"
|
||||
onClick={(e) => { e.stopPropagation() }}
|
||||
className="inline-flex items-center gap-1 text-xs text-muted-foreground hover:underline"
|
||||
>
|
||||
<Github className="h-2.5 w-2.5" /> Repo
|
||||
</a>
|
||||
)}
|
||||
{model.paper && (
|
||||
<a
|
||||
href={model.paper}
|
||||
target="_blank"
|
||||
rel="noopener noreferrer"
|
||||
onClick={(e) => { e.stopPropagation() }}
|
||||
className="inline-flex items-center gap-1 text-xs text-muted-foreground hover:underline"
|
||||
>
|
||||
<FileText className="h-2.5 w-2.5" /> Paper
|
||||
</a>
|
||||
)}
|
||||
</div>
|
||||
</div>
|
||||
)
|
||||
}
|
||||
|
||||
export default ModelCard
|
||||
@@ -1,180 +0,0 @@
|
||||
'use client'
|
||||
|
||||
import { useState } from 'react'
|
||||
import {
|
||||
Atom, Code, Zap, Cpu, Eye, Shield, Search, Network,
|
||||
Mic, Video, Box, Sparkles, Brain, Rocket, Filter, Image,
|
||||
} from 'lucide-react'
|
||||
import { ModelCard } from './ModelCard'
|
||||
import type { ZenModelLike, ModelFamilyLike } from './types'
|
||||
|
||||
const ICON_MAP: Record<string, React.ReactNode> = {
|
||||
Sparkles: <Sparkles className="h-5 w-5" />,
|
||||
Rocket: <Rocket className="h-5 w-5" />,
|
||||
Eye: <Eye className="h-5 w-5" />,
|
||||
Code: <Code className="h-5 w-5" />,
|
||||
Search: <Search className="h-5 w-5" />,
|
||||
Image: <Image className="h-5 w-5" />,
|
||||
Mic: <Mic className="h-5 w-5" />,
|
||||
Brain: <Brain className="h-5 w-5" />,
|
||||
Shield: <Shield className="h-5 w-5" />,
|
||||
Network: <Network className="h-5 w-5" />,
|
||||
Box: <Box className="h-5 w-5" />,
|
||||
Video: <Video className="h-5 w-5" />,
|
||||
Atom: <Atom className="h-5 w-5" />,
|
||||
Cpu: <Cpu className="h-5 w-5" />,
|
||||
Zap: <Zap className="h-5 w-5" />,
|
||||
}
|
||||
|
||||
function isActiveStatus(status: string): boolean {
|
||||
return status === 'available' || status === 'contact-sales' || status === 'cloud-only'
|
||||
}
|
||||
|
||||
export interface ModelFamilySectionProps {
|
||||
family: ModelFamilyLike
|
||||
models: ZenModelLike[]
|
||||
onNavigate?: (id: string) => void
|
||||
chatBaseUrl?: string
|
||||
requestAccessUrl?: string
|
||||
featuredIds?: string[]
|
||||
}
|
||||
|
||||
export function ModelFamilySection({
|
||||
family,
|
||||
models,
|
||||
onNavigate,
|
||||
chatBaseUrl,
|
||||
requestAccessUrl,
|
||||
featuredIds,
|
||||
}: ModelFamilySectionProps) {
|
||||
const icon = (family.icon && ICON_MAP[family.icon]) ?? <Atom className="h-5 w-5" />
|
||||
|
||||
return (
|
||||
<div className="mb-12">
|
||||
<div className="flex items-center gap-3 mb-2">
|
||||
<div className="rounded-lg bg-muted p-2 text-primary">{icon}</div>
|
||||
<div>
|
||||
<h3 className="text-xl font-semibold">{family.name}</h3>
|
||||
<p className="text-sm text-muted-foreground">{family.description}</p>
|
||||
</div>
|
||||
<span className="ml-auto text-xs text-muted-foreground bg-muted px-2 py-1 rounded-full">
|
||||
{models.length} model{models.length !== 1 ? 's' : ''}
|
||||
</span>
|
||||
</div>
|
||||
<div className="grid sm:grid-cols-2 lg:grid-cols-3 gap-3 mt-4">
|
||||
{models.map((m) => (
|
||||
<ModelCard
|
||||
key={m.id}
|
||||
model={m}
|
||||
onNavigate={onNavigate}
|
||||
chatBaseUrl={chatBaseUrl}
|
||||
requestAccessUrl={requestAccessUrl}
|
||||
featuredIds={featuredIds}
|
||||
/>
|
||||
))}
|
||||
</div>
|
||||
</div>
|
||||
)
|
||||
}
|
||||
|
||||
export interface ModelLibraryProps {
|
||||
families: ModelFamilyLike[]
|
||||
allModels: ZenModelLike[]
|
||||
/** URL prefix for model detail navigation. Default: /docs/models/ */
|
||||
linkPrefix?: string
|
||||
/** Base URL for Chat buttons. Default: https://hanzo.chat */
|
||||
chatBaseUrl?: string
|
||||
/** URL for Request Access buttons. Default: https://hanzo.ai/contact */
|
||||
requestAccessUrl?: string
|
||||
/** Model IDs to highlight as featured */
|
||||
featuredIds?: string[]
|
||||
/** Label override for "show all" toggle button */
|
||||
showAllLabel?: string
|
||||
/** Label override for "show current" toggle button */
|
||||
showCurrentLabel?: string
|
||||
/**
|
||||
* Custom navigation handler. If provided, cards are clickable and call this.
|
||||
* Default: navigate to `${linkPrefix}${id}` using window.location.href
|
||||
*/
|
||||
onNavigate?: (id: string) => void
|
||||
}
|
||||
|
||||
/**
|
||||
* ModelLibrary — Full browsable model catalog with family sections and filter toggle.
|
||||
*
|
||||
* Data-agnostic: accepts any ZenModelLike[] + ModelFamilyLike[] data.
|
||||
* Works identically on zen-docs, hanzo.ai, and any other site.
|
||||
*/
|
||||
export function ModelLibrary({
|
||||
families,
|
||||
allModels,
|
||||
linkPrefix = '/docs/models/',
|
||||
chatBaseUrl = 'https://hanzo.chat',
|
||||
requestAccessUrl = 'https://hanzo.ai/contact',
|
||||
featuredIds,
|
||||
showAllLabel = 'Show All Models',
|
||||
showCurrentLabel = 'Show Current Only',
|
||||
onNavigate,
|
||||
}: ModelLibraryProps) {
|
||||
const [showAll, setShowAll] = useState(false)
|
||||
|
||||
const modelById = new Map(allModels.map((m) => [m.id, m]))
|
||||
|
||||
const handleNavigate = (id: string) => {
|
||||
if (onNavigate) {
|
||||
onNavigate(id)
|
||||
} else {
|
||||
window.location.href = `${linkPrefix}${id}`
|
||||
}
|
||||
}
|
||||
|
||||
const visibleFamilies = families
|
||||
.map((f) => {
|
||||
const models = f.models
|
||||
.map((id) => modelById.get(id))
|
||||
.filter((m): m is ZenModelLike => m !== undefined)
|
||||
.filter((m) => showAll || isActiveStatus(m.status))
|
||||
return { ...f, resolvedModels: models }
|
||||
})
|
||||
.filter((f) => f.resolvedModels.length > 0)
|
||||
|
||||
const totalActive = allModels.filter((m) => isActiveStatus(m.status)).length
|
||||
const totalAll = allModels.length
|
||||
const totalHidden = totalAll - totalActive
|
||||
|
||||
return (
|
||||
<>
|
||||
{/* Toggle header */}
|
||||
<div className="flex items-center justify-between mb-8">
|
||||
<p className="text-sm text-muted-foreground">
|
||||
Showing <strong>{showAll ? totalAll : totalActive}</strong> models
|
||||
{!showAll && totalHidden > 0 && (
|
||||
<> · {totalHidden} legacy/upcoming hidden</>
|
||||
)}
|
||||
</p>
|
||||
<button
|
||||
onClick={() => setShowAll(!showAll)}
|
||||
className="inline-flex items-center gap-2 rounded-lg border border-border bg-background px-3 py-1.5 text-sm font-medium hover:bg-muted transition"
|
||||
>
|
||||
<Filter className="h-3.5 w-3.5" />
|
||||
{showAll ? showCurrentLabel : showAllLabel}
|
||||
</button>
|
||||
</div>
|
||||
|
||||
{/* Family sections */}
|
||||
{visibleFamilies.map((family) => (
|
||||
<ModelFamilySection
|
||||
key={family.id}
|
||||
family={family}
|
||||
models={family.resolvedModels}
|
||||
onNavigate={handleNavigate}
|
||||
chatBaseUrl={chatBaseUrl}
|
||||
requestAccessUrl={requestAccessUrl}
|
||||
featuredIds={featuredIds}
|
||||
/>
|
||||
))}
|
||||
</>
|
||||
)
|
||||
}
|
||||
|
||||
export default ModelLibrary
|
||||
@@ -1,118 +0,0 @@
|
||||
'use client'
|
||||
|
||||
import type { ZenModelLike } from './types'
|
||||
|
||||
function fmtCtx(ctx: number | undefined): string {
|
||||
if (!ctx) return '—'
|
||||
if (ctx >= 1_000_000) return `${(ctx / 1_000_000).toFixed(ctx % 1_000_000 === 0 ? 0 : 1)}M`
|
||||
if (ctx >= 1000) return `${Math.round(ctx / 1000)}K`
|
||||
return `${ctx}`
|
||||
}
|
||||
|
||||
function fmtPrice(p: number | null | undefined): string {
|
||||
if (p == null) return '—'
|
||||
return `$${p.toFixed(2)}`
|
||||
}
|
||||
|
||||
function StatusBadge({ status }: { status: string }) {
|
||||
if (status === 'preview' || status === 'coming-soon') {
|
||||
return (
|
||||
<span className="ml-1 text-[9px] font-semibold tracking-wider uppercase bg-amber-500/20 text-amber-600 dark:text-amber-400 px-1.5 py-0.5 rounded-full align-middle">
|
||||
{status === 'preview' ? 'PREVIEW' : 'SOON'}
|
||||
</span>
|
||||
)
|
||||
}
|
||||
if (status === 'contact-sales') {
|
||||
return (
|
||||
<span className="ml-1 text-[9px] font-semibold tracking-wider uppercase bg-purple-500/20 text-purple-600 dark:text-purple-400 px-1.5 py-0.5 rounded-full align-middle">
|
||||
EARLY ACCESS
|
||||
</span>
|
||||
)
|
||||
}
|
||||
return null
|
||||
}
|
||||
|
||||
export interface ModelTableProps {
|
||||
models: ZenModelLike[]
|
||||
/** URL prefix for model links. Default: /docs/models/ */
|
||||
linkPrefix?: string
|
||||
showParams?: boolean
|
||||
showArch?: boolean
|
||||
showContext?: boolean
|
||||
showPricing?: boolean
|
||||
}
|
||||
|
||||
/**
|
||||
* ModelTable — Static table view of models with clickable links.
|
||||
* Works in docs, marketing pages, dashboards.
|
||||
*/
|
||||
export function ModelTable({
|
||||
models,
|
||||
linkPrefix = '/docs/models/',
|
||||
showParams = true,
|
||||
showArch = false,
|
||||
showContext = true,
|
||||
showPricing = true,
|
||||
}: ModelTableProps) {
|
||||
return (
|
||||
<div className="overflow-x-auto my-4">
|
||||
<table className="w-full text-sm">
|
||||
<thead>
|
||||
<tr className="border-b border-border text-left">
|
||||
<th className="pb-2 pr-4 font-medium">Model</th>
|
||||
{showParams && <th className="pb-2 pr-4 font-medium">Parameters</th>}
|
||||
{showArch && <th className="pb-2 pr-4 font-medium">Architecture</th>}
|
||||
{showContext && <th className="pb-2 pr-4 font-medium">Context</th>}
|
||||
{showPricing && <th className="pb-2 pr-4 font-medium text-right">Input $/1M</th>}
|
||||
{showPricing && <th className="pb-2 font-medium text-right">Output $/1M</th>}
|
||||
</tr>
|
||||
</thead>
|
||||
<tbody className="divide-y divide-border">
|
||||
{models.map((m) => (
|
||||
<tr key={m.id}>
|
||||
<td className="py-2 pr-4">
|
||||
<a
|
||||
href={`${linkPrefix}${m.id}`}
|
||||
className="font-mono text-primary hover:underline text-sm"
|
||||
>
|
||||
{m.id}
|
||||
</a>
|
||||
<StatusBadge status={m.status} />
|
||||
</td>
|
||||
{showParams && (
|
||||
<td className="py-2 pr-4 text-sm text-muted-foreground">
|
||||
{m.spec.params && !['N/A', 'TBA', 'TBD'].includes(m.spec.params)
|
||||
? m.spec.params
|
||||
: '—'}
|
||||
{m.spec.activeParams ? ` (${m.spec.activeParams} active)` : ''}
|
||||
</td>
|
||||
)}
|
||||
{showArch && (
|
||||
<td className="py-2 pr-4 text-sm text-muted-foreground">
|
||||
{m.spec.arch ?? '—'}
|
||||
</td>
|
||||
)}
|
||||
{showContext && (
|
||||
<td className="py-2 pr-4 text-sm text-muted-foreground">
|
||||
{fmtCtx(m.spec.context)}
|
||||
</td>
|
||||
)}
|
||||
{showPricing && (
|
||||
<td className="py-2 pr-4 text-sm text-right font-mono">
|
||||
{fmtPrice(m.pricing?.input)}
|
||||
</td>
|
||||
)}
|
||||
{showPricing && (
|
||||
<td className="py-2 text-sm text-right font-mono">
|
||||
{fmtPrice(m.pricing?.output)}
|
||||
</td>
|
||||
)}
|
||||
</tr>
|
||||
))}
|
||||
</tbody>
|
||||
</table>
|
||||
</div>
|
||||
)
|
||||
}
|
||||
|
||||
export default ModelTable
|
||||
@@ -1,78 +0,0 @@
|
||||
'use client'
|
||||
|
||||
import type { CSSProperties } from 'react'
|
||||
|
||||
interface ZenEnsoProps {
|
||||
size?: number
|
||||
color?: string
|
||||
animate?: boolean
|
||||
loop?: boolean
|
||||
/** If true, renders as a loading spinner variant */
|
||||
asLoader?: boolean
|
||||
className?: string
|
||||
}
|
||||
|
||||
/**
|
||||
* ZenEnso — Animated Enso circle logo for Zen LM.
|
||||
* Renders a brush-stroke circle that draws itself.
|
||||
* Uses pure CSS animations — no JS animation library needed.
|
||||
*/
|
||||
export function ZenEnso({
|
||||
size = 64,
|
||||
color = 'white',
|
||||
animate = true,
|
||||
loop = false,
|
||||
asLoader = false,
|
||||
className = '',
|
||||
}: ZenEnsoProps) {
|
||||
const uid = Math.random().toString(36).slice(2, 7)
|
||||
|
||||
const strokeDur = loop ? '1.35s' : '1.25s'
|
||||
const iterCount = loop ? 'infinite' : '1'
|
||||
|
||||
const loaderStyle: CSSProperties = asLoader
|
||||
? { animation: `zenEnsoSpin-${uid} 1.2s linear infinite` }
|
||||
: {}
|
||||
|
||||
return (
|
||||
<span
|
||||
className={`inline-flex items-center justify-center ${className}`}
|
||||
style={{ width: size, height: size }}
|
||||
aria-label="Zen LM"
|
||||
>
|
||||
<style>{`
|
||||
@keyframes zenEnsoDraw-${uid} {
|
||||
to { stroke-dashoffset: 0; }
|
||||
}
|
||||
@keyframes zenEnsoSpin-${uid} {
|
||||
to { transform: rotate(360deg); }
|
||||
}
|
||||
.zen-enso-stroke-${uid} {
|
||||
stroke-dasharray: 1200;
|
||||
stroke-dashoffset: ${animate ? '1200' : '0'};
|
||||
animation: ${animate ? `zenEnsoDraw-${uid} ${strokeDur} cubic-bezier(.2,.9,.25,1) ${iterCount} forwards` : 'none'};
|
||||
}
|
||||
`}</style>
|
||||
<svg
|
||||
viewBox="0 0 512 512"
|
||||
fill="none"
|
||||
xmlns="http://www.w3.org/2000/svg"
|
||||
width={size}
|
||||
height={size}
|
||||
style={loaderStyle}
|
||||
>
|
||||
{/* Brush stroke — draws itself around the circle */}
|
||||
<path
|
||||
className={`zen-enso-stroke-${uid}`}
|
||||
d="M256 74 C154 74 78 160 78 258 C78 352 150 432 250 438 C345 444 434 374 438 276 C441 210 406 150 348 118 C305 94 280 86 256 74"
|
||||
stroke={color}
|
||||
strokeWidth="26"
|
||||
strokeLinecap="round"
|
||||
strokeLinejoin="round"
|
||||
/>
|
||||
</svg>
|
||||
</span>
|
||||
)
|
||||
}
|
||||
|
||||
export default ZenEnso
|
||||
@@ -1,40 +0,0 @@
|
||||
'use client'
|
||||
|
||||
/**
|
||||
* @zenlm/ui — React components for the Zen LM model library
|
||||
*
|
||||
* Provides ready-to-use, data-agnostic components for displaying
|
||||
* Zen models in any React/Next.js application.
|
||||
*
|
||||
* @example
|
||||
* ```tsx
|
||||
* import { ModelLibrary } from '@zenlm/ui'
|
||||
* import { allModels, families } from '@zenlm/models'
|
||||
*
|
||||
* export default function ModelsPage() {
|
||||
* return (
|
||||
* <ModelLibrary
|
||||
* allModels={allModels}
|
||||
* families={families}
|
||||
* chatBaseUrl="https://hanzo.chat"
|
||||
* />
|
||||
* )
|
||||
* }
|
||||
* ```
|
||||
*/
|
||||
|
||||
export { ModelCard } from './ModelCard'
|
||||
export { ModelTable } from './ModelTable'
|
||||
export { ModelLibrary, ModelFamilySection } from './ModelLibrary'
|
||||
export { ZenEnso } from './ZenEnso'
|
||||
|
||||
export type {
|
||||
ZenModelLike,
|
||||
ModelFamilyLike,
|
||||
ModelSpecLike,
|
||||
ModelPricingLike,
|
||||
} from './types'
|
||||
|
||||
export type { ModelCardProps } from './ModelCard'
|
||||
export type { ModelTableProps } from './ModelTable'
|
||||
export type { ModelLibraryProps, ModelFamilySectionProps } from './ModelLibrary'
|
||||
@@ -1,43 +0,0 @@
|
||||
/**
|
||||
* @hanzo/ui — Model component types
|
||||
*
|
||||
* These types are structurally compatible with @hanzo/zen-models ZenModel / ModelFamily,
|
||||
* so ZenModel objects can be passed directly to these components without casting.
|
||||
*/
|
||||
|
||||
export interface ModelSpecLike {
|
||||
params: string
|
||||
activeParams?: string | null
|
||||
context?: number
|
||||
arch?: string
|
||||
}
|
||||
|
||||
export interface ModelPricingLike {
|
||||
input: number | null
|
||||
output: number | null
|
||||
cacheRead?: number | null
|
||||
cacheWrite?: number | null
|
||||
}
|
||||
|
||||
export interface ZenModelLike {
|
||||
id: string
|
||||
name: string
|
||||
description: string
|
||||
spec: ModelSpecLike
|
||||
pricing: ModelPricingLike | null
|
||||
/** 'available' | 'preview' | 'coming-soon' | 'contact-sales' | 'cloud-only' */
|
||||
status: string
|
||||
huggingface?: string | null
|
||||
github?: string | null
|
||||
paper?: string | null
|
||||
}
|
||||
|
||||
export interface ModelFamilyLike {
|
||||
id: string
|
||||
name: string
|
||||
description: string
|
||||
/** lucide-react icon name */
|
||||
icon?: string
|
||||
/** ordered list of model IDs */
|
||||
models: string[]
|
||||
}
|
||||
@@ -1,15 +0,0 @@
|
||||
{
|
||||
"compilerOptions": {
|
||||
"target": "ES2022",
|
||||
"module": "ESNext",
|
||||
"moduleResolution": "bundler",
|
||||
"jsx": "react-jsx",
|
||||
"strict": true,
|
||||
"declaration": true,
|
||||
"esModuleInterop": true,
|
||||
"skipLibCheck": true,
|
||||
"outDir": "dist"
|
||||
},
|
||||
"include": ["src/**/*"],
|
||||
"exclude": ["node_modules", "dist"]
|
||||
}
|
||||
@@ -1,26 +0,0 @@
|
||||
import { defineConfig } from 'tsup'
|
||||
import { glob } from 'glob'
|
||||
|
||||
export default defineConfig({
|
||||
entry: {
|
||||
'index': 'src/index.ts',
|
||||
},
|
||||
format: ['esm', 'cjs'],
|
||||
dts: true,
|
||||
clean: true,
|
||||
treeshake: true,
|
||||
sourcemap: true,
|
||||
external: ['react', 'react-dom', 'lucide-react', '@zenlm/models'],
|
||||
onSuccess: async () => {
|
||||
const fs = (await import('fs')).default
|
||||
const files = glob.sync('dist/**/*.{js,mjs}', { ignore: ['**/*.d.ts'] })
|
||||
for (const file of files) {
|
||||
const content = fs.readFileSync(file, 'utf-8')
|
||||
if (content.includes('react') || content.includes('jsx-runtime')) {
|
||||
if (!content.startsWith('"use client"') && !content.startsWith("'use client'")) {
|
||||
fs.writeFileSync(file, '"use client";\n' + content)
|
||||
}
|
||||
}
|
||||
}
|
||||
},
|
||||
})
|
||||
Generated
+56
-68
@@ -1154,11 +1154,11 @@ importers:
|
||||
specifier: workspace:*
|
||||
version: link:../../packages/radix-ui
|
||||
'@zenlm/models':
|
||||
specifier: workspace:*
|
||||
version: link:../../packages/zenlm-models
|
||||
specifier: ^1.0.2
|
||||
version: 1.0.2
|
||||
'@zenlm/ui':
|
||||
specifier: workspace:*
|
||||
version: link:../../packages/zenlm-ui
|
||||
specifier: ^1.0.4
|
||||
version: 1.0.4([email protected]([email protected]))([email protected])
|
||||
lucide-react:
|
||||
specifier: ^0.562.0
|
||||
version: 0.562.0([email protected])
|
||||
@@ -4253,46 +4253,6 @@ importers:
|
||||
|
||||
packages/zen-models: {}
|
||||
|
||||
packages/zenlm-models:
|
||||
devDependencies:
|
||||
tsup:
|
||||
specifier: ^8.0.0
|
||||
version: 8.5.1([email protected])([email protected])([email protected])([email protected])([email protected])
|
||||
typescript:
|
||||
specifier: ^5.0.0
|
||||
version: 5.9.3
|
||||
|
||||
packages/zenlm-ui:
|
||||
dependencies:
|
||||
'@zenlm/models':
|
||||
specifier: workspace:*
|
||||
version: link:../zenlm-models
|
||||
lucide-react:
|
||||
specifier: ^0.400.0
|
||||
version: 0.400.0([email protected])
|
||||
react:
|
||||
specifier: ^18.0.0 || ^19.0.0
|
||||
version: 19.2.4
|
||||
react-dom:
|
||||
specifier: ^18.0.0 || ^19.0.0
|
||||
version: 19.2.4([email protected])
|
||||
devDependencies:
|
||||
'@types/react':
|
||||
specifier: ^19.0.0
|
||||
version: 19.2.14
|
||||
'@types/react-dom':
|
||||
specifier: ^19.0.0
|
||||
version: 19.2.3(@types/[email protected])
|
||||
glob:
|
||||
specifier: ^11.0.0
|
||||
version: 11.1.0
|
||||
tsup:
|
||||
specifier: ^8.0.0
|
||||
version: 8.5.1([email protected])([email protected])([email protected])([email protected])([email protected])
|
||||
typescript:
|
||||
specifier: ^5.0.0
|
||||
version: 5.9.3
|
||||
|
||||
packages:
|
||||
|
||||
'@ai-sdk/[email protected]':
|
||||
@@ -9281,6 +9241,15 @@ packages:
|
||||
'@zeit/[email protected]':
|
||||
resolution: {integrity: sha512-7kjMwcChYEzMKjeex9ZFXkt1AyNov9R5HZtjBKVsmVpw7pa7ZtlCGvCBC2vnnXctaYN+aRI61HjIqeetZW5ROg==}
|
||||
|
||||
'@zenlm/[email protected]':
|
||||
resolution: {integrity: sha512-mwheakDCwjBWhSvDEPlXssdeKgs4bbMqymLWy4sqsweLc8vvr7rnsL+2Qqs5BfGJ6e+dt13WQGci/3LPaSjxJA==}
|
||||
|
||||
'@zenlm/[email protected]':
|
||||
resolution: {integrity: sha512-sMNMZkVVq5H1bIfEcSPkqPblQPA/y+EzBNOGqXNoJ60e6/OEudAfI1b8ajT35jeZtYfpWPqiZb3rJ3q22gWecg==}
|
||||
peerDependencies:
|
||||
react: ^18.0.0 || ^19.0.0
|
||||
react-dom: ^18.0.0 || ^19.0.0
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-PYAthTa2m2VKxuvSD3DPC/Gy+U+sOA1LAuT8mkmRuvw+NACSaeXEQ+NHcVF7rONl6qcaxV3Uuemwawk+7+SJLw==}
|
||||
engines: {node: '>= 0.6'}
|
||||
@@ -10802,10 +10771,6 @@ packages:
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-k6GAGDyqLe9JaebCsFCoudPPWfihKu8pylYXRlqP1J7ms39iPoTtk2fviNglIeQEwdh0bQeKJ01ZPyuyQvKzwg==}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-gIXjKqtFuWEgzFRJA9WCQeSJLZDjgJUOMCMzxtvFq/37KojM1BFGufqsCy0r4qSQmYLsZYMeyRqzIWOMup03sw==}
|
||||
engines: {node: '>=14'}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-wzsgA6WOq+09wrU1tsJ09udeR/YZRaeArL9e1wPbFg3GG2yDnC2ldKpxs4xunpFF9DgqCqOIra3bc1HWrJ37Ww==}
|
||||
engines: {node: '>=0.4.x'}
|
||||
@@ -10946,16 +10911,14 @@ packages:
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-lkX1HJXwyMcprw/5YUZc2s7DrpAiHB21/V+E1rHUrVNokkvB6bqMzT0VfV6/86ZNabt1k14YOIaT7nDvOX3Iiw==}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-vuNwKSaKiqm7g0THUBu2x7ckSs3XJLXE+2ssL7/MfTGPLLcrJQ/4Uq1CjPTtO5cCIiRxqvN6Twy1qOwhL0Xjcw==}
|
||||
engines: {node: 20 || >=22}
|
||||
deprecated: Old versions of glob are not supported, and contain widely publicized security vulnerabilities, which have been fixed in the current version. Please update. Support for old versions may be purchased (at exorbitant rates) by contacting [email protected]
|
||||
hasBin: true
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-KACie1EOs9BIOMtenFaxwmYODWA3/fTfGSUnLhMJpXRntu1g+uL/Xvub5f8SCTppvo9q62Qy4LeOoUiaL54G5A==}
|
||||
engines: {node: 20 || >=22}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-Wjlyrolmm8uDpm/ogGyXZXb1Z+Ca2B8NbJwqBVg0axK9GbBeoS7yGV6vjXnYdGm6X53iehEuxxbyiKp8QmN4Vw==}
|
||||
engines: {node: 18 || 20 || >=22}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-DpLKbNU4WylpxJykQujfCcwYWiV/Jhm50Goo0wrVILAv5jOr9d+H+UR3PhSCD2rCCEIg0uc+G+muBTwD54JhDQ==}
|
||||
engines: {node: '>= 0.4'}
|
||||
@@ -12183,6 +12146,10 @@ packages:
|
||||
resolution: {integrity: sha512-MClCe8IL5nRRmawL6ib/eT4oLyeKMGCghibcDWK+J0hh0Q8kqSdia6BvbRMVk6mPa6WqUa5uR2oxt6C5jd533A==}
|
||||
engines: {node: 20 || >=22}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-oRjTw/97aTBN0RHbYCdtF1MQfvusSIBQM0IZEgzl6426+8jSC0nF1a/GmnVLpfB9yyr6g6FTqWqiZVbxrtaCIg==}
|
||||
engines: {node: 18 || 20 || >=22}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-J7p63hRiAjw1NDEww1W7i37+ByIrOWO5XQQAzZ3VOcL0PNybwpfmV/N05zFAzwQ9USyEcX6t3UO+K5aqBQOIHw==}
|
||||
|
||||
@@ -12197,6 +12164,10 @@ packages:
|
||||
resolution: {integrity: sha512-qOOzS1cBTWYF4BH8fVePDBOO9iptMnGUEZwNc/cMWnTV2nVLZ7VoNWEPHkYczZA0pdoA7dl6e7FL659nX9S2aw==}
|
||||
engines: {node: '>=16 || 14 >=14.17'}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-tEBHqDnIoM/1rXME1zgka9g6Q2lcoCkxHLuc7ODJ5BxbP5d4c2Z5cGgtXAku59200Cx7diuHTOYfSBD8n6mm8A==}
|
||||
engines: {node: '>=16 || 14 >=14.17'}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-l8D9ODSRWLe2KHJSifWGwBqpTZXIXTeo8mlKjY+E2HAakaTeNpqAyBZ8GSqLzHgw4XmHmC8whvpjJNMbFZN7/g==}
|
||||
|
||||
@@ -12656,6 +12627,10 @@ packages:
|
||||
resolution: {integrity: sha512-oWyT4gICAu+kaA7QWk/jvCHWarMKNs6pXOGWKDTr7cw4IGcUbW+PeTfbaQiLGheFRpjo6O9J0PmyMfQPjH71oA==}
|
||||
engines: {node: 20 || >=22}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-3O/iVVsJAPsOnpwWIeD+d6z/7PmqApyQePUtCndjatj/9I5LylHvt5qluFaBT3I5h3r1ejfR056c+FCv+NnNXg==}
|
||||
engines: {node: 18 || 20 || >=22}
|
||||
|
||||
[email protected]:
|
||||
resolution: {integrity: sha512-RA1GjUVMnvYFxuqovrEqZoxxW5NUZqbwKtYz/Tt7nXerk0LbLblQmrsgdeOxV5SFHf0UDggjS/bSeOZwt1pmEQ==}
|
||||
|
||||
@@ -19916,6 +19891,16 @@ snapshots:
|
||||
|
||||
'@zeit/[email protected]': {}
|
||||
|
||||
'@zenlm/[email protected]': {}
|
||||
|
||||
'@zenlm/[email protected]([email protected]([email protected]))([email protected])':
|
||||
dependencies:
|
||||
'@zenlm/models': 1.0.2
|
||||
glob: 13.0.6
|
||||
lucide-react: 0.400.0([email protected])
|
||||
react: 19.2.4
|
||||
react-dom: 19.2.4([email protected])
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
mime-types: 2.1.35
|
||||
@@ -21812,11 +21797,6 @@ snapshots:
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
cross-spawn: 7.0.6
|
||||
signal-exit: 4.1.0
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
[email protected]:
|
||||
@@ -21941,21 +21921,18 @@ snapshots:
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
foreground-child: 3.3.1
|
||||
jackspeak: 4.2.3
|
||||
minimatch: 10.2.1
|
||||
minipass: 7.1.2
|
||||
package-json-from-dist: 1.0.1
|
||||
path-scurry: 2.0.1
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
minimatch: 10.2.1
|
||||
minipass: 7.1.2
|
||||
path-scurry: 2.0.1
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
minimatch: 10.2.4
|
||||
minipass: 7.1.3
|
||||
path-scurry: 2.0.2
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
define-properties: 1.2.1
|
||||
@@ -23489,6 +23466,10 @@ snapshots:
|
||||
dependencies:
|
||||
brace-expansion: 5.0.2
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
brace-expansion: 5.0.2
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
brace-expansion: 1.1.11
|
||||
@@ -23501,6 +23482,8 @@ snapshots:
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
acorn: 8.15.0
|
||||
@@ -24191,6 +24174,11 @@ snapshots:
|
||||
lru-cache: 11.2.6
|
||||
minipass: 7.1.2
|
||||
|
||||
[email protected]:
|
||||
dependencies:
|
||||
lru-cache: 11.2.6
|
||||
minipass: 7.1.3
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
[email protected]: {}
|
||||
|
||||
Reference in New Issue
Block a user